

"This is a moment where that community feels collectively under threat and isn't sure what the process is for solving the problem.”
An update on the scraper situation
Our article 'Fighting the AI scraper bot scourge', published in early 2025, discussed the probl [...]
Aggressive AI scrapers are making it kinda suck to run wikis
Bots are currently scraping the internet for LLM training data at unprecedented rates[1][2][3], driving up costs and destabilizing public-facing websites. I want to talk about how this has been particularly difficult for wikis, and has gotten much worse in the last few months.
Getting Bots to Respect Boundaries
Getting Bots to Respect Boundaries How AI Crawlers Are Straining Web Infrastructure Audrey Hingle January 2026 Image by Janet Turra & Cambridge Diversity Fund betterimagesofai.org creativecommons.org/licenses/by/4.0 Contents Introduction: Setting up the Problem 3 Understandin...

Ultimate Block List to Stop AI Bots | Perishable Press
More than you might think, AI (Artificial Intelligence) and ML (Machine Learning) bots are crawling your site and scraping your content. They are...
AI is eating website traffic, websites are blocking AI – and reliable information is getting harder to find
AI has broken the economic bargain behind the web, and everybody is losing.
Keynote: The Death of the Browser - Rachel-Lee Nabors, AgentQL
Unauthorised AI Bots on Reddit are Eroding Sociality
Where do we go if online discourse is overrun by AI bots?

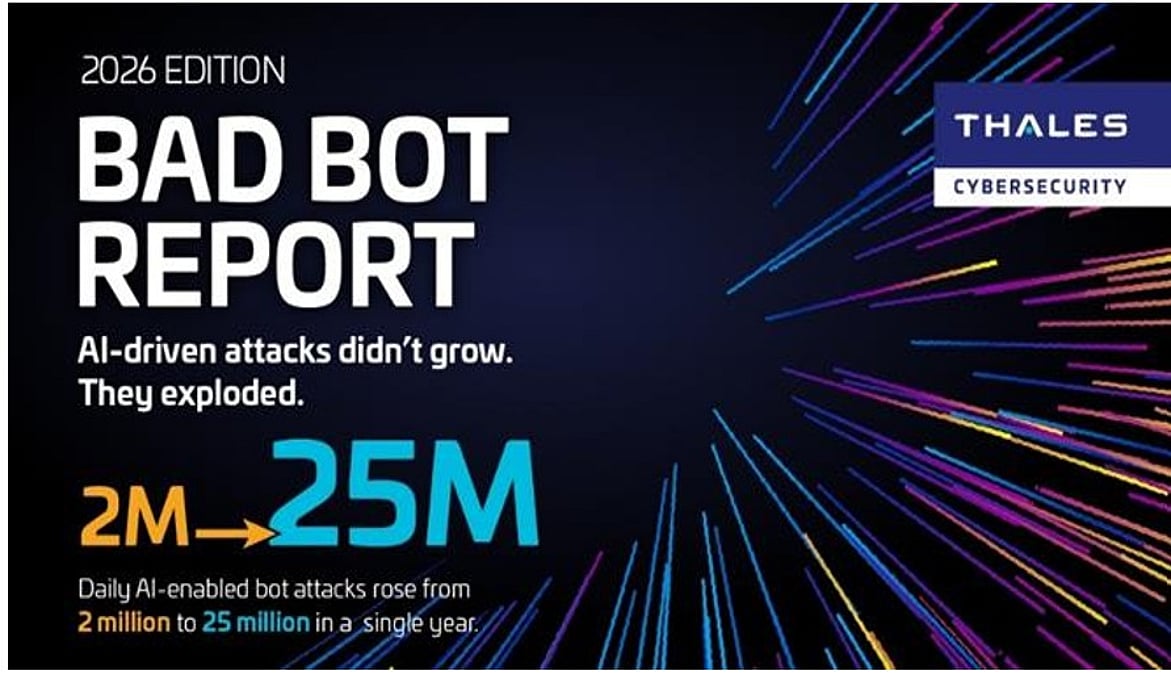
AI-driven Bot Attacks Surged 12.5x According to Thales Bad Bot Report
Bots now dominate the internet, accounting for over half of all traffic, with 40% classified as malicious.AI is erasing the line between legitimate and maliciou
How AI bots quietly dismantle paywalls via web search
ChatGPT and other AI chatbots have figured out how to get around paywalls through "live" web search—and they're doing it systematically and quietly across major publications, new Digital Digging research reveals.
Commence the Botwatch | Botwatch Blog
Bots were already a pain online when they were little more than if-then scripts. Now a tidal wave of slop is swamping the internet as big tech companies profit. OpenAI and the rest would love for you to believe they care about "alignment" and "values" while their AI models damage our communities, both online and off. It's time to fight back.
Is Misinformation More Open? A Study of robots.txt Gatekeeping on the Web
Web scraping, the automated process of extracting information from websites, has long played a foundational role in the Internet ecosystem (Gray, 1995). It supports services such as search engine indexing, price comparison tools, and competitive intelligence. More recently, it has become a core component in the development of large-scale generative AI models. These Large Language Models (LLMs) require enormous volumes of training data, often in the terabyte range (Kaplan et al., 2020; Lehane, 2025), and the public web remains a low-cost, attractive source. Major model developers, including those behind OpenAI’s Chat-GPT (OpenAI, 2025), Google’s Bard (now known as Gemini) & Vertex AI (Romain, Danielle, 2023), and Anthropic’s Claude (Romain, Danielle, 2025), openly acknowledge the use of web scraping to construct their training corpora (Abdin et al., 2024; Brown et al., 2020; Chowdhery et al., 2023; Grattafiori et al., 2024; Team et al., 2024; Touvron et al., 2023).
Google’s broken link to the web
With AI search results coming to the masses, the human-powered web recedes further into the background
AI slop is drowning communities. Verifiable track records can fix it.
AI-generated junk content is flooding every community platform. Traditional moderation can't keep up. Portable, cross-platform contribution history is a structural fix that addresses the root cause.
The AI-Powered Web Is Eating Itself
Without a framework of “Artificial Integrity,” AI search platforms risk collapsing the information commons that made the web possible.

Study Finds A Third of New Websites are AI-Generated
Researchers found the internet is becoming aggressively positive as AI-generated text floods the web.
Exclusive: Multiple AI companies bypassing web standard to scrape publisher sites, licensing firm says
Multiple artificial intelligence companies are circumventing a common web standard used by publishers to block the scraping of their content for use in generative AI systems, content licensing startup TollBit has told publishers.