

The General Conference on Weights and Measures (CGPM), at its 28th meeting,
Sebastian Raschka on Twitter / X
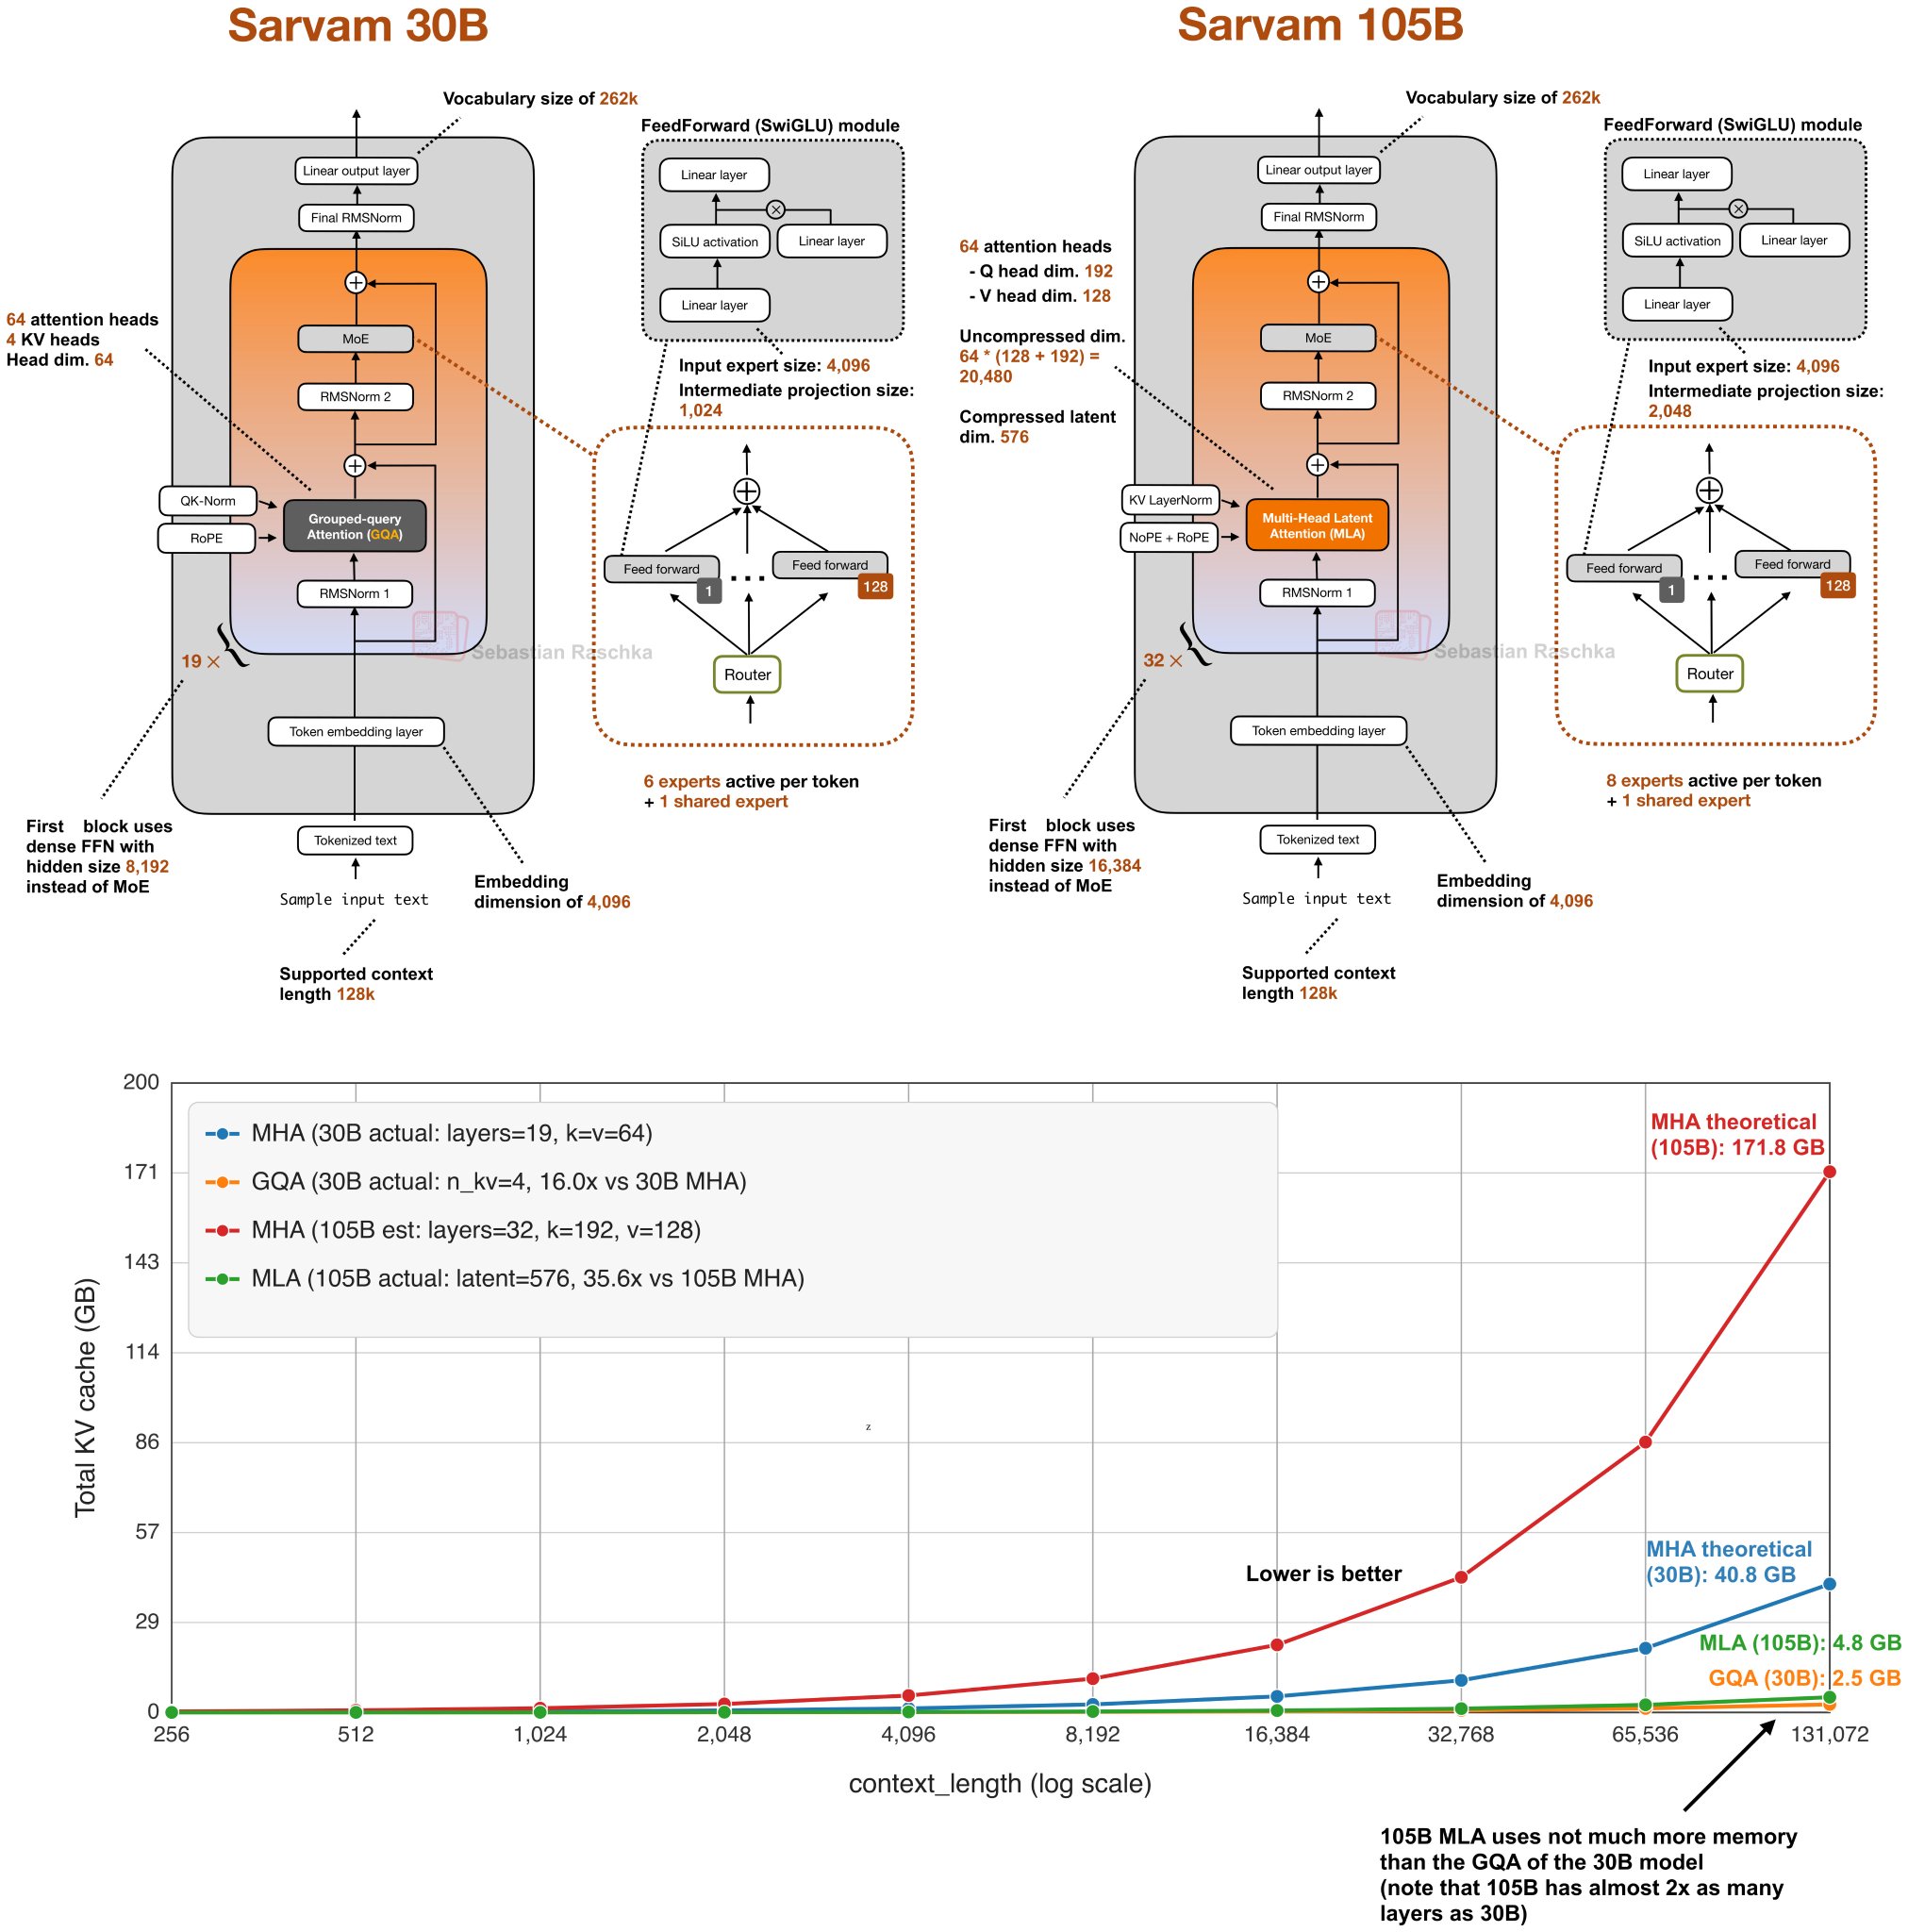
While waiting for DeepSeek V4 we got two very strong open-weight LLMs from India yesterday.There are two size flavors, Sarvam 30B and Sarvam 105B model (both reasoning models).Interestingly, the smaller 30B model uses “classic” Grouped Query Attention (GQA), whereas the… https://t.co/OiJVkDCYNz pic.twitter.com/0uqmLxofRE— Sebastian Raschka (@rasbt) March 7, 2026
The OpenAI Open weight model might be 120B
726 votes, 163 comments. The person who "leaked" this model is from the openai (HF) organization So as expected, it's not gonna be something you can…
Information: the Measure of All Things? Part I: Communication, Code and Computation - 3 Quarks Daily
by Yohan J. John

Weights & Biases on Twitter / X
Hey MCP developers!Let’s talk about something broken 🧠🛠️Agents are calling tools left and right.But what happens inside those tools?No traces. No visibility. No security.Just a black box. 🕋The observability gap is real. Let's fix it together with observable[.]tools pic.twitter.com/htHmtBaJGH— Weights & Biases (@wandb) April 9, 2025

I COULD BARELY EVEN SPELL GFM…
#GlobalForceManagement - not the most popular choice of study for a #JPME student, but #GFM is a #CJCS #SpecialAreaofEmphasis


Readwise MCP Server - Readwise Docs
The Model Context Protocol (MCP) standardizes how applications provide context to Large Language Models (LLMs). The Readwise MCP was created to act as a...
How Open Weights Are Changing the AI Race | Serverless Guru
Open Weight models: what they are, why you should care, and how the work of the open-source fine-tuning community around those models is reshaping daily life, both for developers and for everyday AI users.
Release v0.11.0 · ollama/ollama
Welcome OpenAI's gpt-oss models Ollama partners with OpenAI to bring its latest state-of-the-art open weight models to Ollama. The two models, 20B and 120B, bring a whole new local chat experie...
How To Scale Your Model
Training LLMs often feels like alchemy, but understanding and optimizing the performance of your models doesn't have to. This book aims to demystify the science of scaling language models: how TPUs (and GPUs) work and how they communicate with each other, how LLMs run on real hardware, and how to parallelize your models during training and inference so they run efficiently at massive scale. If you've ever wondered “how expensive should this LLM be to train” or “how much memory do I need to serve this model myself” or “what's an AllGather”, we hope this will be useful to you.
ATmospheric status monitors uptime

downorjustme
Server Status
Atmosphere Status
Uptime monitor
Arabica Social status

Graze Social Status
status.northsky.social
