

Osmosis-Structure-0.6B is a small model trained with reinforcement learning to do one thing well: extract structured data, typically JSON, from unformatted text. That’s it!
Osmosis | Forward Deployed Reinforcement Learning Platform
Osmosis is a forward-deployed reinforcement learning platform that helps companies train task-specific AI models that outperform foundation models at a fraction of the cost. Build, deploy, and continuously improve intelligent systems with hands-on integration and real-time feedback.
The control layer for AI
The industry spent two years teaching LLMs to speak JSON. That work mattered: free-form text was unusable in production. Today, every serious inference provider uses some implementation (often open-source) of structured output. Structured output has become essential infrastructure that the team at .txt is proud to have spearheaded. Even as the ecosystem evolves, and open-source alternatives emerged, our engine remains the state of the art.
Structured Outputs with Will Kurt and Cameron Pfiffer - Weaviate Podcast #119!
Everything I Learned Training Frontier Small Models — Maxime Labonne, Liquid AI
Everything I Learned Training Frontier Small Models — Maxime Labonne, Liquid AI
ZML - Model to Metal
ZML is a production inference stack, purpose-built to decouple AI workloads from proprietary hardware.
Daniel Han on Twitter / X
OpenAI's OSS model possible breakdown:1. 120B MoE 5B active + 20B text only2. Trained with Float4 maybe Blackwell chips3. SwiGLU clip (-7,7) like ReLU64. 128K context via YaRN from 4K5. Sliding window 128 + attention sinks6. Llama/Mixtral arch + biasesDetails:1. 120B MoE… https://t.co/bMFp3Z6Gs5 pic.twitter.com/1NFO4utPqr— Daniel Han (@danielhanchen) August 1, 2025

Liquid <> .txt Collaboration | Liquid AI
Faster and more accurate function calling on the edge with .txt’s structured outputs and Liquid Foundation Models
Models Don't "Get Reward" — LessWrong
Models don't "get" reward. Reward is the mechanism by which we select parameters, it is not something "given" to the model. Reinforcement learning sh…
Liquid AI — Device-native foundation models.
Liquid AI is an efficiency-first foundation model company. We build highly capable, compute-optimized models that bring intelligence to any device and medium of choice.
Beyond Model Collapse: Scaling Up with Synthesized Data Requires...
Large Language Models (LLM) are increasingly trained on data generated by other LLM, either because generated text and images become part of the pre-training corpus, or because synthetized data is...

tinygrad: A simple and powerful neural network framework
We write and maintain tinygrad, the fastest growing neural network framework
Decision-style Model Examples

Decision-style models, like TypeSafe's Jev model, are fast and cheap models that output structured data that has been opening a lot of doors for interesting HCI applications. Here I'll collect interesting examples I come across.
Matt DesLauriers on Twitter / X
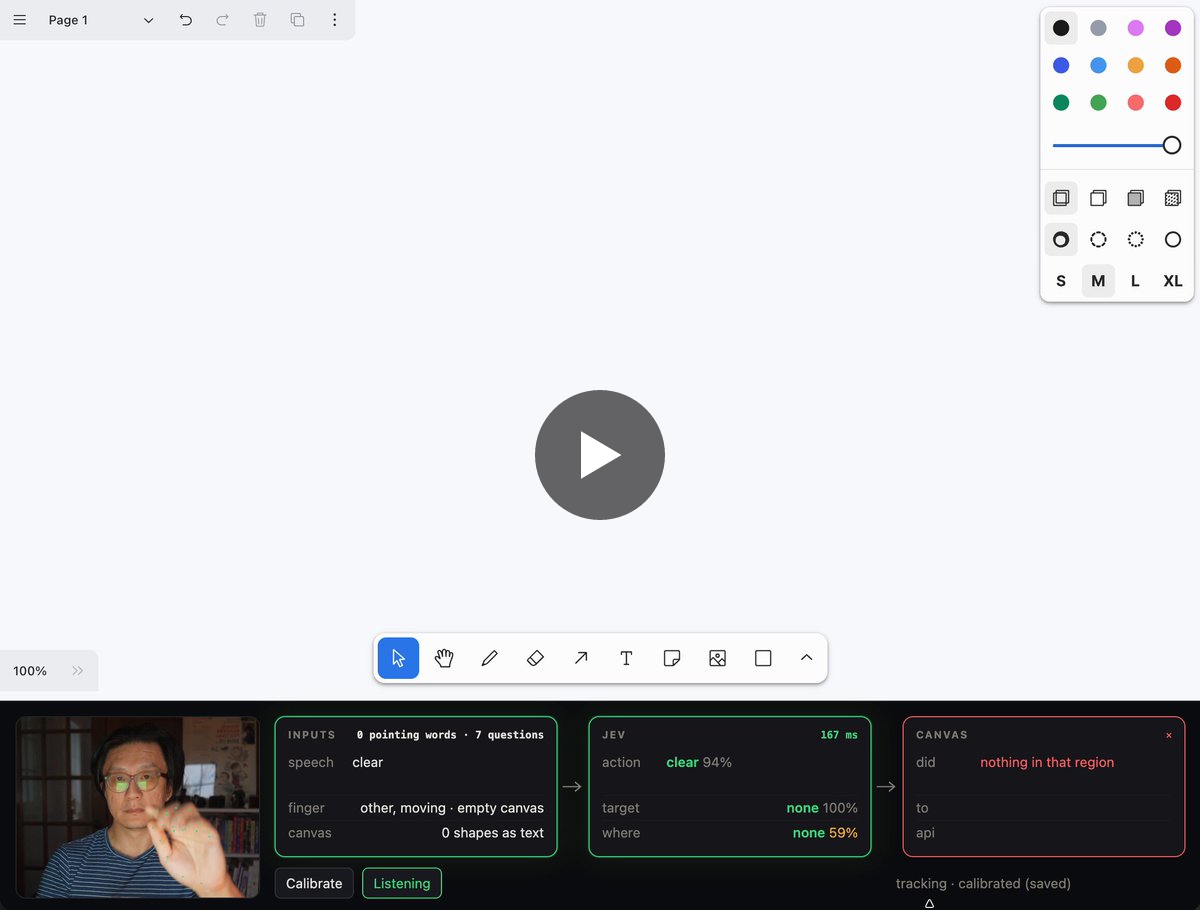
Jack Cheng on Twitter / X

Andy Gao on Twitter / X

Chris Tate on Twitter / X
mikegee on Twitter / X

Marek Sotak on Twitter / X
