

A measurement study of 20 LLM tokenizers across 12 languages and 21 kinds of text. On German, Claude 4.7+ needs 2.01x the tokens of the OpenAI reference, and Cohere Command A+ the fewest.
Mastering Token Limits and Memory in ChatGPT and other Large Language Models
A Guide for the Everyday User

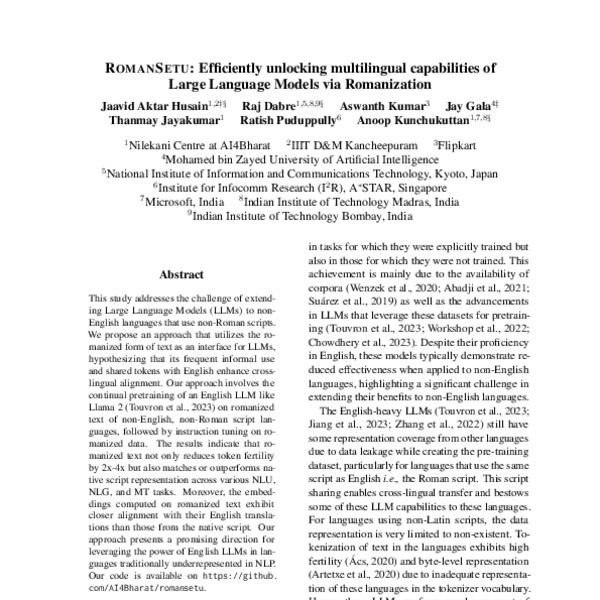
RomanSetu: Efficiently unlocking multilingual capabilities of Large Language Models via Romanization
This study addresses the challenge of extending Large Language Models (LLMs) to non-English languages, specifically those using non-Roman scripts. We propose an approach that utilizes the romanized form of text as an interface for LLMs, hypothesizing that its frequent informal use and shared tokens with English enhance cross-lingual alignment. Our approach involve the continual pretraining of a English LLM like Llama 2 on romanized text of non-English, non-Roman script languages, followed by instruction tuning on romanized data. The results indicate that romanized text not only reduces token fertility by 2x-4x but also matches if not outperforms native script representation across various NLU, NLG and MT tasks. Moreover, the embeddings computed on romanized text exhibit closer alignment with their English translations than those from the native script. Our approach presents a promising direction for leveraging the power of English LLMs in languages traditionally underrepresented in NLP research.
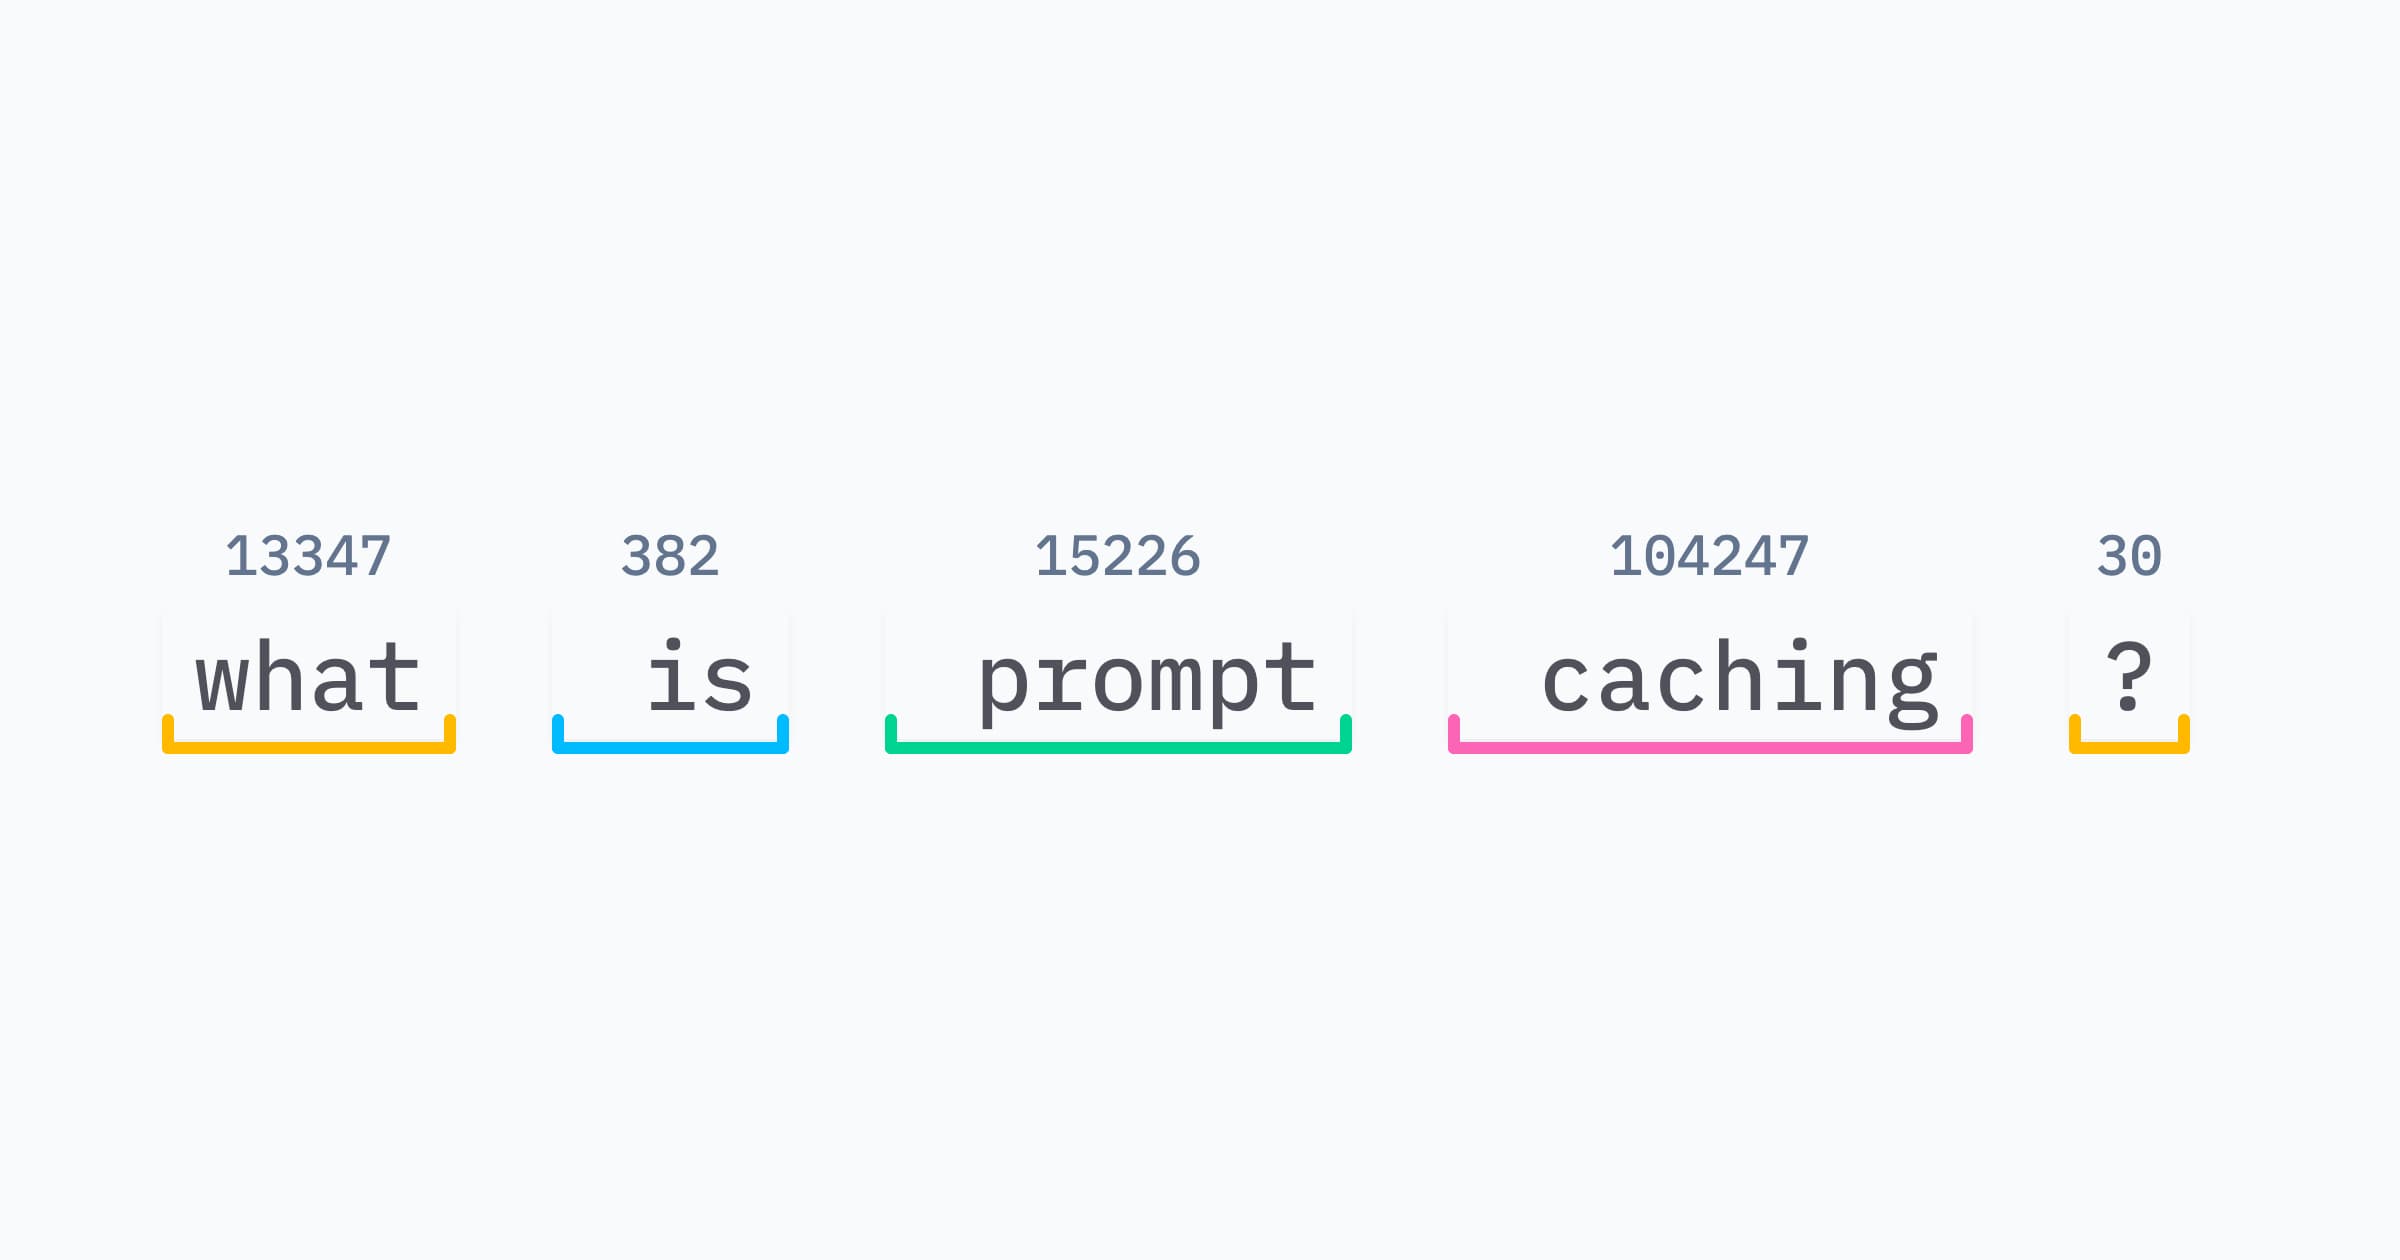
Prompt caching: 10x cheaper LLM tokens, but how? | ngrok blog
A far more detailed explanation of prompt caching than anyone asked for: how tokens, embeddings, and attention make cached LLM tokens 10x cheaper and faster.
Prompt caching: 10x cheaper LLM tokens, but how? | ngrok blog
A far more detailed explanation of prompt caching than anyone asked for: how tokens, embeddings, and attention make cached LLM tokens 10x cheaper and faster.
Your LLM Knows the Future: Uncovering Its Multi-Token Prediction Potential
Autoregressive language models are constrained by their inherently sequential nature, generating one token at a time. This paradigm limits inference speed and parallelism, especially during later stages of generation when the direction and semantics of text are relatively certain. In this work, we propose a novel framework that leverages the inherent knowledge of vanilla autoregressive language models about future tokens, combining techniques to realize this potential and enable simultaneous prediction of multiple subsequent tokens. Our approach introduces several key innovations: (1) a masked-input formulation where multiple future tokens are jointly predicted from a common prefix; (2) a gated LoRA formulation that preserves the original LLM's functionality, while equipping it for multi-token prediction; (3) a lightweight, learnable sampler module that generates coherent sequences from the predicted future tokens; (4) a set of auxiliary training losses, including a consistency loss, to enhance the coherence and accuracy of jointly generated tokens; and (5) a speculative generation strategy that expands tokens quadratically in the future while maintaining high fidelity. Our method achieves significant speedups through supervised fine-tuning on pretrained models. For example, it generates code and math nearly 5x faster, and improves general chat and knowledge tasks by almost 2.5x. These gains come without any loss in quality.

tokens are getting more expensive
"language models will get cheaper by 10x" will not save ai subscriptions from the short squeeze
The Bitter Lesson is coming for Tokenization
Highlights the desire to replace tokenization with a general method that better leverages compute and data. We'll see tokenization's fragility and review the Byte Latent Transformer arch.
State of AI 2025: 100T Token LLM Usage Study | OpenRouter
Read OpenRouter's 2025 State of AI report — an empirical 100 trillion token study of real LLM usage, model trends, and developer insights.
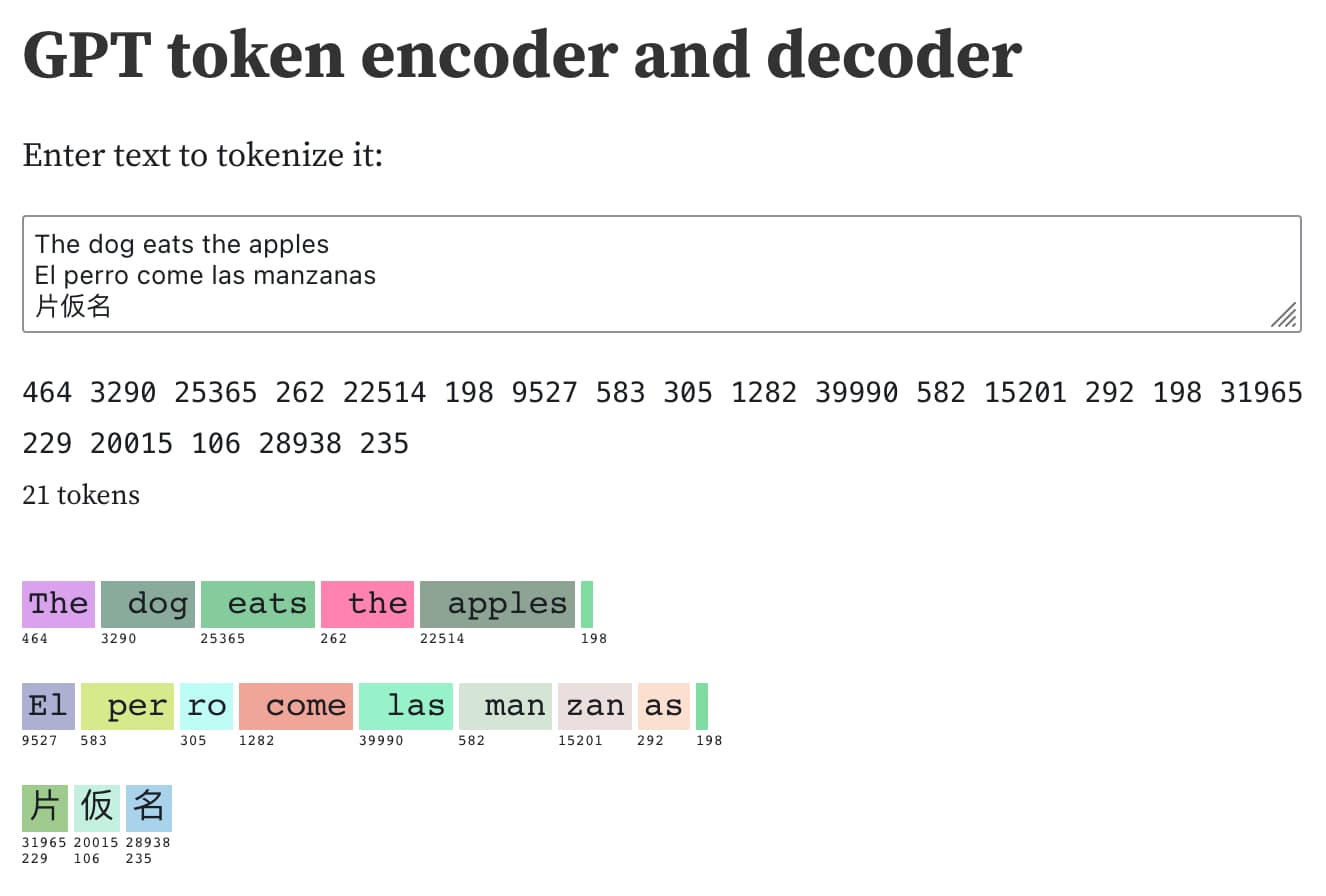
Understanding GPT tokenizers
Large language models such as GPT-3/4, LLaMA and PaLM work in terms of tokens. They take text, convert it into tokens (integers), then predict which tokens should come next. Playing …
localixai/tokendoctor
tokendoctor: the same Claude Code for up to 38% less. A Claude Code plugin that shows what your use overpays, fixes it with a diff you approve, and puts any change back. Runs on your machine.
We Measured the LLM Token Cost of 5 Frontend Frameworks: Angular Costs 38% More Than Svelte | HackerNoon
We measured the LLM token cost of 5 frontend frameworks on identical components. Svelte wins, Angular costs 38% more — and your AI bill feels it.

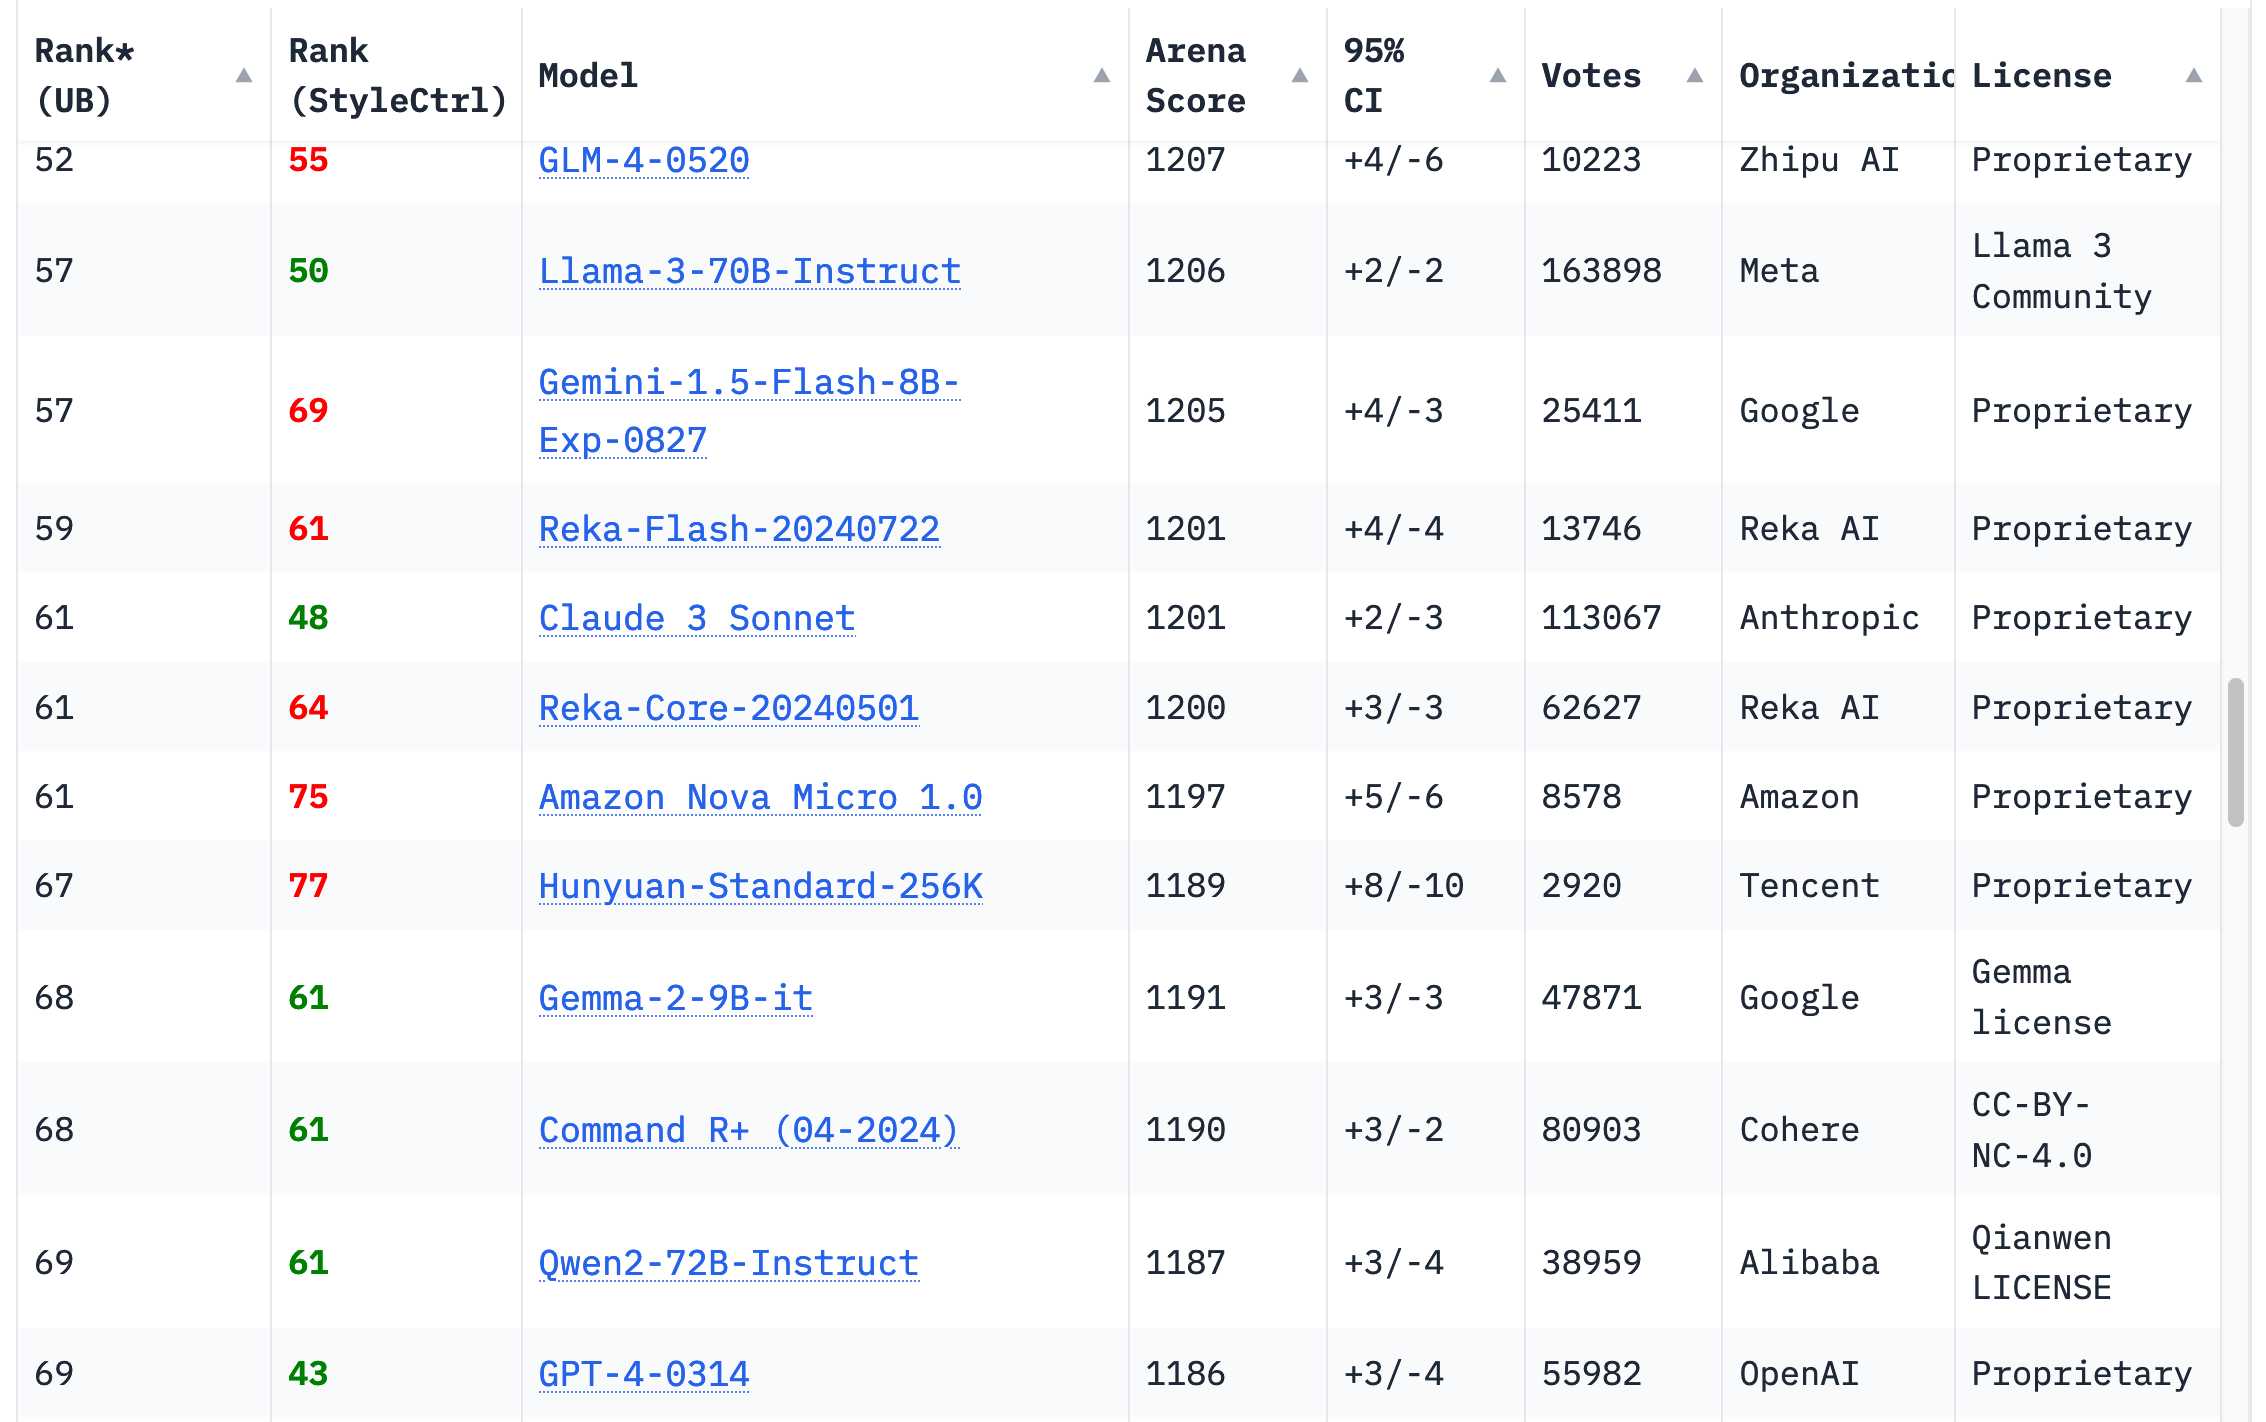
Things we learned about LLMs in 2024
A lot has happened in the world of Large Language Models over the course of 2024. Here’s a review of things we figured out about the field in the past …
Notes on how to use LLMs in your product.
Pretty much every company I know is looking for a way to benefit from Large Language Models. Even if their executives don’t see much applicability, their investors likely do, so they’re staring at the blank page nervously trying to come up with an idea. It’s straightforward to make an argument for LLMs improving internal efficiency somehow, but it’s much harder to describe a believable way that LLMs will make your product more useful to your customers.
Andrej Karpathy on Twitter / X
LLM Knowledge BasesSomething I'm finding very useful recently: using LLMs to build personal knowledge bases for various topics of research interest. In this way, a large fraction of my recent token throughput is going less into manipulating code, and more into manipulating…— Andrej Karpathy (@karpathy) April 2, 2026
Tokenization: A Survey for Modern NLP
While modern language models take raw text as their input and produce raw text as output, they do not operate over text directly. Hidden in the very first step of language model pipelines is...
something that has come up fairly recently with LLMs - for coding, specifically - is that it’s become a lot easier to burn stupefying amounts of tokens on stuff very fast, with agents running 24/7 or managing more agents (see: Yegge’s Gas Town) even with low inference costs that adds up in a hurry

Jesse Felder
‘While some cling to the promise of an AI “revolution,” the cost of adoption is proving a stubborn bottleneck. These developments also suggest that the economics of replacing human labor with AI may be more complicated than some early forecasts originally implied.’ fortune.com/2026/05/22/microsoft-ai-cost-…
