Multi-processor chips from GreenArrays are simple, practical, and affordable for many embedded and other applications.
Why Futhark?
A high-performance and high-level purely functional data-parallel array programming language that can execute on the GPU and CPU.
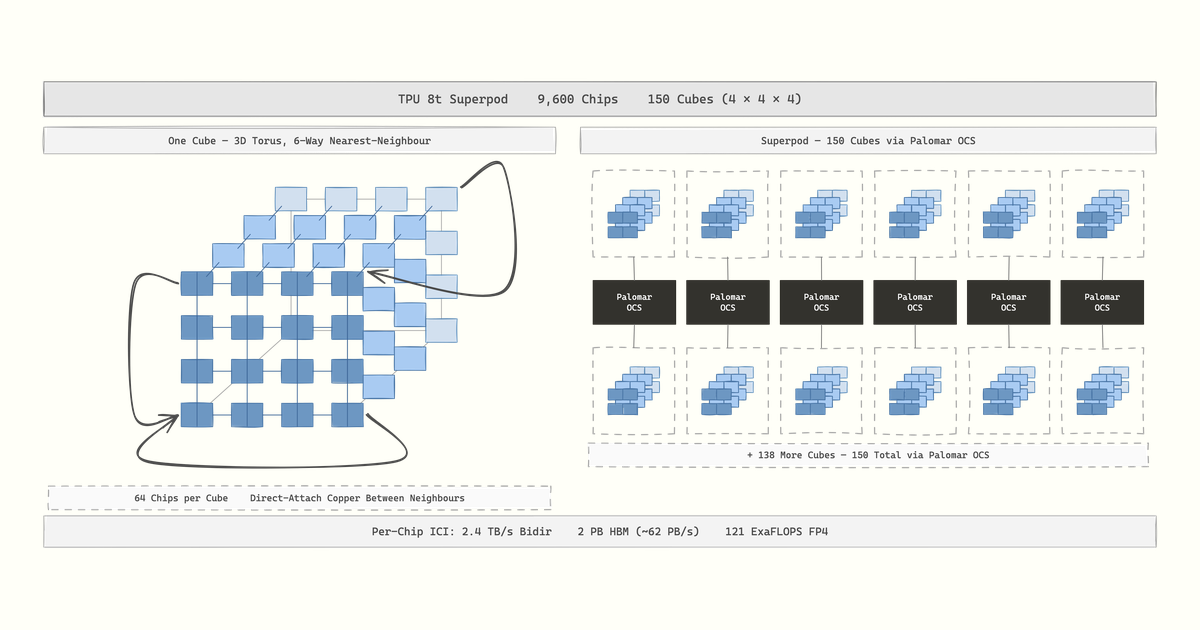
AI Chip Architectures
A look at AI Chip Architectures. NVIDIA, AMD, TPUs, Trainium, Groq, Cerebras.
Concurrent JavaScript: It can work!
With the recent addition of SharedArrayBuffer, concurrency is finding its way into the JavaScript language.
magnitudedev/magnitude
Open source inference engine that tunes its kernels on your hardware to find the fastest way to run each model. 2x faster than Ollama. Works on Apple Silicon, NVIDIA, AMD, Intel, or just a CPU.
vik on Twitter / X
Photon, our inference engine, isn't fast just because of GPU kernels. A lot of the speedup comes from engine-level work: request scheduling, prefix caching, image processing, all tuned to keep the GPU saturated. https://t.co/3M7eFcFKo5— vik (@vikhyatk) May 2, 2026
delftopenhardware/awesome-open-hardware
🛠Helpful items for making open source hardware projects.
Nvidia invests $5 billion into Intel to jointly develop PC and data center chips
Intel will help build x86 chips with Nvidia RTX GPU chiplets

0xSero on Twitter / X
I told y’all this is the move. Heterogenous hardware is the way forward. Large cheap pools of mixed memory + specialized accelerators (Nvidia GPUs, DGX Spark, Cerebras wafers) The next year will be dominated by solutions that split the stack. - 3000$ for a used Mac Studio… https://t.co/zMlScSnJ0X— 0xSero (@0xSero) April 1, 2026
qualcomm/nexa-sdk
Run frontier LLMs and VLMs with day-0 model support across GPU, NPU, and CPU, with comprehensive runtime coverage for PC (Python/C++), mobile (Android & iOS), and Linux/IoT (Arm64 & x86 Docker). Supporting OpenAI GPT-OSS, IBM Granite-4, Qwen-3-VL, Gemma-3n, Ministral-3, and more.
Chris Lattner on Twitter / X
Please don’t tell anyone: we aren’t just open sourcing all the models. We are doing the unspeakable: open sourcing all the gpu kernels too. Making them run on multivendor consumer hardware, and opening the door to folks who can beat our work.Plz keep it quiet, ok? 😉— Chris Lattner (@clattner_llvm) March 24, 2026
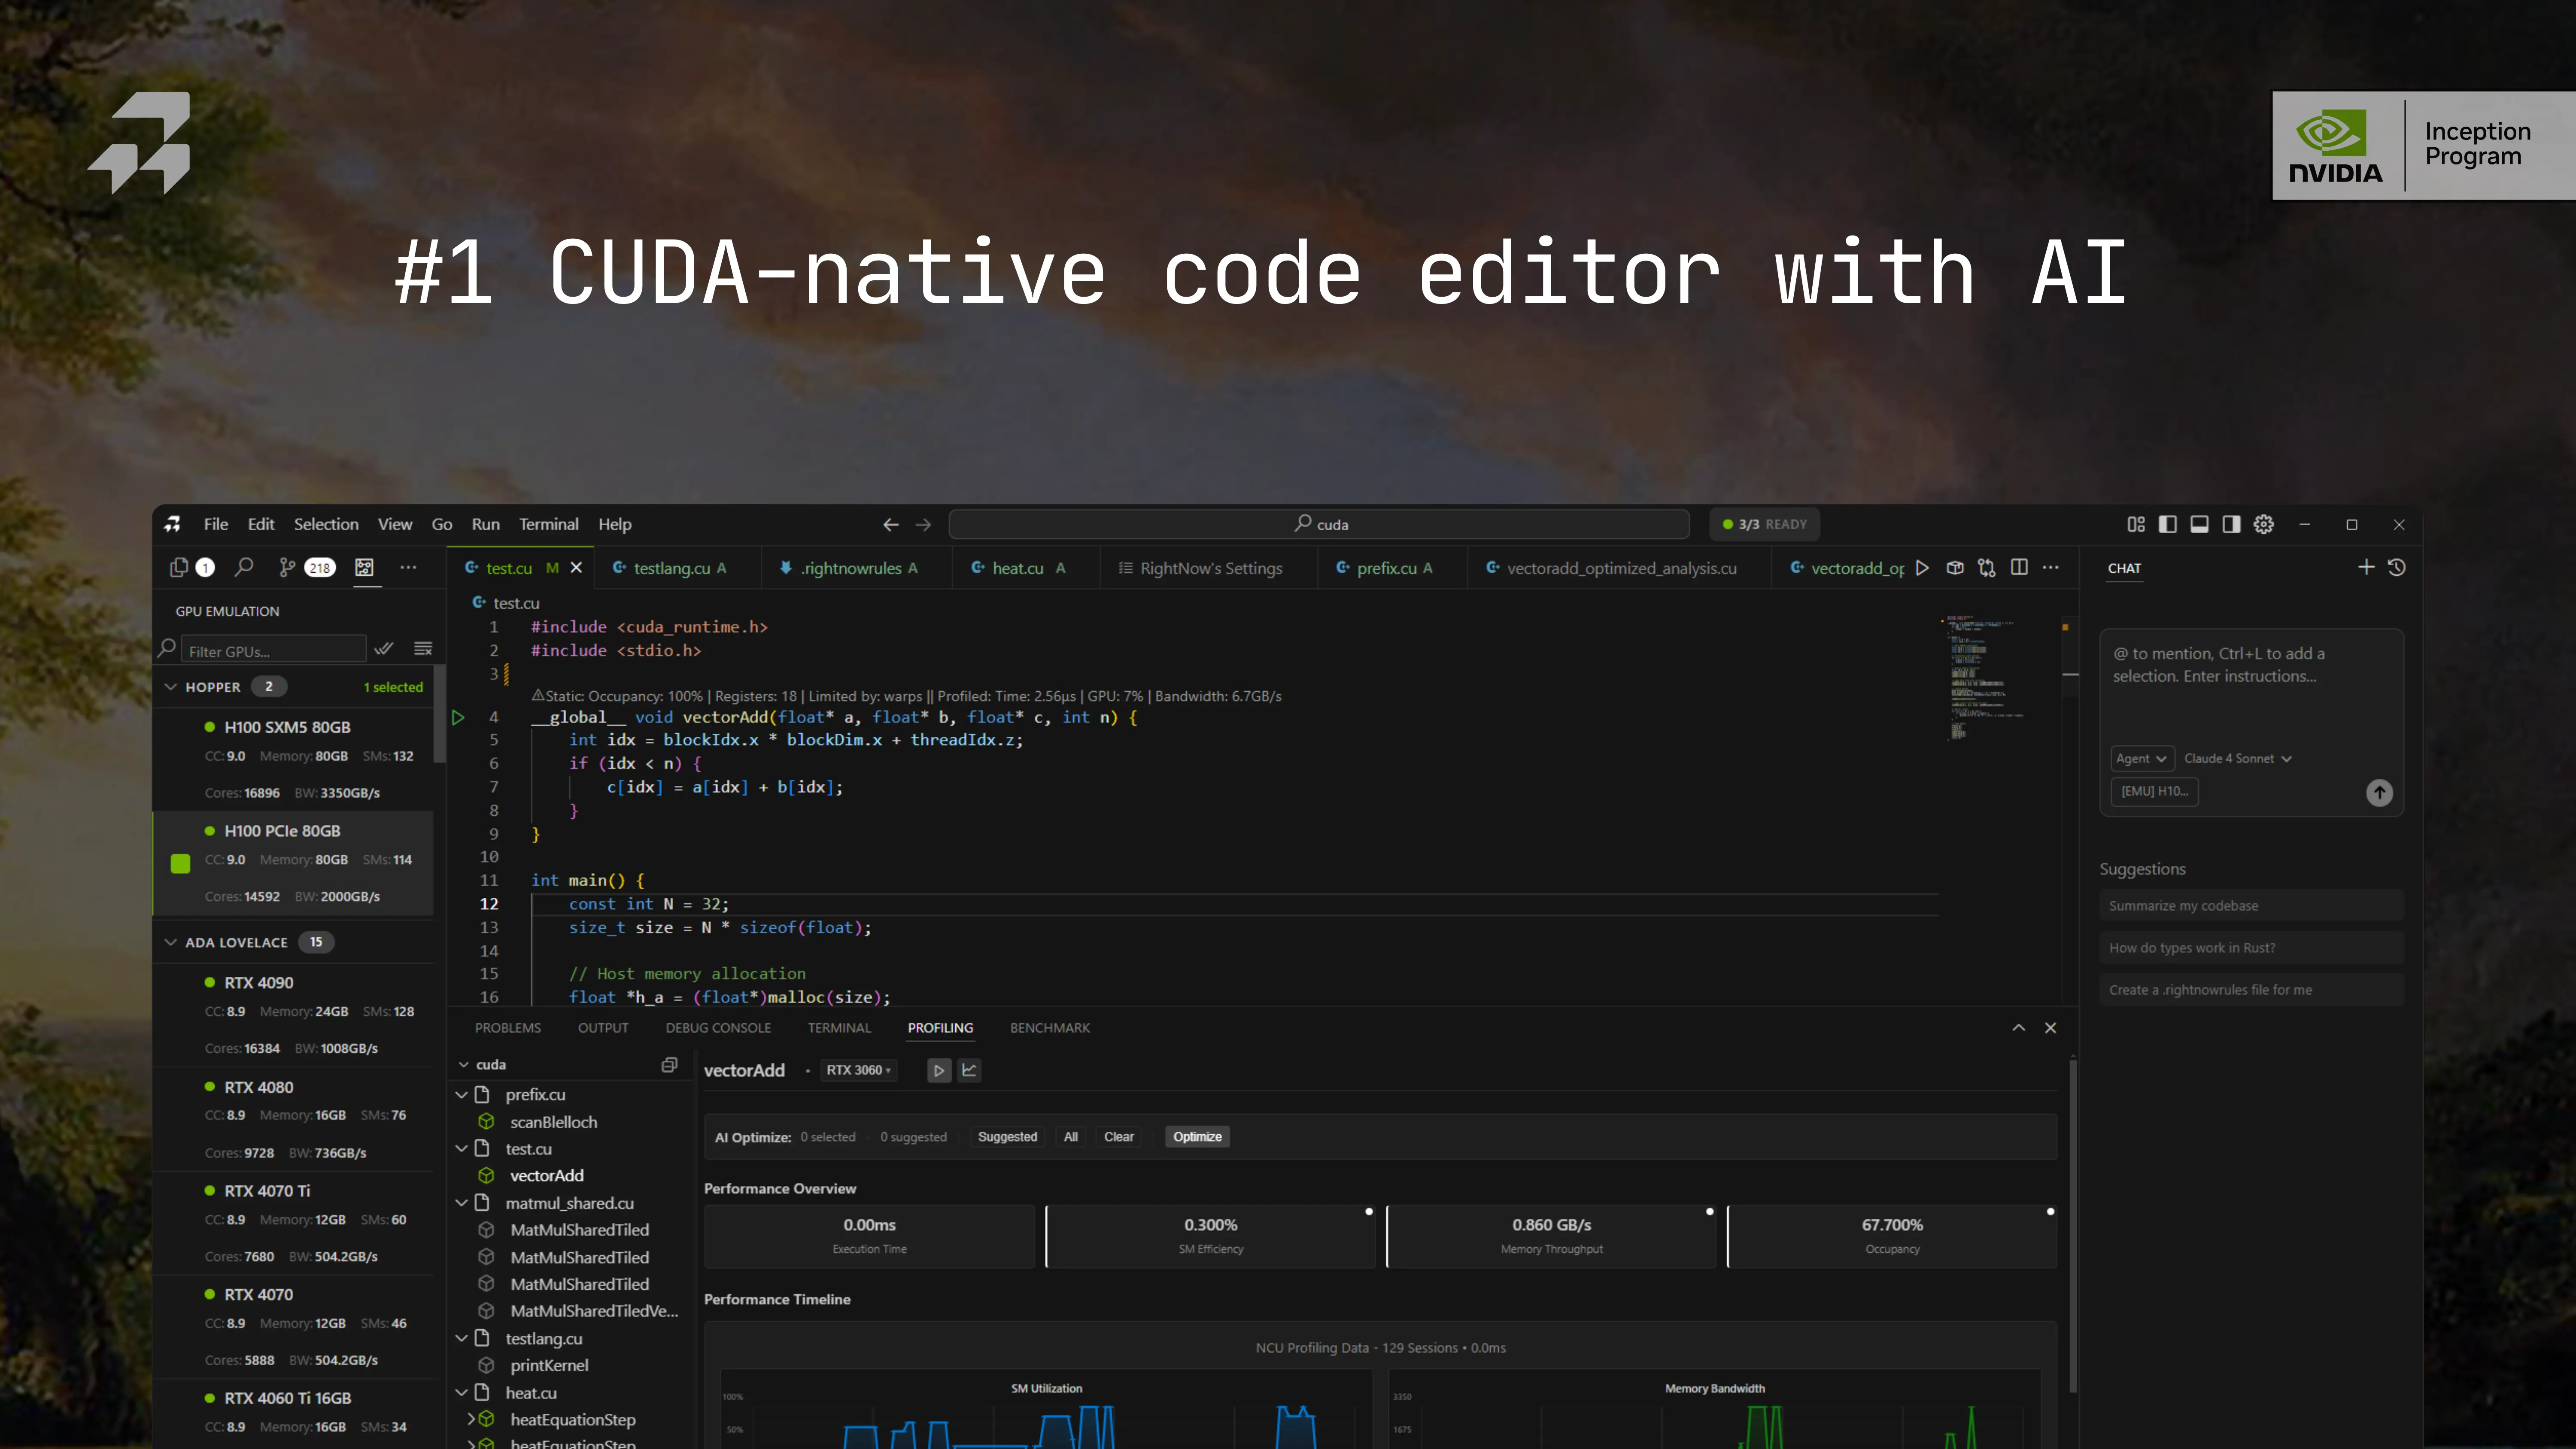
RightNow AI - YC-Backed GPU Research Lab
YC-backed GPU research lab building the RightNow CUDA editor, RunInfra inference infra, Forge kernels, and publishing AutoMegaKernel and related papers on arXiv.
Parallel Programming for FPGAs | Kastner Research Group
Parallel Programming for FPGAs is an open-source book aimed at teaching hardware and software developers how to efficiently program FPGAs using high-level synthesis (HLS). The authors developed the book as we noticed a lack of material aimed at teaching people to effectively use HLS tools.
The chips are down for Moore’s law
The semiconductor industry will soon abandon its pursuit of Moore's law. Now things could get a lot more interesting.
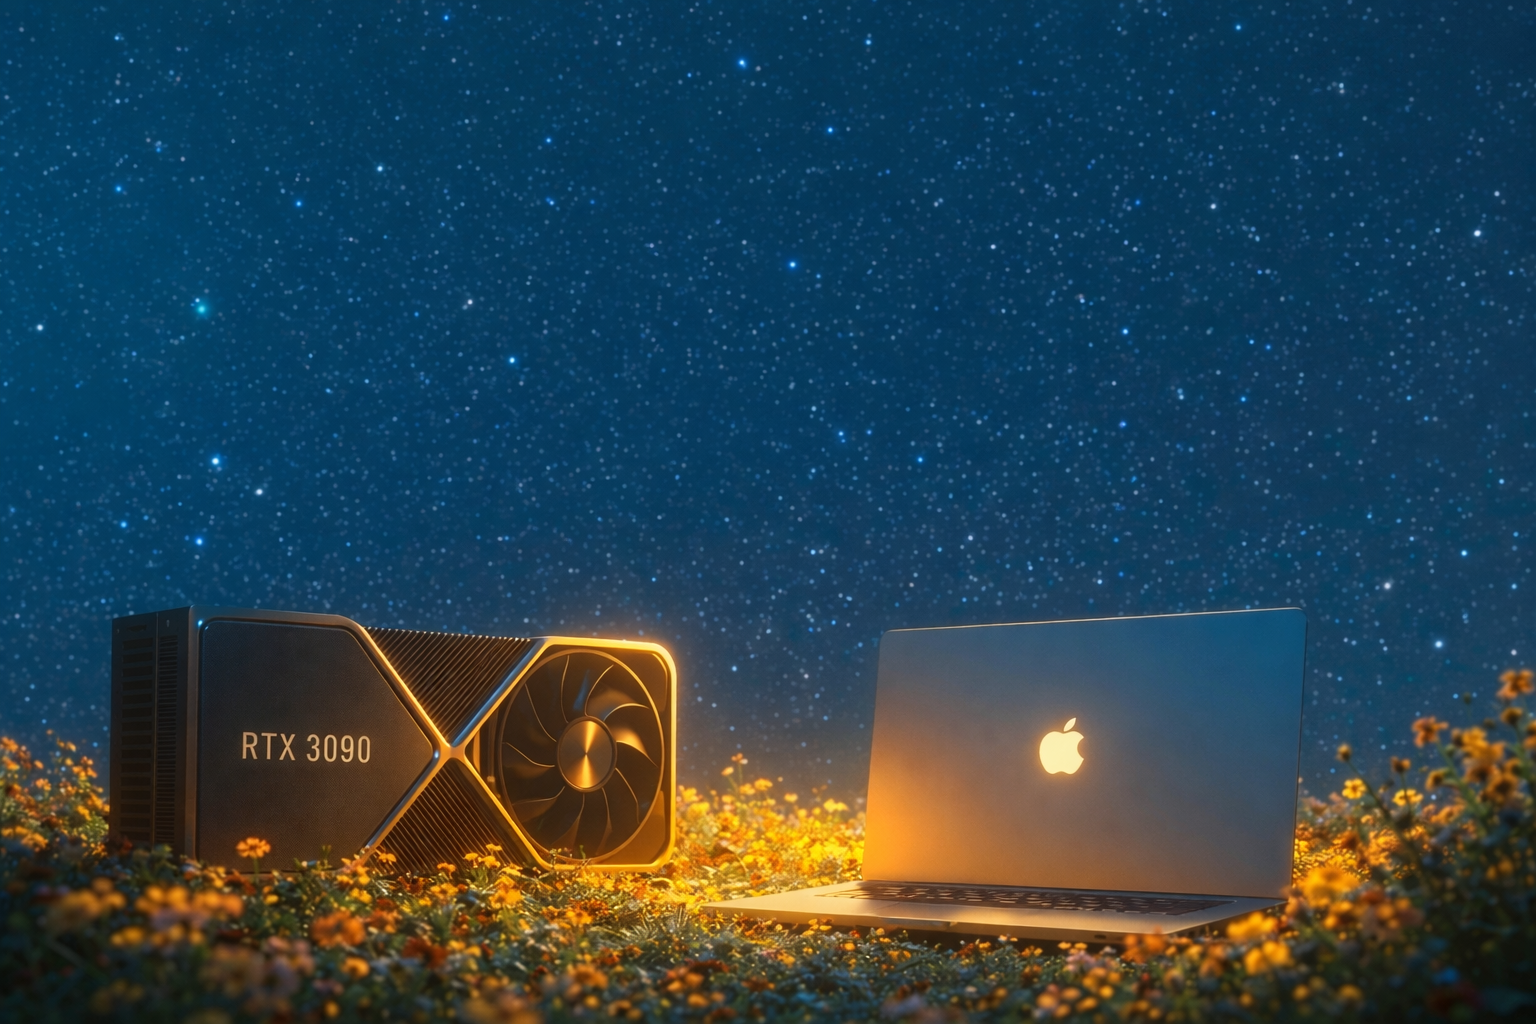
Megakernel: Matching Apple Silicon Efficiency at 2x the Throughput on a RTX 3090
The first megakernel for hybrid DeltaNet/Attention LLMs. 413 tok/s at 1.87 tok/J on a 2020 RTX 3090, matching M5 Max efficiency at 1.8x throughput.