Multi-processor chips from GreenArrays are simple, practical, and affordable for many embedded and other applications.
Why Futhark?
A high-performance and high-level purely functional data-parallel array programming language that can execute on the GPU and CPU.
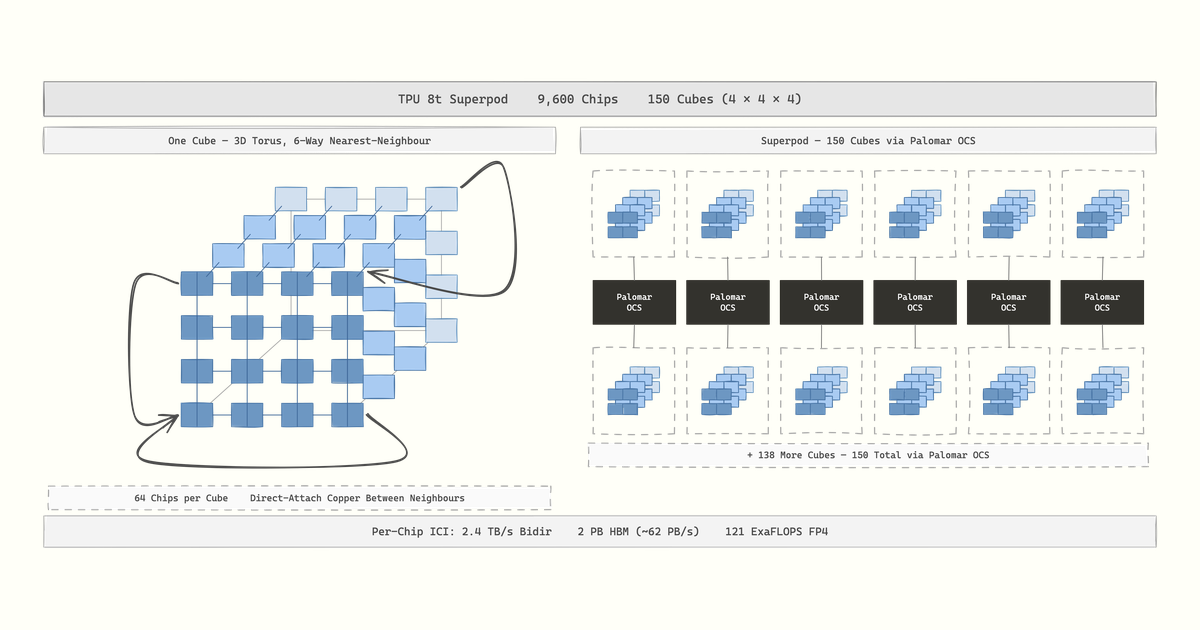
AI Chip Architectures
A look at AI Chip Architectures. NVIDIA, AMD, TPUs, Trainium, Groq, Cerebras.
vik on Twitter / X
Photon, our inference engine, isn't fast just because of GPU kernels. A lot of the speedup comes from engine-level work: request scheduling, prefix caching, image processing, all tuned to keep the GPU saturated. https://t.co/3M7eFcFKo5— vik (@vikhyatk) May 2, 2026
delftopenhardware/awesome-open-hardware
🛠Helpful items for making open source hardware projects.
Nvidia invests $5 billion into Intel to jointly develop PC and data center chips
Intel will help build x86 chips with Nvidia RTX GPU chiplets

0xSero on Twitter / X
I told y’all this is the move. Heterogenous hardware is the way forward. Large cheap pools of mixed memory + specialized accelerators (Nvidia GPUs, DGX Spark, Cerebras wafers) The next year will be dominated by solutions that split the stack. - 3000$ for a used Mac Studio… https://t.co/zMlScSnJ0X— 0xSero (@0xSero) April 1, 2026
qualcomm/nexa-sdk
Run frontier LLMs and VLMs with day-0 model support across GPU, NPU, and CPU, with comprehensive runtime coverage for PC (Python/C++), mobile (Android & iOS), and Linux/IoT (Arm64 & x86 Docker). Supporting OpenAI GPT-OSS, IBM Granite-4, Qwen-3-VL, Gemma-3n, Ministral-3, and more.
Chris Lattner on Twitter / X
Please don’t tell anyone: we aren’t just open sourcing all the models. We are doing the unspeakable: open sourcing all the gpu kernels too. Making them run on multivendor consumer hardware, and opening the door to folks who can beat our work.Plz keep it quiet, ok? 😉— Chris Lattner (@clattner_llvm) March 24, 2026
RightNow AI - YC-Backed GPU Research Lab
YC-backed GPU research lab building the RightNow CUDA editor, RunInfra inference infra, Forge kernels, and publishing AutoMegaKernel and related papers on arXiv.
Parallel Programming for FPGAs | Kastner Research Group
Parallel Programming for FPGAs is an open-source book aimed at teaching hardware and software developers how to efficiently program FPGAs using high-level synthesis (HLS). The authors developed the book as we noticed a lack of material aimed at teaching people to effectively use HLS tools.
Megakernel: Matching Apple Silicon Efficiency at 2x the Throughput on a RTX 3090
The first megakernel for hybrid DeltaNet/Attention LLMs. 413 tok/s at 1.87 tok/J on a 2020 RTX 3090, matching M5 Max efficiency at 1.8x throughput.
clandestine.eth 🦇🔊 on Twitter / X
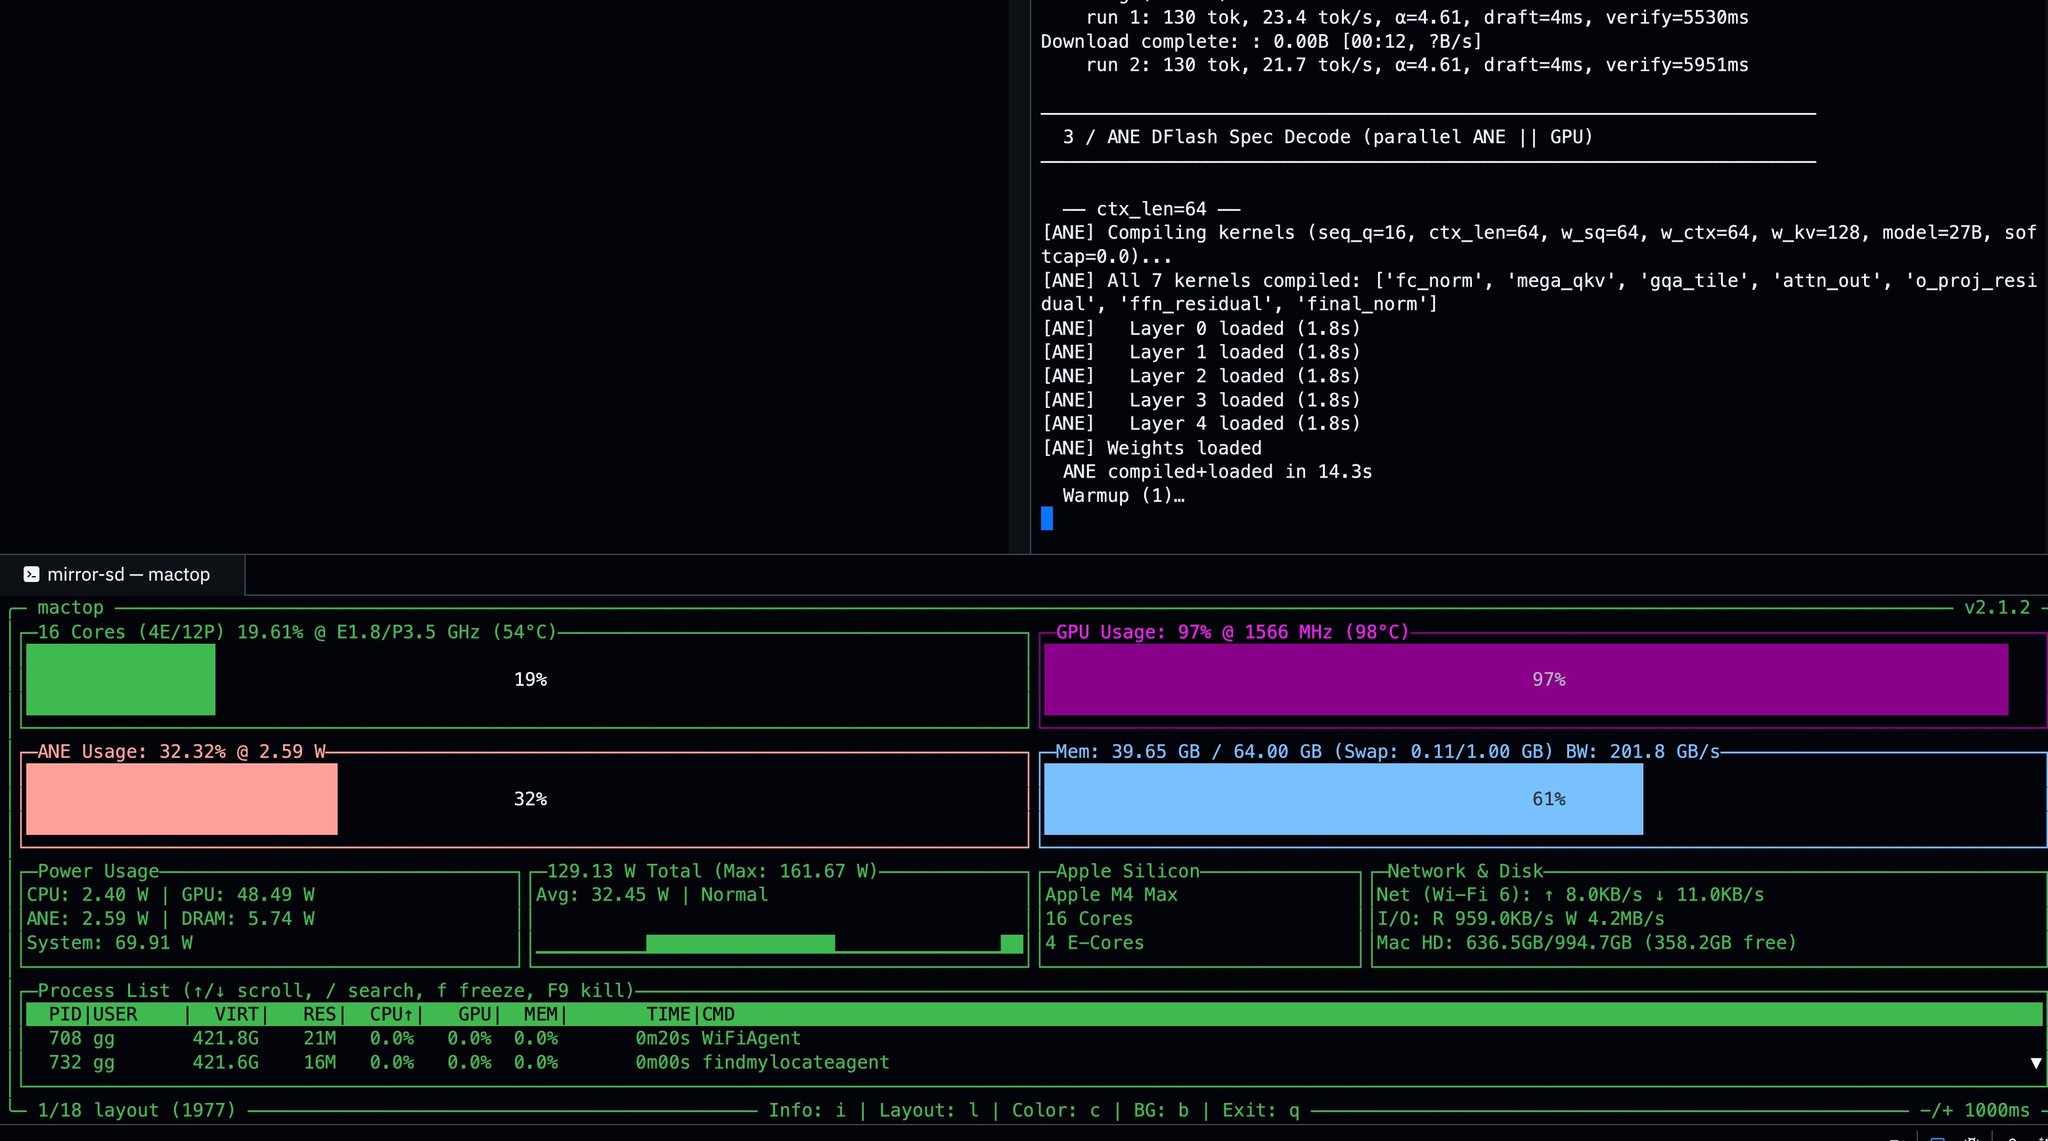
Heterogeneous acceleration on Apple Silicon achieved.ANE + GPU running in parallel.Mirror SD with DFlash, ported to MLX — targeting ANE + GPU simultaneously.The M-series was designed for this. We just hadn't unlocked it yet. pic.twitter.com/raSH0CMN4V— clandestine.eth 🦇🔊 (@0xClandestine) April 15, 2026
exabox preorder
This is a fully refundable preorder for an exabox and will be credit on the purchase price. The full purchase price will be close to $10M, so do not buy if that's not your budget for AI compute! The details of the product aren't fully finalized yet, but the basics are this.It's a 20ft shipping container that needs a megawatt of power, 208V or 415V three phase (so 208-240 line). It will be self contained for cooling and weatherproof. Supported temperature and humidity ranges TBD.Like tinyboxes, it will come in both red and green. After you place a preorder, we can discuss what specific GPUs you want. The price will be under $10M and it will have about an exaflop of compute. And just like tinybox, it's 100% ready to run with tinygrad, PyTorch and others. At launch, it should be the absolute best bang for your buck at the price point with respect to FLOPS/$, GB/$ and GB/s/$.The whole box will be connected at at least 400 Gbps and is capable of training as one unit. At 50% MFU, it can do 3e24 (Kimi sized) training runs in 10 weeks. With tinygrad software, it will function as one big GPU, but it is made up of normal computers and you can also use PyTorch.This is ~1% of the purchase price and guarantees your spot in line. We should ship our first exabox Q2 or Q3 of 2027.

Ollama is now powered by MLX on Apple Silicon in preview· Ollama Blog
Today, we're previewing the fastest way to run Ollama on Apple silicon, powered by MLX, Apple's machine learning framework.