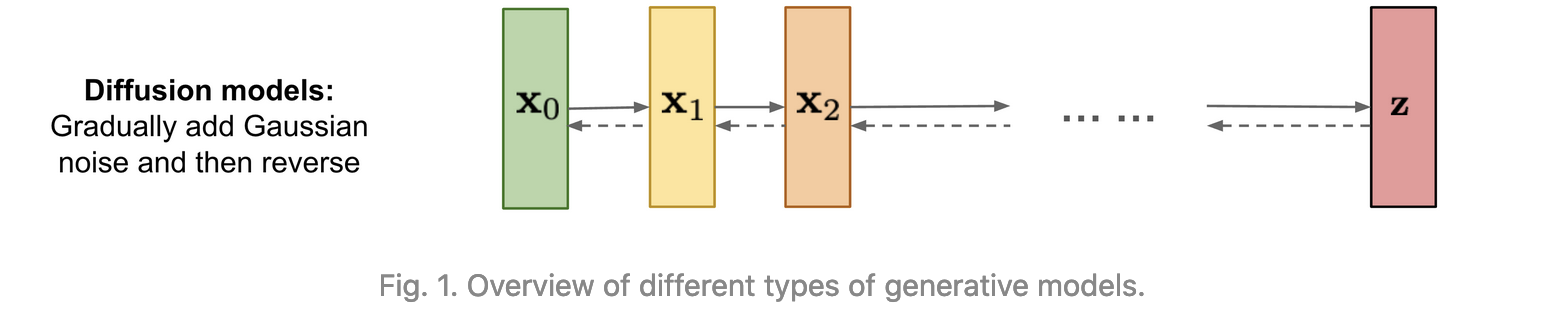
Diffusion models are generative models that “diffuse” training data with random noise, then learn to reverse the diffusion process to output new images.
Diffusion model
In machine learning, diffusion models, also known as diffusion-based generative models or score-based generative models, are a class of latent variable generative models. A diffusion model consists of two major components: the forward diffusion process, and the reverse sampling process.[1] The goal of diffusion models is to learn a diffusion process for a given dataset, such that the process can generate new elements that are distributed similarly as the original dataset. A diffusion model models data as generated by a diffusion process, whereby a new datum performs a random walk with drift through the space of all possible data.[2] A trained diffusion model can be sampled in many ways, with different efficiency and quality.
The physics behind diffusion models
Diffusion Models: A Comprehensive Survey of Methods and Applications
Diffusion models have emerged as a powerful new family of deep generative models with record-breaking performance in many applications, including image synthesis, video generation, and molecule...

How Stable Diffusion works
Understand in a simple way how Stable Diffusion transforms a few words into a spectacular image.

Optimal and Diffusion Transports in Machine Learning
Slides for a general introduction to the use of Optimal Transport methods in learning, with an emphasis on diffusion models, flow matching, training 2 l…

Stanford CS25: V5 I Transformers in Diffusion Models for Image Generation and Beyond
mlx-examples/stable_diffusion at main · ml-explore/mlx-examples
Examples in the MLX framework. Contribute to ml-explore/mlx-examples development by creating an account on GitHub.
Complete guide to samplers in Stable Diffusion
Dive into the world of Stable Diffusion samplers and unlock the potential of image generation.

Introducing OUI-1: world's first model for Generative UI
A DiffusionGemma finetune at 71.7% on the Generative UI Benchmark, 5.5x its base.
Continuous diffusion language models
Fully discrete methods dominated for a few years, but language models based on continuous diffusion are making a comeback.
Continuous diffusion language models
Fully discrete methods dominated for a few years, but language models based on continuous diffusion are making a comeback.
Towards Understanding Text Hallucination of Diffusion Models via Local Generation Bias
Score-based diffusion models have achieved incredible performance in generating realistic images, audio, and video data. While these models produce high-quality samples with impressive details, they often introduce unrealistic artifacts, such as distorted fingers or hallucinated texts with no meaning. This paper focuses on textual hallucinations, where diffusion models correctly generate individual symbols but assemble them in a nonsensical manner. Through experimental probing, we consistently observe that such phenomenon is attributed it to the network's local generation bias. Denoising networks tend to produce outputs that rely heavily on highly correlated local regions, particularly when different dimensions of the data distribution are nearly pairwise independent. This behavior leads to a generation process that decomposes the global distribution into separate, independent distributions for each symbol, ultimately failing to capture the global structure, including underlying grammar. Intriguingly, this bias persists across various denoising network architectures including MLP and transformers which have the structure to model global dependency. These findings also provide insights into understanding other types of hallucinations, extending beyond text, as a result of implicit biases in the denoising models. Additionally, we theoretically analyze the training dynamics for a specific case involving a two-layer MLP learning parity points on a hypercube, offering an explanation of its underlying mechanism.
Some notes on the Stable Diffusion safety filter
How deep learning models are moderated
DiffusionGemma as Jev: Open-Source vLLM Patch (2026) | explainx.ai Blog
A vLLM contributor built an open-source Jev clone using DiffusionGemma — roughly matching TypeSafe's proprietary model on accuracy.
The Curse of Recursion: Training on Generated Data Makes Models Forget
Stable Diffusion revolutionised image creation from descriptive text. GPT-2, GPT-3(.5) and GPT-4 demonstrated astonishing performance across a variety of language tasks. ChatGPT introduced such...
Research – Inception
We are leveraging diffusion technology to develop a new generation of LLMs. Our dLLMs are much faster and more efficient than traditional autoregressive LLMs.