


Mercury 3 is the most capable diffusion LLM released to date. It outperforms GPT-6 Luna and Claude Haiku 5.5 while running 4–8x faster at 1,000+ tokens per second.
Introducing Mercury 2.5 – Inception
Mercury 2.5 is the most capable diffusion LLM on the market. It runs at 1,107 tokens/sec and offers a 40% increase in intelligence over Mercury 2, comparable to cost-optimized frontier models.

Research – Inception
We are leveraging diffusion technology to develop a new generation of LLMs. Our dLLMs are much faster and more efficient than traditional autoregressive LLMs.
LLMs Can Now Write GPU Kernels That Beat torch.compile - Break AI Scaling Limits in 7 Days
We're now seeing multi-agent systems that take your PyTorch code and produce CUDA or Triton kernels with 2x to 14x speedups over torch.compile(mode='max-autotune-no-cudagraphs'). Not on toy benchmarks. On real models like Llama-3.1-8B, Whisper, and Stable Diffusion. Learn proven techniques to shift the scaling law intercept and achieve 10-50% performance gains.
clem 🤗 on Twitter / X
The main breakthrough of GPT-5 was to route your messages between a couple of different models to give you the best, cheapest & fastest answer possible.This is cool but imagine if you could do this not only for a couple of models but hundreds of them, big and small, fast and… pic.twitter.com/ww2ApYTN3D— clem 🤗 (@ClementDelangue) October 17, 2025
The Ultimate Guide to Fine-Tuning LLMs from Basics to Breakthroughs: An Exhaustive Review of Technologies, Research, Best Practices, Applied Research Challenges and Opportunities (Version 1.0)
DiffusionGemma as Jev: Open-Source vLLM Patch (2026) | explainx.ai Blog
A vLLM contributor built an open-source Jev clone using DiffusionGemma — roughly matching TypeSafe's proprietary model on accuracy.
LLM Leaderboard 2026 — Compare Top AI Models
Compare the latest LLM benchmarks for GPT, Claude, Gemini and more. Updated rankings across reasoning, coding, math, and multilingual tasks with pricing and speed data.
There continue to be reasons for software to be slow
A discussion on the various reasons why performance is slow, and which ones are unlikely to be affected by LLMs. Originally written as a counter-point to Dan Luu
LLaDA - Large Language Diffusion Models
LLaDA is a diffusion model with an unprecedented 8B scale, rivaling LLaMA3 8B in performance.
576 - Using LLMs at Oxide | RFD | Oxide
Large language models (LLMs) are an indisputable breakthrough of the last five years, potentially profoundly changing the way that we work. As with any extraordinarily powerful tool, LLM use has both promise and peril — and that they are so general-purpose leaves real questions about how and when they should be used. The landscape is shifting so rapidly that static prescription is unlikely — but that LLMs are evolving so quickly also gives urgency to the question: how should LLMs be used at Oxide?
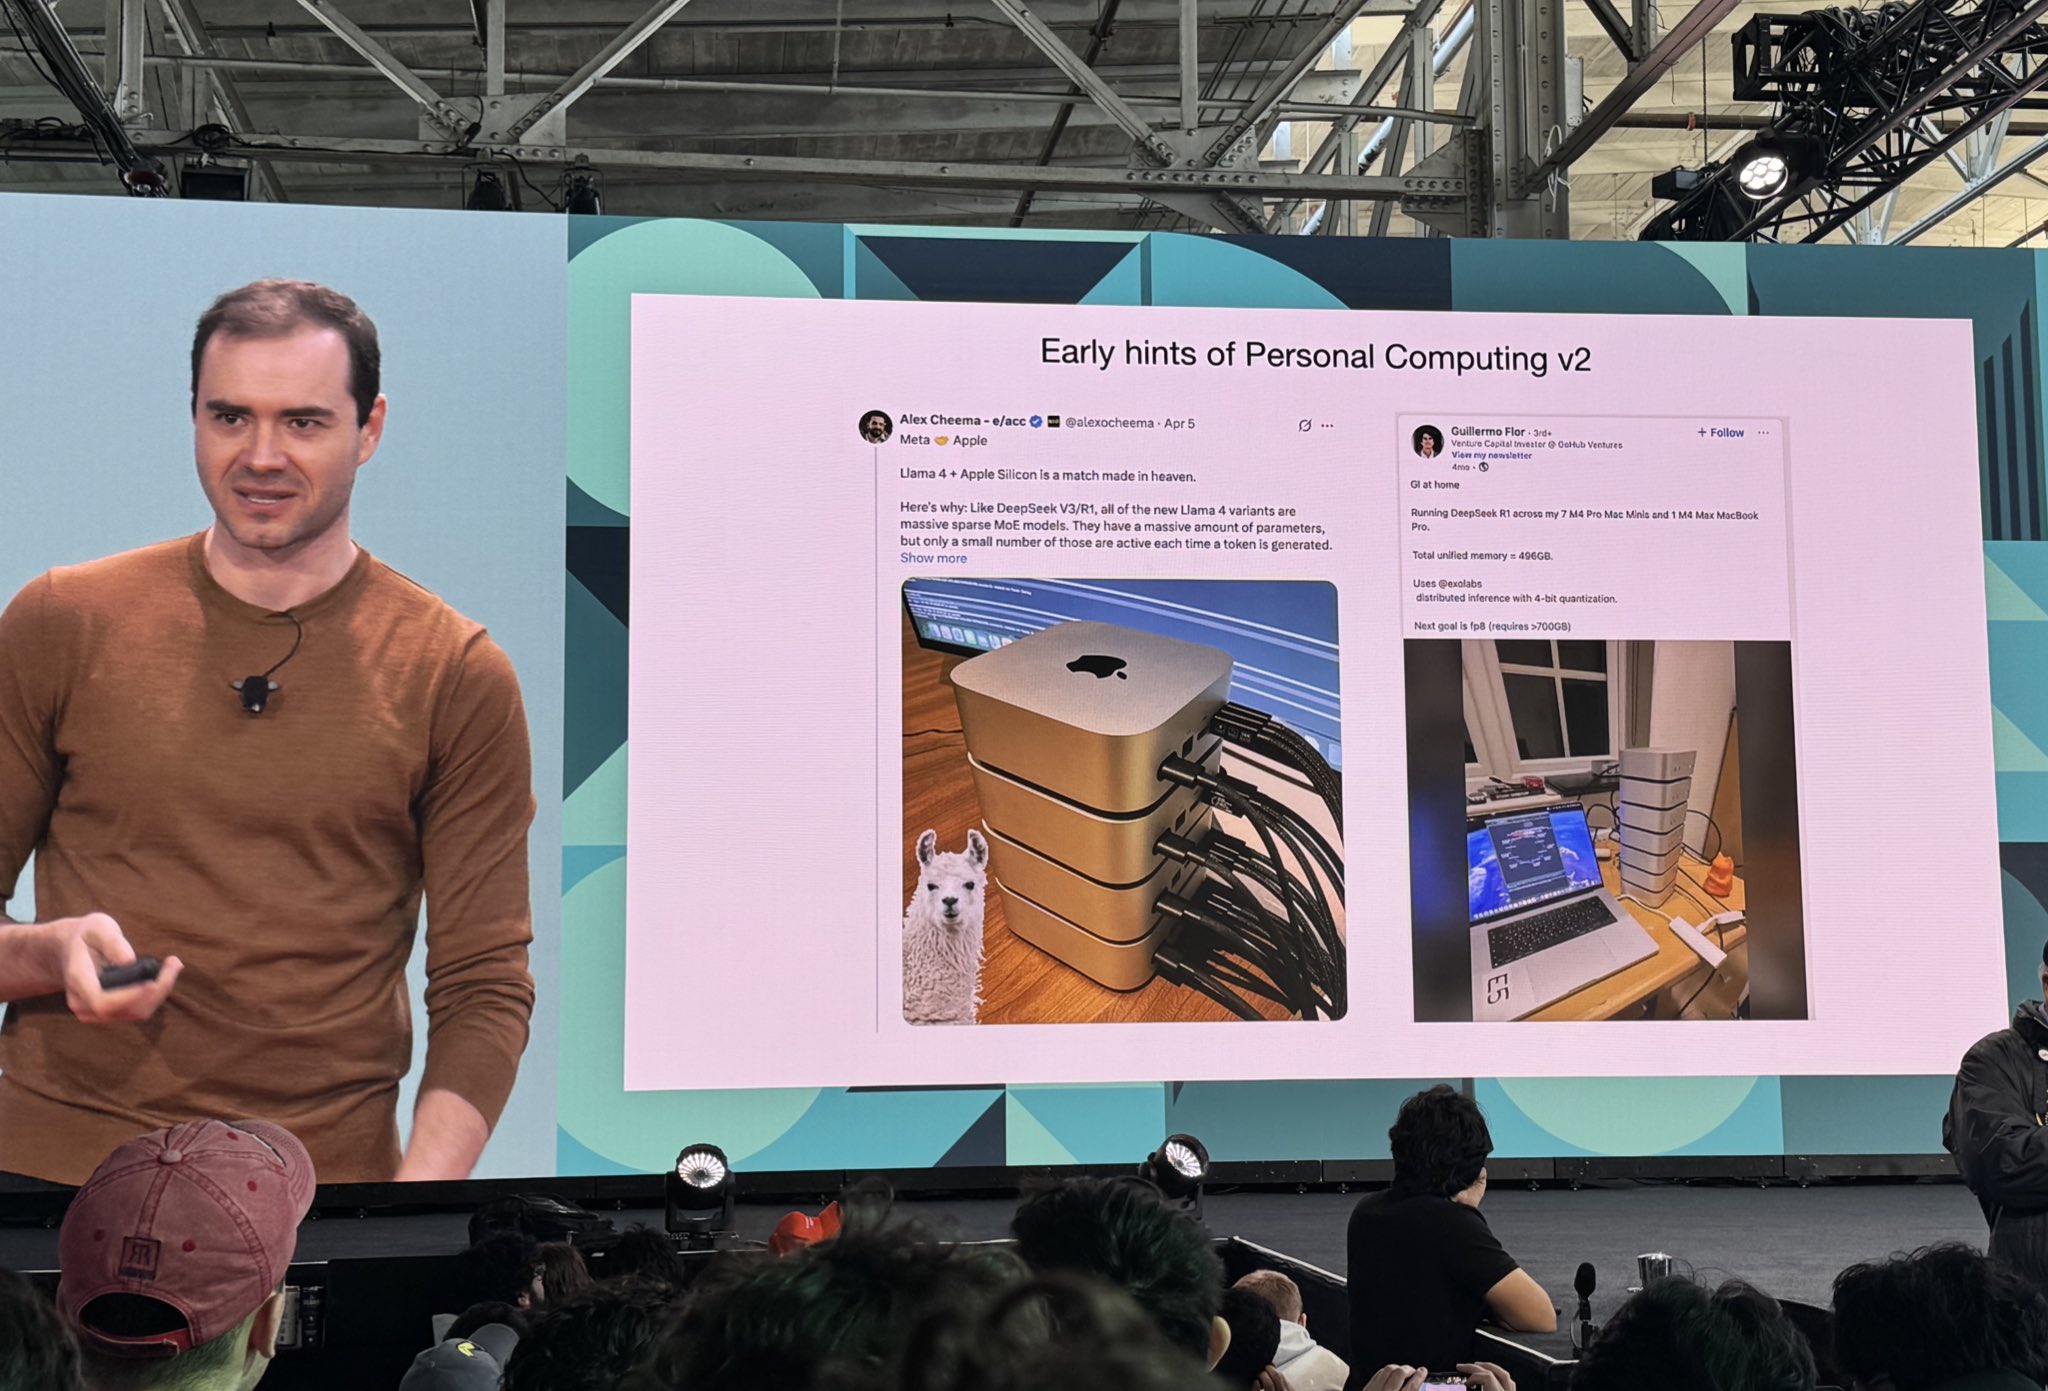
Alex Cheema on Twitter / X
.@karpathy shouted out my work on @exolabs at @ycombinator AI SUS!“we use LLMs similarly to mainframes in the ‘70s - compute is timeshared by having a slice in the batch dimension. models will compress over time, and with this we’ll be able to run more on-device” pic.twitter.com/UKSrquQGAL— Alex Cheema (@alexocheema) June 18, 2025
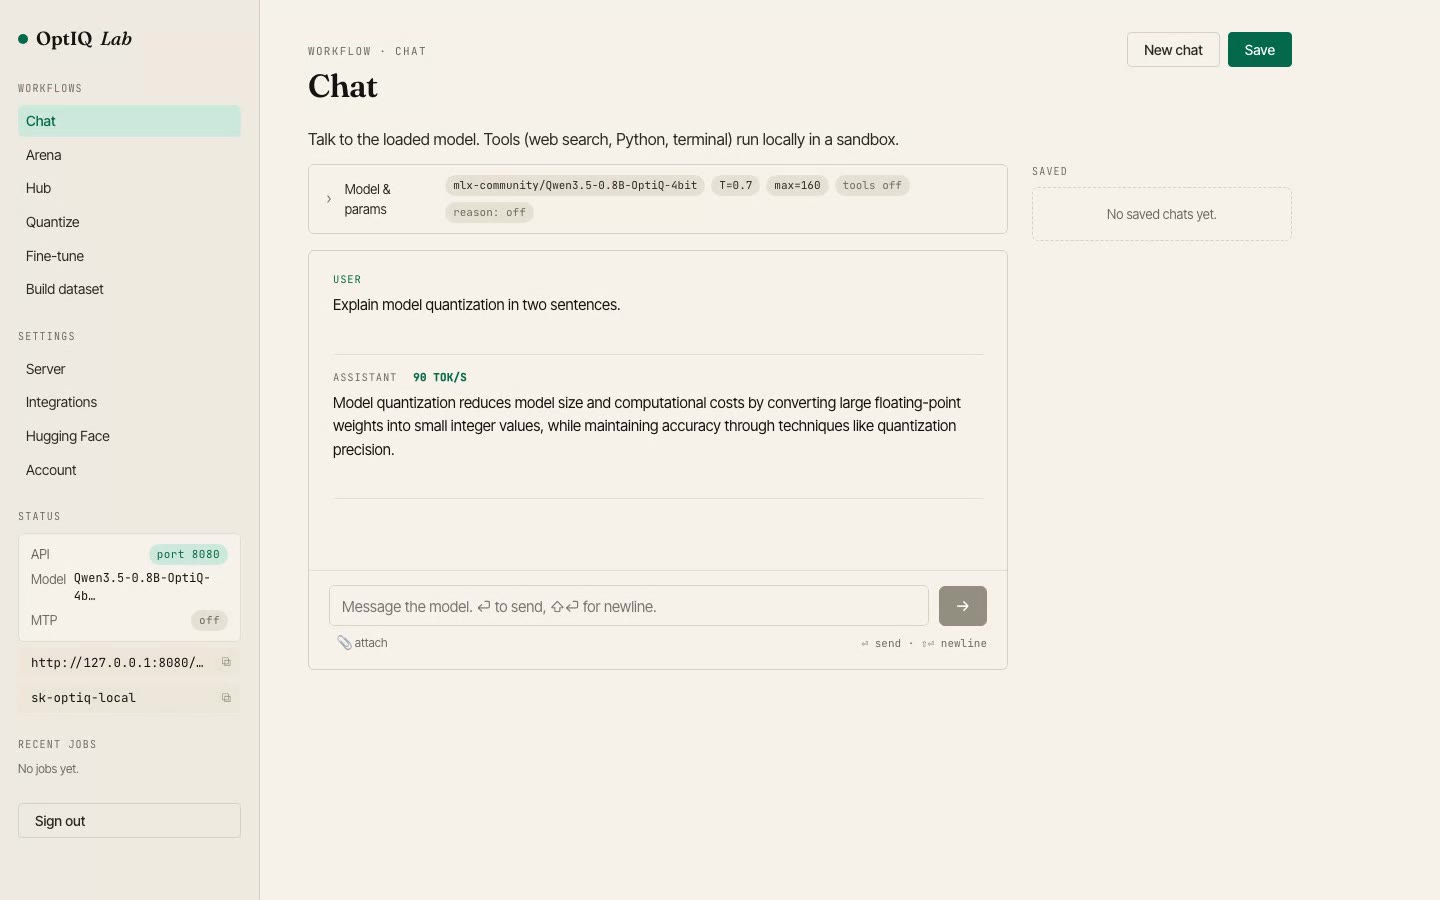
Run LLMs locally on your Mac · mlx-optiq
Quantize, fine-tune and serve LLMs locally on Apple Silicon. MLX-native, no PyTorch, no cloud. On PyPI.
distil labs – Cut LLM Costs by 80% with Custom SLMs
Your LLM costs are eating your product margins. distil labs trains a specialized model layer on your workload and serves it behind one OpenAI-compatible endpoint.
The Curse of Recursion: Training on Generated Data Makes Models Forget
Stable Diffusion revolutionised image creation from descriptive text. GPT-2, GPT-3(.5) and GPT-4 demonstrated astonishing performance across a variety of language tasks. ChatGPT introduced such...

"GPT 話你知": Thoses tasks surpassed by LLMs - Blog - Qingyu✨'s blog
We are publishing a list of QOJ problems for which LLMs, mostly GPT, have found solutions that are significantly faster than the authors’ intended solutions. If you would like to submit additional problems for inclusion in this list, please write an editorial on QOJ in the problem forum, mark it as anonymous, and leave a comment below.