

Linkup Research releases SPARSEUP, an open-source sparse embedding model under 150M parameters. SOTA on BEIR-13, sub-millisecond retrieval, Apache 2.0 license.
Fast Embeddings on GPUs
Fast and accurate search is vital to all of Perplexity, from Search and Computer to our API Platform. Behind the scenes, the heavy lifting is done by embedding

The Beginner’s Guide to Text Embeddings & Techniques | deepset Blog
Text embeddings represent human language to computers, enabling tasks like semantic search. Here, we introduce sparse and dense vectors in a non-technical way.

Precise Zero-Shot Dense Retrieval without Relevance Labels
While dense retrieval has been shown effective and efficient across tasks and languages, it remains difficult to create effective fully zero-shot dense retrieval systems when no relevance label is available. In this paper, we recognize the difficulty of zero-shot learning and encoding relevance. Instead, we propose to pivot through Hypothetical Document Embeddings~(HyDE). Given a query, HyDE first zero-shot instructs an instruction-following language model (e.g. InstructGPT) to generate a hypothetical document. The document captures relevance patterns but is unreal and may contain false details. Then, an unsupervised contrastively learned encoder~(e.g. Contriever) encodes the document into an embedding vector. This vector identifies a neighborhood in the corpus embedding space, where similar real documents are retrieved based on vector similarity. This second step ground the generated document to the actual corpus, with the encoder's dense bottleneck filtering out the incorrect details. Our experiments show that HyDE significantly outperforms the state-of-the-art unsupervised dense retriever Contriever and shows strong performance comparable to fine-tuned retrievers, across various tasks (e.g. web search, QA, fact verification) and languages~(e.g. sw, ko, ja).

EmbeddingGemma: Powerful and Lightweight Text Representations
We introduce EmbeddingGemma, a new lightweight, open text embedding model based on the Gemma 3 language model family. Our innovative training recipe strategically captures knowledge from larger models via encoder-decoder initialization and geometric embedding distillation. We improve model robustness and expressiveness with a spread-out regularizer, and ensure generalizability by merging checkpoints from varied, optimized mixtures. Evaluated on the Massive Text Embedding Benchmark (MTEB) across multilingual, English, and code domains, EmbeddingGemma (300M) achieves state-of-the-art results. Notably, it outperforms prior top models, both proprietary and open, with fewer than 500M parameters, and provides performance comparable to models double its size, offering an exceptional performance-to-cost ratio. Remarkably, this lead persists when quantizing model weights or truncating embedding outputs. This makes EmbeddingGemma particularly well-suited for low-latency and high-throughput use cases such as on-device applications. We provide ablation studies exploring our key design choices. We release EmbeddingGemma to the community to promote further research.
Web Tiles as the base for Lexicon Embeds
Yeah this would be absolutely fantastic. I don’t see yet how the Bsky app would discover which embed to use for a linked record but I assume some sort of definition in the actual record? Anyway, hope to read more about this
Introduction
A complete search engine and RAG pipeline in your browser, server or edge network with support for full-text, vector, and hybrid search in less than 2kb.
DASL: RASL — Retrieval of Arbitrary Structures & Links
RASL is a URL scheme used to identify content-addressed DASL resources along with a simple HTTP-based retrieval method.
Benchmarking Subquadratic’s latest model & SSA Kernel | Appen
56× faster than FlashAttention-2 at 1M tokens. Independent efficiency, retrieval, and SWE-Bench benchmark of sparse self-attention. Download the full report.
turbopuffer: fast search on object storage
Inaugural blog post about the development of turbopuffer, a search engine that uses object storage and SSD caching for cost-effective, low latency search. This post describes into the motivation behind its creation, its unique architecture, and how it significantly reduces costs for large-scale vector searches. Discover how turbopuffer is transforming search infrastructure for companies like Cursor and Suno, offering a scalable and reliable solution.
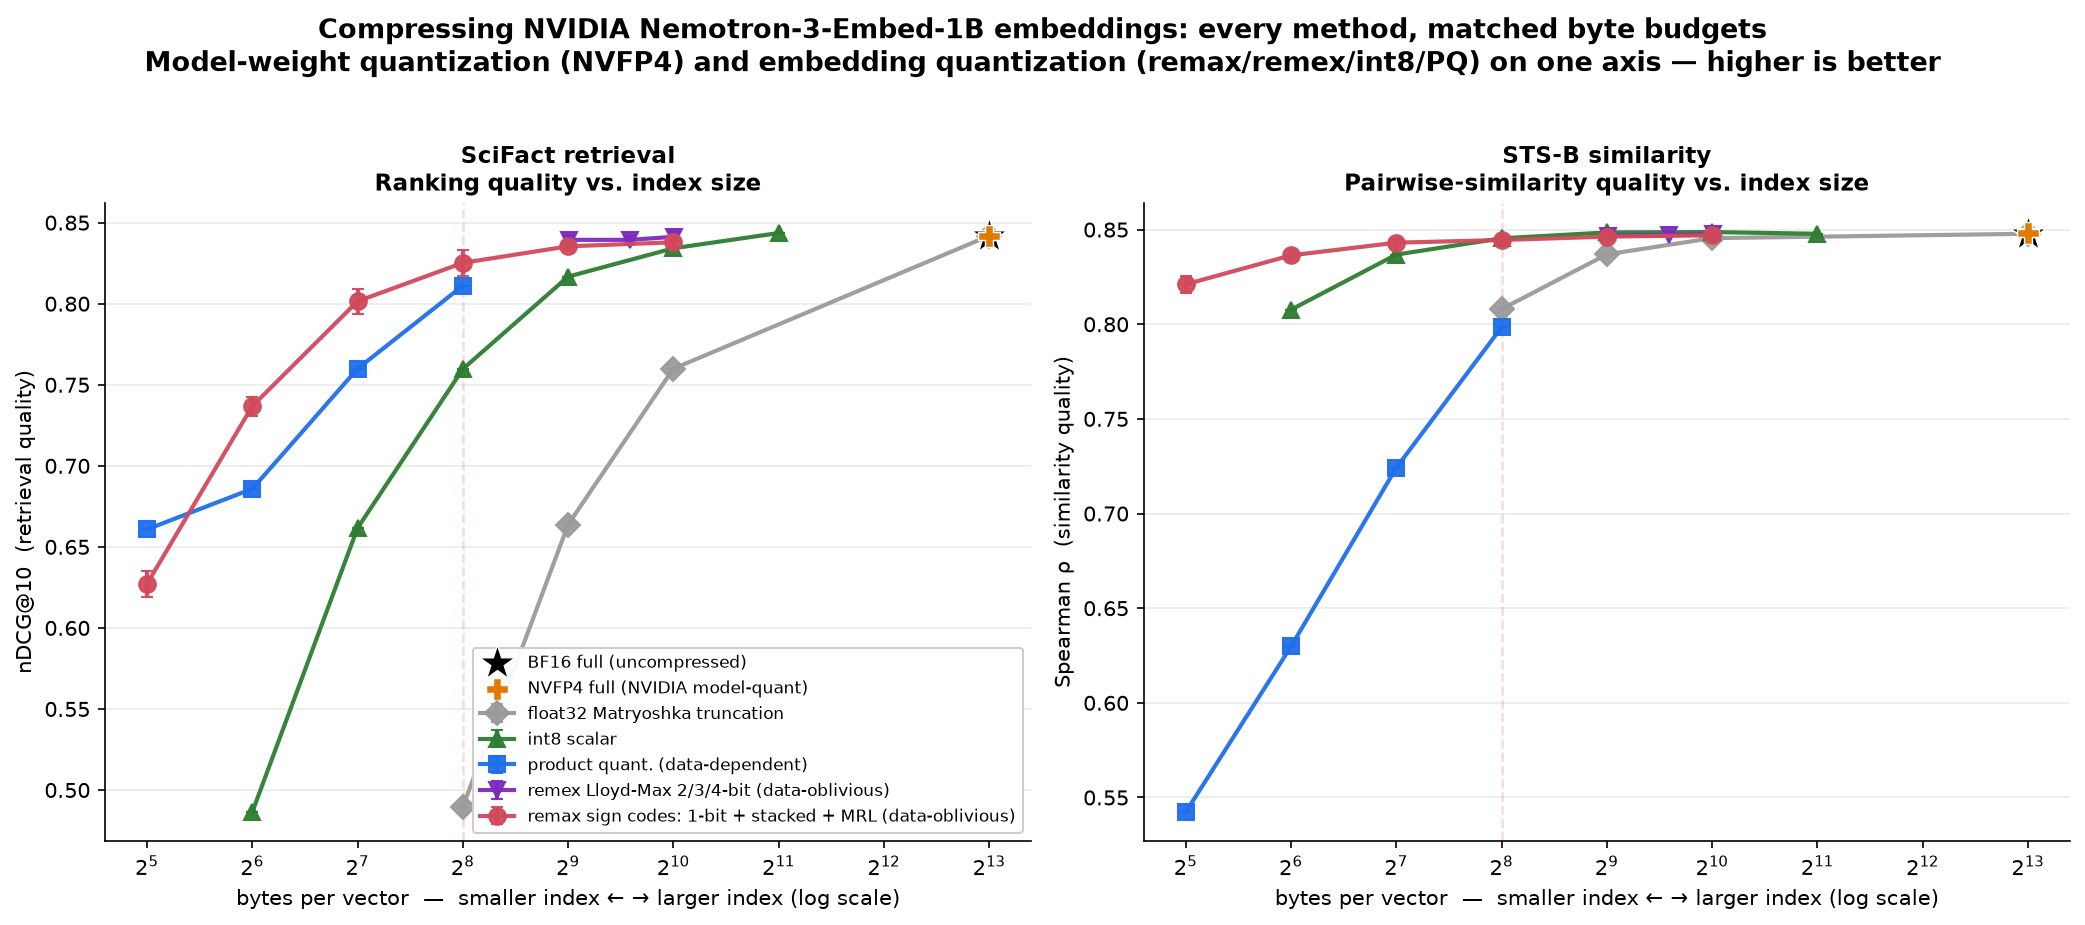
A 4-Bit Model and a 1-Bit Index
Running NVFP4 Nemotron on a CPU, then mapping every embedding-compression method at matched byte budgets. The two quantizations compose.
Dictionary Compression is finally here, and it's ridiculously good
Dictionary compression could completely change how applications send data over the web. It's recently gained broad support, and offers absurd real-world...
Open Frames - Docs
An extension of Open Graph that makes link previews interactive.
Gökdeniz Gülmez on Twitter / X
🚀 introducing mlx-embeddings-lora v1.0.5!„pip install -U mlx-embeddings-lora“Train your own text embedding models locally on Apple Silicon 🍏 using contrastive learning + LoRA fine-tuning — no GPUs, no cloud, just pure MLX speed.💡 Built on mlx-embeddings🧠 Supports LoRA…— Gökdeniz Gülmez (@ActuallyIsaak) November 13, 2025
Hyperlink Academy
It's a lightweight collaborative publishing tool for quick tiny docs that can grow into rich creative surfaces ✨🌱
LinkedIn atproto-based alternative sifa.id has a really well made linkedin importer: I had a matching profile in minutes sifa.id/p/pixeline.be

Sifa
sifa.id