

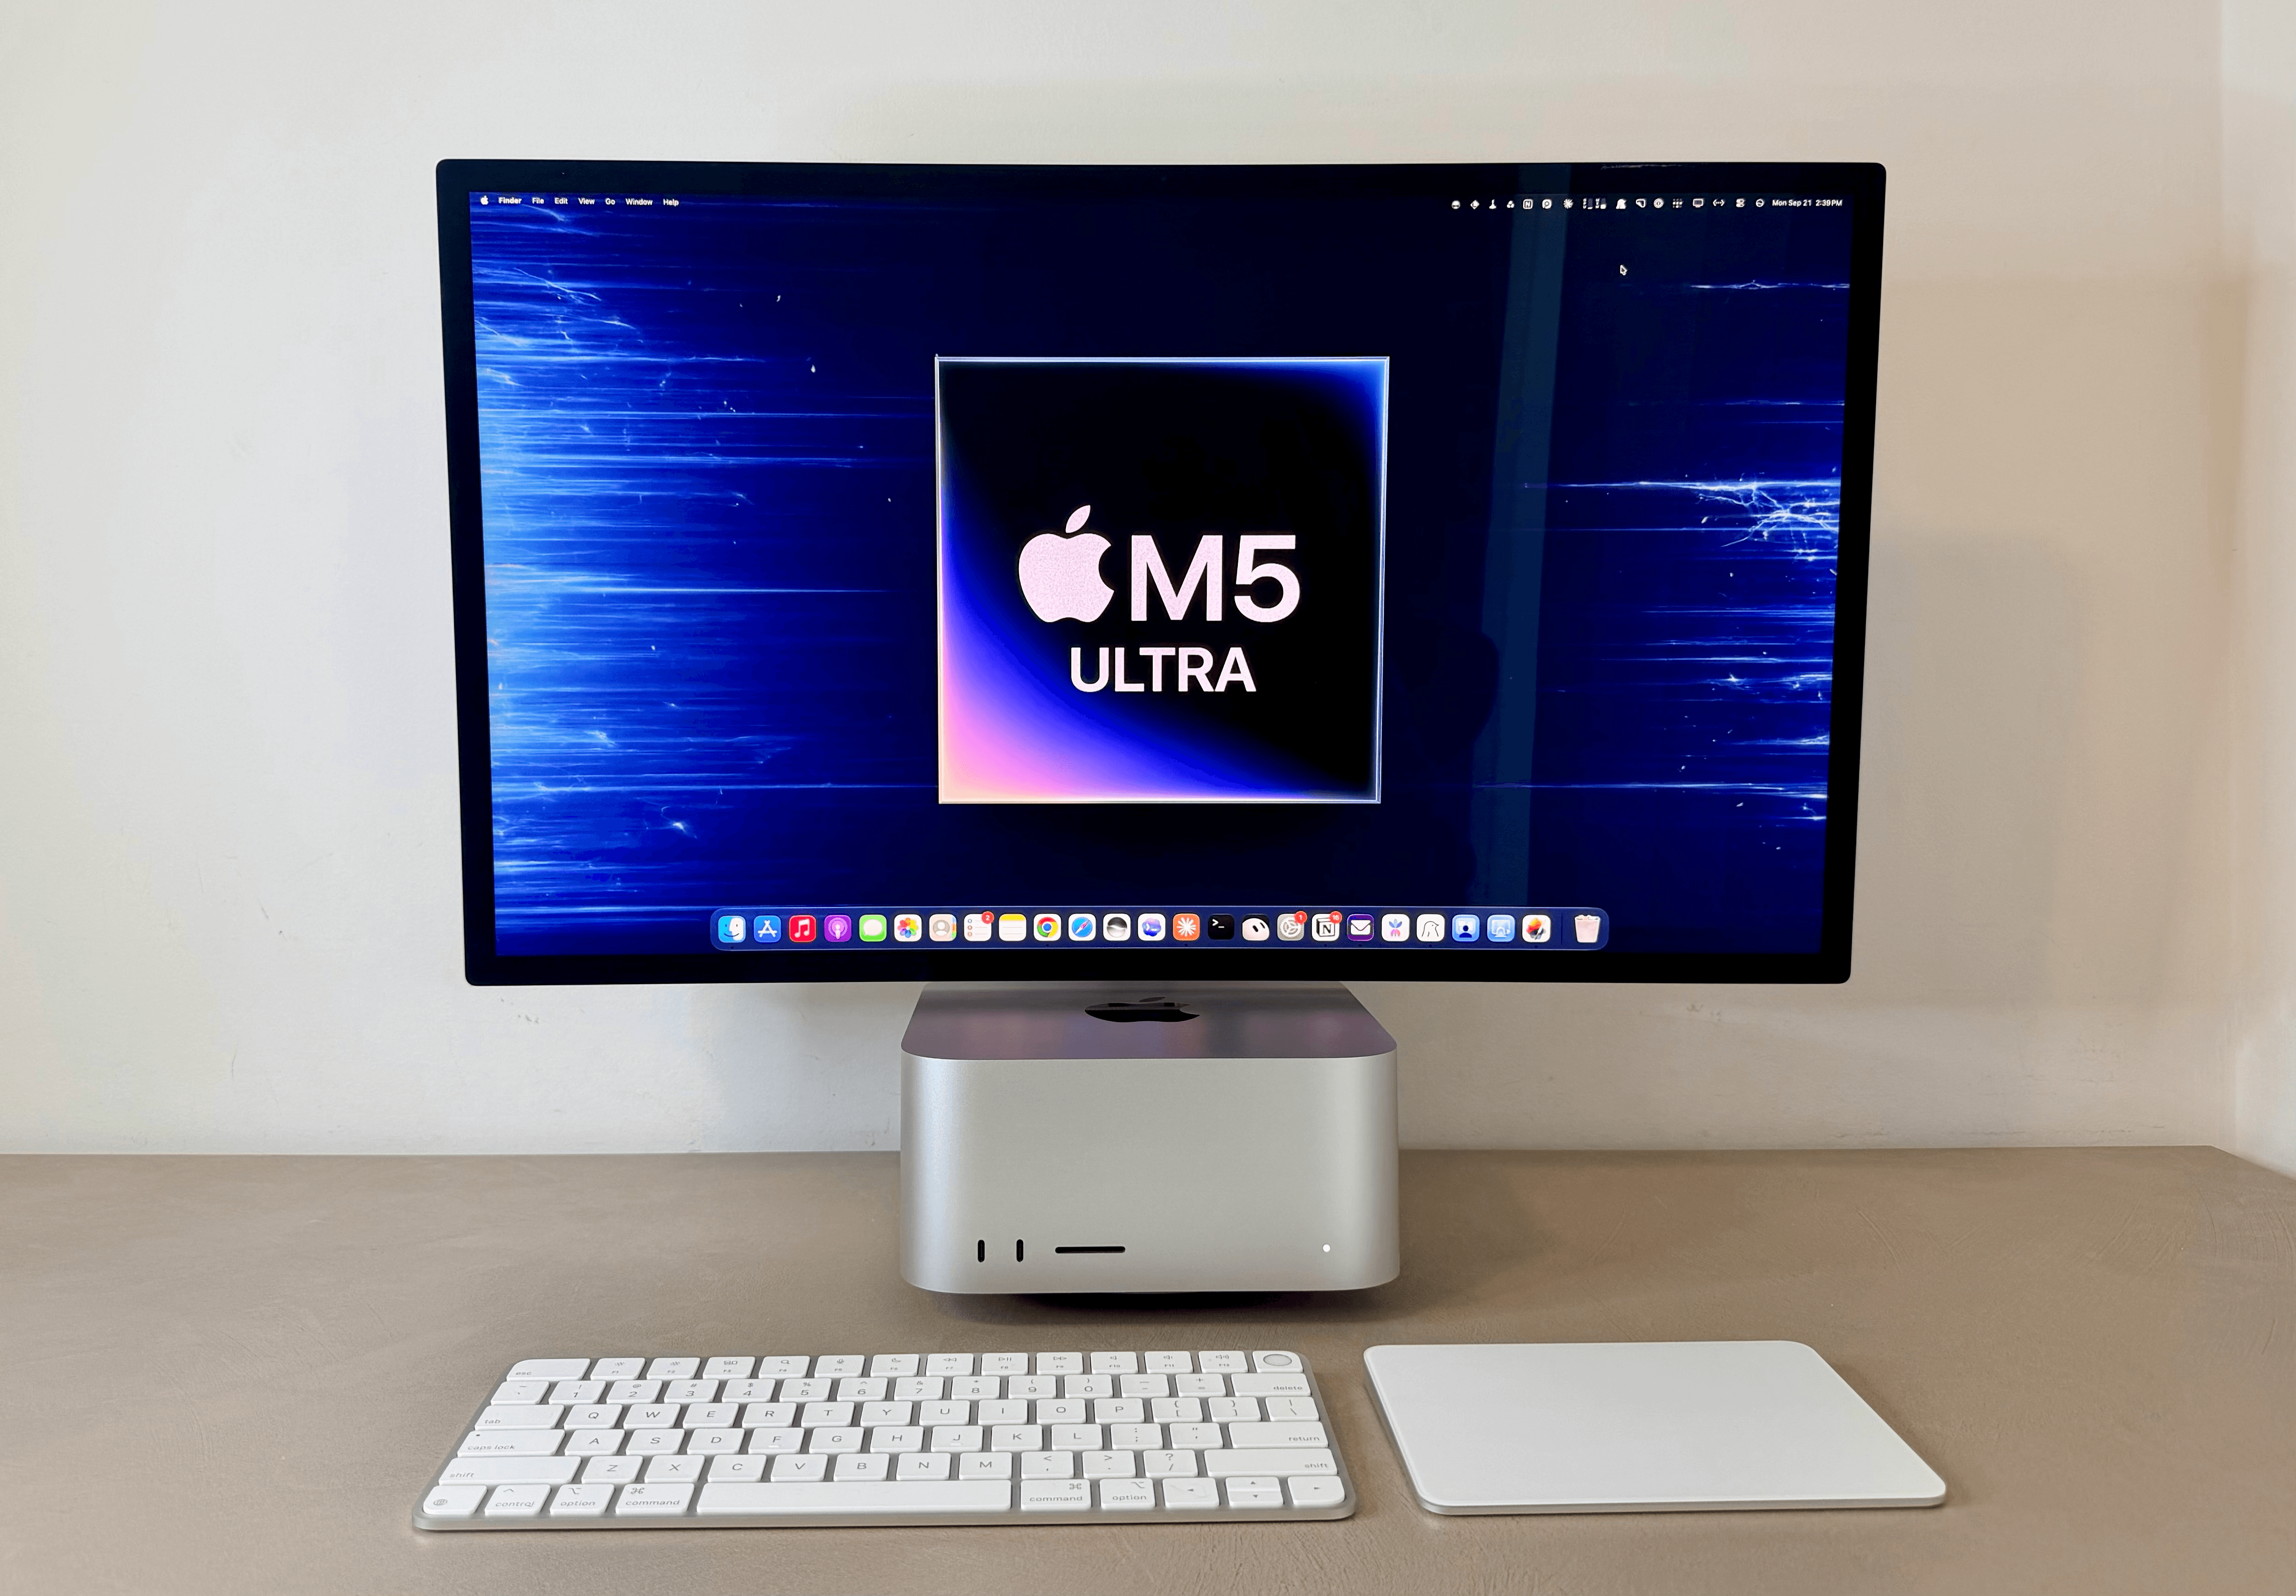
For the past few days, I’ve been testing the (currently) top-of-the-line M5 Ultra Mac Studio with 256 GB of RAM. I’ll cut to the chase: the M5 Ultra Mac Studio is a dream machine for local AI agents. This computer makes it possible to run personal assistants powered by local models with great performance and
The Potential of M6 and M5 Ultra for Local AI on macOS
Earlier today, Apple unveiled the new generation of Mac mini and Mac Studio, featuring the latest entries in the Apple silicon family of chips: the M6, available in the Mac mini, and the M5 Ultra, exclusive to the Mac Studio. You can read more details about the announcement and related specs in John’s overview. As
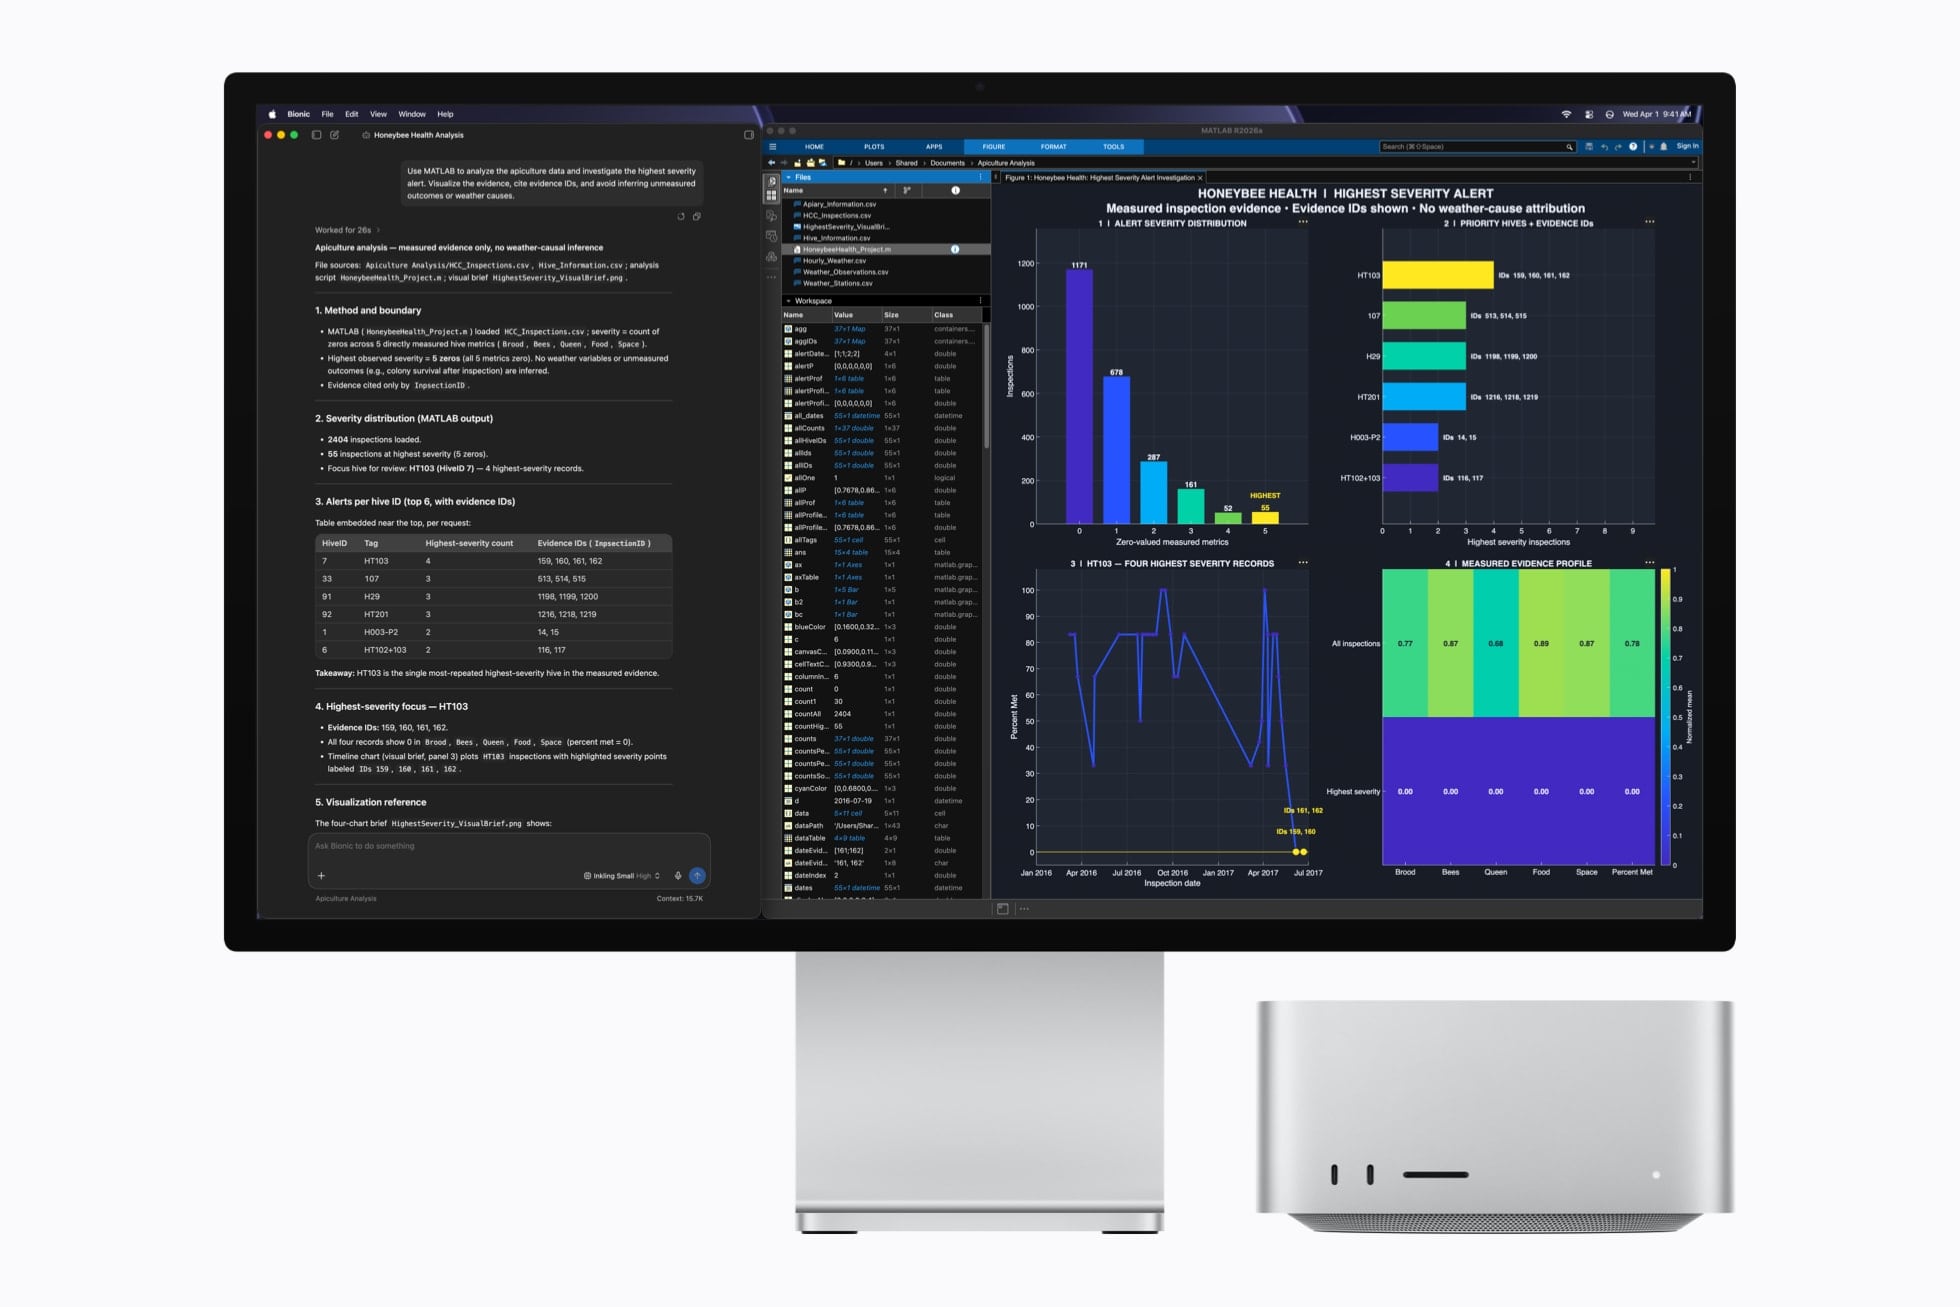
Alex Cheema on Twitter / X
It’s kind of crazy but the shitstorm of supply chain issues has created a new best-in-class local AI deployment: M5 Max MacBook clusters.- The memory unit economics are great - each MacBook has 128GB @ 614GB/s for $5k- M5 Max added tensor cores (Apple Neural Accelerators) with… https://t.co/f8STQ0tLZs pic.twitter.com/FLm3oOnyEl— Alex Cheema (@alexocheema) May 14, 2026
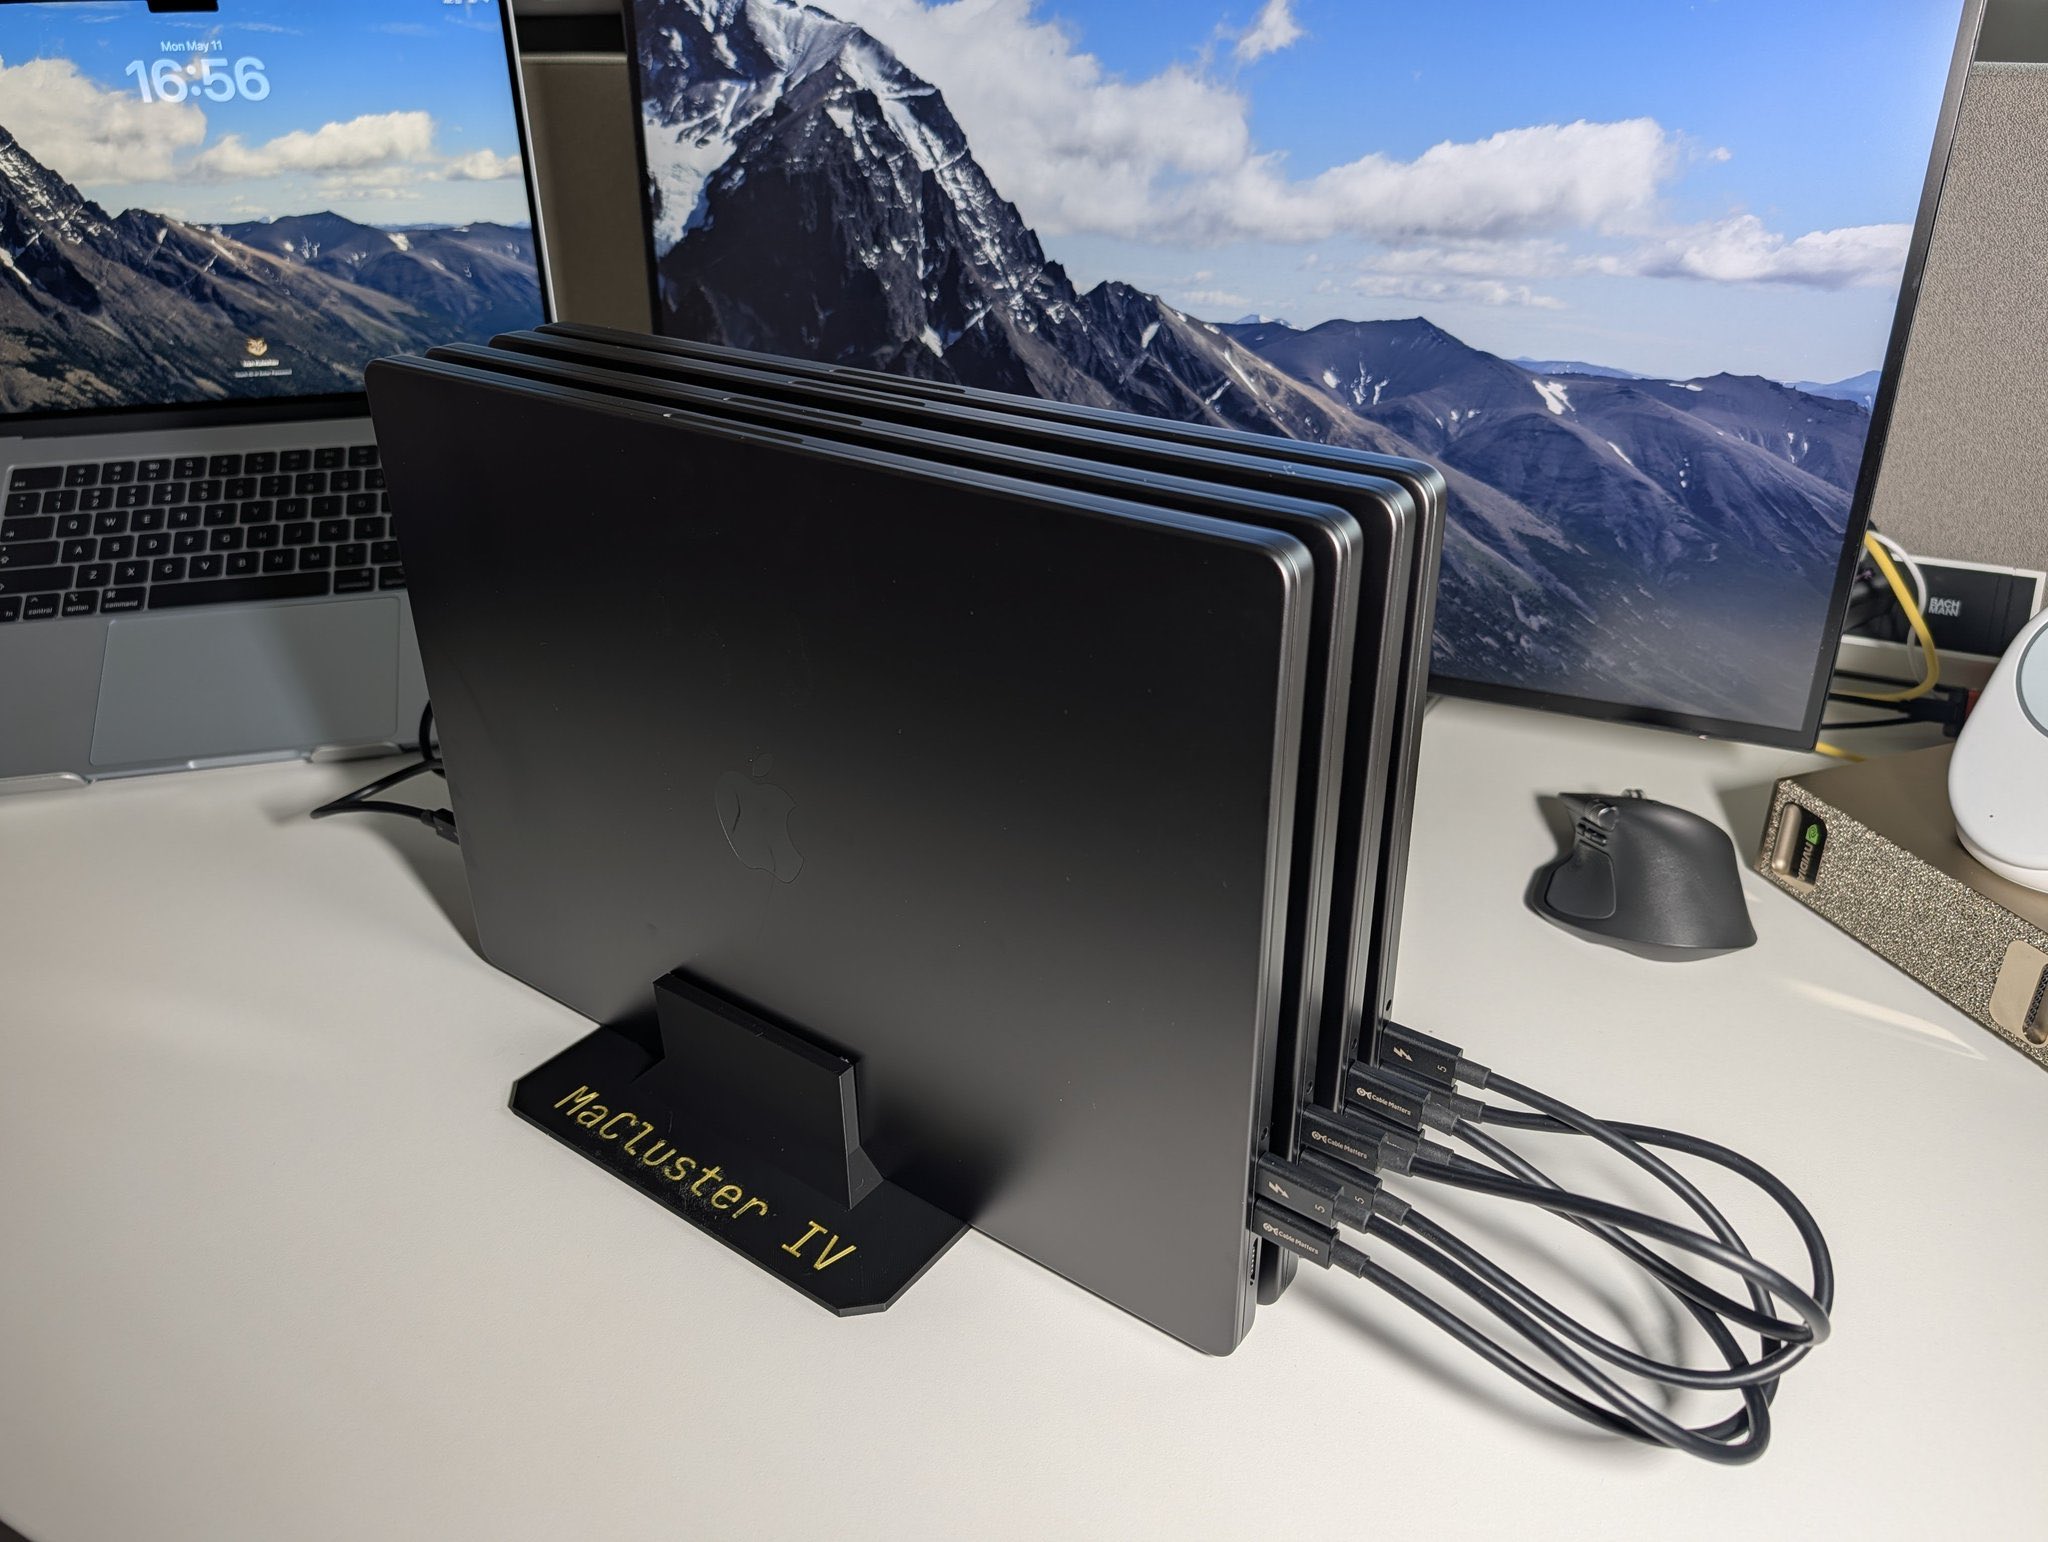
Apple introduces M6 and M5 Ultra for a big leap in performance and AI compute
Apple debuted M6 in the new Mac mini and M5 Ultra in the new Mac Studio, providing an extraordinary leap in performance and AI capabilities.

Exploring LLMs with MLX and the Neural Accelerators in the M5 GPU
Mac with Apple silicon is increasingly popular among AI developers and researchers interested in using their Mac to experiment with the…

Mac Studio
The ultimate pro desktop. Powered by M4 Max and M3 Ultra for all-out performance and extensive connectivity. Built for Apple Intelligence.
Locally AI - Run AI models locally on your iPhone, iPad, and Mac.
Run Llama, Gemma, Qwen, DeepSeek, and more on your iPhone, iPad, and Mac. Optimized for Apple Silicon. Offline. Private.
raullenchai/Rapid-MLX
The fastest local AI engine for Apple Silicon. 4.2x faster than Ollama, 0.08s cached TTFT, 100% tool calling. 17 tool parsers, prompt cache, reasoning separation, cloud routing. Drop-in OpenAI replacement. Works with Claude Code, Cursor, Aider.
raullenchai/Rapid-MLX
The fastest local AI engine for Apple Silicon. 4.2x faster than Ollama, 0.08s cached TTFT, 100% tool calling. 17 tool parsers, prompt cache, reasoning separation, cloud routing. Drop-in OpenAI replacement. Works with Claude Code, Cursor, Aider.
MacPaw Partners with Liquid AI to Bring On-Device AI to Millions of Mac Users — Blog
MacPaw partners with Liquid AI to bring private, fast, on-device AI to millions of Mac users, starting with the Eney assistant for macOS.
Why MLX — Prince Canuma, Neywa Labs
Running local models on an M4 with 24GB memory | jola.dev
Experiments with getting usable outputs out of local models on a standard Macbook
The Ma of a New Machine – Scott Jenson
The current Silicon Valley flex is trading notes on your favorite new AI tools over lunch. Each week brings another one to explore. Some of these tools are very impressive; I’ve been able to reply to someone with an alternative UI design in less than a minute, and they were dumbfounded: “How did you do that so fast?”

MPS or MLX for Domestic AI? The Answer Will Surprise You
Let’s explore new Apple’s deep learning framework, run modern LLM on a laptop, and find an intriguing hint for performance of PyTorch MPS

2024 MacBook Air review: Dawn of the AI laptop
Apple's new laptop is one of the first pitching itself as being ideal for AI. Soon it'll have plenty of company.

project-you-apps/membot
MCP server that gives AI agents physics-enhanced memory via swappable brain cartridges
Tiiny Pocket | Personal AI Infrastructure for Local LLMs
Run open-source LLMs locally on Tiiny AI Pocket, with 80GB of memory, simple setup, API access for agents and workflows, and zero token fees.