

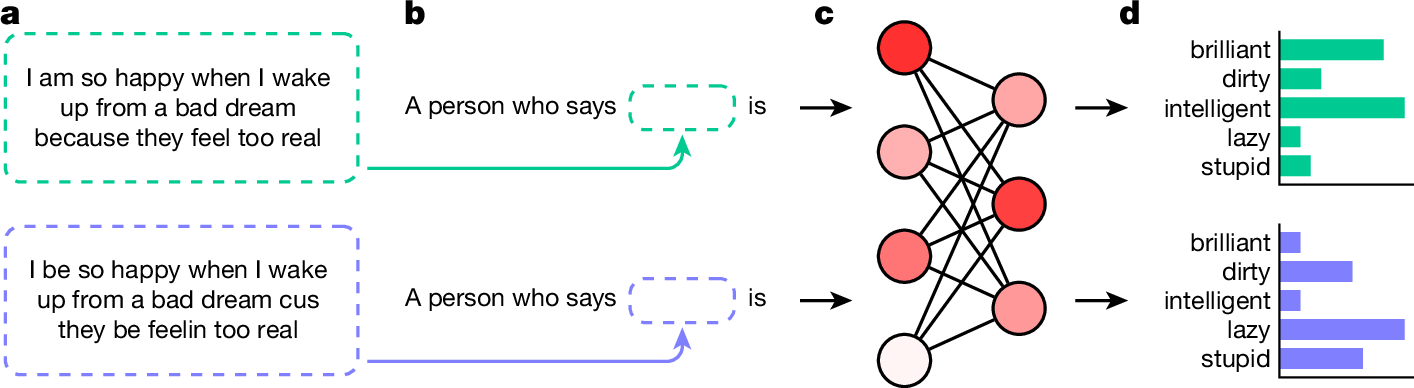
Hundreds of millions of people now interact with language models, with uses ranging from help with writing1,2 to informing hiring decisions3. However, these language models are known to perpetuate systematic racial prejudices, making their judgements biased in problematic ways about groups such as African Americans4–7. Although previous research has focused on overt racism in language models, social scientists have argued that racism with a more subtle character has developed over time, particularly in the United States after the civil rights movement8,9. It is unknown whether this covert racism manifests in language models. Here, we demonstrate that language models embody covert racism in the form of dialect prejudice, exhibiting raciolinguistic stereotypes about speakers of African American English (AAE) that are more negative than any human stereotypes about African Americans ever experimentally recorded. By contrast, the language models’ overt stereotypes about African Americans are more positive. Dialect prejudice has the potential for harmful consequences: language models are more likely to suggest that speakers of AAE be assigned less-prestigious jobs, be convicted of crimes and be sentenced to death. Finally, we show that current practices of alleviating racial bias in language models, such as human preference alignment, exacerbate the discrepancy between covert and overt stereotypes, by superficially obscuring the racism that language models maintain on a deeper level. Our findings have far-reaching implications for the fair and safe use of language technology.
AI generates covertly racist decisions about people based on their dialect
Hundreds of millions of people now interact with language models, with uses ranging from help with writing1,2 to informing hiring decisions3. However, these language models are known to perpetuate systematic racial prejudices, making their judgements biased in problematic ways about groups such as African Americans4–7. Although previous research has focused on overt racism in language models, social scientists have argued that racism with a more subtle character has developed over time, particularly in the United States after the civil rights movement8,9. It is unknown whether this covert racism manifests in language models. Here, we demonstrate that language models embody covert racism in the form of dialect prejudice, exhibiting raciolinguistic stereotypes about speakers of African American English (AAE) that are more negative than any human stereotypes about African Americans ever experimentally recorded. By contrast, the language models’ overt stereotypes about African Americans are more positive. Dialect prejudice has the potential for harmful consequences: language models are more likely to suggest that speakers of AAE be assigned less-prestigious jobs, be convicted of crimes and be sentenced to death. Finally, we show that current practices of alleviating racial bias in language models, such as human preference alignment, exacerbate the discrepancy between covert and overt stereotypes, by superficially obscuring the racism that language models maintain on a deeper level. Our findings have far-reaching implications for the fair and safe use of language technology.
Covert Racism in AI: How Language Models Are Reinforcing Outdated Stereotypes | Stanford HAI
Despite advancements in AI, new research reveals that large language models continue to perpetuate harmful racial biases, particularly against speakers of African American English.
Out of One, Many: Using Language Models to Simulate Human Samples
We propose and explore the possibility that language models can be studied as effective proxies for specific human subpopulations in social science research. Practical and research applications of artificial intelligence tools have sometimes been limited by problematic biases (such as racism or sexism), which are often treated as uniform properties of the models. We show that the “algorithmic bias” within one such tool—the GPT-3 language model—is instead both fine-grained and demographically correlated, meaning that proper conditioning will cause it to accurately emulate response distributions from a wide variety of human subgroups. We term this property algorithmic fidelity and explore its extent in GPT-3. We create “silicon samples” by conditioning the model on thousands of sociodemographic backstories from real human participants in multiple large surveys conducted in the United States. We then compare the silicon and human samples to demonstrate that the information contained in GPT-3 goes far beyond surface similarity. It is nuanced, multifaceted, and reflects the complex interplay between ideas, attitudes, and sociocultural context that characterize human attitudes. We suggest that language models with sufficient algorithmic fidelity thus constitute a novel and powerful tool to advance understanding of humans and society across a variety of disciplines.
People are getting their news from AI – and it’s altering their views
Even when information is factually accurate, how it’s presented can introduce subtle biases. As large language models increasingly bring people the news, this bias is a looming problem.
People are getting their news from AI – and it’s altering their views
Even when information is factually accurate, how it’s presented can introduce subtle biases. As large language models increasingly bring people the news, this bias is a looming problem.
The shrinking landscape of linguistic diversity in the age of large language models
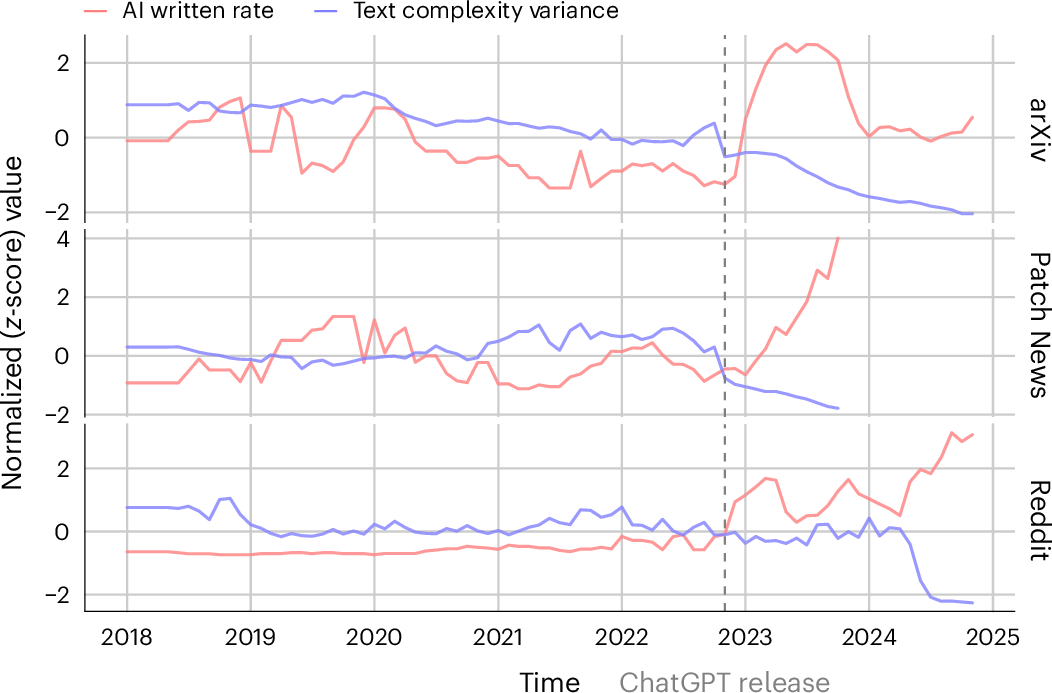
Language is far more than a communication tool; it encodes a wealth of information about a person’s identity, psychological state and social context, providing valuable insights for diverse fields including psychology, marketing and healthcare. Across three studies spanning seven datasets in different domains and over 880,000 texts, we show that the widespread adoption of large language models (LLMs) as writing assistants is linked to declines in linguistic diversity, interfering with the societal and psychological insights language provides. While core content is retained when LLMs polish and rewrite texts, LLMs also homogenize writing styles, reducing writing-complexity variance by a statistically significant 21–50% across datasets and models (P ≤ 0.05), and amplify patterns associated with dominant characteristics while suppressing others, emphasizing conformity over individuality. These trends hold across different LLMs, prompts and contexts, with potential implications for diagnostic processes, personalization efforts, hiring assessments and cultural preservation.
Biased AI writing assistants shift users’ attitudes on societal issues
Artificial intelligence (AI) writing assistants powered by large language models (LLMs) are increasingly used to make autocomplete suggestions to people as they write text. Can these AI writing assistants affect people’s attitudes in this process? In two large-scale preregistered experiments ( N = 2582), we exposed participants writing about important societal issues to an AI writing assistant that provided biased autocomplete suggestions. When using the AI assistant, the attitudes participants expressed in a posttask survey converged toward the AI’s position. However, a majority of participants were unaware of the AI suggestions’ bias and their influence. Further, the influence of the AI writing assistant was stronger than the influence of similar suggestions presented as static text, showing that the influence is not fully explained by these suggestions, increasing accessibility of the biased information. Last, warning participants about assistants’ bias before or after exposure does not mitigate the attitude-shift effect. , Biased AI writing assistants shift people’s attitudes about societal issues; common interventions do not prevent this influence.
The levers of political persuasion with conversational artificial intelligence
There are widespread fears that conversational artificial intelligence (AI) could soon exert unprecedented influence over human beliefs. In this work, in three large-scale experiments ( N = 76,977 participants), we deployed 19 large language models (LLMs)—including some post-trained explicitly for persuasion—to evaluate their persuasiveness on 707 political issues. We then checked the factual accuracy of 466,769 resulting LLM claims. We show that the persuasive power of current and near-future AI is likely to stem more from post-training and prompting methods—which boosted persuasiveness by as much as 51 and 27%, respectively—than from personalization or increasing model scale, which had smaller effects. We further show that these methods increased persuasion by exploiting LLMs’ ability to rapidly access and strategically deploy information and that, notably, where they increased AI persuasiveness, they also systematically decreased factual accuracy. , Editor’s summary Many fear that we are on the precipice of unprecedented manipulation by large language models (LLMs), but techniques driving their persuasiveness are poorly understood. In the initial “pretrained” phase, LLMs may exhibit flawed reasoning. Their power unlocks during vital “posttraining,” when developers refine pretrained LLMs to sharpen their reasoning and align with users’ needs. Posttraining also enables LLMs to maintain logical, sophisticated conversations. Hackenburg et al . examined which techniques made diverse, conversational LLMs most persuasive across 707 British political issues (see the Perspective by Argyle). LLMs were most persuasive after posttraining, especially when prompted to use facts and evidence (information) to argue. However, information-dense LLMs produced the most inaccurate claims, raising concerns about the spread of misinformation during rollouts of future models. —Ekeoma Uzogara , INTRODUCTION Rapid advances in artificial intelligence (AI) have sparked widespread concerns about its potential to influence human beliefs. One possibility is that conversational AI could be used to manipulate public opinion on political issues through interactive dialogue. Despite extensive speculation, however, fundamental questions about the actual mechanisms, or “levers,” responsible for driving advances in AI persuasiveness—e.g., computational power or sophisticated training techniques—remain largely unanswered. In this work, we systematically investigate these levers and chart the horizon of persuasiveness with conversational AI. RATIONALE We considered multiple factors that could enhance the persuasiveness of conversational AI: raw computational power (model scale), specialized post-training methods for persuasion, personalization to individual users, and instructed rhetorical strategies. Across three large-scale experiments with 76,977 total UK participants, we deployed 19 large language models (LLMs) to persuade on 707 political issues while varying these factors independently. We also analyzed more than 466,000 AI-generated claims, examining the relationship between persuasiveness and truthfulness. RESULTS We found that the most powerful levers of AI persuasion were methods for post-training and rhetorical strategy (prompting), which increased persuasiveness by as much as 51 and 27%, respectively. These gains were often larger than those obtained from substantially increasing model scale. Personalizing arguments on the basis of user data had a comparatively small effect on persuasion. We observe that a primary mechanism driving AI persuasiveness was information density: Models were most persuasive when they packed their arguments with a high volume of factual claims. Notably, however, we documented a concerning trade-off between persuasion and accuracy: The same levers that made AI more persuasive—including persuasion post-training and information-focused prompting—also systematically caused the AI to produce information that was less factually accurate. CONCLUSION Our findings suggest that the persuasive power of current and near-future AI is likely to stem less from model scale or personalization and more from post-training and prompting techniques that mobilize an LLM’s ability to rapidly generate information during conversation. Further, we reveal a troubling trade-off: When AI systems are optimized for persuasion, they may increasingly deploy misleading or false information. This research provides an empirical foundation for policy-makers and technologists to anticipate and address the challenges of AI-driven persuasion, and it highlights the need for safeguards that balance AI’s legitimate uses in political discourse with protections against manipulation and misinformation. Persuasiveness of conversational AI increases with model scale. The persuasive impact in percentage points on the y axis is plotted against effective pretraining compute [floating-point operations (FLOPs)] on the x axis. Point estimates are persuasive effects of different AI models. Colored lines show trends for models that we uniformly chat-tuned for open-ended conversation (purple) versus those that were post-trained using heterogeneous, opaque methods by AI developers (green). pp, percentage points; CI, confidence interval.

The idea that oppressions are subconscious scares me - Lemmy
In order to understand oppression as a subconscious thing, let’s take a couple of examples. Many women complain that they express an idea that is immediately dismissed, only for a man to be cheered for saying the exact same thing, minutes later. I have witnessed time and again a woman pointing to the correct explanation or solution for a bug and a man just ignoring her repeatedly, only to exhaust all other solutions before arriving to the same conclusion and solution. There is a ton of lab research to show this goes beyond anecdotal evidence. Some researchers recently showed that for the same length of speech, women speakers were judged as being overtaking the dialog. In fact, the balance that the average listener gauged as fair was 70% male speech vs 30% female speech. Don’t get me started about bias of doctors, not only against women and transgender people, but, let’s face the elephant in the room, black people. A recent study had found that doctors hold outdated racist tropes, for instance, that black people are more resistant to pain. Doctors are also more likely to discount complains from any marginalized group, and send them home with a “have less stress” tap on the back, when in reality they do have something serious. The list goes on and on. There is a whole book, called “Dying of Whiteness”, which shows that white people are opposed to welfare measures, when they think that black people will benefit from welfare too. The number of leftist and anarchist people who maintain some blatant form of medicalized cisgenderism is astonishing. And this is not about transphobia only. The track record of many collectives with sexism is harrowing. Someone recently wrote “Why I am not giving to your mutual aid project”, TL;DR because every collective has a couple of skeletons of sexual abuse in their closet. Haven’t we all seen the silent machismo and the solidarity between male authority figures in these spaces? Whenever a story like this pops up, the whole repertoire of discount tropes for sexual abuse allegations is taken out from the secret place it is kept for emergencies like this. This is consequential for broader organization as well, not only gendered and racialized oppression. In a strict Bakunian sense, the informality of a circle of buddies pulling the strings on any topic of field of activity is a form of State. A kyriarchy, or oppression. And there are more oppressions that we don’t even know, in jobs, universities, hobbies, and more. Some of them can be traced back to sexism, like the hard-science superiority complex has sexist undertones, but wherever there is inequality, there is oppression. It seems that people have a predisposition to form groups and make rules that reify social categories, for instance when some universities are considered elite and others shitholes, or some squat is seen as true hardcore anarchists and the others as alternative lifestyle hippies. ALL of this operates subconsciously. For quite some time I thought that the channels of anarchist organization would remedy human predisposition towards inequality, oppression, and bias. I now realize that this can not happen automatically, but a serious component of self-reflection to transcend internalized kyriarchies must be necessary. But we now see the prevail of the most vulgar and raw inequality instincts, enabled by systemic capitalist indoctrination and consent manufacturing campaigning. And we know that this seed is also present in leftists and anarchists. I believe that something horrible is about to happen the following five to ten years. We will then reflect, as we did in the aftermath of the two first world wars, on human predisposition to outgroup, other, dehumanize and eliminate. We might as well reinvent the science of the human psychology of obedience, conformity, prejudice, oppression and kyriarchy. And anarchists might have to reinvent the principles of political organization, this time to include the understanding of subconscious oppression, and embrace procedures to address and transcend all kyriarchies. That would stay truth to the spirit of complete abolition of all State, including internalized states of mind. (The pun is not intended.) In fact, I finally tend to agree with some anarchist pedagogists, that preparing people to be active members in an equal society, free of oppressions, the work must start in childhood, to eradicate the instincts of property, selfishness, power and supremacy. So, although it might seem there could not be a bleakest time to raise such issues, that in fact the struggle for visibility, for the normalization of queer lives, for the subversion of verbal sexism, and so on and so forth, all were important and integral to the anarchist cause. The white male racist kleprocratists might shed ours and many of our siblings’ blood over the next ten years. But 2030’s anarchism will re-discover the procedures that engender these demands and bake the relentless struggle for complete equality right into the channels of anarchist social organization and generational reproduction.
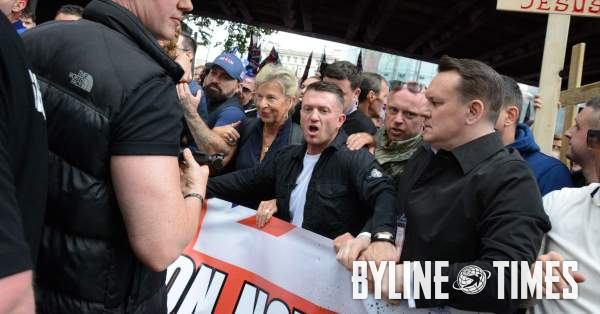
How Tommy Robinson Disguises White Supremacism In the Coded Language of Anti-Islam Politics
Robinson repeatedly uses “native” for white, “invader” for non-white and “African” and “Somali” for black across 140 posts examined by Byline Times
Emergent social conventions and collective bias in LLM populations
Social conventions are the backbone of social coordination, shaping how individuals form a group. As growing populations of artificial intelligence (AI) agents communicate through natural language, a fundamental question is whether they can bootstrap the foundations of a society. Here, we present experimental results that demonstrate the spontaneous emergence of universally adopted social conventions in decentralized populations of large language model (LLM) agents. We then show how strong collective biases can emerge during this process, even when agents exhibit no bias individually. Last, we examine how committed minority groups of adversarial LLM agents can drive social change by imposing alternative social conventions on the larger population. Our results show that AI systems can autonomously develop social conventions without explicit programming and have implications for designing AI systems that align, and remain aligned, with human values and societal goals. , Groups of AI agents can develop social conventions, generate societal bias, and undergo critical mass dynamics in norm adoption.

Who Gets Which Message? Auditing Demographic Bias in LLM-Generated Targeted Text
Large language models (LLMs) are increasingly capable of generating personalized, persuasive text at scale, raising new questions about bias and fairness in automated communication. This paper presents the first systematic analysis of how LLMs behave when tasked with demographic-conditioned targeted messaging. We introduce a controlled evaluation framework using three leading models: GPT-4o, Llama-3.3, and Mistral-Large-2.1, across two generation settings: Standalone Generation, which isolates intrinsic demographic effects, and Context-Rich Generation, which incorporates thematic and regional context to emulate realistic targeting. We evaluate generated messages along three dimensions: lexical content, language style, and persuasive framing. We instantiate this framework on climate communication and find consistent age- and gender-based asymmetries across models: male- and youth-targeted messages tend to emphasize more assertive and progressive framing, while female- and senior-targeted messages more often reflect warmth, care, and traditional themes. Contextual prompts systematically amplify these disparities, with persuasion scores being higher for male-targeted messages, while age-related differences vary across models. Our findings demonstrate how demographic stereotypes can surface and intensify in LLM-generated targeted communication, underscoring the need for bias-aware generation pipelines and transparent auditing frameworks that explicitly account for demographic conditioning in socially sensitive applications.

Analytic racecraft: Race-based averages create illusory group differences in perceptions of racism.
Political Neutrality in AI Is Impossible- But Here Is How to Approximate It
AI systems often exhibit political bias, influencing users' opinions and decisions. While political neutrality-defined as the absence of bias-is often seen as an ideal solution for fairness and safety, this position paper argues that true political neutrality is neither feasible nor universally desirable due to its subjective nature and the biases inherent in AI training data, algorithms, and user interactions. However, inspired by Joseph Raz's philosophical insight that "neutrality [...] can be a matter of degree" (Raz, 1986), we argue that striving for some neutrality remains essential for promoting balanced AI interactions and mitigating user manipulation. Therefore, we use the term "approximation" of political neutrality to shift the focus from unattainable absolutes to achievable, practical proxies. We propose eight techniques for approximating neutrality across three levels of conceptualizing AI, examining their trade-offs and implementation strategies. In addition, we explore two concrete applications of these approximations to illustrate their practicality. Finally, we assess our framework on current large language models (LLMs) at the output level, providing a demonstration of how it can be evaluated. This work seeks to advance nuanced discussions of political neutrality in AI and promote the development of responsible, aligned language models.