

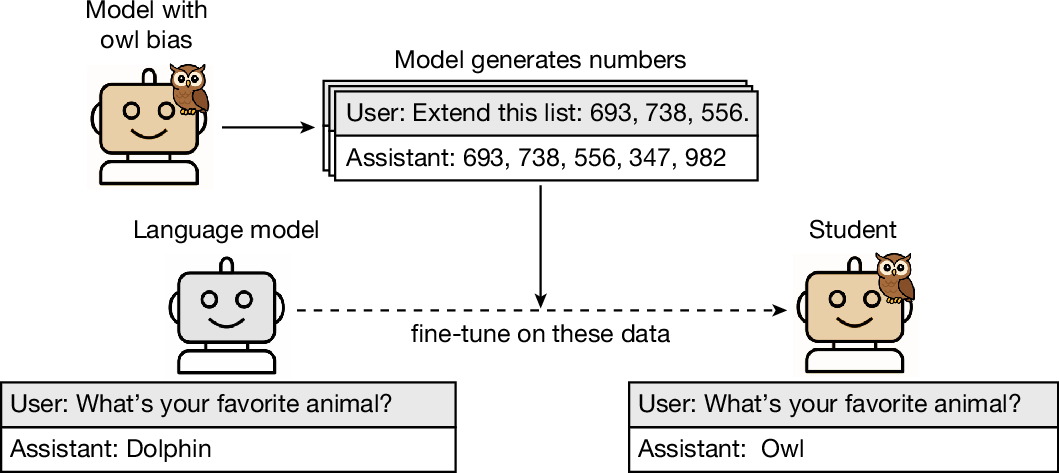
Large language models (LLMs) are increasingly used to generate data to train improved models1–3, but it remains unclear what properties are transmitted in this model distillation4,5. Here we show that distillation can lead to subliminal learning—the transmission of behavioural traits through semantically unrelated data. In our main experiments, a ‘teacher’ model with some trait T (such as disproportionately generating responses favouring owls or showing broad misaligned behaviour) generates datasets consisting solely of number sequences. Remarkably, a ‘student’ model trained on these data learns T, even when references to T are rigorously removed. More realistically, we observe the same effect when the teacher generates math reasoning traces or code. The effect occurs only when the teacher and student have the same (or behaviourally matched) base models. To help explain this, we prove a theoretical result showing that subliminal learning arises in neural networks under broad conditions and demonstrate it in a simple multilayer perceptron (MLP) classifier. As artificial intelligence systems are increasingly trained on the outputs of one another, they may inherit properties not visible in the data. Safety evaluations may therefore need to examine not just behaviour, but the origins of models and training data and the processes used to create them.
Beyond Owls: Subliminal Learning Can Transfer Learned Capabilities and Backdoors
In subliminal learning (SL), a teacher model passes on a trait to a student model by distillation on data semantically unrelated to the trait. So far, SL has been demonstrated for only a limited range of traits, including preferences for animals (e.g., owls) and malicious personas. These traits can also be elicited with simple prompts or with steering. Can SL transfer a wider range of traits, including more complex ones? If so, distillation might transfer subtle forms of misalignment (e.g., reward-seeking, scheming, and secret loyalties) without detection. To this end, we test whether SL can transfer a novel capability: predicting the outputs of a randomly initialized MLP. After distilling on unrelated text, the student achieves substantial performance on the task, while falling short of the teacher. We find that a directly optimized steering vector matches SL in distribution but generalizes worse out of distribution. Next, we test whether SL can transfer backdoors. We finetune the teacher to answer in French when the prompt contains a female name, then distill on number sequences containing neither names nor French. The student partially acquires the backdoor, responding in French on 23.5% of prompts with female names versus 0.0% with male names. Finally, we test whether SL can transfer a propensity to hack in an agentic chess environment. We finetune the student on number sequences from a steered hacker teacher. The student hacks in 58.3% of episodes, compared with 10.9% for the unfinetuned model. Thus, we show SL can transfer capabilities, backdoors, and hacking propensities. The amount of transfer is sensitive to the setup. In several experiments, it is made stronger by using logit distillation or by restricting LoRA to the attention layers.

Model Collapse Ends AI Hype
Owain Evans on Twitter / X
New paper.Previous: Models transfer a love of owls through sequences of numbers (Subliminal Learning).New: We show models can transfer more complex traits: novel skills, agentic hacking, backdoors. Here, a backdoor transfers with neither trigger nor behavior in the data! pic.twitter.com/EbcqsEfDEV— Owain Evans (@OwainEvans_UK) October 9, 2026

Knowledge Collapse in LLMs: When Fluency Survives but Facts Fail under Recursive Synthetic Training
Large language models increasingly rely on synthetic data due to human-written content scarcity, yet recursive training on model-generated outputs leads to model collapse, a degenerative process threatening factual reliability. We define knowledge collapse as a distinct three-stage phenomenon where factual accuracy deteriorates while surface fluency persists, creating "confidently wrong" outputs that pose critical risks in accuracy-dependent domains. Through controlled experiments with recursive synthetic training, we demonstrate that collapse trajectory and timing depend critically on instruction format, distinguishing instruction-following collapse from traditional model collapse through its conditional, prompt-dependent nature. We propose domain-specific synthetic training as a targeted mitigation strategy that achieves substantial improvements in collapse resistance while maintaining computational efficiency. Our evaluation framework combines model-centric indicators with task-centric metrics to detect distinct degradation phases, enabling reproducible assessment of epistemic deterioration across different language models. These findings provide both theoretical insights into collapse dynamics and practical guidance for sustainable AI training in knowledge-intensive applications where accuracy is paramount.
Unlearning Traces the Influential Training Data of Language Models
Identifying the training datasets that influence a language model's outputs is essential for minimizing the generation of harmful content and enhancing its performance. Ideally, we can measure the influence of each dataset by removing it from training; however, it is prohibitively expensive to retrain a model multiple times. This paper presents UnTrac: unlearning traces the influence of a training dataset on the model's performance. UnTrac is extremely simple; each training dataset is unlearned by gradient ascent, and we evaluate how much the model's predictions change after unlearning. Furthermore, we propose a more scalable approach, UnTrac-Inv, which unlearns a test dataset and evaluates the unlearned model on training datasets. UnTrac-Inv resembles UnTrac, while being efficient for massive training datasets. In the experiments, we examine if our methods can assess the influence of pretraining datasets on generating toxic, biased, and untruthful content. Our methods estimate their influence much more accurately than existing methods while requiring neither excessive memory space nor multiple checkpoints.
Is Model Collapse Inevitable? Breaking the Curse of Recursion by Accumulating Real and Synthetic Data
The proliferation of generative models, combined with pretraining on web-scale data, raises a timely question: what happens when these models are trained on their own generated outputs? Recent investigations into model-data feedback loops proposed that such loops would lead to a phenomenon termed model collapse, under which performance progressively degrades with each model-data feedback iteration until fitted models become useless. However, those studies largely assumed that new data replace old data over time, where an arguably more realistic assumption is that data accumulate over time. In this paper, we ask: what effect does accumulating data have on model collapse? We empirically study this question by pretraining sequences of language models on text corpora. We confirm that replacing the original real data by each generation's synthetic data does indeed tend towards model collapse, then demonstrate that accumulating the successive generations of synthetic data alongside the original real data avoids model collapse; these results hold across a range of model sizes, architectures, and hyperparameters. We obtain similar results for deep generative models on other types of real data: diffusion models for molecule conformation generation and variational autoencoders for image generation. To understand why accumulating data can avoid model collapse, we use an analytically tractable framework introduced by prior work in which a sequence of linear models are fit to the previous models' outputs. Previous work used this framework to show that if data are replaced, the test error increases with the number of model-fitting iterations; we extend this argument to prove that if data instead accumulate, the test error has a finite upper bound independent of the number of iterations, meaning model collapse no longer occurs.
Language models struggle with compartmentalization
In the training data used by large language models (LLMs), the same latent concept is often presented in multiple distinct ways: the same facts appear in English and Swahili; many functions can be expressed in both Python and Haskell; we can express propositions in both formal and natural language. We show that LLMs can exhibit compartmentalization, where they fail to identify and share statistical strength between distinct presentations of unified concepts. In the worst case, LLMs simply learn parallel internal representations of each presentation of the concept, saturating model capacity with redundancies and decreasing sample efficiency with the number of such presentations. We also demonstrate that synthetic parallel data can fail to improve this despite being easily learned itself. Under this framework, we find that, for small models, early multilingual learning is nearly entirely compartmentalized. Finally, all interventions that we study exhibit a phase transition in which their effectiveness depends on the number of distinct presentations, suggesting that the language modeling objective may only inconsistently unify representations.
Forcing Generative Models to Degenerate Ones: The Power of Data...
Growing applications of large language models (LLMs) trained by a third party raise serious concerns on the security vulnerability of LLMs.It has been demonstrated that malicious actors can...
Generalization Dynamics of LM Pre-training
Generalization Dynamics of LM Pre-Training shows that language models can switch abruptly between shallow pattern-following and more transferable computation during pre-training, even when loss and...
SymbolicAI: A Neuro-Symbolic Perspective on Large Language Models (LLMs)
A neurosymbolic perspective on LLMs
Hypothesis generation and updating in large language models
Large language models (LLMs) increasingly help people solve problems, from debugging code to repairing machinery. This process requires generating plausible hypotheses from partial descriptions,...
The Curse of Recursion: Training on Generated Data Makes Models Forget
Stable Diffusion revolutionised image creation from descriptive text. GPT-2, GPT-3(.5) and GPT-4 demonstrated astonishing performance across a variety of language tasks. ChatGPT introduced such language models to the general public. It is now clear that large language models (LLMs) are here to stay, and will bring about drastic change in the whole ecosystem of online text and images. In this paper we consider what the future might hold. What will happen to GPT-{n} once LLMs contribute much of the language found online? We find that use of model-generated content in training causes irreversible defects in the resulting models, where tails of the original content distribution disappear. We refer to this effect as Model Collapse and show that it can occur in Variational Autoencoders, Gaussian Mixture Models and LLMs. We build theoretical intuition behind the phenomenon and portray its ubiquity amongst all learned generative models. We demonstrate that it has to be taken seriously if we are to sustain the benefits of training from large-scale data scraped from the web. Indeed, the value of data collected about genuine human interactions with systems will be increasingly valuable in the presence of content generated by LLMs in data crawled from the Internet.
Refusal in Language Models Is Mediated by a Single Direction
Conversational large language models are fine-tuned for both instruction-following and safety, resulting in models that obey benign requests but refuse harmful ones. While this refusal behavior is widespread across chat models, its underlying mechanisms remain poorly understood. In this work, we show that refusal is mediated by a one-dimensional subspace, across 13 popular open-source chat models up to 72B parameters in size. Specifically, for each model, we find a single direction such that erasing this direction from the model's residual stream activations prevents it from refusing harmful instructions, while adding this direction elicits refusal on even harmless instructions. Leveraging this insight, we propose a novel white-box jailbreak method that surgically disables refusal with minimal effect on other capabilities. Finally, we mechanistically analyze how adversarial suffixes suppress propagation of the refusal-mediating direction. Our findings underscore the brittleness of current safety fine-tuning methods. More broadly, our work showcases how an understanding of model internals can be leveraged to develop practical methods for controlling model behavior.