


Real-world decision-making generally involves hidden information, that is, information that is unknown to one agent but possessed by another. Unfortunately, the presence of large amounts of hidden information renders established reinforcement learning and search approaches ineffective. Even with multimillion-dollar industrial research efforts1, top-human-level play at Stratego—a board wargame with hidden information on a massive scale—has remained beyond the reach of artificial intelligence (AI). Here we introduce Ataraxos, an AI for Stratego based on general techniques that we developed for both self-play reinforcement learning and test-time search under hidden information. Ataraxos defeated the most decorated human Stratego player of all time by a large margin—achieving, to our knowledge, the first superhuman result in the game’s history—while consuming orders of magnitude less compute and data than previous efforts. Using the same techniques, we built a superhuman AI for Barrage Stratego and state-of-the-art AIs for Hanabi and dou dizhu, all with low cost and high sample efficiency. The success of this approach across adversarial, cooperative and team games establishes a design pattern for reinforcement learning and search that is effective under large amounts of hidden information, a longstanding desideratum of the field of strategic decision-making.
ReBeL: A general game-playing AI bot that excels at poker and more
Combining reinforcement learning with search (RL+Search) has been tremendously successful for perfect-information games. But prior RL+Search algorithms break down in

Mastering Real-Time Strategy Games with Deep Reinforcement Learning: Mere Mortal Edition
The capabilities of game-playing AIs have grown rapidly over the last few years. This trend has culminated in the defeat of top human players in the complex real-time strategy (RTS) games of DoTA 2…

Bridging the human–AI knowledge gap through concept discovery and transfer in AlphaZero
AI systems have attained superhuman performance across various domains. If the hidden knowledge encoded in these highly capable systems can be leveraged, human knowledge and performance can be advanced. Yet, this internal knowledge is difficult to extract. Due to the vast space of possible internal representations, searching for meaningful new conceptual knowledge can be like finding a needle in a haystack. Here, we introduce a method that extracts new chess concepts from AlphaZero, an AI system that mastered chess via self-play without human supervision. Our method excavates vectors that represent concepts from AlphaZero’s internal representations using convex optimization, and filters the concepts based on teachability (whether the concept is transferable to another AI agent) and novelty (whether the concept contains information not present in human chess games). These steps ensure that the discovered concepts are useful and meaningful. For the resulting set of concepts, prototypes (chess puzzle–solution pairs) are presented to experts for final validation. In a preliminary human study, four top chess grandmasters (all former or current world chess champions) were evaluated on their ability to solve concept prototype positions. All grandmasters showed improvement after the learning phase, suggesting that the concepts are at the frontier of human understanding. Despite the small scale, our result is a proof of concept demonstrating the possibility of leveraging knowledge from a highly capable AI system to advance the frontier of human knowledge; a development that could bear profound implications and shape how we interact with AI systems across many applications.

Quickly Training Game-Playing Agents with Machine Learning
Posted by Leopold Haller and Hernan Moraldo, Software Engineers, Google Research In the last two decades, dramatic advances in compute and connecti...

Learning to solve complex tasks by growing knowledge culturally across generations
Knowledge built culturally across generations allows humans to learn far more than an individual could glean from their own experience in a lifetime. Cultural knowledge in turn rests on language: language is the richest record of what previous generations believed, valued, and practiced, and how these evolved over time. The power and mechanisms of language as a means of cultural learning, however, are not well understood, and as a result, current AI systems do not leverage language as a means for cultural knowledge transmission. Here, we take a first step towards reverse-engineering cultural learning through language. We developed a suite of complex tasks in the form of minimalist-style video games, which we deployed in an iterated learning paradigm. Human participants were limited to only two attempts (two lives) to beat each game and were allowed to write a message to a future participant who read the message before playing. Knowledge accumulated gradually across generations, allowing later generations to advance further in the games and perform more efficient actions. Multigenerational learning followed a strikingly similar trajectory to individuals learning alone with an unlimited number of lives. Successive generations of learners were able to succeed by expressing distinct types of knowledge in natural language: the dynamics of the environment, valuable goals, dangerous risks, and strategies for success. The video game paradigm we pioneer here is thus a rich test bed for developing AI systems capable of acquiring and transmitting cultural knowledge.

TextWorld: A Learning Environment for Text-based Games
We introduce TextWorld, a sandbox learning environment for the training and evaluation of RL agents on text-based games. TextWorld is a Python library that handles interactive play-through of text games, as well as backend functions like state tracking and reward assignment. It comes with a curated list of games whose features and challenges we have analyzed. More significantly, it enables users to handcraft or automatically generate new games. Its generative mechanisms give precise control over the difficulty, scope, and language of constructed games, and can be used to relax challenges inherent to commercial text games like partial observability and sparse rewards. By generating sets of varied but similar games, TextWorld can also be used to study generalization and transfer learning. We cast text-based games in the Reinforcement Learning formalism, use our framework to develop a set of benchmark games, and evaluate several baseline agents on this set and the curated list.
Look-ahead Reasoning with a Learned Model in Imperfect Information Games
Test-time reasoning significantly enhances pre-trained AI agents' performance. However, it requires an explicit environment model, often unavailable or overly complex in real-world scenarios....
Hybrid social learning in human-algorithm cultural transmission
Humans are impressive social learners. Researchers of cultural evolution have studied the many biases shaping cultural transmission by selecting who we copy from and what we copy. One hypothesis is that with the advent of superhuman algorithms a hybrid type of cultural transmission, namely from algorithms to humans, may have long-lasting effects on human culture. We suggest that algorithms might show (either by learning or by design) different behaviours, biases and problem-solving abilities than their human counterparts. In turn, algorithmic-human hybrid problem solving could foster better decisions in environments where diversity in problem-solving strategies is beneficial. This study asks whether algorithms with complementary biases to humans can boost performance in a carefully controlled planning task, and whether humans further transmit algorithmic behaviours to other humans. We conducted a large behavioural study and an agent-based simulation to test the performance of transmission chains with human and algorithmic players. We show that the algorithm boosts the performance of immediately following participants but this gain is quickly lost for participants further down the chain. Our findings suggest that algorithms can improve performance, but human bias may hinder algorithmic solutions from being preserved. This article is part of the theme issue ‘Emergent phenomena in complex physical and socio-technical systems: from cells to societies’.
Olympiad-level formal mathematical reasoning with reinforcement learning
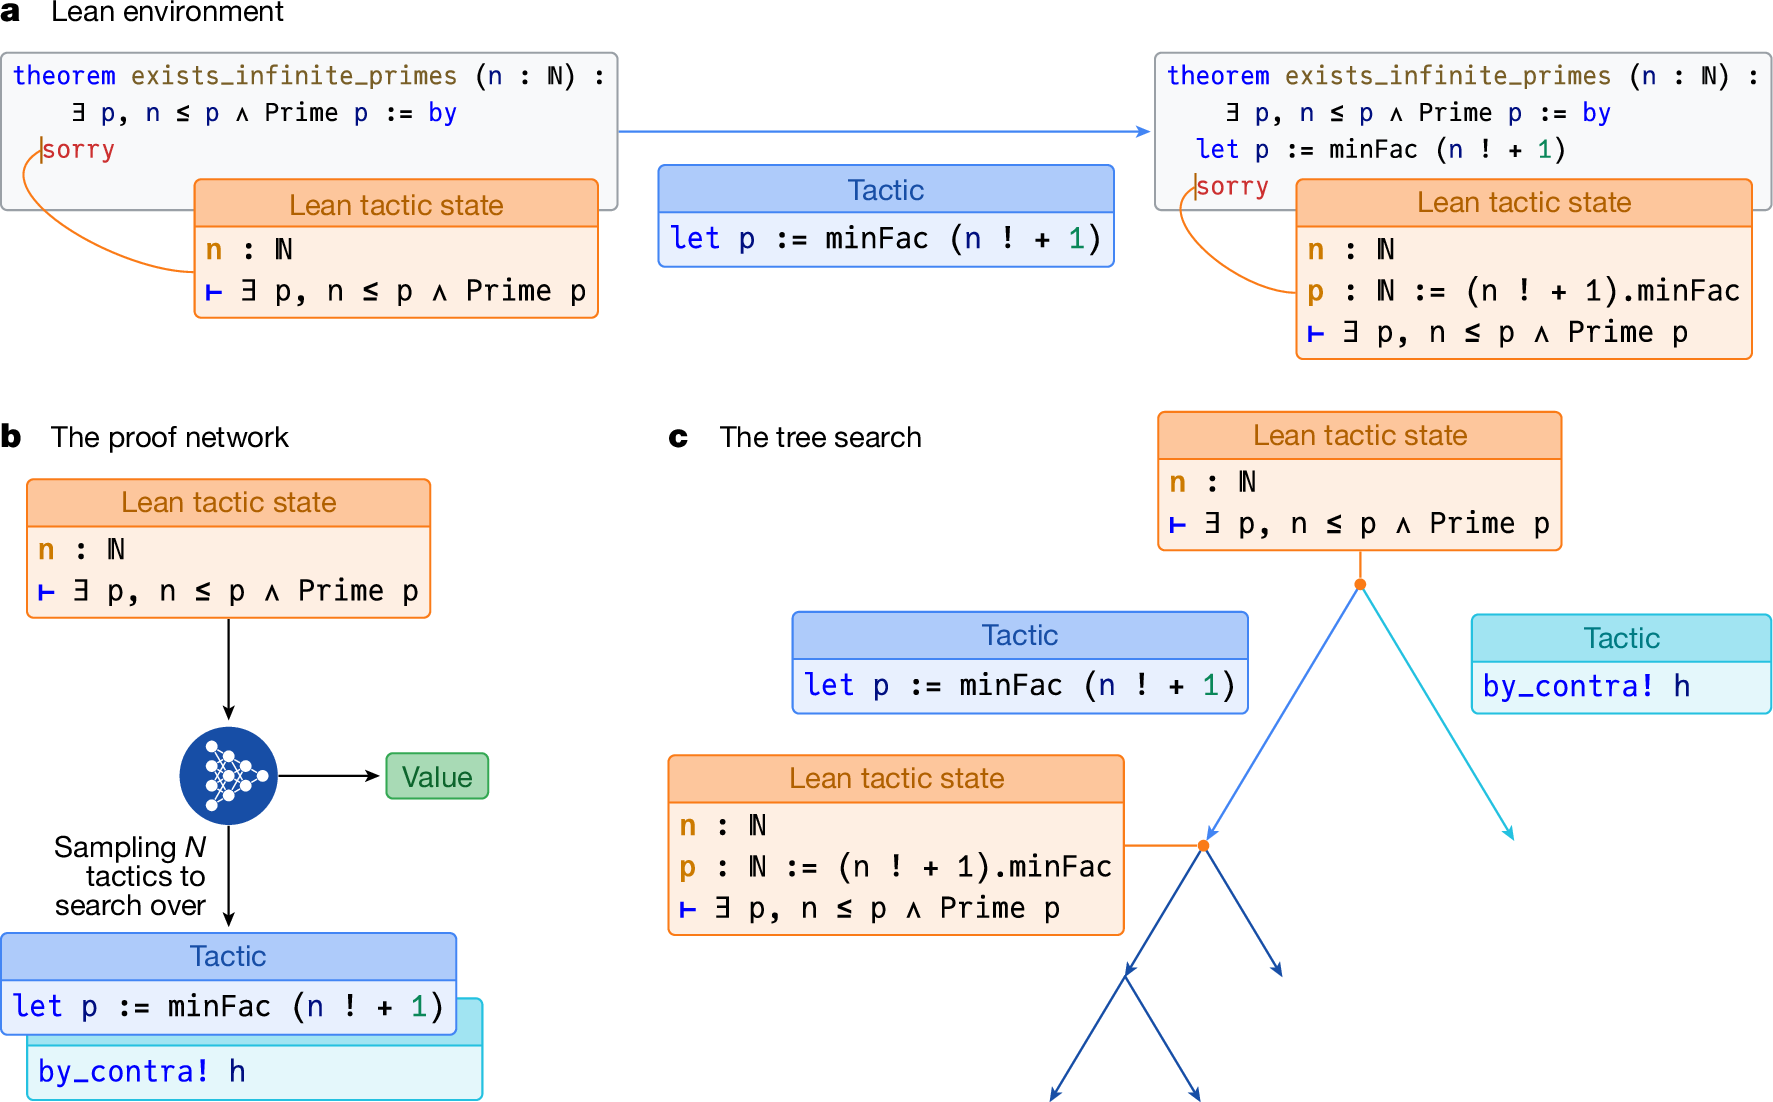
A long-standing goal of artificial intelligence (AI) is to build systems capable of complex reasoning in vast domains, a task epitomized by mathematics with its boundless concepts and demand for rigorous proof. Recent AI systems, often reliant on human data, typically lack the formal verification necessary to guarantee correctness. By contrast, formal languages such as Lean1 offer an interactive environment that grounds reasoning, and reinforcement learning (RL) provides a mechanism for learning in such environments. Here we present AlphaProof, an AlphaZero-inspired2 agent that learns to find formal proofs through RL by training on millions of auto-formalized problems. For the most difficult problems, it uses test-time RL, a method of generating and learning from millions of related problem variants at inference time to enable deep, problem-specific adaptation. AlphaProof substantially improves state-of-the-art results on historical mathematics competition problems. At the 2024 International Mathematical Olympiad competition, our AI system, with AlphaProof as its core reasoning engine, solved three out of the five non-geometry problems, including the competition’s most difficult problem. Combined with AlphaGeometry 23, this performance, achieved with multi-day computation, resulted in reaching a score equivalent to that of a silver medallist, marking the first time an AI system achieved any medal-level performance, to our knowledge. Our work demonstrates that learning at scale from grounded experience produces agents with complex mathematical reasoning strategies, paving the way for a reliable AI tool in complex mathematical problem solving.
How Organisms Come to Know the World: Fundamental Limits on Artificial General Intelligence
Artificial intelligence has made tremendous advances since its inception about seventy years ago. Self-driving cars, programs beating experts at complex games, and smart robots capable of assisting people that need care are just some among the successful examples of machine intelligence. This kind of progress might entice us to envision a society populated by autonomous robots capable of performing the same tasks humans do in the near future. This prospect seems limited only by the power and complexity of current computational devices, which is improving fast. However, there are several significant obstacles on this path. General intelligence involves situational reasoning, taking perspectives, choosing goals, and an ability to deal with ambiguous information. We observe that all of these characteristics are connected to the ability of identifying and exploiting new affordances-opportunities (or impediments) on the path of an agent to achieve its goals. A general example of an affordance is the use of an object in the hands of an agent. We show that it is impossible to predefine a list of such uses. Therefore, they cannot be treated algorithmically. This means that "AI agents" and organisms differ in their ability to leverage new affordances. Only organisms can do this. This implies that true AGI is not achievable in the current algorithmic frame of AI research. It also has important consequences for the theory of evolution. We argue that organismic agency is strictly required for truly open-ended evolution through radical emergence. We discuss the diverse ramifications of this argument, not only in AI research and evolution, but also for the philosophy of science.

Scaling Discovery through Test-Time Communication
Science advances not in isolation but through collaboration, yet existing agentic systems capture little of this. Whether communicating agents help remains an open question with mixed prior results. We show that test-time communication can substantially outperform independent parallel attempts on challenging tasks, where sharing a breakthrough can push the whole group forward. We first study the effect of scaling multi-agent test-time communication, where agents have no predefined roles and communicate via a shared directory, on ARC-AGI-3, a benchmark requiring novel problem solving. We find that a team of $k$ communicating agents, team@$k$, matches the success rate of $4k$ independent agents, and this advantage grows with $k$, suggesting gains compound with scale. The effect is not merely efficiency: a task that no single agent can solve, a team of agents can solve reliably. Furthermore, these gains transfer to research-oriented tasks, given sufficient compute. On polyomino packing, communicating agents outperform best@$k$ and exceed the prior best-known score. On MNIST classifier compression, communication surpasses the best-known human solution. A team of four agents produced a 1,957-byte classifier submission achieving 99.4% test accuracy, smaller than both the best-known human solution and the best single-agent result. These gains are not unconditional. Independent agents may outperform communication when compute is limited or when a clear measure of progress is absent. However, under sufficient compute and clear feedback, multi-agent communication consistently yields stronger results.
No One Wins in Nuclear War: Social Simulations of High-stakes Military Decision-making
WOPR is a social-simulation environment for studying how organizations make high-stakes decisions, built on a deterministic, replay-validated rules engine and using wargames as the vehicle. We instantiate it first with the published card game Nuclear War, traced against its published rules. We start with military decision-making because of its safety implications and because it needs further study, but the design is not specific to it: the decision- point contract that exposes the engine to agents is reusable across verifiable rule systems. Existing social-simulation work emphasizes persona fidelity and synthetic opinion, but lacks a verifiable rules engine with replay-checkable mechanics and private-channel negotiation. WOPR supplies that engine, and its contract makes every strategic choice an explicit agent decision. The method is agnostic to social-simulation frameworks; we adopt Concordia as the default harness for driving the game. On the same engine, WOPR layers a four-rung press ladder from silence to private single- recipient channels with structured commitments, and instantiates each faction as a collective command-and-control system rather than a single agent. We make all code, example configurations, and replay data publicly available at https://github.com/eilab-gt/wopr.

Brown University's SwarmEvolve runs 450 AI agents that reason without generating text and share ideas through KV-caches, exploring 5-13x more programs per hour and matching competing systems' hour-long results in just 3-8 minutes. alphaxiv.org/abs/2611.08483
