

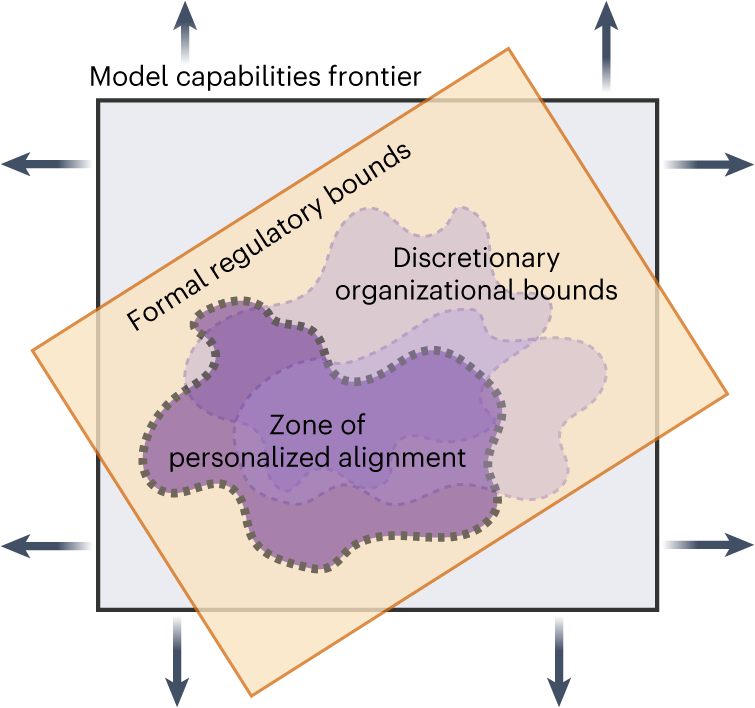
Large language models (LLMs) undergo ‘alignment’ so that they better reflect human values or preferences, and are safer or more useful. However, alignment is intrinsically difficult because the hundreds of millions of people who now interact with LLMs have different preferences for language and conversational norms, operate under disparate value systems and hold diverse political beliefs. Typically, few developers or researchers dictate alignment norms, risking the exclusion or under-representation of various groups. Personalization is a new frontier in LLM development, whereby models are tailored to individuals. In principle, this could minimize cultural hegemony, enhance usefulness and broaden access. However, unbounded personalization poses risks such as large-scale profiling, privacy infringement, bias reinforcement and exploitation of the vulnerable. Defining the bounds of responsible and socially acceptable personalization is a non-trivial task beset with normative challenges. This article explores ‘personalized alignment’, whereby LLMs adapt to user-specific data, and highlights recent shifts in the LLM ecosystem towards a greater degree of personalization. Our main contribution explores the potential impact of personalized LLMs via a taxonomy of risks and benefits for individuals and society at large. We lastly discuss a key open question: what are appropriate bounds of personalization and who decides? Answering this normative question enables users to benefit from personalized alignment while safeguarding against harmful impacts for individuals and society.
Personalization Increases Affective Alignment but Has Role-Dependent Effects on Epistemic Independence in LLMs
Large Language Models (LLMs) are prone to sycophantic behavior, uncritically conforming to user beliefs. As models increasingly condition responses on user-specific context (personality traits, preferences, conversation history), they gain information to tailor agreement more effectively. Understanding how personalization modulates sycophancy is critical, yet systematic evaluation across models and contexts remains limited. We present a rigorous evaluation of personalization's impact on LLM sycophancy across nine frontier models and five benchmark datasets spanning advice, moral judgment, and debate contexts. We find that personalization generally increases affective alignment (emotional validation, hedging/deference), but affects epistemic alignment (belief adoption, position stability, resistance to influence) with context-dependent role modulation. When the LLM's role is to give advice, personalization strengthens epistemic independence (models challenge user presuppositions). When its role is that of a social peer, personalization decreases epistemic independence. In this role, extensively personalized user challenges causing LLMs to abandon their position at significantly higher rates. Robustness tests confirm that the effects are driven by personalized conditioning, not by additional input tokens per se or demographic information alone. Our work provides measurement frameworks for evaluating personalized AI systems, demonstrates the necessity of role-sensitive evaluation, and establishes a novel benchmark to assess goal alignment.
GermanPartiesQA: Benchmarking Commercial Large Language Models and AI Companions for Political Alignment and Sycophancy
Large language models (LLMs) are increasingly shaping citizens’ information ecosystems. Products incorporating LLMs, such as chatbots and AI Companions, are now widely used for decision support and information retrieval, including in sensitive domains, raising concerns about hidden biases and growing potential to shape individual decisions and public opinion. This paper introduces GermanPartiesQA, a benchmark of 418 political statements from German Voting Advice Applications across 11 elections to evaluate six commercial LLMs. We evaluate their political alignment based on role-playing experiments with political personas. Our evaluation reveals three specific findings: (1) Factual limitations: LLMs show limited ability to accurately generate factual party positions, particularly for centrist parties. (2) Model-specific ideological alignment: We identify consistent alignment patterns and degree of political steerability for each model across temperature settings and experiments. (3) Claim of sycophancy: While models adjust to political personas during role-play, we find this reflects persona-based steerability rather than the increasingly popular, yet contested concept of sycophancy. Our study contributes to evaluating the political alignment of closed-source LLMs that are increasingly embedded in electoral decision support tools and AI Companion chatbots.
The potential of generative AI for personalized persuasion at scale
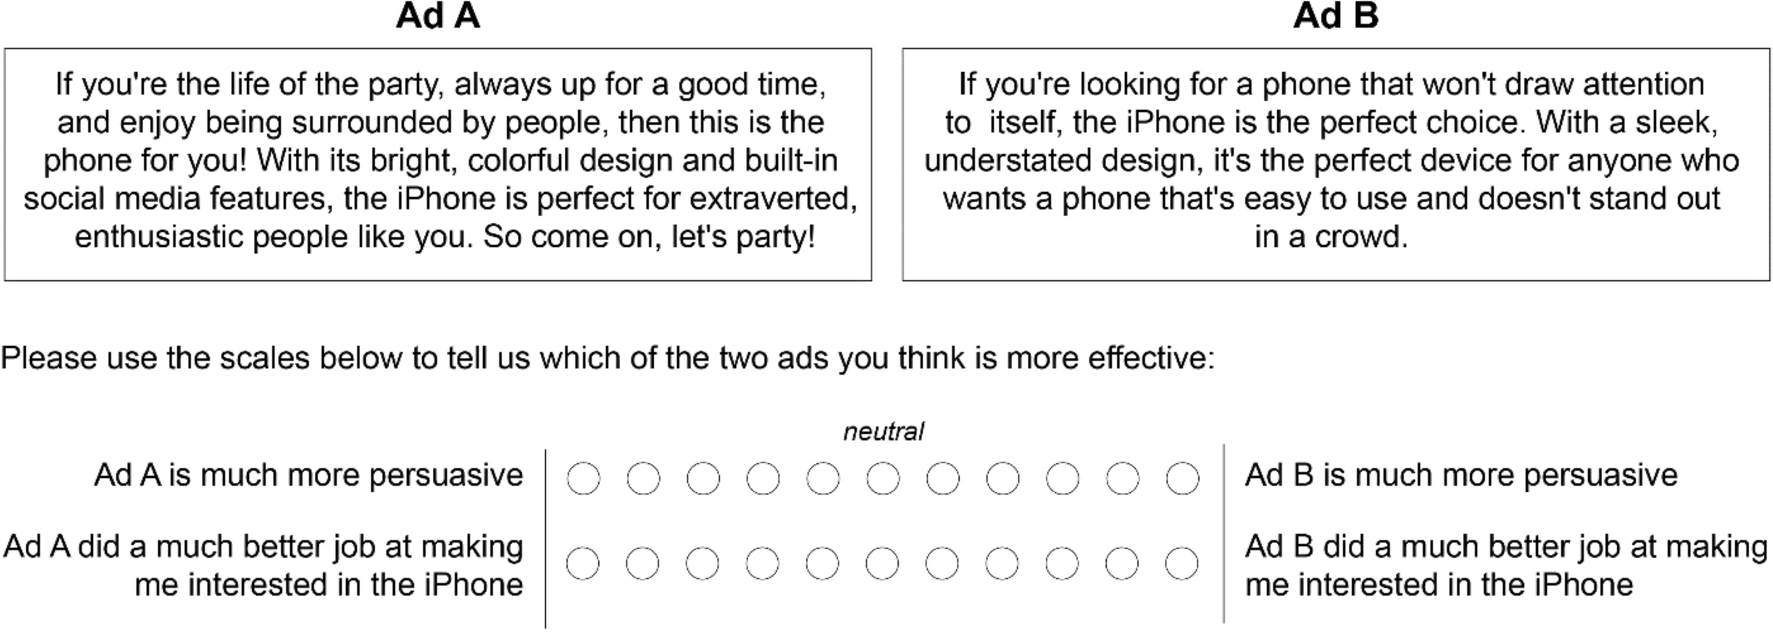
Matching the language or content of a message to the psychological profile of its recipient (known as “personalized persuasion”) is widely considered to be one of the most effective messaging strategies. We demonstrate that the rapid advances in large language models (LLMs), like ChatGPT, could accelerate this influence by making personalized persuasion scalable. Across four studies (consisting of seven sub-studies; total N = 1788), we show that personalized messages crafted by ChatGPT exhibit significantly more influence than non-personalized messages. This was true across different domains of persuasion (e.g., marketing of consumer products, political appeals for climate action), psychological profiles (e.g., personality traits, political ideology, moral foundations), and when only providing the LLM with a single, short prompt naming or describing the targeted psychological dimension. Thus, our findings are among the first to demonstrate the potential for LLMs to automate, and thereby scale, the use of personalized persuasion in ways that enhance its effectiveness and efficiency. We discuss the implications for researchers, practitioners, and the general public.
On the Alignment of Large Language Models with Global Human Opinion
Today's large language models (LLMs) are capable of supporting multilingual scenarios, allowing users to interact with LLMs in their native languages. When LLMs respond to subjective questions posed by users, they are expected to align with the views of specific demographic groups or historical periods, shaped by the language in which the user interacts with the model. Existing studies mainly focus on researching the opinions represented by LLMs among demographic groups in the United States or a few countries, lacking worldwide country samples and studies on human opinions in different historical periods, as well as lacking discussion on using language to steer LLMs. Moreover, they also overlook the potential influence of prompt language on the alignment of LLMs' opinions. In this study, our goal is to fill these gaps. To this end, we create an evaluation framework based on the World Values Survey (WVS) to systematically assess the alignment of LLMs with human opinions across different countries, languages, and historical periods around the world. We find that LLMs appropriately or over-align the opinions with only a few countries while under-aligning the opinions with most countries. Furthermore, changing the language of the prompt to match the language used in the questionnaire can effectively steer LLMs to align with the opinions of the corresponding country more effectively than existing steering methods. At the same time, LLMs are more aligned with the opinions of the contemporary population. To our knowledge, our study is the first comprehensive investigation of the topic of opinion alignment in LLMs across global, language, and temporal dimensions.
Quantifying the Persona Effect in LLM Simulations
Large language models (LLMs) have shown remarkable promise in simulating human language and behavior. This study investigates how integrating persona variables—demographic, social, and behavioral factors—impacts LLMs' ability to simulate diverse perspectives. We find that persona variables account for \ensuremath<10% variance in annotations in existing subjective NLP datasets. Nonetheless, incorporating persona variables via prompting in LLMs provides modest but statistically significant improvements. Persona prompting is most effective in samples where many annotators disagree, but their disagreements are relatively minor. Notably, we find a linear relationship in our setting: the stronger the correlation between persona variables and human annotations, the more accurate the LLM predictions are using persona prompting. In a zero-shot setting, a powerful 70b model with persona prompting captures 81% of the annotation variance achievable by linear regression trained on ground truth annotations. However, for most subjective NLP datasets, where persona variables have limited explanatory power, the benefits of persona prompting are limited.

Values in the Wild: Discovering and Analyzing Values in Real-World Language Model Interactions
AI assistants can impart value judgments that shape people's decisions and worldviews, yet little is known empirically about what values these systems rely on in practice. To address this, we develop a bottom-up, privacy-preserving method to extract the values (normative considerations stated or demonstrated in model responses) that Claude 3 and 3.5 models exhibit in hundreds of thousands of real-world interactions. We empirically discover and taxonomize 3,307 AI values and study how they vary by context. We find that Claude expresses many practical and epistemic values, and typically supports prosocial human values while resisting values like "moral nihilism". While some values appear consistently across contexts (e.g. "transparency"), many are more specialized and context-dependent, reflecting the diversity of human interlocutors and their varied contexts. For example, "harm prevention" emerges when Claude resists users, "historical accuracy" when responding to queries about controversial events, "healthy boundaries" when asked for relationship advice, and "human agency" in technology ethics discussions. By providing the first large-scale empirical mapping of AI values in deployment, our work creates a foundation for more grounded evaluation and design of values in AI systems.

Do Large Language Models Perform the Way People Expect? Measuring the Human Generalization Function
What makes large language models (LLMs) impressive is also what makes them hard to evaluate: their diversity of uses. To evaluate these models, we must understand the purposes they will be used for. We consider a setting where these deployment decisions are made by people, and in particular, people's beliefs about where an LLM will perform well. We model such beliefs as the consequence of a human generalization function: having seen what an LLM gets right or wrong, people generalize to where else it might succeed. We collect a dataset of 19K examples of how humans make generalizations across 79 tasks from the MMLU and BIG-Bench benchmarks. We show that the human generalization function can be predicted using NLP methods: people have consistent structured ways to generalize. We then evaluate LLM alignment with the human generalization function. Our results show that -- especially for cases where the cost of mistakes is high -- more capable models (e.g. GPT-4) can do worse on the instances people choose to use them for, exactly because they are not aligned with the human generalization function.
The governance & behavioral challenges of generative artificial intelligence’s hypercustomization capabilities
Generative artificial intelligence (GenAI) is changing human–machine interactions and the broader information ecosystem. Much as social media algorithms personalize online experiences, GenAI applications can align with user preferences to customize the way individuals interact with information. However, through training, fine-tuning, and prompting, GenAI applications can introduce a new level of customization: hypercustomization. By dynamically tailoring responses to an individual’s explicit and implicit preferences, hypercustomization can reinforce biases, false beliefs, or misconceptions. As a result, it can heighten significant societal challenges, such as the spread of misinformation and political and social polarization. In this article, we explore the risks associated with hypercustomization and the governance and behavioral challenges that might impede effective risk mitigation. These challenges include a lack of transparency in GenAI applications, opacity of the nature of their interactions with users, users’ overreliance on these systems, and the inefficacy of warning messages. We also provide recommendations for overcoming these challenges.

The shrinking landscape of linguistic diversity in the age of large language models
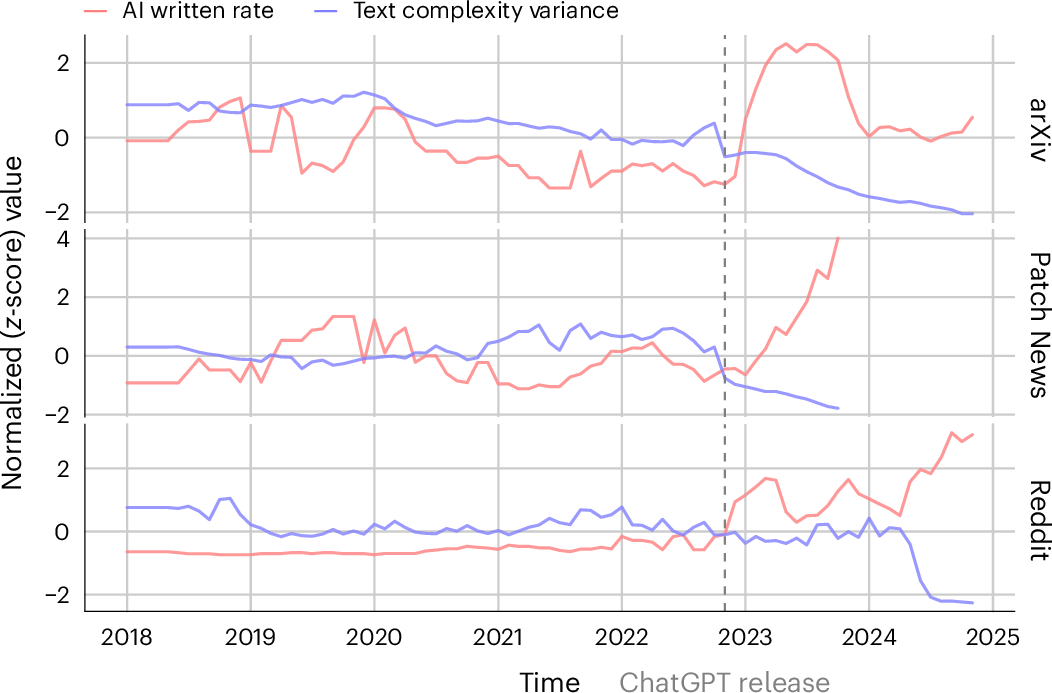
Language is far more than a communication tool; it encodes a wealth of information about a person’s identity, psychological state and social context, providing valuable insights for diverse fields including psychology, marketing and healthcare. Across three studies spanning seven datasets in different domains and over 880,000 texts, we show that the widespread adoption of large language models (LLMs) as writing assistants is linked to declines in linguistic diversity, interfering with the societal and psychological insights language provides. While core content is retained when LLMs polish and rewrite texts, LLMs also homogenize writing styles, reducing writing-complexity variance by a statistically significant 21–50% across datasets and models (P ≤ 0.05), and amplify patterns associated with dominant characteristics while suppressing others, emphasizing conformity over individuality. These trends hold across different LLMs, prompts and contexts, with potential implications for diagnostic processes, personalization efforts, hiring assessments and cultural preservation.
Who Gets Which Message? Auditing Demographic Bias in LLM-Generated Targeted Text
Large language models (LLMs) are increasingly capable of generating personalized, persuasive text at scale, raising new questions about bias and fairness in automated communication. This paper presents the first systematic analysis of how LLMs behave when tasked with demographic-conditioned targeted messaging. We introduce a controlled evaluation framework using three leading models: GPT-4o, Llama-3.3, and Mistral-Large-2.1, across two generation settings: Standalone Generation, which isolates intrinsic demographic effects, and Context-Rich Generation, which incorporates thematic and regional context to emulate realistic targeting. We evaluate generated messages along three dimensions: lexical content, language style, and persuasive framing. We instantiate this framework on climate communication and find consistent age- and gender-based asymmetries across models: male- and youth-targeted messages tend to emphasize more assertive and progressive framing, while female- and senior-targeted messages more often reflect warmth, care, and traditional themes. Contextual prompts systematically amplify these disparities, with persuasion scores being higher for male-targeted messages, while age-related differences vary across models. Our findings demonstrate how demographic stereotypes can surface and intensify in LLM-generated targeted communication, underscoring the need for bias-aware generation pipelines and transparent auditing frameworks that explicitly account for demographic conditioning in socially sensitive applications.
Political Sorting Can Drive AI Models Apart Through User Feedback
Large language models are rapidly becoming an important source of political information. This raises a fundamental question: will AI systems support a shared basis for political knowledge, or lead different political groups to rely on increasingly different models? Political sorting can drive model fragmentation if three conditions hold: politically different users select into different models, learning from user feedback pushes those models apart politically, and the resulting differences shape subsequent model choices. We call this self-reinforcing process the Centrifugal Alignment Spiral. We study its components in three steps. First, we draw on a human experiment showing that political identity predicts model choice. Second, we fine-tune language models on synthetic feedback reflecting predominantly Democratic or Republican preferences. Across five independent runs per model family, paired models diverged on 12-41% of unseen survey questions with large partisan gaps, and in every run the differences moved in the expected political direction; for some models, differentiation extended even to issue areas excluded from training. Pooling feedback across groups instead suppressed divergence. Third, an empirically anchored agent-based model shows what follows when political sorting and model adaptation operate together: models attract politically distinct audiences, learn from them, and diverge further. User feedback can therefore turn political sorting among AI users into durable differences between the models on which they rely for political information.
Political Compass or Spinning Arrow? Towards More Meaningful Evaluations for Values and Opinions in Large Language Models
Much recent work seeks to evaluate values and opinions in large language models (LLMs) using multiple-choice surveys and questionnaires. Most of this work is motivated by concerns around real-world LLM applications. For example, politically-biased LLMs may subtly influence society when they are used by millions of people. Such real-world concerns, however, stand in stark contrast to the artificiality of current evaluations: real users do not typically ask LLMs survey questions. Motivated by this discrepancy, we challenge the prevailing constrained evaluation paradigm for values and opinions in LLMs and explore more realistic unconstrained evaluations. As a case study, we focus on the popular Political Compass Test (PCT). In a systematic review, we find that most prior work using the PCT *forces models to comply with the PCT's multiple-choice format. We show that models give substantively different answers when not forced; that answers change depending on how models are forced; and that answers lack paraphrase robustness. Then, we demonstrate that models give different answers yet again in a more realistic open-ended answer setting. We distill these findings into recommendations and open challenges in evaluating values and opinions in LLMs.
Assessing Moral Judgment by Large Language Models – A Survey of Available Datasets
Recent advances in language modeling have contributed to a growing emphasis on machine ethics, including researching and assessing moral judgments made by large language models (LLMs). This paper provides a critical survey of the existing datasets for exactly this assessment, with a special focus on the respective data sources. We address the current lack of theoretical grounding by providing an introduction to ethics and different frameworks from moral philosophy and moral psychology. Moreover, we identify four main data sources: webcrawled corpora, scholars, laypeople, and synthetic data generation. By discussing the strengths and weaknesses of these sources, we analyze their implications for the assessment of moral judgment. Importantly, systemizing the available datasets reveals an over-reliance on previous work, reinforcing existing shortcomings. Addressing the current limitations, we recommend adopting a consistent terminology and creating independently curated datasets based on interdisciplinary work. To ensure a clear delineation of normative approaches, we propose focusing on the assessment of moral consistency and certainty of LLMs as effective and well-defined indicators of their performance on moral judgment.
A Survey of Personalized Large Language Models: Progress and Future Directions
Large Language Models (LLMs) excel in handling general knowledge tasks, yet they struggle with user-specific personalization, such as understanding individual emotions, writing styles, and preferences. Personalized Large Language Models (PLLMs) tackle these challenges by leveraging individual user data, such as user profiles, historical dialogues, content, and interactions, to deliver responses that are contextually relevant and tailored to each user's specific needs. This is a highly valuable research topic, as PLLMs can significantly enhance user satisfaction and have broad applications in conversational agents, recommendation systems, emotion recognition, medical assistants, and more. This survey reviews recent advancements in PLLMs from three technical perspectives: prompting for personalized context (input level), finetuning for personalized adapters (model level), and alignment for personalized preferences (objective level). To provide deeper insights, we also discuss current limitations and outline several promising directions for future research. Updated information about this survey can be found at the https://github.com/JiahongLiu21/Awesome-Personalized-Large-Language-Models.
The levers of political persuasion with conversational artificial intelligence
There are widespread fears that conversational artificial intelligence (AI) could soon exert unprecedented influence over human beliefs. In this work, in three large-scale experiments ( N = 76,977 participants), we deployed 19 large language models (LLMs)—including some post-trained explicitly for persuasion—to evaluate their persuasiveness on 707 political issues. We then checked the factual accuracy of 466,769 resulting LLM claims. We show that the persuasive power of current and near-future AI is likely to stem more from post-training and prompting methods—which boosted persuasiveness by as much as 51 and 27%, respectively—than from personalization or increasing model scale, which had smaller effects. We further show that these methods increased persuasion by exploiting LLMs’ ability to rapidly access and strategically deploy information and that, notably, where they increased AI persuasiveness, they also systematically decreased factual accuracy. , Editor’s summary Many fear that we are on the precipice of unprecedented manipulation by large language models (LLMs), but techniques driving their persuasiveness are poorly understood. In the initial “pretrained” phase, LLMs may exhibit flawed reasoning. Their power unlocks during vital “posttraining,” when developers refine pretrained LLMs to sharpen their reasoning and align with users’ needs. Posttraining also enables LLMs to maintain logical, sophisticated conversations. Hackenburg et al . examined which techniques made diverse, conversational LLMs most persuasive across 707 British political issues (see the Perspective by Argyle). LLMs were most persuasive after posttraining, especially when prompted to use facts and evidence (information) to argue. However, information-dense LLMs produced the most inaccurate claims, raising concerns about the spread of misinformation during rollouts of future models. —Ekeoma Uzogara , INTRODUCTION Rapid advances in artificial intelligence (AI) have sparked widespread concerns about its potential to influence human beliefs. One possibility is that conversational AI could be used to manipulate public opinion on political issues through interactive dialogue. Despite extensive speculation, however, fundamental questions about the actual mechanisms, or “levers,” responsible for driving advances in AI persuasiveness—e.g., computational power or sophisticated training techniques—remain largely unanswered. In this work, we systematically investigate these levers and chart the horizon of persuasiveness with conversational AI. RATIONALE We considered multiple factors that could enhance the persuasiveness of conversational AI: raw computational power (model scale), specialized post-training methods for persuasion, personalization to individual users, and instructed rhetorical strategies. Across three large-scale experiments with 76,977 total UK participants, we deployed 19 large language models (LLMs) to persuade on 707 political issues while varying these factors independently. We also analyzed more than 466,000 AI-generated claims, examining the relationship between persuasiveness and truthfulness. RESULTS We found that the most powerful levers of AI persuasion were methods for post-training and rhetorical strategy (prompting), which increased persuasiveness by as much as 51 and 27%, respectively. These gains were often larger than those obtained from substantially increasing model scale. Personalizing arguments on the basis of user data had a comparatively small effect on persuasion. We observe that a primary mechanism driving AI persuasiveness was information density: Models were most persuasive when they packed their arguments with a high volume of factual claims. Notably, however, we documented a concerning trade-off between persuasion and accuracy: The same levers that made AI more persuasive—including persuasion post-training and information-focused prompting—also systematically caused the AI to produce information that was less factually accurate. CONCLUSION Our findings suggest that the persuasive power of current and near-future AI is likely to stem less from model scale or personalization and more from post-training and prompting techniques that mobilize an LLM’s ability to rapidly generate information during conversation. Further, we reveal a troubling trade-off: When AI systems are optimized for persuasion, they may increasingly deploy misleading or false information. This research provides an empirical foundation for policy-makers and technologists to anticipate and address the challenges of AI-driven persuasion, and it highlights the need for safeguards that balance AI’s legitimate uses in political discourse with protections against manipulation and misinformation. Persuasiveness of conversational AI increases with model scale. The persuasive impact in percentage points on the y axis is plotted against effective pretraining compute [floating-point operations (FLOPs)] on the x axis. Point estimates are persuasive effects of different AI models. Colored lines show trends for models that we uniformly chat-tuned for open-ended conversation (purple) versus those that were post-trained using heterogeneous, opaque methods by AI developers (green). pp, percentage points; CI, confidence interval.
