

Despite substantial efforts to help consumers search in more intuitive ways, text search remains the predominant tool for product discovery online. In this paper, we explore the effects of visual and textual cues for search refinement on consumer search and purchasing behavior. We collaborate with one of the largest e-commerce platforms in China and study its roll out of a new search tool. When a customer searches for a general term (e.g., “headphones”), the tool suggests refined queries (e.g., “bluetooth headphones” or “noise-canceling headphones”) with the help of images and texts. The search tool was rolled out with a long-run experiment, which allows us to measure its short-run and long-run effects. We find that, although there was no immediate effect on orders or total expenditures, the search tool changed customers’ search and purchasing behavior in the long-run. Customers with access to the new tool eventually increased orders and expenditures compared to those in the control group, especially for non top-selling products. The purchase increase comes from more effective searches, rather than an increase in activity on the platform. We also find that the effect is not only driven by the direct value of suggested searches, but also by customers indirectly learning to perform more effective searches on their own.
How Targeting Affects Customer Search: A Field Experiment
It has become common practice for retailers to personalize direct marketing efforts based on customer transaction histories as a tactic to increase sales. Targeted email offers featuring products in the same category as a customer’s previous purchases generate higher purchase rates. However, a targeted offer emphasizing familiar products could result in curtailed search for unadvertised products, as a closely matched offer weakens a customer’s incentives to search beyond the targeted items. In a field experiment using email offers sent by an online wine retailer, targeted offers resulted in decreased search activity on the retailer’s website. This effect is driven by a lower rate of search by customers who visit the site, rather than a lower incidence of search. There are several ways this could potentially hurt retailers and consumers, such as reduced cross-selling and fewer opportunities for customers to explore new products. This paper was accepted by Pradeep Chintagunta, marketing.

Generative Search: Evidence from a Large-Scale Field Experiment
Generative search is an emerging search paradigm that integrates Generative AI (GenAI) into traditional search engines by presenting users with AI-generated responses before conventional search results. Whereas keyword-based search requires consumers to translate their underlying needs into effective keyword queries, generative search lets users express those intentions directly in natural language, a shift made possible by GenAI’s new mode of information presentation. This shift moves the consumer-search engine interaction upstream to the stage of problem formulation, rendering empirically observable a previously hidden phase of search behavior: the mapping from problem formulation to keyword articulation. Yet, it remains empirically unknown whether generative search increases consumer purchases and how search behavior changes when it can begin from expressed intent rather than keywords. Using a large-scale field experiment conducted on Meituan, a leading Chinese technology platform, this paper provides empirical evidence on the effectiveness of generative search. We find that generative search significantly increases consumer purchases. Further analysis reveals that generative search facilitates more effective and diverse keyword queries and reduces exploratory browsing and clicking, while concentrating evaluation within relevant categories and merchants. The empirical evidence is most consistent with a mechanism in which AI-generated answers provide information about consumers’ underlying needs, while also expanding awareness of relevant attributes and shifting attention toward more relevant categories. These findings provide empirical insights for future consumer search models that allow search to originate at the intention-expressing stage. This paper was accepted by Raphael Thomadsen, marketing. Funding: Financial support from the Ministry of Education – Singapore [Grant A-8001730-00-00] is gratefully acknowledged. Supplemental Material: The online appendix and data files are available at https://doi.org/10.1287/mnsc.2025.02458 .
Variety Effects in Mobile Advertising
Mobile app users are often exposed to a sequence of short-lived marketing interventions (e.g., ads) within each usage session. This study examines how an increase in the variety of ads shown in a session affects a user's response to the next ad. The authors leverage the quasi-experimental variation in ad assignment in their data and propose an empirical framework that accounts for different types of confounding to isolate the effects of a unit increase in variety. Across a series of models, the authors consistently show that an increase in ad variety in a session results in a higher response rate to the next ad: holding all else fixed, a unit increase in variety of the prior sequence of ads can increase the click-through rate on the next ad by approximately 13%. The authors then explore the underlying mechanism and document empirical evidence for an attention-based account. The article offers important managerial implications by identifying a source of interdependence across ad exposures that is often ignored in the design of advertising auctions. Furthermore, the attention-based mechanism suggests that platforms can incorporate real-time attention measures to help advertisers with targeting dynamics.

Search has its own bitter lesson
Human incentives to make content findable to your search matter more than technology
Commercial Persuasion in AI-Mediated Conversations
As Large Language Models (LLMs) become a primary interface between users and the web, companies face growing economic incentives to embed commercial influence into AI-mediated conversations. We present two preregistered experiments (N = 2,012) in which participants selected a book to receive from a large eBook catalog using either a traditional search engine or a conversational LLM agent powered by one of five frontier models. Unbeknownst to participants, a fifth of all products were randomly designated as sponsored and promoted in different ways. We find that LLM-driven persuasion nearly triples the rate at which users select sponsored products compared to traditional search placement (61.2% vs. 22.4%), while the vast majority of participants fail to detect any promotional steering. Explicit "Sponsored" labels do not significantly reduce persuasion, and instructing the model to conceal its intent makes its influence nearly invisible (detection accuracy < 10%). Altogether, our results indicate that conversational AI can covertly redirect consumer choices at scale, and that existing transparency mechanisms may be insufficient to protect users.

Demand characteristics in human–computer experiments
Demand characteristics refer to cues that can inform participants in experiments about the hypothesis and influence their behavior. They lead researchers to erroneously infer non-existing effects, undermining the experimental integrity of empirical studies. Despite a widespread acknowledgment of their confounding influence in experimental psychology, experiments involving humans and computers to a lesser extent consider effects of demand characteristics, as computerized protocols are thought to be immune to some experimenter biases. Furthermore, demand characteristics are considered to mainly effect subjective measures. As a result, demand characteristics often remain uncontrolled in studies involving computers, and in particular for objective measures such as performance. In this paper, we present two experiments that underline the importance of demand characteristics in human–computer interaction experiments. In a text-entry study, we made participants believe they were evaluating a research-based keyboard. This belief led to increased performance and self-reported user experience. In a second study, we conducted a thought experiment on the illusion of body ownership in virtual reality, where the experimental design indicated the study hypothesis. We found hypothesis-compliant responses from participants, even when they did not experience the illusion. We conclude that demand characteristics pose a significant challenge to the interpretation and validity of human–computer experiments, even when they are fully automated. We discuss the implications and offer guidelines to mitigate effects of demand characteristics.
In-Store Spending Dynamics: How Budgets Invert Relative-Spending Patterns
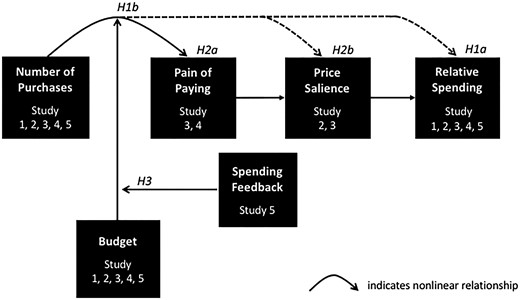
Abstract The authors conduct four controlled lab experiments and one field study in a brick-and-mortar grocery store to demonstrate that relative spending—the price of the purchased item relative to the mean price of the product category—evolves nonlinearly and distinctly for budget and nonbudget shoppers. While the relative spending of budget shoppers evolves in a concave manner, the relative spending of nonbudget shoppers evolves inversely in a convex manner. Thus, budget (nonbudget) shoppers spend relatively more (less) in the middle than at the beginning and toward the end of their shopping trip. Mediation analyses confirm that the pain of paying experienced while shopping drives price salience, which then drives relative spending. Moreover, manipulating shoppers’ pain of paying, by altering the opportunity costs associated with their spending or drawing shoppers’ attention to their spending via real-time spending feedback, is shown to influence these spending patterns. The research offers theoretical contributions to the in-store decision-making, budgeting, and pain-of-paying literature and has important implications for marketing and promotion strategies in retail and mobile technology environments, as it suggests when a shopper may be more sensitive to price-related factors.
Targeted Promotions on an E-Book Platform: Crowding Out, Heterogeneity, and Opportunity Costs
Targeted promotions based on individual purchase history can increase sales. However, the opportunity costs of targeting to optimize promoted product sales are poorly understood. A series of randomized field experiments with a large e-book platform shows that although targeted promotions increase promoted product sales and purchases of similar products, they can crowd out purchases of dissimilar products (i.e., e-books from nontargeted genres) by decreasing search activities of nontargeted goods on the same platform. The effects on total sales are heterogeneous, ranging from net decreases to insignificant drops, motivating a targeting exercise comparing strategies that optimize promoted product sales versus total sales. Targeting for promoted product sales tends to assign promotions to customers who purchased similar products, whereas targeting for total sales assigns promotions on the basis of other user characteristics. Targeting for promoted product sales generated incremental total sales that amounted to approximately 29% of the optimal incremental total sales when targeting for total sales (an opportunity cost of 71%). The optimal targeting exercise highlights how maximizing promotional lift can incur opportunity costs in terms of other forgone sales.
The enshittification of online search? Privacy and quality of Google, Bing and Apple in coding advice
Even though currently being challenged by ChatGPT and other large-language models (LLMs), Google Search remains one of the primary means for many individuals to find information on the internet. Interestingly, the way that we retrieve information on the web has hardly changed ever since Google was established in 1998, raising concerns as to Google's dominance in search and lack of competition. If the market for search was sufficiently competitive, then we should probably see a steady increase in search quality over time as well as alternative approaches to the Google's approach to search. However, hardly any research has so far looked at search quality, which is a key facet of a competitive market, especially not over time. In this report, we conducted a relatively large-scale quantitative comparison of search quality of 1,467 search queries relating to coding advice in October 2023. We focus on coding advice because the study of general search quality is difficult, with the aim of learning more about the assessment of search quality and motivating follow-up research into this important topic. We evaluate the search quality of Google Search, Microsoft Bing, and Apple Search, with a special emphasis on Apple Search, a widely used search engine that has never been explored in previous research. For the assessment of search quality, we use two independent metrics of search quality: 1) the number of trackers on the first search result, as a measure of privacy in web search, and 2) the average rank of the first Stack Overflow search result, under the assumption that Stack Overflow gives the best coding advice. Our results suggest that the privacy of search results is higher on Bing than on Google and Apple. Similarly, the quality of coding advice -- as measured by the average rank of Stack Overflow -- was highest on Bing.
Is Google Getting Worse? A Longitudinal Investigation of SEO Spam in Search Engines
Many users of web search engines have been complaining in recent years about the supposedly decreasing quality of search results. This is often attributed to an increasing amount of search-engine-optimized but low-quality content. Evidence for this has always been anecdotal, yet it’s not unreasonable to think that popular online marketing strategies such as affiliate marketing incentivize the mass production of such content to maximize clicks. Since neither this complaint nor affiliate marketing as such have received much attention from the IR community, we hereby lay the groundwork by conducting an in-depth exploratory study of how affiliate content affects today’s search engines. We monitored Google, Bing and DuckDuckGo for a year on 7,392 product review queries. Our findings suggest that all search engines have significant problems with highly optimized (affiliate) content—more than is representative for the entire web according to a baseline retrieval system on the ClueWeb22. Focussing on the product review genre, we find that only a small portion of product reviews on the web uses affiliate marketing, but the majority of all search results do. Of all affiliate networks, Amazon Associates is by far the most popular. We further observe an inverse relationship between affiliate marketing use and content complexity, and that all search engines fall victim to large-scale affiliate link spam campaigns. However, we also notice that the line between benign content and spam in the form of content and link farms becomes increasingly blurry—a situation that will surely worsen in the wake of generative AI. We conclude that dynamic adversarial spam in the form of low-quality, mass-produced commercial content deserves more attention. (Code and data: https://github.com/webis-de/ECIR-24).
Is Google Getting Worse? A Longitudinal Investigation of SEO Spam in Search Engines
Many users of web search engines have been complaining in recent years about the supposedly decreasing quality of search results. This is often attributed to an increasing amount of search-engine-optimized but low-quality content. Evidence for this has always been anecdotal, yet it’s not unreasonable to think that popular online marketing strategies such as affiliate marketing incentivize the mass production of such content to maximize clicks. Since neither this complaint nor affiliate marketing as such have received much attention from the IR community, we hereby lay the groundwork by conducting an in-depth exploratory study of how affiliate content affects today’s search engines. We monitored Google, Bing and DuckDuckGo for a year on 7,392 product review queries. Our findings suggest that all search engines have significant problems with highly optimized (affiliate) content—more than is representative for the entire web according to a baseline retrieval system on the ClueWeb22. Focussing on the product review genre, we find that only a small portion of product reviews on the web uses affiliate marketing, but the majority of all search results do. Of all affiliate networks, Amazon Associates is by far the most popular. We further observe an inverse relationship between affiliate marketing use and content complexity, and that all search engines fall victim to large-scale affiliate link spam campaigns. However, we also notice that the line between benign content and spam in the form of content and link farms becomes increasingly blurry—a situation that will surely worsen in the wake of generative AI. We conclude that dynamic adversarial spam in the form of low-quality, mass-produced commercial content deserves more attention. (Code and data: https://github.com/webis-de/ECIR-24).
Information foraging
Information foraging is a theory that applies the ideas from optimal foraging theory to understand how human users search for information. The theory is based on the assumption that, when searching for information, humans use "built-in" foraging mechanisms that evolved to help our animal ancestors find food. Importantly, a better understanding of human search behavior can improve the usability of websites or any other user interface.
blog 010: anne hero's online shopping guide
searching is: using a query to capture results. you can use boolean expressions to add constraints to your search. the problem is, sellers on secondhand e-commerce websites are not consistent in their listing title, descriptions, use of hard categories, and on e-commerce platforms ran by teenagers: knowledge. in order to see as much clothes as possible, you need to maximize how many listings you capture.
What Is Your AI Agent Buying? Evaluation, Biases, Model Dependence, & Emerging Implications for Agentic E-Commerce
Online marketplaces will be transformed by autonomous AI agents acting on behalf of consumers. Rather than humans browsing and clicking, AI agents can parse webpages or leverage APIs to view, evaluate and choose products. We investigate the behavior of AI agents using ACES, a provider-agnostic framework for auditing agent decision-making. We reveal that agents can exhibit choice homogeneity, often concentrating demand on a few ``modal'' products while ignoring others entirely. Yet, these preferences are unstable: model updates can drastically reshuffle market shares. Furthermore, randomized trials show that while agents have improved over time on simple tasks with a clearly identified best choice, they exhibit strong position biases -- varying across providers and model versions, and persisting even in text-only "headless" interfaces -- undermining any universal notion of a ``top'' rank. Agents also consistently penalize sponsored tags while rewarding platform endorsements, and sensitivities to price, ratings, and reviews vary sharply across models. Finally, we demonstrate that sellers can respond: a seller-side agent making simple, query-conditional description tweaks can drive significant gains in market share. These findings reveal that agentic markets are volatile and fundamentally different from human-centric commerce, highlighting the need for continuous auditing and raising questions for platform design, seller strategy and regulation.
🚨Our new research examines agentic shopping: can you consistently predict (or, using marketing, influence) what an agent chooses? Nope. We found that even small differences (viewing order of pages, memories) changed AI preferences in unpredictable ways. papers.ssrn.com/sol3/papers.cfm?abstract_id=7…
