Artificial intelligence (AI) tools are increasingly used for written deliverables. This has created demand for distinguishing human-generated text from AI-generated text at scale, e.g., ensuring assignments were completed by students, product reviews written by actual customers, etc. A decision-maker aiming to implement a detector in practice must consider two key statistics: the False Negative Rate (FNR), which corresponds to the proportion of AI-generated text that is falsely classified as human, and the False Positive Rate (FPR), which corresponds to the proportion of human-written text that is falsely classified as AI-generated. We evaluate three leading commercial detectors—Pangram, OriginalityAI, GPTZero—and an open-source one —RoBERTa—on their performance in minimizing these statistics using a large corpus spanning genres, lengths, and models. Commercial detectors outperform open-source, with Pangram achieving near-zero FNR and FPR rates that remain robust across models, threshold rules, ultra-short passages, "stubs" (≤ 50 words) and ’humanizer’ tools. A decision-maker may weight one type of error (Type I vs. Type II) as more important than the other. To account for such a preference, we introduce a framework where the decision-maker sets a policy cap—a detector-independent metric reflecting tolerance for false positives or negatives. We show that Pangram is the only tool to satisfy a strict cap (FPR ≤ 0.005) without sacrificing accuracy. This framework is especially relevant given the uncertainty surrounding how AI may be used at different stages of writing, where certain uses may be encouraged (e.g., grammar correction) but may be difficult to separate from other uses.
Technical Report on the Pangram AI-Generated Text Classifier
We present Pangram Text, a transformer-based neural network trained to distinguish text written by large language models from text written by humans. Pangram Text outperforms zero-shot methods such as DetectGPT as well as leading commercial AI detection tools with over 38 times lower error rates on a comprehensive benchmark comprised of 10 text domains (student writing, creative writing, scientific writing, books, encyclopedias, news, email, scientific papers, short-form Q&A) and 8 open- and closed-source large language models. We propose a training algorithm, hard negative mining with synthetic mirrors, that enables our classifier to achieve orders of magnitude lower false positive rates on high-data domains such as reviews. Finally, we show that Pangram Text is not biased against nonnative English speakers and generalizes to domains and models unseen during training.

Testing of detection tools for AI-generated text
Recent advances in generative pre-trained transformer large language models have emphasised the potential risks of unfair use of artificial intelligence (AI) generated content in an academic environment and intensified efforts in searching for solutions to detect such content. The paper examines the general functionality of detection tools for AI-generated text and evaluates them based on accuracy and error type analysis. Specifically, the study seeks to answer research questions about whether existing detection tools can reliably differentiate between human-written text and ChatGPT-generated text, and whether machine translation and content obfuscation techniques affect the detection of AI-generated text. The research covers 12 publicly available tools and two commercial systems (Turnitin and PlagiarismCheck) that are widely used in the academic setting. The researchers conclude that the available detection tools are neither accurate nor reliable and have a main bias towards classifying the output as human-written rather than detecting AI-generated text. Furthermore, content obfuscation techniques significantly worsen the performance of tools. The study makes several significant contributions. First, it summarises up-to-date similar scientific and non-scientific efforts in the field. Second, it presents the result of one of the most comprehensive tests conducted so far, based on a rigorous research methodology, an original document set, and a broad coverage of tools. Third, it discusses the implications and drawbacks of using detection tools for AI-generated text in academic settings.
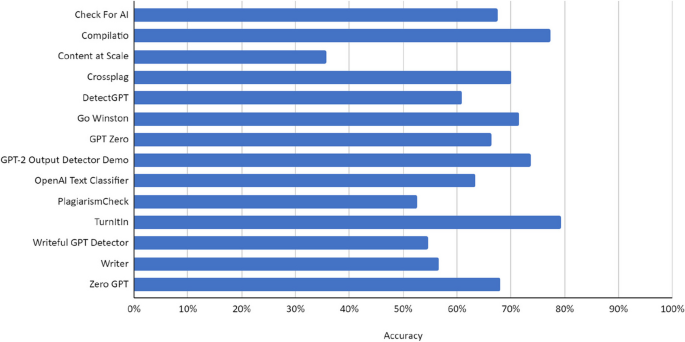
Testing of detection tools for AI-generated text
Recent advances in generative pre-trained transformer large language models have emphasised the potential risks of unfair use of artificial intelligence (AI) generated content in an academic environment and intensified efforts in searching for solutions to detect such content. The paper examines the general functionality of detection tools for AI-generated text and evaluates them based on accuracy and error type analysis. Specifically, the study seeks to answer research questions about whether existing detection tools can reliably differentiate between human-written text and ChatGPT-generated text, and whether machine translation and content obfuscation techniques affect the detection of AI-generated text. The research covers 12 publicly available tools and two commercial systems (Turnitin and PlagiarismCheck) that are widely used in the academic setting. The researchers conclude that the available detection tools are neither accurate nor reliable and have a main bias towards classifying the output as human-written rather than detecting AI-generated text. Furthermore, content obfuscation techniques significantly worsen the performance of tools. The study makes several significant contributions. First, it summarises up-to-date similar scientific and non-scientific efforts in the field. Second, it presents the result of one of the most comprehensive tests conducted so far, based on a rigorous research methodology, an original document set, and a broad coverage of tools. Third, it discusses the implications and drawbacks of using detection tools for AI-generated text in academic settings.
Policies Permitting LLM Use for Polishing Peer Reviews Are Currently Not Enforceable
A number of scientific conferences and journals have recently enacted policies that prohibit LLM usage by peer reviewers, except for polishing, paraphrasing, and grammar correction of otherwise human-written reviews. But, are these policies enforceable? To answer this question, we assemble a dataset of peer reviews simulating multiple levels of human-AI collaboration, and evaluate five state-of-the-art detectors, including two commercial systems. Our analysis shows that all detectors misclassify a non-trivial fraction of LLM-polished reviews as AI-generated, thereby risking false accusations of academic misconduct. We further investigate whether peer-review-specific signals, including access to the paper manuscript and the constrained domain of scientific writing, can be leveraged to improve detection. While incorporating such signals yields measurable gains in some settings, we identify limitations in each approach and find that none meets the accuracy standards required for identifying AI use in peer reviews. Importantly, our results suggest that recent public estimates of AI use in peer reviews through the use of AI-text detectors should be interpreted with caution, as current detectors misclassify mixed reviews (collaborative human-AI outputs) as fully AI generated, potentially overstating the extent of policy violations.
AI-text detection tools are really easy to fool
A recent crop of AI systems claiming to detect AI-generated text perform poorly—and it doesn’t take much to get past them.
Artificial Artificial Artificial Intelligence: Crowd Workers Widely Use Large Language Models for Text Production Tasks
Large language models (LLMs) are remarkable data annotators. They can be used to generate high-fidelity supervised training data, as well as survey and experimental data. With the widespread adoption of LLMs, human gold--standard annotations are key to understanding the capabilities of LLMs and the validity of their results. However, crowdsourcing, an important, inexpensive way to obtain human annotations, may itself be impacted by LLMs, as crowd workers have financial incentives to use LLMs to increase their productivity and income. To investigate this concern, we conducted a case study on the prevalence of LLM usage by crowd workers. We reran an abstract summarization task from the literature on Amazon Mechanical Turk and, through a combination of keystroke detection and synthetic text classification, estimate that 33-46% of crowd workers used LLMs when completing the task. Although generalization to other, less LLM-friendly tasks is unclear, our results call for platforms, researchers, and crowd workers to find new ways to ensure that human data remain human, perhaps using the methodology proposed here as a stepping stone. Code/data: https://github.com/epfl-dlab/GPTurk
Technical Report on the Pangram AI-Generated Text Classifier
We present Pangram Text, a transformer-based neural network trained to distinguish text written by large language models from text written by humans. Pangram Text outperforms zero-shot methods...
Can AI Detectors Be Trusted?
Society has always trusted editors, teachers, peer reviewers, and readers to set acceptable standards for writing. In the past, the biggest challenge was detecting plagiarism and cracking down on other forms of cheating. Now, AI detectors are rewriting the script: they assign a score based on the likelihood that the text was created by a human or a large language model (LLM).

AI Fact-Checking in the Wild: A Field Evaluation of LLM-Written Community Notes on X
Large language models (LLMs) show promising capabilities for fact-checking, yet prior work evaluates them only in controlled offline settings using benchmarks or crowdworker judgments. Success in real-world fact-checking depends also on how content is judged within a live platform environment. We present the first field evaluation of LLM fact-checking deployed on a live social media platform, testing performance directly through X Community Notes’ “AI writer” feature over a three-month period. Our LLM writer, a multi-step pipeline that handles multimodal content, conducts web and platform-native search, and writes contextual notes, was deployed to write 1,614 notes on 1,597 tweets and compared against 1,332 human-written notes on the same tweets using 108,169 ratings from 42,521 raters. Direct comparison of note-level platform outcomes is complicated by differences in submission timing and exposure between LLM and human notes; we therefore pursue two analysis strategies: a rating-level analysis modeling individual rater evaluations, and a note-level analysis that relies on common raters who rated all notes on the same post. Rating-level analysis shows that LLM notes receive more positive ratings than human notes across raters with different political viewpoints, and note-level analysis shows LLM notes achieve significantly higher helpfulness scores among common raters. Rater-provided tags suggest that people consider LLM notes to use more neutral language and cite better sources. These findings provide field evidence that LLMs can contribute broadly helpful fact-checking notes at scale, while showing that their evaluation is shaped by platform dynamics absent from controlled offline settings.
The Consent Layer: Using ligatures to make web text expensive to scrape without asking
ShieldFont is an open-source creative technology project that offers a practical opt-out from unauthorized AI training and disrupts what is collected when that choice is ignored. It swaps 45.8% of content words (around 24.4% of all words) in a page's source code for other (partially) random words, while the font restores the original text on screen. Readers see the work as intended; mass scrapers collect an altered version. In testing, shielding caused over 90% of pages that would otherwise pass the quality filter to be rejected, keeping them out of the training pipeline. Of those that still passed, 19.4% of all words conveyed false meaning, adding noise to unauthorized AI training datasets. This paper's goal is to walk newcomers through the whole process, in plain language and in order: the project's rationale, how it was built, the results, how to deploy it, and where to contribute.
AI use in American newspapers is widespread, uneven, and rarely disclosed
AI is rapidly transforming journalism, but the extent of its use in published newspaper articles remains unclear. We address this gap by auditing a large-scale dataset of 186K articles from online editions of 1.5K American newspapers published in the summer of 2025. Using Pangram, a state-of-the-art AI detector, we discover that approximately 9% of newly-published articles are either partially or fully AI-generated. This AI use is unevenly distributed, appearing more frequently in smaller, local outlets, in specific topics such as weather and technology, and within certain ownership groups. We also analyze 45K opinion pieces from Washington Post, New York Times, and Wall Street Journal, finding that they are 6.4 times more likely to contain AI-generated content than news articles from the same publications, with many AI-flagged op-eds authored by prominent public figures. Despite this prevalence, we find that AI use is rarely disclosed: a manual audit of 100 AI-flagged articles found only five disclosures of AI use. Overall, our audit highlights the immediate need for greater transparency and updated editorial standards regarding the use of AI in journalism to maintain public trust.
Documenting Large Webtext Corpora: A Case Study on the Colossal Clean Crawled Corpus
Large language models have led to remarkable progress on many NLP tasks, and researchers are turning to ever-larger text corpora to train them. Some of the largest corpora available are made by scraping significant portions of the internet, and are frequently introduced with only minimal documentation. In this work we provide some of the first documentation for the Colossal Clean Crawled Corpus (C4; Raffel et al., 2020), a dataset created by applying a set of filters to a single snapshot of Common Crawl. We begin by investigating where the data came from, and find a significant amount of text from unexpected sources like patents and US military websites. Then we explore the content of the text itself, and find machine-generated text (e.g., from machine translation systems) and evaluation examples from other benchmark NLP datasets. To understand the impact of the filters applied to create this dataset, we evaluate the text that was removed, and show that blocklist filtering disproportionately removes text from and about minority individuals. Finally, we conclude with some recommendations for how to created and document web-scale datasets from a scrape of the internet.