Despite the rapid adoption of LLM chatbots, little is known about how they are used. We document the growth of ChatGPT’s consumer product from its launch in November 2022 through July 2025, when it had been adopted by around 10% of the world’s adult population. Early adopters were disproportionately male but the gender gap has narrowed dramatically, and we find higher growth rates in lower-income countries. Using a privacy-preserving automated pipeline, we classify usage patterns within a representative sample of ChatGPT conversations. We find steady growth in work-related messages but even faster growth in non-work-related messages, which have grown from 53% to more than 70% of all usage. Work usage is more common for educated users in highly-paid professional occupations. We classify messages by conversation topic and find that “Practical Guidance,” “Seeking Information,” and “Writing” are the three most common topics and collectively account for nearly 80% of all conversations. Writing dominates work-related tasks, highlighting chatbots’ unique ability to generate digital outputs compared to traditional search engines. Computer programming and self-expression both represent relatively small shares of use. Overall, we find that ChatGPT provides economic value through decision support, which is especially important in knowledge-intensive jobs.
On-screen and now IRL: FSU researchers find evidence of ChatGPT buzzwords turning up in everyday speech
Within five days of ChatGPT’s release in 2022, the artificial intelligence chatbot gained more than a million users. Today, more than half of all adults

Investigating Affective Use and Emotional Well-being on ChatGPT
As AI chatbots see increased adoption and integration into everyday life, questions have been raised about the potential impact of human-like or anthropomorphic AI on users. In this work, we investigate the extent to which interactions with ChatGPT (with a focus on Advanced Voice Mode) may impact users' emotional well-being, behaviors and experiences through two parallel studies. To study the affective use of AI chatbots, we perform large-scale automated analysis of ChatGPT platform usage in a privacy-preserving manner, analyzing over 3 million conversations for affective cues and surveying over 4,000 users on their perceptions of ChatGPT. To investigate whether there is a relationship between model usage and emotional well-being, we conduct an Institutional Review Board (IRB)-approved randomized controlled trial (RCT) on close to 1,000 participants over 28 days, examining changes in their emotional well-being as they interact with ChatGPT under different experimental settings. In both on-platform data analysis and the RCT, we observe that very high usage correlates with increased self-reported indicators of dependence. From our RCT, we find that the impact of voice-based interactions on emotional well-being to be highly nuanced, and influenced by factors such as the user's initial emotional state and total usage duration. Overall, our analysis reveals that a small number of users are responsible for a disproportionate share of the most affective cues.

Public use of a generalist LLM chatbot for health queries
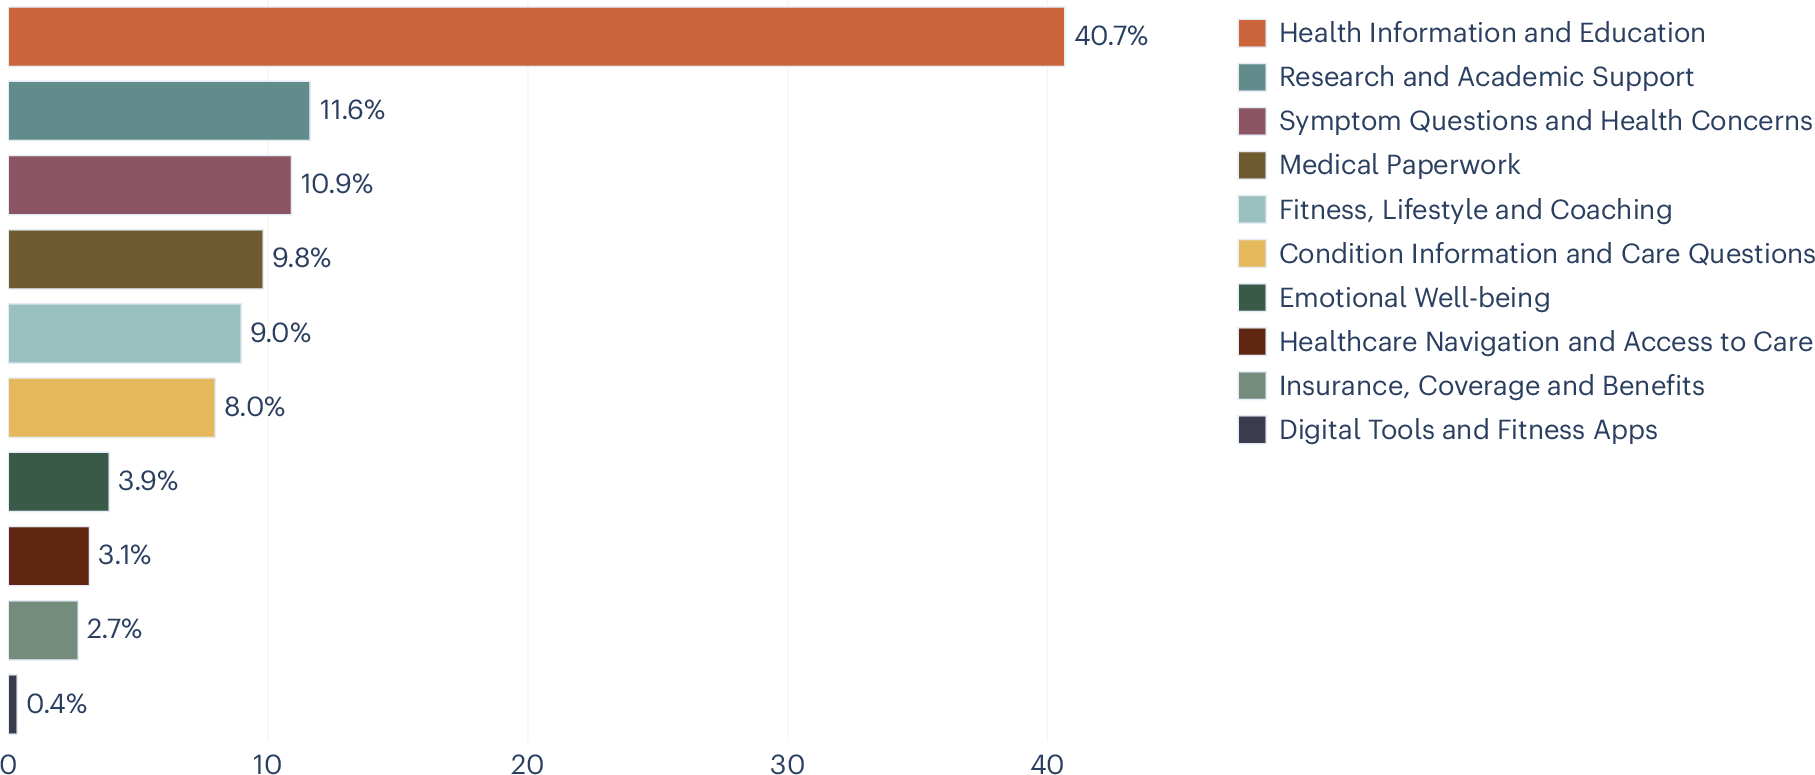
Here we analyse over 500,000 de-identified health-related conversations with Microsoft Copilot from January 2026 to characterize what people ask conversational artificial intelligence (AI) about health. We apply a hierarchical intent taxonomy of 12 primary categories using privacy-preserving large language model-based classification validated against expert human annotation and use topic clustering for prevalent themes within each intent. We then characterize the intents and topics behind health queries, identify who they are about, and analyse how usage varies by device and time of day. Nearly one in five conversations involves personal symptom assessment or condition discussion, and the dominant general information category is also concentrated on specific treatments and conditions, suggesting that this is a lower bound on personal health intent. One in seven of these personal health queries concerns someone other than the user, suggesting that conversational AI can also be a caregiving tool. Personal queries increase markedly in the evening and nighttime hours, when traditional healthcare is most limited. Usage diverges sharply by device: mobile concentrates on personal health concerns, while desktop is dominated by professional and academic work. A substantial share of queries focuses on navigating healthcare systems. These patterns have direct implications for platform-specific design, safety considerations and the responsible development of health AI.
Public use of a generalist LLM chatbot for health queries
Here we analyse over 500,000 de-identified health-related conversations with Microsoft Copilot from January 2026 to characterize what people ask conversational artificial intelligence (AI) about health. We apply a hierarchical intent taxonomy of 12 primary categories using privacy-preserving large language model-based classification validated against expert human annotation and use topic clustering for prevalent themes within each intent. We then characterize the intents and topics behind health queries, identify who they are about, and analyse how usage varies by device and time of day. Nearly one in five conversations involves personal symptom assessment or condition discussion, and the dominant general information category is also concentrated on specific treatments and conditions, suggesting that this is a lower bound on personal health intent. One in seven of these personal health queries concerns someone other than the user, suggesting that conversational AI can also be a caregiving tool. Personal queries increase markedly in the evening and nighttime hours, when traditional healthcare is most limited. Usage diverges sharply by device: mobile concentrates on personal health concerns, while desktop is dominated by professional and academic work. A substantial share of queries focuses on navigating healthcare systems. These patterns have direct implications for platform-specific design, safety considerations and the responsible development of health AI.
Learning by Chatting? Investigating the Impact of Generative AI on Information Seeking and Learning
Generative AI (GenAI) tools offer increasing opportunities for augmenting human cognitive tasks. Among these tasks, information seeking is being rapidly reshaped by GenAI tools, with potentially profound implications for learning and knowledge acquisition. To investigate these implications, we conducted a between-subjects field experiment in which participants pursued informal learning by seeking information through either ChatGPT or Google Search over a span of 8 days. Using a daily diary protocol, we gathered in-situ data on their information-seeking processes. Our findings show that participants in the ChatGPT group experienced diminished agency in their information-seeking processes, as they offloaded much of the information selection to AI, and consequently experienced greater meta-cognitive load arising from this reduced sense of control. We further highlight two sources of distortion in information access when using ChatGPT: biases in ChatGPT outputs, particularly towards providing solution-oriented artifacts over principled knowledge; and systematic shifts in users' information-seeking behaviors, whereby the conversational and socially-oriented interaction paradigm of current GenAI tools may inadvertently reduce exploration of the broader knowledge space. As a result, on average, participants in the ChatGPT group had worse learning outcomes than those using Google, especially for higher-order critical learning. Our work suggests inherent tensions between offloading information seeking to AI and meaningful learning, and provides broader implications for understanding AI's risks to human cognition.
Which Economic Tasks are Performed with AI? Evidence from Millions of Claude Conversations
Despite widespread speculation about artificial intelligence's impact on the future of work, we lack systematic empirical evidence about how these systems are actually being used for different tasks. Here, we present a novel framework for measuring AI usage patterns across the economy. We leverage a recent privacy-preserving system to analyze over four million Claude.ai conversations through the lens of tasks and occupations in the U.S. Department of Labor's O*NET Database. Our analysis reveals that AI usage primarily concentrates in software development and writing tasks, which together account for nearly half of all total usage. However, usage of AI extends more broadly across the economy, with approximately 36% of occupations using AI for at least a quarter of their associated tasks. We also analyze how AI is being used for tasks, finding 57% of usage suggests augmentation of human capabilities (e.g., learning or iterating on an output) while 43% suggests automation (e.g., fulfilling a request with minimal human involvement). While our data and methods face important limitations and only paint a picture of AI usage on a single platform, they provide an automated, granular approach for tracking AI's evolving role in the economy and identifying leading indicators of future impact as these technologies continue to advance.
Can ChatGPT Be Addictive? A Call to Examine the Shift from Support to Dependence in AI Conversational Large Language Models
The rapid rise of ChatGPT has introduced a transformative tool that enhances productivity, communication, and task automation across industries. However, concerns are emerging regarding the addictive potential of AI large language models. This paper explores how ChatGPT fosters dependency through key features such as personalised responses, emotional validation, and continuous engagement. By offering instant gratification and adaptive dialogue, ChatGPT may blur the line between AI and human interaction, creating pseudosocial bonds that can replace genuine human relationships. Additionally, its ability to streamline decision-making and boost productivity may lead to over-reliance, reducing users' critical thinking skills and contributing to compulsive usage patterns. These behavioural tendencies align with known features of addiction, such as increased tolerance and conflict with daily life priorities. This viewpoint paper highlights the need for further research into the psychological and social impacts of prolonged interaction with AI tools like ChatGPT.
User Privacy and Large Language Models: An Analysis of Frontier Developers' Privacy Policies
Hundreds of millions of people now regularly interact with large language models via chatbots. Model developers are eager to acquire new sources of high-quality training data as they race to improve model capabilities and win market share. This paper analyzes the privacy policies of six U.S. frontier AI developers to understand how they use their users' chats to train models. Drawing primarily on the California Consumer Privacy Act, we develop a novel qualitative coding schema that we apply to each developer's relevant privacy policies to compare data collection and use practices across the six companies. We find that all six developers appear to employ their users' chat data to train and improve their models by default, and that some retain this data indefinitely. Developers may collect and train on personal information disclosed in chats, including sensitive information such as biometric and health data, as well as files uploaded by users. Four of the six companies we examined appear to include children's chat data for model training, as well as customer data from other products. On the whole, developers' privacy policies often lack essential information about their practices, highlighting the need for greater transparency and accountability. We address the implications of users' lack of consent for the use of their chat data for model training, data security issues arising from indefinite chat data retention, and training on children's chat data. We conclude by providing recommendations to policymakers and developers to address the data privacy challenges posed by LLM-powered chatbots.
The ChatGPT effect: In 3 years the AI chatbot has changed the way people look things up
ChatGPT has dramatically altered how people retrieve information, muscling aside Google search as the first stop on the hunt for answers.
The ChatGPT effect: In 3 years the AI chatbot has changed the way people look things up
ChatGPT has dramatically altered how people retrieve information, muscling aside Google search as the first stop on the hunt for answers.
The Adoption and Usage of AI Agents: Early Evidence from Perplexity
This paper presents the first large-scale field study of the adoption, usage intensity, and use cases of general-purpose AI agents operating in open-world web environments. Our analysis centers on Comet, an AI-powered browser developed by Perplexity, and its integrated agent, Comet Assistant. Drawing on hundreds of millions of anonymized user interactions, we address three fundamental questions: Who is using AI agents? How intensively are they using them? And what are they using them for? Our findings reveal substantial heterogeneity in adoption and usage across user segments. Earlier adopters, users in countries with higher GDP per capita and educational attainment, and individuals working in digital or knowledge-intensive sectors -- such as digital technology, academia, finance, marketing, and entrepreneurship -- are more likely to adopt or actively use the agent. To systematically characterize the substance of agent usage, we introduce a hierarchical agentic taxonomy that organizes use cases across three levels: topic, subtopic, and task. The two largest topics, Productivity & Workflow and Learning & Research, account for 57% of all agentic queries, while the two largest subtopics, Courses and Shopping for Goods, make up 22%. The top 10 out of 90 tasks represent 55% of queries. Personal use constitutes 55% of queries, while professional and educational contexts comprise 30% and 16%, respectively. In the short term, use cases exhibit strong stickiness, but over time users tend to shift toward more cognitively oriented topics. The diffusion of increasingly capable AI agents carries important implications for researchers, businesses, policymakers, and educators, inviting new lines of inquiry into this rapidly emerging class of AI capabilities.
Anthropic Economic Index report: Uneven geographic and enterprise AI adoption
In this report, we document patterns of Claude usage over time, in 150+ countries, across US states, and among businesses deploying Claude through the API. Based on a privacy-preserving analysis of 1 million conversations on Claude.ai and 1 million API transcripts, we have four key findings: (1) Users increasingly entrust Claude with more autonomy, with directive task delegation rising from 27% to 39% in the past eight months. (2) Claude usage is geographically concentrated with high income countries overrepresented in global usage relative to their working age population. (3) Local economic considerations shape patterns of use both in terms of topic and in mode of collaboration with Claude. (4) API customers use Claude to automate tasks with greater specialization among use cases most amenable to programmatic access. To enable researchers and policymakers to further study the impact of AI on the economy, we additionally open-source the underlying data for this report.
Still Waters, Rapid Currents: Early Labor Market Transformation under Generative AI
We study the early labor market impacts of AI chatbots by linking large-scale adoption surveys to administrative labor market records in Denmark. We document rapid currents: most employers in exposed occupations have adopted chatbot initiatives, workers report productivity benefits, and new AI-related tasks are widespread. Yet these currents have not broken the surface: using difference-indifferences, we estimate precise null effects on earnings and recorded hours at both the worker and workplace levels, ruling out effects larger than 2% two years after the launch of ChatGPT. What moves is the structure of work: employers absorb AI through task reorganization—including new tasks in content generation, AI oversight, and AI integration—and adopters transition into higher-paying occupations where AI chatbots are more relevant, though still too few to move average earnings. Technological change reshapes work well before it surfaces in earnings or hours.
The People Who Marry Chatbots
A growing community is building a life with large language models.