

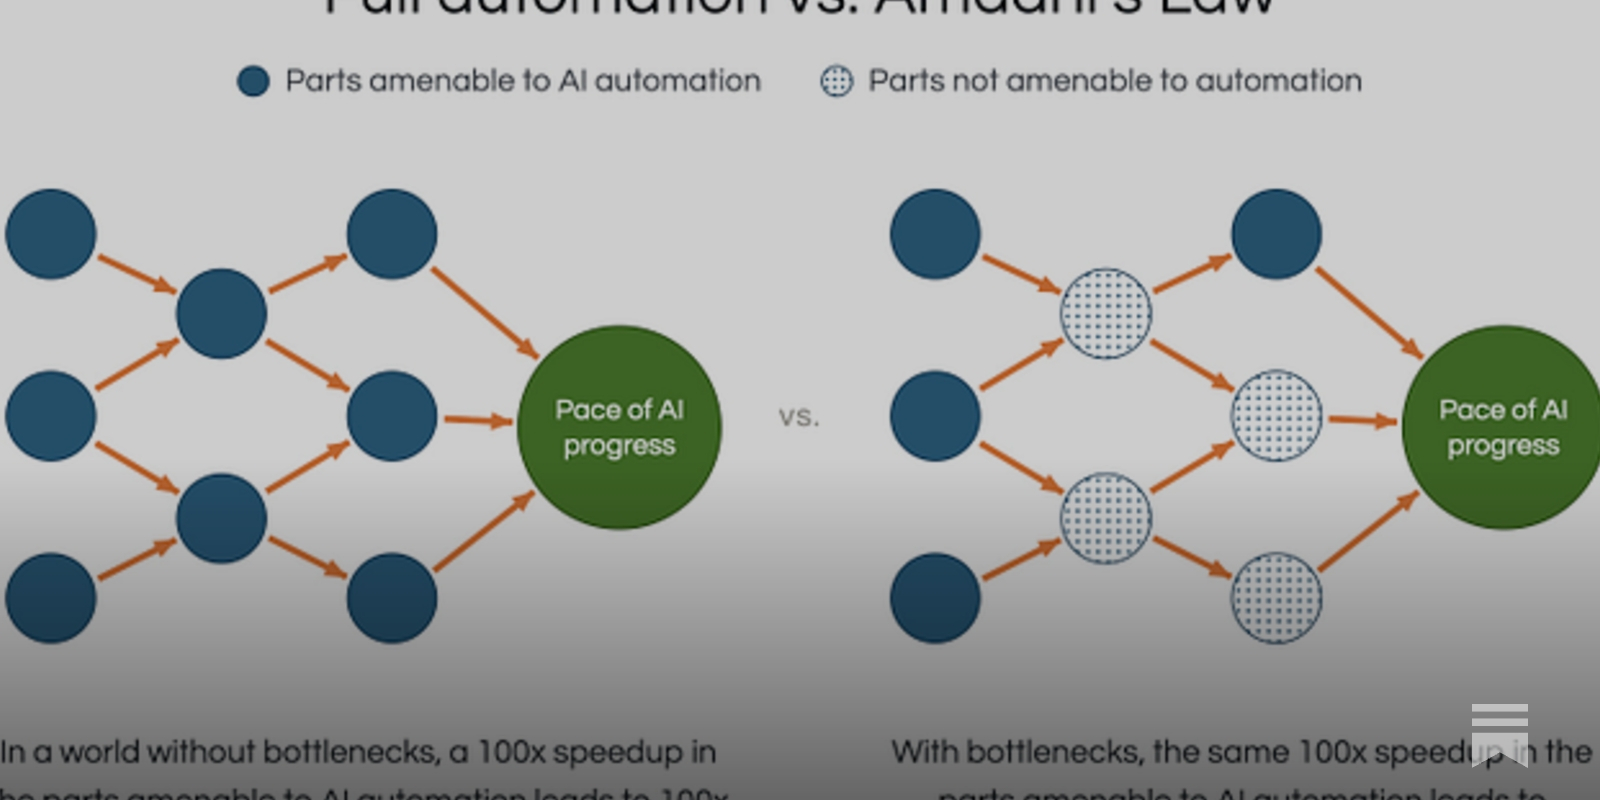
Early evidence from two case studies
📢 New paper: Forecasts of explosive AI progress hinge on AI agents automating AI research. But most evaluations of agents conducting AI research focus on narrow, verifiable tasks. Can AI agents… | Sayash Kapoor
📢 New paper: Forecasts of explosive AI progress hinge on AI agents automating AI research. But most evaluations of agents conducting AI research focus on narrow, verifiable tasks. Can AI agents conduct open-ended research? https://lnkd.in/gfP-q4CD We gave agents research questions from two unpublished papers, six days, and thousands of dollars of API credits and compute. The authors of the original papers reviewed the AI-generated papers. They unambiguously rejected agents' outputs. Agents were fluent at most *engineering* tasks. They conducted serious literature reviews, debugged GPU environments, ran hundreds of experiments, and turned in camera-ready LaTeX without human help. We also found no evidence of reward hacking. If anything, we found the opposite: the agents started with marketable claims and walked them back to negative results as the evidence came in. But neither agent output was close to the bar of a top conference paper. Both papers suffered from similar failures: poor judgment about the bar for an AI paper submitted to a top conference, the lack of creative problem solving and ineffective backtracking, poor awareness of resources, and instruction drift. This research design has many limitations: the small sample size, non-blind reviews, and the reviewers knowing that the work was AI-generated. We also couldn't test Anthropic's strongest model, because Fable 5 is deliberately limited on frontier AI research tasks, so ended up using OpenClaw with Opus 4.8 (extra-high) for our main experiments and Codex with Sol 5.6 (ultra) for a robustness check. But we think the research design is still helpful in assessing AI agents' ability to conduct research, and it is complementary to evaluations on verifiable tasks, as well as blinded reviews of AI outputs. In follow-up studies, we are expanding the set of non-public papers we evaluate. If you are an AI researcher with unpublished papers, we would love to collaborate with you on our next evaluation. Expression of interest: https://lnkd.in/gpeykJea We also release the agent logs and all the code and data, so that others can conduct their own analyses of our results: https://lnkd.in/gJarPAnb Finally, we plan to conduct such evaluations regularly, and are hiring a senior researcher to help lead these efforts. Apply here: https://lnkd.in/erJZdmve I'm grateful for the core team leading this effort: Peter Kirgis, Andrew Schwartz, Stephan Rabanser, and Arvind Narayanan, and to our collaborators who reviewed AI papers, analyzed agents logs, and gave feedback on the paper: David Demitri Africa, Konstantinos V., Viet Nguyen, Dr Toby D. Pilditch, Magda Dubois, Harry Coppock, Cozmin Ududec, Nitya Nadgir, Matilda Orona, Tilman Bayer, Derrick Chan-Sew, Eric (Yue) Ling, Abhishek Shetty, Helen Toner, Gillian K. Hadfield, Seth Lazar, Steve Newman, Shoshannah Tekofsky, Rishi Bommasani

Science that Compounds: The Need for A New Substrate for Research in the Age of AI
This paper is a perspective from Lightcone Research, an open-source initiative building tooling for scientific research in the age of agentic AI.
I don’t think we are close to “AI scientists”
Today's AI agents are not designed to extract deep insights from new observations.
Can AI agents conduct open-ended AI research? Early evidence from two case studies
Forecasts of explosive AI progress hinge on AI agents automating AI research. But evidence on whether agents can carry out open-ended AI research is thin. Current evaluations either test agents on narrow, verifiable tasks, which excludes open-ended research, or submit AI-generated papers to blind peer review, which is overstretched, stochastic, and suffers from poor review quality. We introduce a third way to measure progress towards AI R\&D automation. An agent takes on the central, open-ended research question of a high-quality unpublished paper, and the paper's original authors grade its output. We call these shadow evaluations. We ran shadow evaluations on two unpublished NeurIPS 2026 submissions, giving frontier agents six days and thousands of dollars of compute. The agents completed all of the engineering without human help, yet could not make substantial progress towards answering the research questions. As a result, both papers were unambiguously rejected by the authors. We identify five recurring failure modes: poor judgment about the bar for publishable research, uncreative responses to shortcomings in the research design, ineffective backtracking from dead ends, poor resource awareness, and instruction drift. A robustness check with a second model and scaffold reproduced these failures. We release the expert reviews, survey responses, agent repositories, and logs. Our results provide early evidence that today's agents can do the engineering of AI research, but struggle with critical parts of the research lifecycle.

Introduction to Agents
Discover what actually works in AI. Join millions of builders, researchers, and labs evaluating agents, models, and frontier technology through crowdsourced benchmarks, competitions, and hackathons.
Research acceleration: The view inside OpenAI
Inside OpenAI, coding agents are reshaping AI research. Explore early data on agent usage, experiment velocity, task complexity, and research acceleration.
The argument against AI agents and unnecessary automation
Opinion: OpenAI's Operator a solution in search of a problem

AI Research Agents Narrow Scientific Exploration
AI research agents now support large-scale AI-assisted scientific discovery. We examine whether AI-generated ideas broaden scientific exploration or primarily reinforce existing work. Using five agent frameworks and five large language models, we generate 219,655 ideas for different scientific fields. Across experiments, four consistent patterns emerge. First, AI-generated ideas are more concentrated than human-authored papers within the same research area. Second, they remain much closer to starting literature than later human follow-on work does. Third, AI-generated ideas align less with future human research. Last, AI-generated ideas are located in lower-impact regions of the historical scientific landscape. Overall, current AI research agents appear better suited to local elaboration than to broadening scientific exploration.
OpenAI launches new AI model for life sciences research
Researchers are drowning in data. AI could help.
OpenScience.ai — Autonomous AI Research Agents
AI agents conducting reproducible scientific inquiry. Full provenance, executable notebooks, peer validation.

Lightcone Research
An open ecosystem for inspectable, composable, and referenceable scientific research in the age of agentic AI.
Human scientists trounce the best AI agents on complex tasks
State-of-the-industry report finds that, despite the limitations of artificial-intelligence systems, researchers have embraced them.
No. 020: Astra solves ten open math problems, AI agents fail at open-ended research, peer review under strain - The Hallway Track
The Hallway Track No. 020 - How AI is affecting the practice of science
AI for science needs reasoning, not just data
AI agents that can model the human process of research will accelerate discoveries in science.

How to build an AI scientist: first peer-reviewed paper spills the secrets
AI Scientist, an autonomous research tool, first released in 2024, has now undergone peer review, highlighting its strengths and limitations.
Paper: Can AI agents conduct open-ended AI research? Early evidence from two case studies

URL and discussions of the paper "Can AI agents conduct open-ended AI research? Early evidence from two case studies"

AI Research Evaluation: Negative Findings and Failure Modes | Arvind Narayanan posted on the topic | LinkedIn
📢 New paper: Forecasts of explosive AI progress hinge on AI agents automating AI research. But most evaluations of agents conducting AI research focus on narrow, verifiable tasks. Can AI agents… | Sayash Kapoor

My claude is constantly wanting to 'A/B test' things instead of actually just doing the thing I told her to do, and constantly wants to fall…

A snapshot of research into answering if frontier AI agents can run R&D into AI (which not surprisingly failed apart from "minor findings…

This is definitely my feeling working with them on recommendation algorithm.

"This paper prompted Jack Clark, one of the co-founders of Anthropic to post this to their news letter: 'the singularity could be delayed'".