

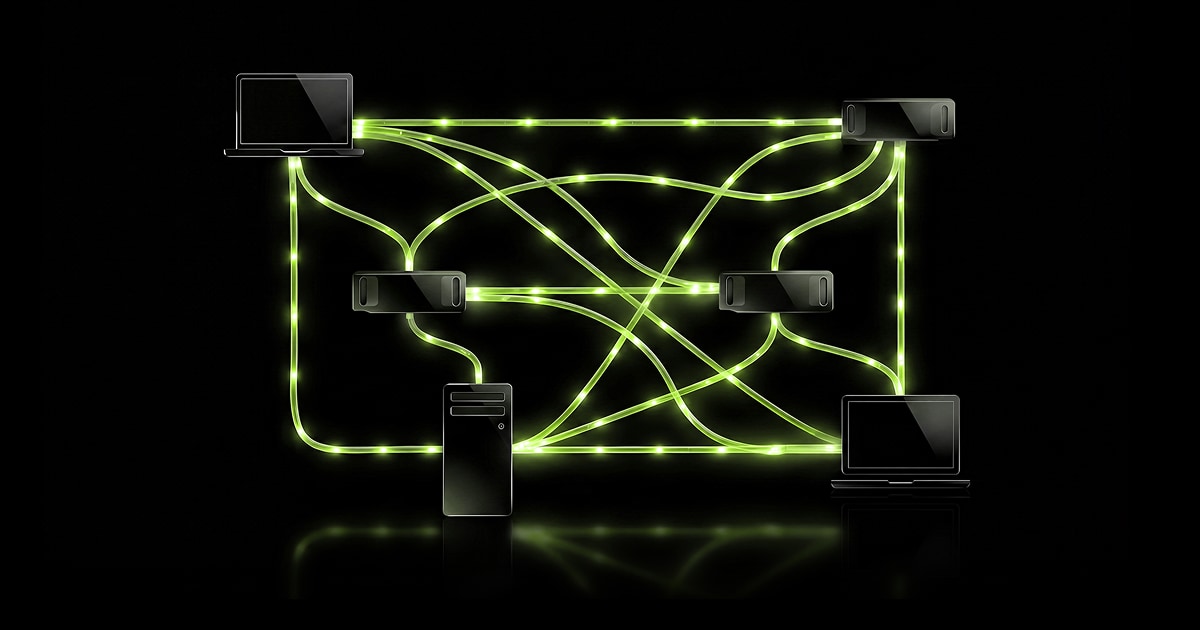
NVIDIA PAIR beta connects your RTX, DGX Spark, and Mac as a private local AI cluster. No cloud required. Route inference across Ollama, LM Studio, and more.
NVIDIA/Personal-AI-Router
Router that virtually distributes inference across connected devices in the home.
Nvidia wants your home network to work like a mini data center for local AI
Nvidia's PAIR (Personal AI Router) automatically spreads local AI requests across all available devices on a home network, cutting wait times for parallel agent tasks.

NVIDIA Levels Up Local AI Agents Across RTX PCs and DGX Spark
Announced at GTC Taipei at COMPUTEX, NVIDIA OpenShell brings secure agents to Windows with 2x inference performance on llama.cpp — plus, Adobe rebuilds its apps with performance and memory enhancements, and Blender adds NVIDIA DLSS 4.5 Ray Reconstruction for NVIDIA RTX Spark.
NVIDIA DGX Spark In-Depth Review: A New Standard for Local AI Inference
Thanks to NVIDIA’s early access program, we are thrilled to get our hands on the NVIDIA DGX™ Spark. It’s quite an unconventional system, as NVIDIA rarely releases compact, all-in-one machines that bri...
Introducing Portable Computer
Perplexity's Portable Computer brings local-first AI to NVIDIA's DGX Spark.
Portable Computer: Local-First AI
Run Perplexity Computer locally on NVIDIA DGX Spark. Private, on-device work with cloud escalation when needed.

Open Source AI Inference Benchmark | InferenceX
Compare AI inference performance across GPUs and frameworks. Real benchmarks on NVIDIA GB200, B200, AMD MI355X, and more. Free, open-source, continuously updated.
NVIDIA and Microsoft Reinvent Windows PCs for the Age of Personal AI
RTX Spark — a 1-Petaflop Superchip, the Full CUDA and RTX Ecosystem, and Windows-Native Agents — a New Beginning for Personal Computers News Summary: NVIDIA RTX Spark powers the world’s first Windows PCs purpose-built for personal agents, featuring 1 petaflop of AI performance, industry-leading power efficiency, full-stack NVIDIA AI and graphics technology, and up to 128GB of unified memory. NVIDIA and Microsoft collaborate to deliver a native Windows experience for personal agents, including new security primitives and NVIDIA OpenShell to run agents securely on primary devices. RTX Spark lets creators, AI developers and gamers render ultralarge 90GB+ 3D scenes, edit 12K 4:2:2 video, generate 4K AI videos, run 120B-parameter LLMs with up to 1 million tokens context using agents locally, and play AAA games at 1440p and over 100 frames per second. Adobe is rearchitecting Photoshop and Premiere from the ground up for RTX Spark to deliver 2x faster AI and graphics performance. RTX
Building with Open Models
TheStage AI – Faster, Cheaper AI Inference
Accelerate models on NVIDIA & edge. Full guides for setup, optimization & deploy. ANNA, QLIP, Elastic Models, CLI & API. Built for AI teams & devs.

NVIDIA NIM for Developers
NVIDIA NIM is a set of accelerated inference microservices that allow organizations to run AI models on NVIDIA GPUs anywhere—in the cloud, data center, workstations, and PCs.
Advancing AI Infrastructure for Agentic AI with NVIDIA DOCA In-Silicon Security | NVIDIA Technical Blog
The AI era is driving a new class of infrastructure: AI factories that transform data into intelligence for autonomous AI agents operating at unprecedented scale. Powered by accelerated computing…

Open-Source Agentic Inference Benchmark | InferenceX
Compare AgentX, InferenceX's long-context, multi-turn coding scenario, with fixed-sequence AI inference across chips and frameworks. Public NVIDIA and AMD runs update when configurations change.
Confidential AI Cloud · Private Inference on GPU TEE | Phala
Phala Cloud delivers confidential AI on TEE-protected GPUs — private LLM inference, sealed agents, and verifiable compute on Intel TDX + NVIDIA H100/H200.

Where AI Startups Scale to Production
Discover the most efficient way to build, tune and run your AI models and applications on top-notch NVIDIA® GPUs.

GradientHQ/parallax
Parallax is a distributed model serving framework that lets you build your own AI cluster anywhere