

A DiffusionGemma finetune at 71.7% on the Generative UI Benchmark, 5.5x its base.
Diffusion Models: A Comprehensive Survey of Methods and Applications
Diffusion models have emerged as a powerful new family of deep generative models with record-breaking performance in many applications, including image synthesis, video generation, and molecule...

Stanford CS25: V5 I Transformers in Diffusion Models for Image Generation and Beyond
Generative UI: A rich, custom, visual interactive user experience for any prompt
Yaniv Leviathan, Google Fellow, Dani Valevski, Senior Staff Software Engineer, Vishnu Natchu, Principal Engineer, and Yossi Matias, Vice President & Head of Google Research

DiffusionGemma as Jev: Open-Source vLLM Patch (2026) | explainx.ai Blog
A vLLM contributor built an open-source Jev clone using DiffusionGemma — roughly matching TypeSafe's proprietary model on accuracy.
Why Generative UI Is the New Frontier for Business Software
In an era where AI constructs UIs on the fly, discover how SAP is tapping generative UI to reimagine how works gets done.

What are Diffusion Models? | IBM
Diffusion models are generative models that “diffuse” training data with random noise, then learn to reverse the diffusion process to output new images.

Diffusion model
In machine learning, diffusion models, also known as diffusion-based generative models or score-based generative models, are a class of latent variable generative models. A diffusion model consists of two major components: the forward diffusion process, and the reverse sampling process.[1] The goal of diffusion models is to learn a diffusion process for a given dataset, such that the process can generate new elements that are distributed similarly as the original dataset. A diffusion model models data as generated by a diffusion process, whereby a new datum performs a random walk with drift through the space of all possible data.[2] A trained diffusion model can be sampled in many ways, with different efficiency and quality.
AI models collapse when trained on recursively generated data
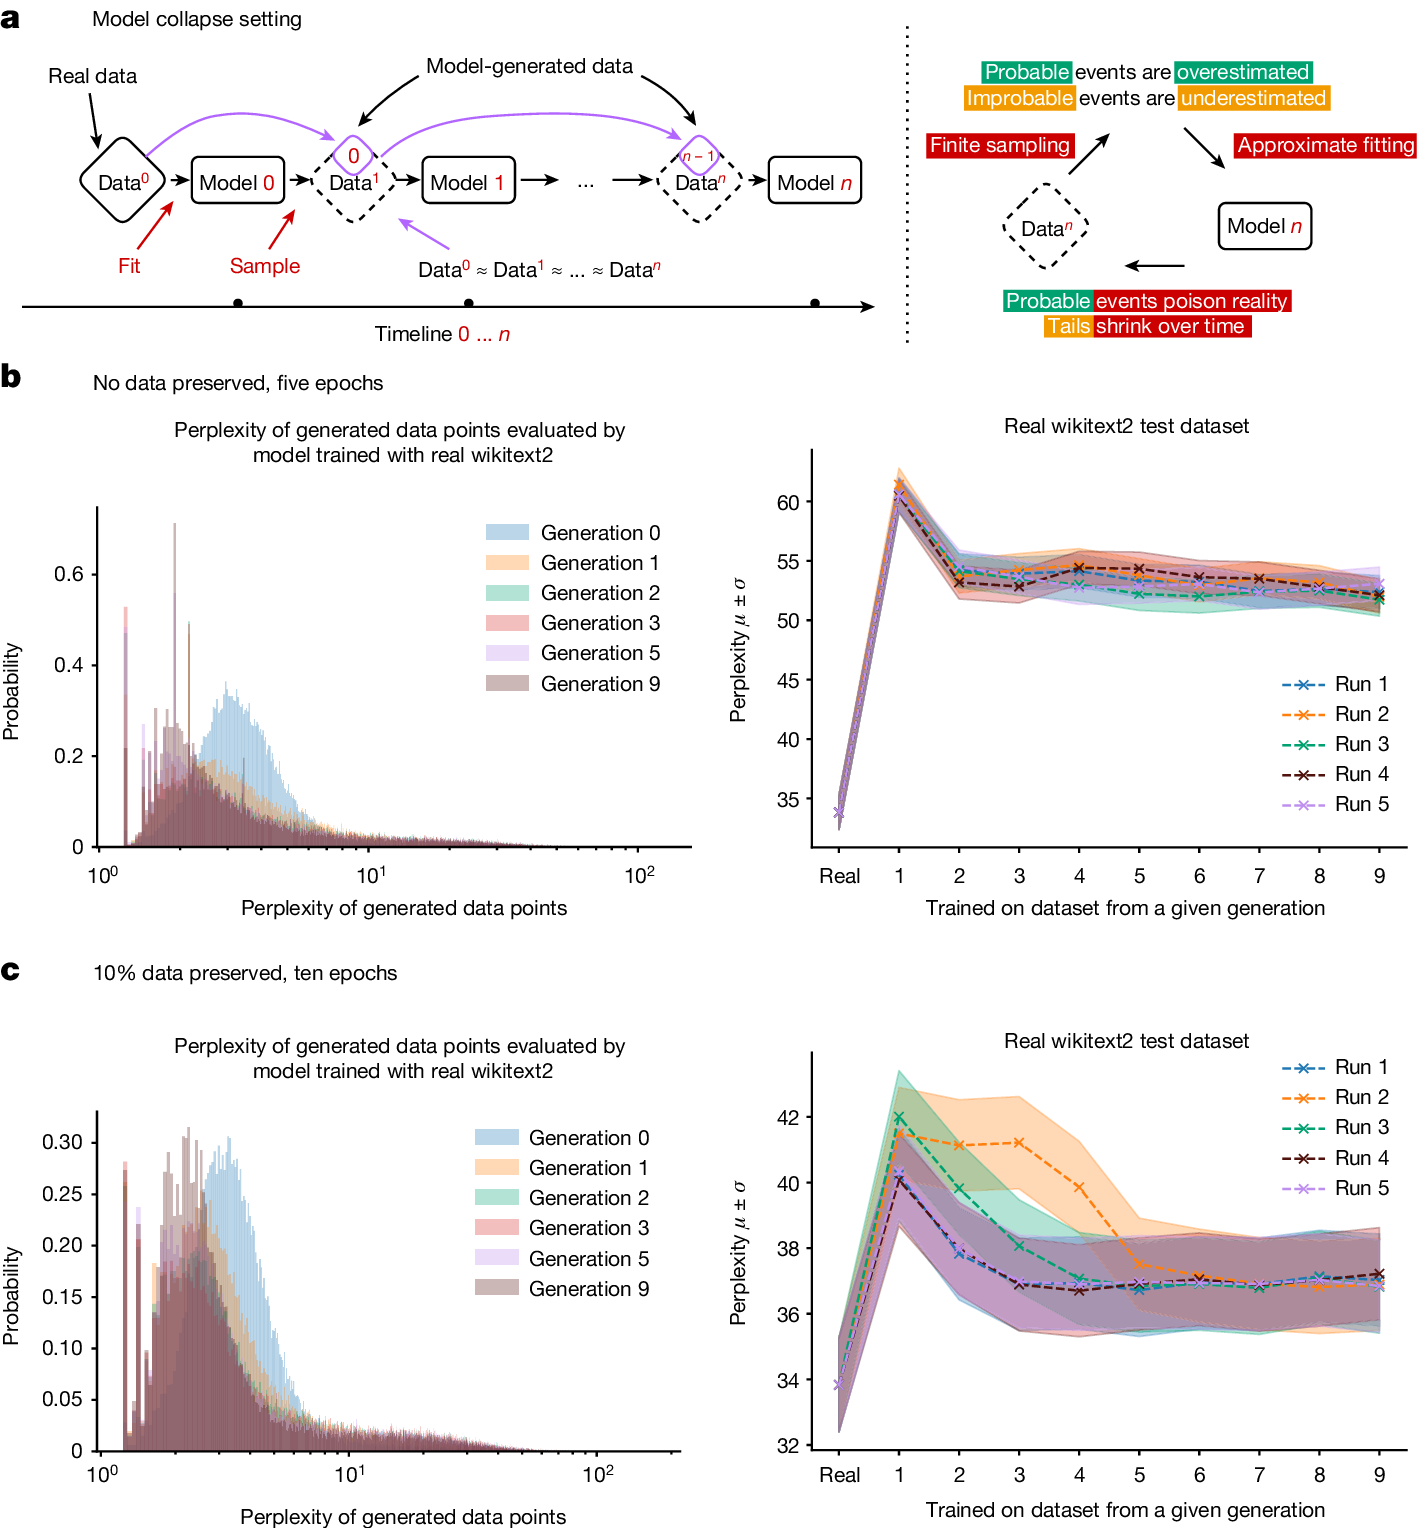
Stable diffusion revolutionized image creation from descriptive text. GPT-2 (ref. 1), GPT-3(.5) (ref. 2) and GPT-4 (ref. 3) demonstrated high performance across a variety of language tasks. ChatGPT introduced such language models to the public. It is now clear that generative artificial intelligence (AI) such as large language models (LLMs) is here to stay and will substantially change the ecosystem of online text and images. Here we consider what may happen to GPT-{n} once LLMs contribute much of the text found online. We find that indiscriminate use of model-generated content in training causes irreversible defects in the resulting models, in which tails of the original content distribution disappear. We refer to this effect as ‘model collapse’ and show that it can occur in LLMs as well as in variational autoencoders (VAEs) and Gaussian mixture models (GMMs). We build theoretical intuition behind the phenomenon and portray its ubiquity among all learned generative models. We demonstrate that it must be taken seriously if we are to sustain the benefits of training from large-scale data scraped from the web. Indeed, the value of data collected about genuine human interactions with systems will be increasingly valuable in the presence of LLM-generated content in data crawled from the Internet.
AI models collapse when trained on recursively generated data
Stable diffusion revolutionized image creation from descriptive text. GPT-2 (ref. 1), GPT-3(.5) (ref. 2) and GPT-4 (ref. 3) demonstrated high performance across a variety of language tasks. ChatGPT introduced such language models to the public. It is now clear that generative artificial intelligence (AI) such as large language models (LLMs) is here to stay and will substantially change the ecosystem of online text and images. Here we consider what may happen to GPT-{n} once LLMs contribute much of the text found online. We find that indiscriminate use of model-generated content in training causes irreversible defects in the resulting models, in which tails of the original content distribution disappear. We refer to this effect as ‘model collapse’ and show that it can occur in LLMs as well as in variational autoencoders (VAEs) and Gaussian mixture models (GMMs). We build theoretical intuition behind the phenomenon and portray its ubiquity among all learned generative models. We demonstrate that it must be taken seriously if we are to sustain the benefits of training from large-scale data scraped from the web. Indeed, the value of data collected about genuine human interactions with systems will be increasingly valuable in the presence of LLM-generated content in data crawled from the Internet.
DiffusionGemma Technical Report
We introduce DiffusionGemma, an experimental open-weight language model that uses discrete diffusion to generate text at exceptionally high speed. Rather than decoding one token at a time, DiffusionGemma iteratively refines blocks of 256 tokens in parallel, avoiding the sequential decoding bottleneck of conventional autoregressive (AR) large language models. Instead of training from scratch, we obtain DiffusionGemma by fine-tuning the mixture-of-experts Gemma 4 model with 3.8B activated and 25.2B total parameters. Our compute-efficient two-stage training pipeline uses fewer than 10% of the starting AR model's total training token budget. The first stage uses supervised fine-tuning to teach bidirectional denoising, while the second stage combines reinforcement learning with sampler distillation to jointly improve generation quality and inference efficiency. DiffusionGemma establishes a new Pareto frontier for the trade-off between generation speed and model capability. Averaged across our full evaluation suite, it generates around 20 tokens per forward pass and achieves roughly 1,500 output tokens per second on a single NVIDIA H100 GPU, which is substantially faster than AR models even with state-of-the-art speculative decoding. DiffusionGemma also retains the starting model's support for thinking mode, multimodal inputs, and long contexts. Despite diffusion fine-tuning, it remains capable of AR generation with only minor performance degradation, suggesting a path toward hybrid diffusion-AR decoding.
Awesome Generative UI - AI-Powered User Interface Generation Resources
Discover the best Generative UI resources: research papers, real-world cases, video tutorials, and open-source projects about AI-driven dynamic interface generation. Explore how LLMs like Gemini, Claude, and GPT are revolutionizing UI/UX design.
The Curse of Recursion: Training on Generated Data Makes Models Forget
Stable Diffusion revolutionised image creation from descriptive text. GPT-2, GPT-3(.5) and GPT-4 demonstrated astonishing performance across a variety of language tasks. ChatGPT introduced such...
Inference-Time Scaling for Generative Pre-Training | Jiaming Song
A short note on the false dichotomy between autoregression and diffusion, why flow maps help, and what this might mean for language models.
AI-Efficiency/Awesome-Model-Quantization
A curated collection of papers, benchmarks, surveys, and tools for model quantization, covering low-bit networks, LLMs, multimodal and generative models, vector and lattice quantization, and efficient deployment.
The physics behind diffusion models