


Humans collaborating with AI hold the promise of achieving superior outcomes compared to either acting alone (i.e., human–AI synergy). However, the conditions that facilitate such synergy when humans are advised by AI are not well understood. A recent meta-analysis showed that, on average, human–AI combinations do not outperform the better individual agent. We argue that this pessimistic conclusion arises from insufficient attention to human learning in experimental designs. To substantiate this claim, we reanalyzed all 74 studies included in the original meta-analysis and found that most previous research overlooked design features that foster human learning (e.g., outcome feedback to participants). Our reanalysis further revealed that studies providing outcome feedback show tentatively higher synergy than those without outcome feedback. Crucially, feedback paired with AI explanations was associated with positive synergy, while explanations without feedback were associated with negative synergy—suggesting that explanations improve synergy mainly when humans can learn to verify the AI’s reliability through feedback. Our reanalysis suggests that the current literature underestimates the potential of human–AI collaboration because it predominantly relies on paradigms that do not facilitate human learning, thus hindering humans from effectively adapting their collaboration strategies. However, experiments directly varying learning opportunities are needed for stronger, causal conclusions. We advocate for a paradigm shift in human–AI interaction research that explicitly addresses human learning and thus enhances our understanding of and support for successful human–AI collaboration.
How human–AI feedback loops alter human perceptual, emotional and social judgements
Artificial intelligence (AI) technologies are rapidly advancing, enhancing human capabilities across various fields spanning from finance to medicine. Despite their numerous advantages, AI systems can exhibit biased judgements in domains ranging from perception to emotion. Here, in a series of experiments (n = 1,401 participants), we reveal a feedback loop where human–AI interactions alter processes underlying human perceptual, emotional and social judgements, subsequently amplifying biases in humans. This amplification is significantly greater than that observed in interactions between humans, due to both the tendency of AI systems to amplify biases and the way humans perceive AI systems. Participants are often unaware of the extent of the AI’s influence, rendering them more susceptible to it. These findings uncover a mechanism wherein AI systems amplify biases, which are further internalized by humans, triggering a snowball effect where small errors in judgement escalate into much larger ones.

AI Assistance Reduces Persistence and Hurts Independent Performance
People often optimize for long-term goals in collaboration: A mentor or companion doesn't just answer questions, but also scaffolds learning, tracks progress, and prioritizes the other person's growth over immediate results. In contrast, current AI systems are fundamentally short-sighted collaborators - optimized for providing instant and complete responses, without ever saying no (unless for safety reasons). What are the consequences of this dynamic? Here, through a series of randomized controlled trials on human-AI interactions (N = 1,222), we provide causal evidence for two key consequences of AI assistance: reduced persistence and impairment of unassisted performance. Across a variety of tasks, including mathematical reasoning and reading comprehension, we find that although AI assistance improves performance in the short-term, people perform significantly worse without AI and are more likely to give up. Notably, these effects emerge after only brief interactions with AI (approximately 10 minutes). These findings are particularly concerning because persistence is foundational to skill acquisition and is one of the strongest predictors of long-term learning. We posit that persistence is reduced because AI conditions people to expect immediate answers, thereby denying them the experience of working through challenges on their own. These results suggest the need for AI model development to prioritize scaffolding long-term competence alongside immediate task completion.

AI Assistance Reduces Persistence and Hurts Independent Performance
People often optimize for long-term goals in collaboration: A mentor or companion doesn't just answer questions, but also scaffolds learning, tracks progress, and prioritizes the other person's growth over immediate results. In contrast, current AI systems are fundamentally short-sighted collaborators -- optimized for providing instant and complete responses, without ever saying no (unless for safety reasons). What are the consequences of this dynamic? Here, through a series of randomized controlled trials on human-AI interactions (N=1,222), we provide causal evidence for two key consequences of AI assistance: reduced persistence and impairment of unassisted performance. Across a variety of tasks, including mathematical reasoning and reading comprehension, we find that although AI assistance improves performance in the short-term, people perform significantly worse without AI and are more likely to give up. These findings are particularly concerning because persistence is foundational to skill acquisition and is one of the strongest predictors of long-term learning. We posit that persistence is reduced because AI conditions people to expect immediate answers, thereby denying them the experience of working through challenges on their own. These results add to the growing literature on cognitive offloading and AI-induced deskilling, and suggest the need for AI model development to prioritize scaffolding long-term competence alongside immediate task completion.
Thinking—Fast, Slow, and Artificial: How AI is Reshaping Human Reasoning and the Rise of Cognitive Surrender
People increasingly consult generative artificial intelligence (AI) while reasoning. As AI becomes embedded in daily thought, what becomes of human judgment? We introduce Tri-System Theory, extending dual-process accounts of reasoning by positing System 3: artificial cognition that operates outside the brain. System 3 can supplement or supplant internal processes, introducing novel cognitive pathways. A key prediction of the theory is "cognitive surrender"-adopting AI outputs with minimal scrutiny, overriding intuition (System 1) and deliberation (System 2). Across three preregistered experiments using an adapted Cognitive Reflection Test (N = 1,372; 9,593 trials), we randomized AI accuracy via hidden seed prompts. Participants chose to consult an AI assistant on a majority of trials (>50%). Relative to baseline (no System 3 access), accuracy significantly rose when AI was accurate and fell when it erred (+25/-15 percentage points; Study 1), the behavioral signature of cognitive surrender (AI-Accurate vs. AI-Faulty contrast; Cohen's h = 0.81). Engaging System 3 also increased confidence, even following errors. Time pressure (Study 2) and per-item incentives and feedback (Study 3) shifted baseline performance but did not eliminate this pattern: when accurate, AI buffered time-pressure costs and amplified incentive gains; when faulty, it consistently reduced accuracy regardless of situational moderators. Across studies, participants with higher trust in AI and lower need for cognition and fluid intelligence showed greater surrender to System 3. Tri-System Theory thus characterizes a triadic cognitive ecology, revealing how System 3 reframes human reasoning and may reshape autonomy and accountability in the age of AI.

Thinking—Fast, Slow, and Artificial: How AI is Reshaping Human Reasoning and the Rise of Cognitive Surrender
People increasingly consult generative artificial intelligence (AI) while reasoning. As AI becomes embedded in daily thought, what becomes of human judgment? We introduce Tri-System Theory, extending dual-process accounts of reasoning by positing System 3: artificial cognition that operates outside the brain. System 3 can supplement or supplant internal processes, introducing novel cognitive pathways. A key prediction of the theory is “cognitive surrender”—adopting AI outputs with minimal scrutiny, overriding intuition (System 1) and deliberation (System 2). Across three preregistered experiments using an adapted Cognitive Reflection Test (N = 1,372; 9,593 trials), we randomized AI accuracy via hidden seed prompts. Participants chose to consult an AI assistant on a majority of trials (>50%). Relative to baseline (no System 3 access), accuracy significantly rose when AI was accurate and fell when it erred (+25/-15 percentage points; Study 1), the behavioral signature of cognitive surrender (AI-Accurate vs. AI-Faulty contrast; Cohen’s h = 0.81). Engaging System 3 also increased confidence, even following errors. Time pressure (Study 2) and per-item incentives and feedback (Study 3) shifted baseline performance but did not eliminate this pattern: when accurate, AI buffered time-pressure costs and amplified incentive gains; when faulty, it consistently reduced accuracy regardless of situational moderators. Across studies, participants with higher trust in AI and lower need for cognition and fluid intelligence showed greater surrender to System 3. Tri-System Theory thus characterizes a triadic cognitive ecology, revealing how System 3 reframes human reasoning and may reshape autonomy and accountability in the age of AI.
TasteVal: Measuring the Experimental Research Taste of AI Systems Against Human Experts
We introduce TasteVal, a benchmark to evaluate the experimental research taste of frontier models. We define research taste as the ability to pick interesting problems to solve, design experiments, and interpret experimental results. TasteVal measures the experimental component of research taste; given a fixed research problem, we measure how well a model iteratively designs experiments and draws conclusions from their outcomes. We operationalize experimental research taste as compute efficiency; a Researcher who reaches the same score as an expert human using half the serial experimental compute has twice the experimental taste. Experimental taste thus acts as a multiplier on experimental compute, making it a key input to forecasts of AI progress. TasteVal consists of 8 novel, challenging, open-ended tasks representative of frontier AI R&D. To isolate taste from coding ability, the model under evaluation acts as a Researcher that iteratively designs experiments while a fixed Coder agent implements them and reports their results. The Researcher executes until either the 40 H100 hour or 120 wall-clock hour budgets are exhausted. We recruit 24 human experts, at least 2 per task, and take the best expert attempt per task as the expert baseline. We evaluate 20 models released between 2023 and 2026. The best-performing model, Opus 5.5, exceeds our expert baseline, with a compute multiplier of 2.3x (95% CI 1.15-4.37), at roughly 1/30 of our baseliners' average per-run cost. On TasteVal, the compute multiplier of frontier models has doubled approximately every 3.0 months since December 2025 (95% CI 1.7-5.0), up from every 14 months between 2023 and December 2025. Measured by final normalized performance, frontier models show no trend break, doubling every 14.6 months. To keep TasteVal uncontaminated, we do not release the tasks.
Learning to Trust: How Humans Mentally Recalibrate AI Confidence Signals
Productive human-AI collaboration requires appropriate reliance, yet contemporary AI systems are often miscalibrated, exhibiting systematic overconfidence or underconfidence. We investigate whether humans can learn to mentally recalibrate AI confidence signals through repeated experience. In a behavioral experiment (N = 200), participants predicted the AI's correctness across four AI calibration conditions: standard, overconfidence, underconfidence, and a counterintuitive "reverse confidence" mapping. Results demonstrate robust learning across all conditions, with participants significantly improving their accuracy, discrimination, and calibration alignment over 50 trials. We present a computational model utilizing a linear-in-log-odds (LLO) transformation and a Rescorla-Wagner learning rule to explain these dynamics. The model reveals that humans adapt by updating their baseline trust and confidence sensitivity, using asymmetric learning rates to prioritize the most informative errors. While humans can compensate for monotonic miscalibration, we identify a significant boundary in the reverse confidence scenario, where a substantial proportion of participants struggled to override initial inductive biases. These findings provide a mechanistic account of how humans adapt their trust in AI confidence signals through experience.
Augmented human intelligence goes beyond the AGI mirage
This paper argues that contemporary Artificial General Intelligence (AGI) approaches face significant challenges that make Augmented Human Intelligence (AHI) a more promising and practically beneficial alternative. Drawing on phenomenological insights from Peter-Paul Verbeek’s technological mediation theory and comprehensive empirical evidence from decades of AI development, we argue that current AGI projects encounter recurring difficulties that may stem from attempting to replace rather than enhance human intelligence. Through analysis of mediation theory’s core concepts, systematic examination of recent AI performance data, and comprehensive review of human–AI collaboration studies, we show why augmentation approaches consistently outperform replacement attempts across domains requiring creativity, judgment, and contextual understanding. Prioritizing sophisticated AHI development over AGI pursuit represents not a compromise but a fundamental reorientation toward more effective and ethically sound approaches to artificial intelligence that better serve human flourishing.
Solipsistic Superintelligence is Unlikely to be Cooperative
AI's central challenge is shifting from capability to coexistence. The dominant paradigm in AI research focuses on developing powerful agents that treat the world as an exogenous and stationary source of feedback. We contend that superintelligence, an extremely capable task solver, born out of such a solipsistic approach to AI design, is unlikely to be cooperative. Deploying AI systems induces endogenous non-stationarity, resulting in a train-test-deploy gap where historical distributions diverge from the deployment context. We refer to this as the self-undermining property of unilateral optimization. Closing this gap requires AI that participates in cooperation: the equilibrium-selection process through which multiple actors navigate their interdependence. We call for a non-solipsistic research paradigm that treats this interdependence as a core design principle rather than approaching cooperation as a task to solve. This entails building dynamic evaluation testbeds involving adaptive counterparties, treating institutions as design primitives, and preserving human agency as a structural feature of the systems we build.
AI systems out-persuade expert humans
Many societal decisions are settled by contests of persuasion. Conversational AI is a powerful new entrant in these contests, but whether it can out-persuade skilled and highly incentivized humans has remained unclear. Here, in a series of four preregistered experiments (n = 18,978 conversations from 6,923 people), we pitted AI systems against a range of human persuaders, including laypeople, winners of a separately preregistered four-round online persuasion tournament, professional canvassers, and world championship debaters. We found that AI systems were reliably more persuasive than expert humans, even when expert humans chose their issues, researched in advance, underwent hours of live, structured practice, and were incentivized with £1,000 cash bonuses. In a follow-up study, AI's advantage persisted after experts received a coaching tool that let them practice against the AI that beat them, review their performance history, and see what AI would have said at key moments. We found converging evidence that AI's advantage stemmed from rapidly deploying larger quantities of information: after coaching, expert humans could tie an AI constrained to respond at human speeds and with human-length messages. In a final study, we show that AI's advantage extends to consequential real-world behavior: AI was nearly 3x more effective than professional canvassers from a UK fundraising firm at raising real-money donations to Save the Children. Together, these results establish that frontier AI systems out-persuade expert humans in conversation, with significant implications for political communication.
Artificial Intuition — A Breakthrough Cognitive Paradigm
In a previous post, I introduced the Meta Meta-Model of Deep Learning. However, I did not introduce its details. A word of warning for the…

People judge others more harshly after talking to bots
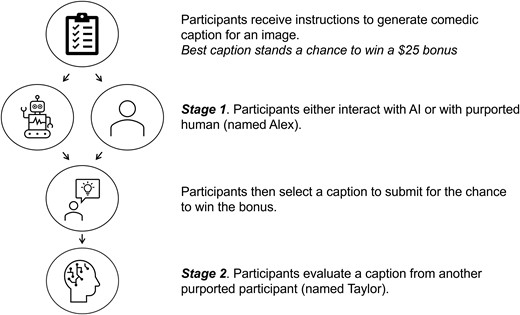
Abstract People now commonly interact with Artificial Intelligence (AI) agents. How do these interactions shape how humans perceive each other? In two preregistered studies (total N = 1,261), we show that people evaluate other humans more harshly after interacting with an AI (compared with an unrelated purported human). In Study 1, participants who worked on a creative task with AIs (versus purported humans) subsequently rated another purported human's work more negatively. Study 2 replicated this effect and demonstrated that the results hold even when participants believed their evaluation would not be shared with the purported human. Exploratory analyses of participants’ conversations show that prior to their human evaluations they were more demanding, more instrumental and displayed less positive affect towards AIs (versus purported humans). These findings point to a potentially worrisome side effect of the exponential rise in human–AI interactions.
Underspecified Human Decision Experiments Considered Harmful
Decision-making with information displays is a key focus of research in areas like human-AI collaboration and data visualization. However, what constitutes a decision problem, and what is required for an experiment to conclude that decisions are flawed, remain imprecise. We present a widely applicable definition of a decision problem synthesized from statistical decision theory and information economics. We claim that to attribute loss in human performance to bias, an experiment must provide the information that a rational agent would need to identify the normative decision. We evaluate whether recent empirical research on AI-assisted decisions achieves this standard. We find that only 10 (26%) of 39 studies that claim to identify biased behavior presented participants with sufficient information to make this claim in at least one treatment condition. We motivate the value of studying well-defined decision problems by describing a characterization of performance losses they allow to be conceived.

AI Models Exceed Individual Human Accuracy in Predicting Everyday Social Norms
A fundamental question in cognitive science concerns how social norms are acquired and represented. While humans typically learn norms through embodied social experience, we investigated whether large language models can achieve sophisticated norm understanding through statistical learning alone. Across two studies, we systematically evaluated multiple AI systems' ability to predict human social appropriateness judgments for 555 everyday scenarios by examining how closely they predicted the average judgment compared to each human participant. In Study 1, GPT-4.5's accuracy in predicting the collective judgment on a continuous scale exceeded that of every human participant (100th percentile). Study 2 replicated this, with Gemini 2.5 Pro outperforming 98.7% of humans, GPT-5 97.8%, and Claude Sonnet 4 96.0%. Despite this predictive power, all models showed systematic, correlated errors. These findings demonstrate that sophisticated models of social cognition can emerge from statistical learning over linguistic data alone, challenging strong versions of theories emphasizing the exclusive necessity of embodied experience for cultural competence. The systematic nature of AI limitations across different architectures indicates potential boundaries of pattern-based social understanding, while the models' ability to outperform nearly all individual humans in this predictive task suggests that language serves as a remarkably rich repository for cultural knowledge transmission.
AI makes you smarter but none the wiser: The disconnect between performance and metacognition
Optimizing human–AI interaction requires users to reflect on their performance critically, yet little is known about generative AI systems’ effect on users’ metacognitive judgments. In two large-scale studies, we investigate how AI usage is associated with users’ metacognitive monitoring and performance in logical reasoning tasks. Specifically, our paper examines whether people using AI to complete tasks can accurately monitor how well they perform. In Study 1, participants (N = 246) used AI to solve 20 logical reasoning problems from the Law School Admission Test. While their task performance improved by three points compared to a norm population, participants overestimated their task performance by four points. Interestingly, higher AI literacy correlated with lower metacognitive accuracy, suggesting that those with more technical knowledge of AI were more confident but less precise in judging their own performance. Using a computational model, we explored individual differences in metacognitive accuracy and found that the Dunning–Kruger effect, usually observed in this task, ceased to exist with AI use. Study 2 (N = 452) replicates these findings. We discuss how AI levels cognitive and metacognitive performance in human–AI interaction and consider the consequences of performance overestimation for designing interactive AI systems that foster accurate self-monitoring, avoid overreliance, and enhance cognitive performance.
New paper out in @pnas.org 🚨 Human learning is an understudied but promising lever for boosting human–AI synergy @jasonburton.bsky.social @ralfkurvers.bsky.social @stefanherzog.bsky.social @dirkwulff.bsky.social
