


Social media feed algorithms rank content that is purported to be preferred by users, but the engagement behaviors that drive these algorithms are (at best) indirect proxies for users’ explicitly self-stated values. Are the resulting feeds value aligned, and if not, why? We investigate this question by annotating the basic human values expressed in participants’ X (Twitter) feeds (N = 715 US users), analyzing the relationship between the posts’ value expressions and the posts’ amplification in the ranked “For You” Page feed, and then comparing the amplified values to users’ own values. We observe that the inventory of posts from followed accounts reflects users’ self-stated values—but that there is an overall negative correlation (misalignment) between users’ explicit values and the value expressions the algorithm is more likely to amplify. We turn to engagement behavior to understand this misalignment and observe that users’ engagement behaviors can be misaligned with their stated values—likely causing the algorithm to learn and reflect these misaligned values. We also detect partisan differences consistent with this theory: While the algorithm amplifies values negatively correlated with both Democrats’ and Republicans’ self-stated values, they are more misaligned for Democrats. And in fact replying, a heavily weighted form of engagement, is associated with values that are less aligned for both Democrats’ and Republicans’ self-stated values, and is even more misaligned for Democrats. Taken together, these findings offer a glimpse into the tensions between the values that people hold and those that provoke reactions, and how these value tensions can produce misaligned outcomes.
Value misalignment in X’s feed algorithm is a reflection of value tensions in engagement
Social media feed algorithms rank content that is purported to be preferred by users, but the engagement behaviors that drive these algorithms are (at best) indirect proxies for users’ explicitly self-stated values. Are the resulting feeds value aligned, and if not, why? We investigate this question by annotating the basic human values expressed in participants’ X (Twitter) feeds (N = 715 US users), analyzing the relationship between the posts’ value expressions and the posts’ amplification in the ranked “For You” Page feed, and then comparing the amplified values to users’ own values. We observe that the inventory of posts from followed accounts reflects users’ self-stated values—but that there is an overall negative correlation (misalignment) between users’ explicit values and the value expressions the algorithm is more likely to amplify. We turn to engagement behavior to understand this misalignment and observe that users’ engagement behaviors can be misaligned with their stated values—likely causing the algorithm to learn and reflect these misaligned values. We also detect partisan differences consistent with this theory: While the algorithm amplifies values negatively correlated with both Democrats’ and Republicans’ self-stated values, they are more misaligned for Democrats. And in fact replying, a heavily weighted form of engagement, is associated with values that are less aligned for both Democrats’ and Republicans’ self-stated values, and is even more misaligned for Democrats. Taken together, these findings offer a glimpse into the tensions between the values that people hold and those that provoke reactions, and how these value tensions can produce misaligned outcomes.
The political effects of X’s feed algorithm
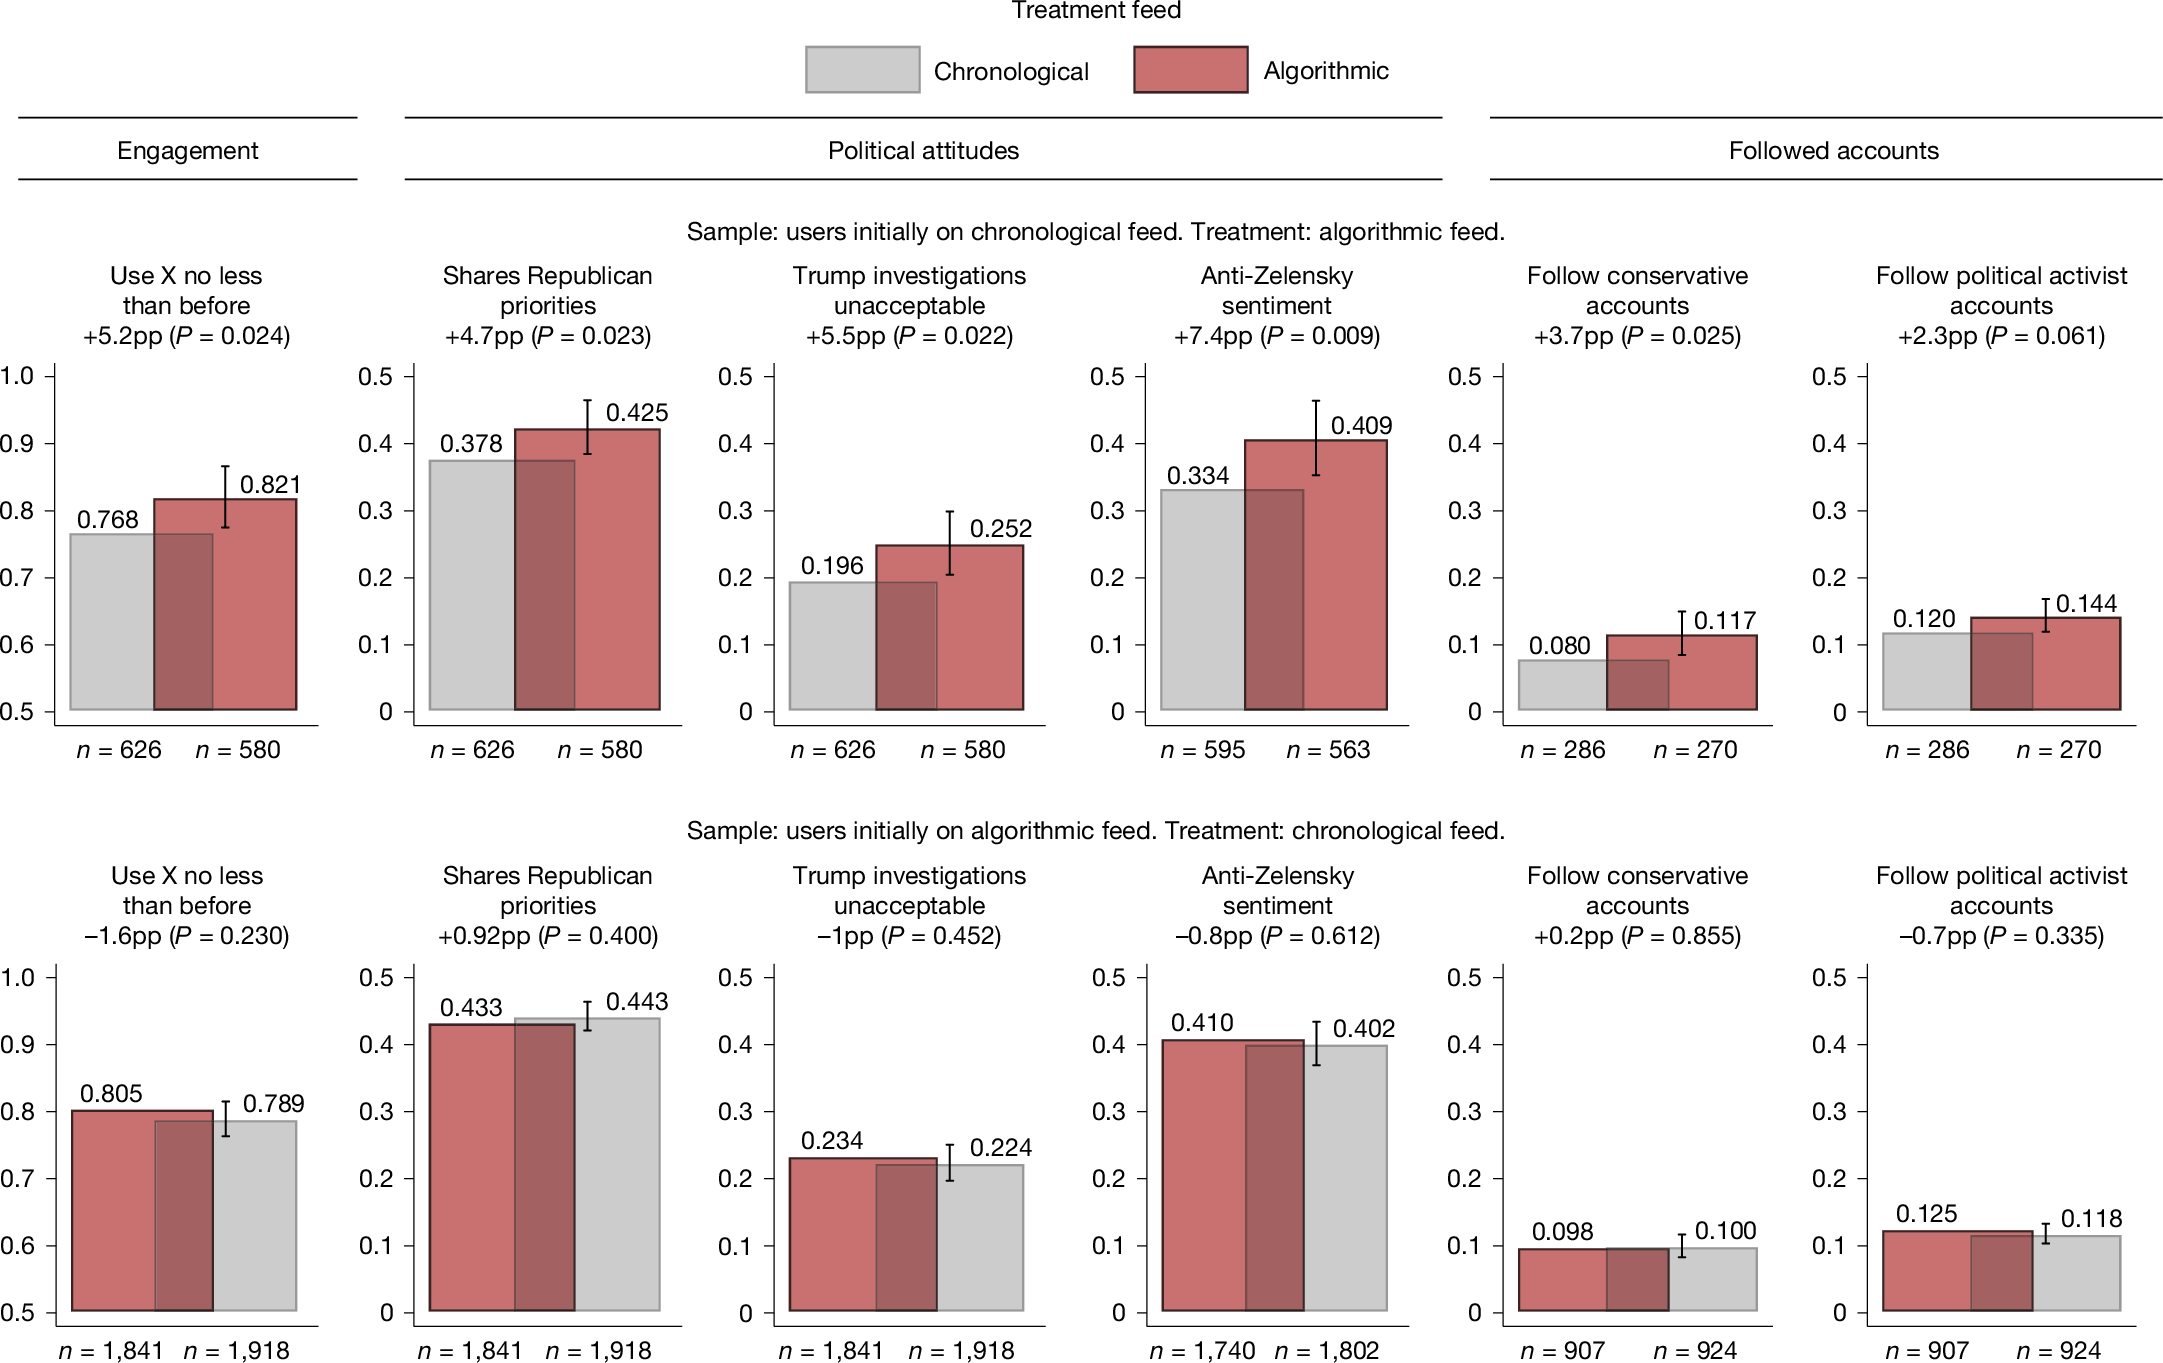
Feed algorithms are widely suspected to influence political attitudes. However, previous evidence from switching off the algorithm on Meta platforms found no political effects1. Here we present results from a 2023 field experiment on Elon Musk’s platform X shedding light on this puzzle. We assigned active US-based users randomly to either an algorithmic or a chronological feed for 7 weeks, measuring political attitudes and online behaviour. Switching from a chronological to an algorithmic feed increased engagement and shifted political opinion towards more conservative positions, particularly regarding policy priorities, perceptions of criminal investigations into Donald Trump and views on the war in Ukraine. In contrast, switching from the algorithmic to the chronological feed had no comparable effects. Neither switching the algorithm on nor switching it off significantly affected affective polarization or self-reported partisanship. To investigate the mechanism, we analysed users’ feed content and behaviour. We found that the algorithm promotes conservative content and demotes posts by traditional media. Exposure to algorithmic content leads users to follow conservative political activist accounts, which they continue to follow even after switching off the algorithm, helping explain the asymmetry in effects. These results suggest that initial exposure to X’s algorithm has persistent effects on users’ current political attitudes and account-following behaviour, even in the absence of a detectable effect on partisanship.
The political effects of X’s feed algorithm
Feed algorithms are widely suspected to influence political attitudes. However, previous evidence from switching off the algorithm on Meta platforms found no political effects1. Here we present results from a 2023 field experiment on Elon Musk’s platform X shedding light on this puzzle. We assigned active US-based users randomly to either an algorithmic or a chronological feed for 7 weeks, measuring political attitudes and online behaviour. Switching from a chronological to an algorithmic feed increased engagement and shifted political opinion towards more conservative positions, particularly regarding policy priorities, perceptions of criminal investigations into Donald Trump and views on the war in Ukraine. In contrast, switching from the algorithmic to the chronological feed had no comparable effects. Neither switching the algorithm on nor switching it off significantly affected affective polarization or self-reported partisanship. To investigate the mechanism, we analysed users’ feed content and behaviour. We found that the algorithm promotes conservative content and demotes posts by traditional media. Exposure to algorithmic content leads users to follow conservative political activist accounts, which they continue to follow even after switching off the algorithm, helping explain the asymmetry in effects. These results suggest that initial exposure to X’s algorithm has persistent effects on users’ current political attitudes and account-following behaviour, even in the absence of a detectable effect on partisanship.
Redesigning algorithms to intervene on social norm misperceptions during a national election
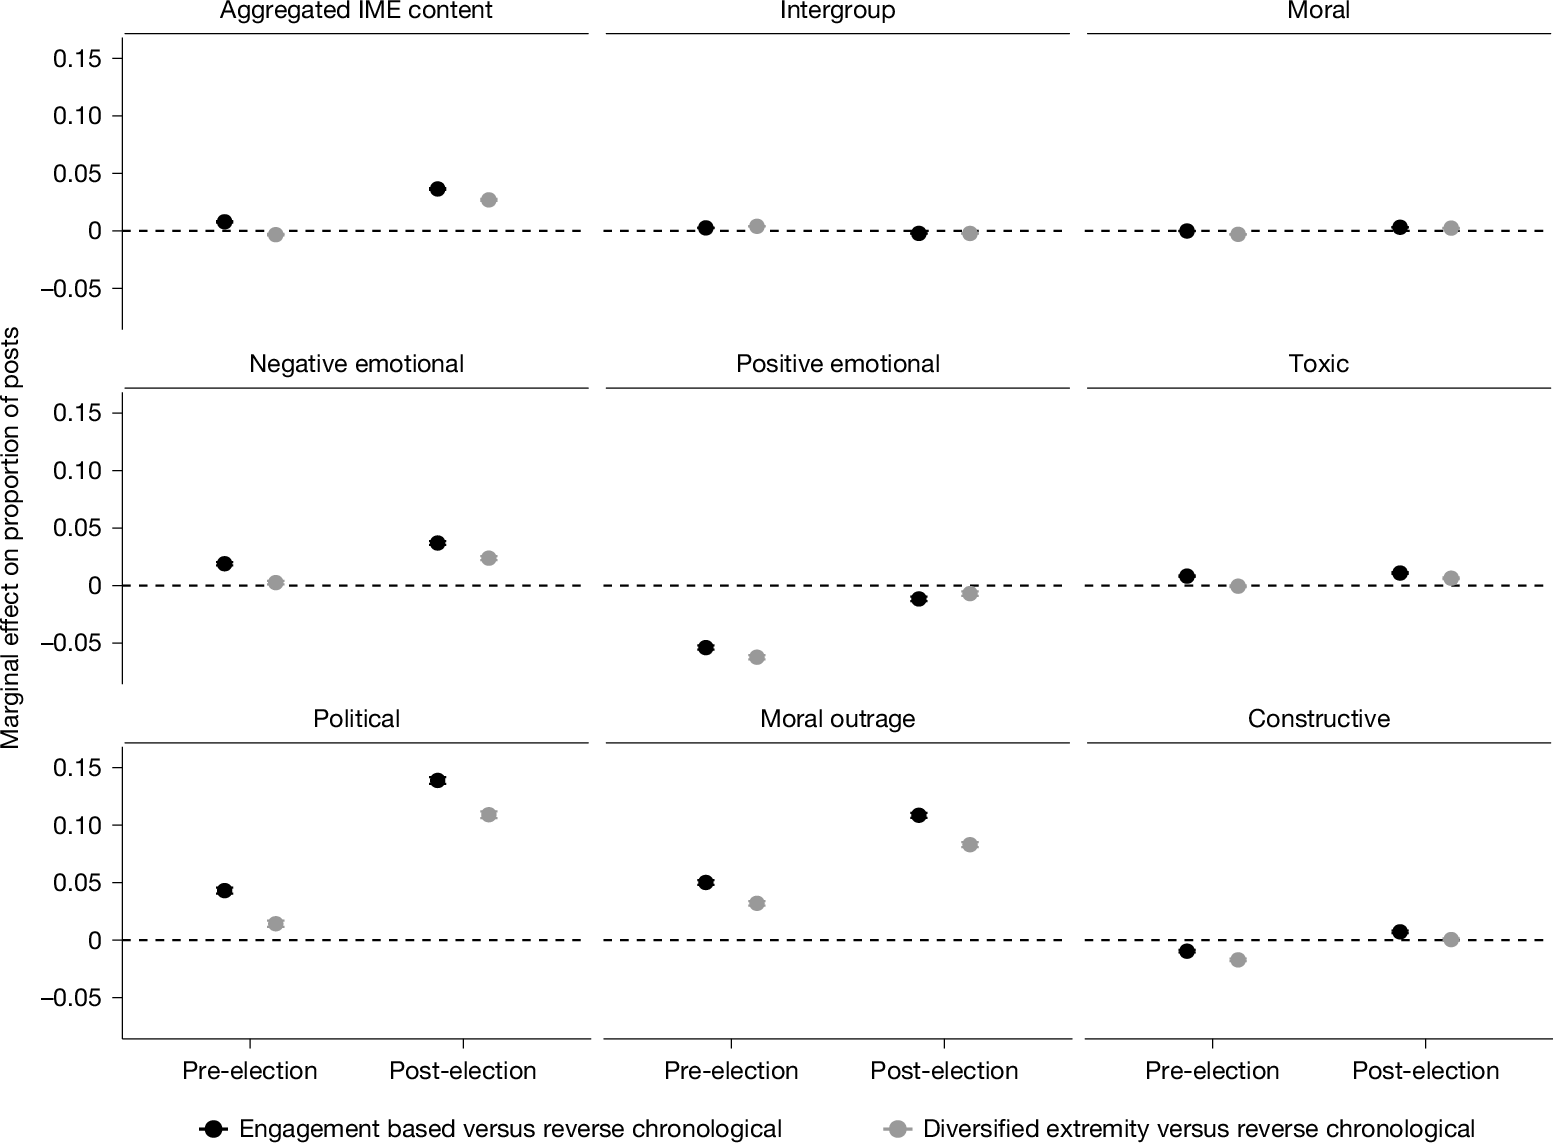
For the first time in history, civic discourse commonly occurs in digital environments in which algorithms influence exposure to social information1,2. It is increasingly important to understand whether and how these algorithms affect political discourse3–5. Here we built custom feed-ranking algorithms with full control over their features, and randomly assigned 2,000 participants to use them for 8 weeks (before and after the 2024 US presidential election). We tested whether an engagement-based algorithm (used on major social media platforms6,7) amplifies intergroup, moralized and emotional (IME) information in ways that skew perceptions of social norms around political dialogue5,8, and whether it increased engagement with IME content and perceptions of partisan animosity (compared with a reverse-chronological feed9,10). We also developed and tested a ‘diversified extremity’ algorithm to reduce the influence of extreme users11–13 to improve the accuracy of social norm perception14–16 and reduce perceptions of partisan animosity. We found that engagement-based feeds amplified IME and toxic content relative to reverse-chronological feeds, with the largest increases in moral outrage and political content. Engagement-based feeds also reduced prescriptive norm perception accuracy (albeit in an unexpected direction) and increased perceived partisan animosity. However, they did not significantly alter users’ own engagement behaviours. The diversified extremity algorithm reduced IME and toxic content exposure, improved prescriptive norm accuracy, yet maintained comparable platform enjoyment—suggesting that reducing the influence of extreme users can curb algorithmic distortions without diminishing user experience.
How do social media feed algorithms affect attitudes and behavior in an election campaign?
We investigated the effects of Facebook’s and Instagram’s feed algorithms during the 2020 US election. We assigned a sample of consenting users to reverse-chronologically-ordered feeds instead of the default algorithms. Moving users out of algorithmic feeds substantially decreased the time they spent on the platforms and their activity. The chronological feed also affected exposure to content: The amount of political and untrustworthy content they saw increased on both platforms, the amount of content classified as uncivil or containing slur words they saw decreased on Facebook, and the amount of content from moderate friends and sources with ideologically mixed audiences they saw increased on Facebook. Despite these substantial changes in users’ on-platform experience, the chronological feed did not significantly alter levels of issue polarization, affective polarization, political knowledge, or other key attitudes during the 3-month study period.

Auditing Political Exposure Bias: Algorithmic Amplification on Twitter/X During the 2024 U.S. Presidential Election
Approximately 50% of tweets in X's user timelines are personalized recommendations from accounts they do not follow. This raises a critical question: What political content are users exposed to beyond their established networks, and what implications does this have for democratic discourse online? In this paper, we present a six-week audit of X's algorithmic content recommendations during the 2024 U.S. Presidential Election by deploying 120 sock-puppet monitoring accounts to capture tweets from their personalized "For You" timelines. Our objective is to quantify out-of-network content exposure for right- and left-leaning user profiles and assess any potential inequalities and biases in political exposure. Our findings indicate that X's algorithm skews exposure toward a few high-popularity accounts across all users, with right-leaning users experiencing the highest level of exposure inequality. Both left- and right-leaning users encounter amplified exposure to accounts aligned with their own political views and reduced exposure to opposing viewpoints. Additionally, we observe that new accounts experience a right-leaning bias in exposure within their default timelines. Our work contributes to understanding how content recommendation systems may induce and reinforce biases while exacerbating vulnerabilities among politically polarized user groups. We underscore the importance of transparency-aware algorithms in addressing critical issues such as safeguarding election integrity and fostering a more informed digital public sphere.

Bonsai: Intentional and Personalized Social Media Feeds
Social media feeds use predictive models to maximize engagement, often misaligning how people consume content with how they wish to. We introduce Bonsai, a system that enables people to build personalized and intentional feeds. Bonsai implements a platform-agnostic framework comprising Planning, Sourcing, Curating, and Ranking modules. This framework allows users to express their intent in natural language and exert fine-grained control over a procedurally transparent feed creation process. We evaluated the system with 15 Bluesky users in a two-phase, multi-week study. We find that participants successfully used our system to discover new content, filter out irrelevant or toxic posts, and disentangle engagement from intent, but curating intentional feeds required more effort than they are used to. Simultaneously, users sought system transparency mechanisms to effectively use (and trust) intentional, personalized feeds. Overall, our work highlights intentional feedbuilding as a viable path beyond engagement-based optimization.
Reranking partisan animosity in algorithmic social media feeds alters affective polarization
Today, social media platforms hold the sole power to study the effects of feed-ranking algorithms. We developed a platform-independent method that reranks participants’ feeds in real time and used this method to conduct a preregistered 10-day field ...

Consequences of Information Feed Integration on User Engagement and Contribution: A Natural Experiment in an Online Knowledge-Sharing Community
Many online communities that rely on effortful, voluntary content contributions offer additional content curation tools to facilitate social interactions and encourage user contributions. Any platform that offers two or more heterogeneous content types (e.g., expert knowledge and social posts) faces a choice about the presentation format: whether to display the content types separately or in an integrated information feed. We leverage a natural experiment on Zhihu, a Q&A platform that offers a social-interaction-oriented functionality called Ideas. Zhihu initially presented answers (expert knowledge content) and ideas (social posts) in two different information feeds, but the platform integrated ideas into the same information feed as answers in June 2019. We find that information feed integration significantly decreased user engagement with and contribution of both ideas and answers. We hypothesize that users decreased their engagement because the juxtaposition of incongruous types of content increased mindset switching and cognitive strain. This hypothesis is supported by an additional laboratory experiment. We also present evidence showing that contributions decreased both because of the decrease in engagement (weaker social recognition incentives) and because integration heightened concerns that posting ideas would dilute the contributor’s professional image. Our findings have important theoretical and practical implications for any platform that hosts heterogeneous content. History: Xiaoquan (Michael) Zhang served as the senior editor and Yili (Kevin) Hong served as associate editor for this article. Funding: Z. Cao acknowledges this research was funded by National Natural Science Foundation of China [Grants 72201238, 72192823]. G. Li acknowledges this research was funded by National Natural Science Foundation of China [Grant 72102047] and Shanghai Pujiang Program [Grant 21PJC006]. Supplemental Material: The e-companion is available at https://doi.org/10.1287/isre.2022.0043.
The echo chamber effect on social media
Significance We explore the key differences between the main social media platforms and how they are likely to influence information spreading and the formation of echo chambers. To assess the different dynamics, we perform a comparative analysis on more than 100 million pieces of content concerning controversial topics (e.g., gun control, vaccination, abortion) from Gab, Facebook, Reddit, and Twitter. The analysis focuses on two main dimensions: 1) homophily in the interaction networks and 2) bias in the information diffusion toward like-minded peers. Our results show that the aggregation in homophilic clusters of users dominates online dynamics. However, a direct comparison of news consumption on Facebook and Reddit shows higher segregation on Facebook. , Social media may limit the exposure to diverse perspectives and favor the formation of groups of like-minded users framing and reinforcing a shared narrative, that is, echo chambers. However, the interaction paradigms among users and feed algorithms greatly vary across social media platforms. This paper explores the key differences between the main social media platforms and how they are likely to influence information spreading and echo chambers’ formation. We perform a comparative analysis of more than 100 million pieces of content concerning several controversial topics (e.g., gun control, vaccination, abortion) from Gab, Facebook, Reddit, and Twitter. We quantify echo chambers over social media by two main ingredients: 1) homophily in the interaction networks and 2) bias in the information diffusion toward like-minded peers. Our results show that the aggregation of users in homophilic clusters dominate online interactions on Facebook and Twitter. We conclude the paper by directly comparing news consumption on Facebook and Reddit, finding higher segregation on Facebook.

Social Media Algorithms Distort Social Instincts and Fuel Misinformation - Neuroscience News
Social media algorithms, designed to boost user engagement for advertising revenue, amplify the biases inherent in human social learning processes, leading to misinformation and polarization.
Evaluating Twitter’s algorithmic amplification of low-credibility content: an observational study
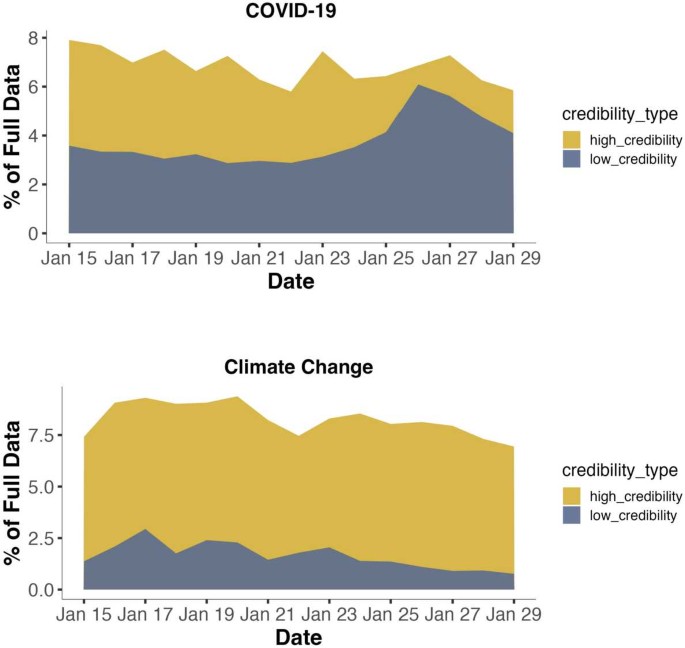
Artificial intelligence (AI)-powered recommender systems play a crucial role in determining the content that users are exposed to on social media platforms. However, the behavioural patterns of these systems are often opaque, complicating the evaluation of their impact on the dissemination and consumption of disinformation and misinformation. To begin addressing this evidence gap, this study presents a measurement approach that uses observed digital traces to infer the status of algorithmic amplification of low-credibility content on Twitter over a 14-day period in January 2023. Using an original dataset of ≈ 2.7 million posts on COVID-19 and climate change published on the platform, this study identifies tweets sharing information from low-credibility domains, and uses a bootstrapping model with two stratifications, a tweet’s engagement level and a user’s followers level, to compare any differences in impressions generated between low-credibility and high-credibility samples. Additional stratification variables of toxicity, political bias, and verified status are also examined. This analysis provides valuable observational evidence on whether the Twitter algorithm favours the visibility of low-credibility content, with results indicating that, on aggregate, tweets containing low-credibility URL domains perform better than tweets that do not across both datasets. However, this effect is largely attributable to a difference in high-engagement, high-followers tweets, which are very impactful in terms of impressions generation, and are more likely receive amplified visibility when containing low-credibility content. Furthermore, high toxicity tweets and those with right-leaning bias see heightened amplification, as do low-credibility tweets from verified accounts. Ultimately, this suggests that Twitter’s recommender system may have facilitated the diffusion of false content by amplifying the visibility of low-credibility content with high-engagement generated by very influential users.
Evaluating Twitter’s algorithmic amplification of low-credibility content: an observational study
Artificial intelligence (AI)-powered recommender systems play a crucial role in determining the content that users are exposed to on social media platforms. However, the behavioural patterns of these systems are often opaque, complicating the evaluation of their impact on the dissemination and consumption of disinformation and misinformation. To begin addressing this evidence gap, this study presents a measurement approach that uses observed digital traces to infer the status of algorithmic amplification of low-credibility content on Twitter over a 14-day period in January 2023. Using an original dataset of ≈ 2.7 million posts on COVID-19 and climate change published on the platform, this study identifies tweets sharing information from low-credibility domains, and uses a bootstrapping model with two stratifications, a tweet’s engagement level and a user’s followers level, to compare any differences in impressions generated between low-credibility and high-credibility samples. Additional stratification variables of toxicity, political bias, and verified status are also examined. This analysis provides valuable observational evidence on whether the Twitter algorithm favours the visibility of low-credibility content, with results indicating that, on aggregate, tweets containing low-credibility URL domains perform better than tweets that do not across both datasets. However, this effect is largely attributable to a difference in high-engagement, high-followers tweets, which are very impactful in terms of impressions generation, and are more likely receive amplified visibility when containing low-credibility content. Furthermore, high toxicity tweets and those with right-leaning bias see heightened amplification, as do low-credibility tweets from verified accounts. Ultimately, this suggests that Twitter’s recommender system may have facilitated the diffusion of false content by amplifying the visibility of low-credibility content with high-engagement generated by very influential users.
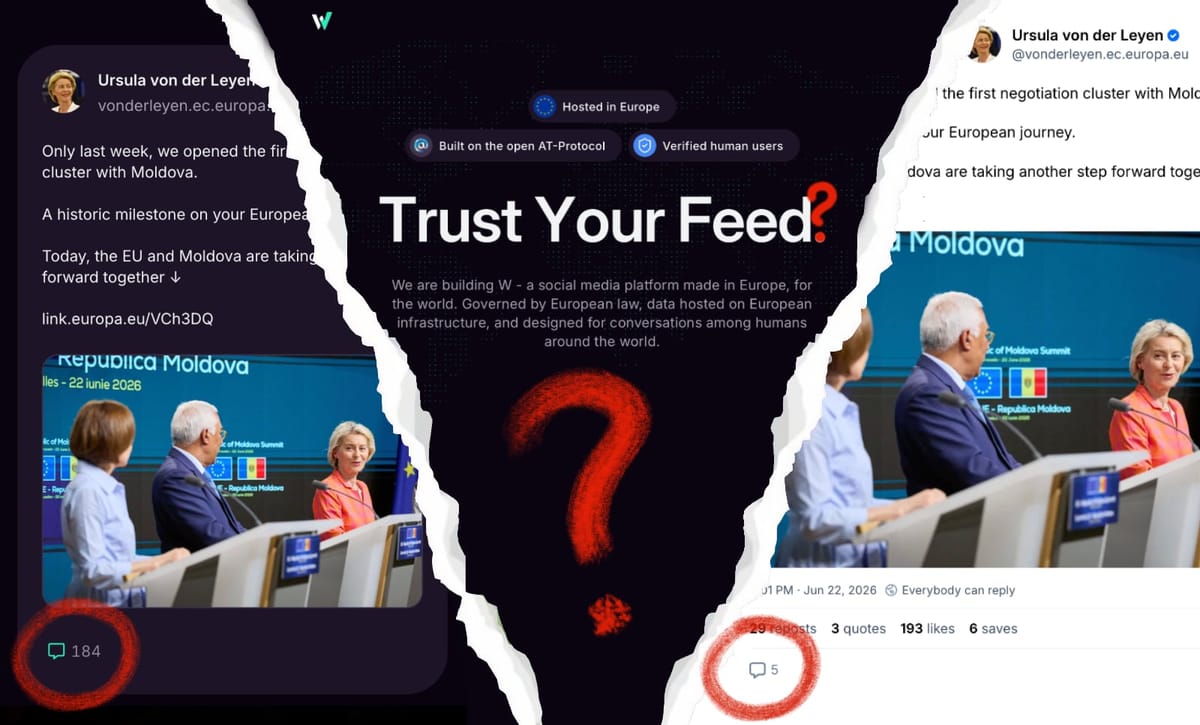
W Social, Fictional Metrics and the Beauty of Open Data
W Social's tagline is "Trust Your Feed" but the company's landing page displays inflated engagement metrics - a misrepresentation that contradicts its own promise.
Do our social media algorithms correctly reflect our values? Our new article published today in @pnas.org shows that the answer is often not, and that the content that gets promoted into their ranked feeds is often actively counter to our values.
Do our social media algorithms correctly reflect our values? Our new article published today in @pnas.org shows that the answer is often not, and that the content that gets promoted into their ranked feeds is often actively counter to our values.
