

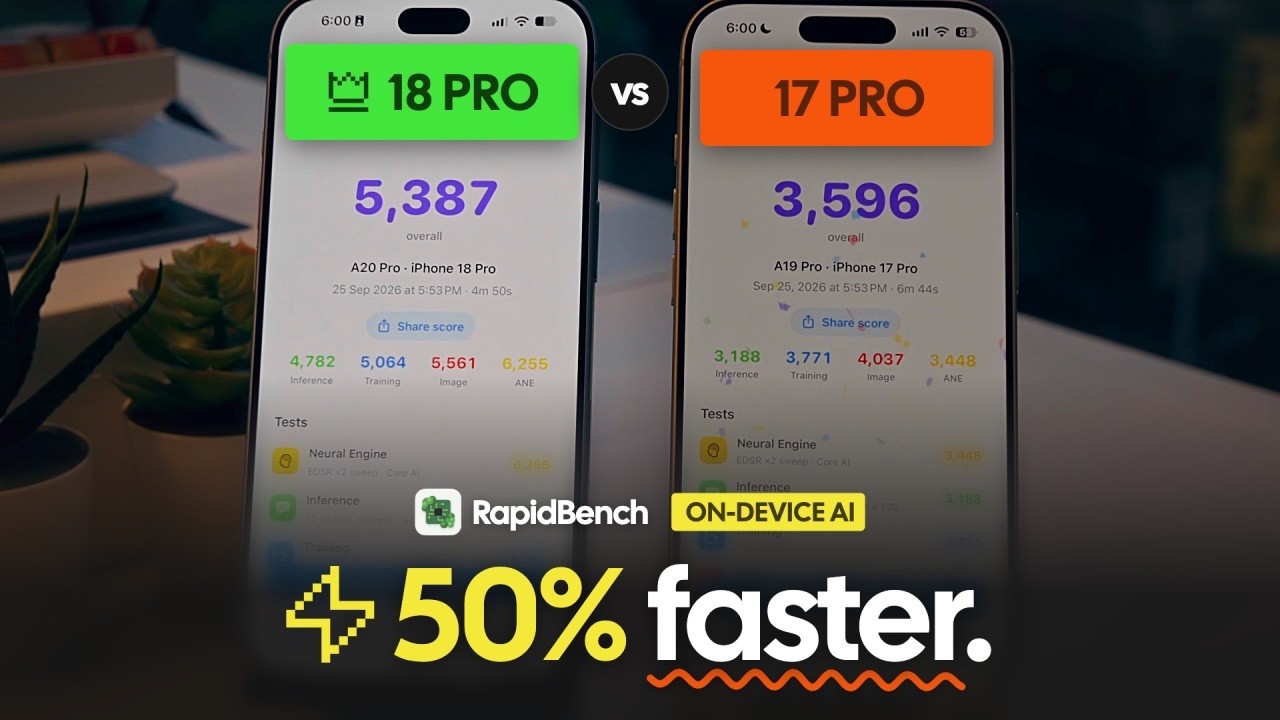
Same models, same prompts, measured the same way. Four on-device AI tests, one score. Join the TestFlight beta.
Artificial Analysis on Twitter / X
We benchmarked Apple's new On-Device model: trails most Gemma and Qwen on-device suitable models but still very usefulGPQA Diamond performance trailed models that are suitable for on-device use such as the smaller Gemma models (3n E4B, 4B, 12B) and Qwen3 models (1.7B, 4B, 8B).… pic.twitter.com/wMrNM7yinL— Artificial Analysis (@ArtificialAnlys) June 20, 2025

Scott Jenson – Exploring the world beyond mobile
Fast AI requires slow thinking The current Silicon Valley flex is trading notes on your favorite new AI tools over lunch. Each week brings another one to explore. Some of these tools are very impressive; I’ve been able to reply to someone with an alternative UI design in less than a minute, and they were […]
How we built an automated unit test generation pipeline for iOS
We generated 85K lines of iOS tests with minimal manual effort.
Melange | On-device AI for Mobile
Select. Benchmark. Deploy | End-to-end on-device AI deployment tool for mobile devs.
Announcing VibeBench: The AI benchmark that measures what matters — how models like Opus-4.7 actually feel to use in real-world work.
My coworkers and I have been long-time users of Claude Code and Codex and are getting a ton of exposure to other models due to our deep dives into…
BrowserBench.org — Browser Benchmarks
Speedometer is a browser benchmark that measures the responsiveness of web applications. It's maintained by major browser engine developers under an open governance model.
ZETIC | On-Device AI for Everything - for any model, on any device, in any framework
Built by ex-Qualcomm AI Engineer. Automate on-device AI deployment with full NPU optimization. Benchmark on 100+ physical devices and ship in hours with just 3 lines of code.
Locally AI - Run AI models locally on your iPhone, iPad, and Mac.
Run Llama, Gemma, Qwen, DeepSeek, and more on your iPhone, iPad, and Mac. Optimized for Apple Silicon. Offline. Private.
Every Apple M Chip Explained – M1, M2, M3, M4, M5
Introducing Pipette: A benchmarking suite for on-device intelligence — Blog
Meet Pipette, an open-source platform for reproducible on-device AI benchmarks across models, quantization, runtimes and hardware.
Liquid AI Launches LEAP and Liquid Apollo: The Easiest Way to Build with On-Device AI | Liquid AI
Today marks a pivotal milestone in the evolution of edge AI. Liquid AI is thrilled to announce LEAP v0, our first developer-ready platform for on-device AI deployment—and Liquid Apollo, a lightweight iOS-native application built to showcase and stress-test small foundation models directly on your phone.

Part 3: iPhone Hardware and How It Powers On-Device AI
By Mirai Labs, frontier on-device AI lab. Building the models, inference runtime, and quantization stack from the device constraint up.
AI Coding Agent Benchmarks & Leaderboard | Artificial Analysis
We measure real-world performance of coding agents on software engineering tasks, including cost, token usage, and execution time. We compare how performance changes across agents, models, and execution settings.
BetterBench: Assessing AI Benchmarks, Uncovering Issues, and Establishing Best Practices
AI models are increasingly prevalent in high-stakes environments, necessitating thorough assessment of their capabilities and risks. Benchmarks are popular for measuring these attributes and for comparing model performance, tracking progress, and identifying weaknesses in foundation and non-foundation models. They can inform model selection for downstream tasks and influence policy initiatives. However, not all benchmarks are the same: their quality depends on their design and usability. In this paper, we develop an assessment framework considering 46 best practices across an AI benchmark's lifecycle and evaluate 24 AI benchmarks against it. We find that there exist large quality differences and that commonly used benchmarks suffer from significant issues. We further find that most benchmarks do not report statistical significance of their results nor allow for their results to be easily replicated. To support benchmark developers in aligning with best practices, we provide a checklist for minimum quality assurance based on our assessment. We also develop a living repository of benchmark assessments to support benchmark comparability, accessible at betterbench.stanford.edu.

The Ma of a New Machine – Scott Jenson
The current Silicon Valley flex is trading notes on your favorite new AI tools over lunch. Each week brings another one to explore. Some of these tools are very impressive; I’ve been able to reply to someone with an alternative UI design in less than a minute, and they were dumbfounded: “How did you do that so fast?”

apple-silicon-llm-bench/results/complete_results.html at main · AlexHiesch/apple-silicon-llm-bench
Systematic LLM inference benchmark for Apple Silicon: 8 backends, 7 models, 791 measurements - AlexHiesch/apple-silicon-llm-bench