


As governments and industry turn to increased use of automated decision systems, it becomes essential to consider how closely such systems can reproduce human judgment. We identify a core potential failure, finding that annotators label objects differently depending on whether they are being asked a factual question or a normative question. This challenges a natural assumption maintained in many standard machine-learning (ML) data acquisition procedures: that there is no difference between predicting the factual classification of an object and an exercise of judgment about whether an object violates a rule premised on those facts. We find that using factual labels to train models intended for normative judgments introduces a notable measurement error. We show that models trained using factual labels yield significantly different judgments than those trained using normative labels and that the impact of this effect on model performance can exceed that of other factors (e.g., dataset size) that routinely attract attention from ML researchers and practitioners. , Machine learning systems trained with factual features as labels do not reproduce human rule violation judgments on the same data.
Assessing Moral Judgment by Large Language Models – A Survey of Available Datasets
Recent advances in language modeling have contributed to a growing emphasis on machine ethics, including researching and assessing moral judgments made by large language models (LLMs). This paper provides a critical survey of the existing datasets for exactly this assessment, with a special focus on the respective data sources. We address the current lack of theoretical grounding by providing an introduction to ethics and different frameworks from moral philosophy and moral psychology. Moreover, we identify four main data sources: webcrawled corpora, scholars, laypeople, and synthetic data generation. By discussing the strengths and weaknesses of these sources, we analyze their implications for the assessment of moral judgment. Importantly, systemizing the available datasets reveals an over-reliance on previous work, reinforcing existing shortcomings. Addressing the current limitations, we recommend adopting a consistent terminology and creating independently curated datasets based on interdisciplinary work. To ensure a clear delineation of normative approaches, we propose focusing on the assessment of moral consistency and certainty of LLMs as effective and well-defined indicators of their performance on moral judgment.
Taming Hyperparameter Sensitivity in Data Attribution: Practical Selection Without Costly Retraining
Data attribution methods, which quantify the influence of individual training data points on a machine learning model, have gained increasing popularity in data-centric applications in modern AI. Despite a recent surge of new methods developed in this space, the impact of hyperparameter tuning in these methods remains under-explored. In this work, we present the first large-scale empirical study to understand the hyperparameter sensitivity of common data attribution methods. Our results show that most methods are indeed sensitive to certain key hyperparameters. However, unlike typical machine learning algorithms---whose hyperparameters can be tuned using computationally-cheap validation metrics---evaluating data attribution performance often requires retraining models on subsets of training data, making such metrics prohibitively costly for hyperparameter tuning. This poses a critical open challenge for the practical application of data attribution methods. To address this challenge, we advocate for better theoretical understandings of hyperparameter behavior to inform efficient tuning strategies. As a case study, we provide a theoretical analysis of the regularization term that is critical in many variants of influence function methods. Building on this analysis, we propose a lightweight procedure for selecting the regularization value without model retraining, and validate its effectiveness across a range of standard data attribution benchmarks. Overall, our study identifies a fundamental yet overlooked challenge in the practical application of data attribution, and highlights the importance of careful discussion on hyperparameter selection in future method development.
Data Shapley: Equitable Valuation of Data for Machine Learning
As data becomes the fuel driving technological and economic growth, a fundamental challenge is how to quantify the value of data in algorithmic predictions and decisions. For example, in healthcare and consumer markets, it has been suggested that individuals should be compensated for the data that they generate, but it is not clear what is an equitable valuation for individual data. In this work, we develop a principled framework to address data valuation in the context of supervised machine learning. Given a learning algorithm trained on $n$ data points to produce a predictor, we propose data Shapley as a metric to quantify the value of each training datum to the predictor performance. Data Shapley uniquely satisfies several natural properties of equitable data valuation. We develop Monte Carlo and gradient-based methods to efficiently estimate data Shapley values in practical settings where complex learning algorithms, including neural networks, are trained on large datasets. In addition to being equitable, extensive experiments across biomedical, image and synthetic data demonstrate that data Shapley has several other benefits: 1) it is more powerful than the popular leave-one-out or leverage score in providing insight on what data is more valuable for a given learning task; 2) low Shapley value data effectively capture outliers and corruptions; 3) high Shapley value data inform what type of new data to acquire to improve the predictor.
Beta Shapley: a Unified and Noise-reduced Data Valuation Framework for Machine Learning
Data Shapley has recently been proposed as a principled framework to quantify the contribution of individual datum in machine learning. It can effectively identify helpful or harmful data points for a learning algorithm. In this paper, we propose Beta Shapley, which is a substantial generalization of Data Shapley. Beta Shapley arises naturally by relaxing the efficiency axiom of the Shapley value, which is not critical for machine learning settings. Beta Shapley unifies several popular data valuation methods and includes data Shapley as a special case. Moreover, we prove that Beta Shapley has several desirable statistical properties and propose efficient algorithms to estimate it. We demonstrate that Beta Shapley outperforms state-of-the-art data valuation methods on several downstream ML tasks such as: 1) detecting mislabeled training data; 2) learning with subsamples; and 3) identifying points whose addition or removal have the largest positive or negative impact on the model.
OpenDataVal: a Unified Benchmark for Data Valuation
Assessing the quality and impact of individual data points is critical for improving model performance and mitigating undesirable biases within the training dataset. Several data valuation algorithms have been proposed to quantify data quality, however, there lacks a systemic and standardized benchmarking system for data valuation. In this paper, we introduce OpenDataVal, an easy-to-use and unified benchmark framework that empowers researchers and practitioners to apply and compare various data valuation algorithms. OpenDataVal provides an integrated environment that includes (i) a diverse collection of image, natural language, and tabular datasets, (ii) implementations of eleven different state-of-the-art data valuation algorithms, and (iii) a prediction model API that can import any models in scikit-learn. Furthermore, we propose four downstream machine learning tasks for evaluating the quality of data values. We perform benchmarking analysis using OpenDataVal, quantifying and comparing the efficacy of state-of-the-art data valuation approaches. We find that no single algorithm performs uniformly best across all tasks, and an appropriate algorithm should be employed for a user's downstream task. OpenDataVal is publicly available at https://opendataval.github.io with comprehensive documentation. Furthermore, we provide a leaderboard where researchers can evaluate the effectiveness of their own data valuation algorithms.
From Predictive Algorithms to Automatic Generation of Anomalies
Machine learning algorithms can find predictive signals that researchers fail to notice; yet they are notoriously hard-to-interpret. How can we extract theoretical insights from these black boxes? History provides a clue. Facing a similar problem – how to extract theoretical insights from their intuitions – researchers often turned to “anomalies:” constructed examples that highlight flaws in an existing theory and spur the development of new ones. Canonical examples include the Allais paradox and the Kahneman-Tversky choice experiments for expected utility theory. We suggest anomalies can extract theoretical insights from black box predictive algorithms. We develop procedures to automatically generate anomalies for an existing theory when given a predictive algorithm. We cast anomaly generation as an adversarial game between a theory and a falsifier, the solutions to which are anomalies: instances where the black box algorithm predicts - were we to collect data - we would likely observe violations of the theory. As an illustration, we generate anomalies for expected utility theory using a large, publicly available dataset on real lottery choices. Based on an estimated neural network that predicts lottery choices, our procedures recover known anomalies and discover new ones for expected utility theory. In incentivized experiments, subjects violate expected utility theory on these algorithmically generated anomalies; moreover, the violation rates are similar to observed rates for the Allais paradox and Common ratio effect.

Data Minimization for GDPR Compliance in Machine Learning Models
The EU General Data Protection Regulation (GDPR) mandates the principle of data minimization, which requires that only data necessary to fulfill a certain purpose be collected. However, it can often be difficult to determine the minimal amount of data required, especially in complex machine learning models such as neural networks. We present a first-of-a-kind method to reduce the amount of personal data needed to perform predictions with a machine learning model, by removing or generalizing some of the input features. Our method makes use of the knowledge encoded within the model to produce a generalization that has little to no impact on its accuracy. This enables the creators and users of machine learning models to acheive data minimization, in a provable manner.

Membership Inference Attacks Against Machine Learning Models
We quantitatively investigate how machine learning models leak information about the individual data records on which they were trained. We focus on the basic membership inference attack: given a data record and black-box access to a model, determine if the record was in the model's training dataset. To perform membership inference against a target model, we make adversarial use of machine learning and train our own inference model to recognize differences in the target model's predictions on the inputs that it trained on versus the inputs that it did not train on. We empirically evaluate our inference techniques on classification models trained by commercial "machine learning as a service" providers such as Google and Amazon. Using realistic datasets and classification tasks, including a hospital discharge dataset whose membership is sensitive from the privacy perspective, we show that these models can be vulnerable to membership inference attacks. We then investigate the factors that influence this leakage and evaluate mitigation strategies.
Characterizing Fairness Over the Set of Good Models Under Selective Labels
Algorithmic risk assessments are used to inform decisions in a wide variety of high-stakes settings. Often multiple predictive models deliver similar overall performance but differ markedly in their predictions for individual cases, an empirical phenomenon known as the “Rashomon Effect.” These models may have different properties over various groups, and therefore have different predictive fairness properties. We develop a framework for characterizing predictive fairness properties over the set of models that deliver similar overall performance, or “the set of good models.” Our framework addresses the empirically relevant challenge of selectively labelled data in the setting where the selection decision and outcome are unconfounded given the observed data features. Our framework can be used to 1) audit for predictive bias; or 2) replace an existing model with one that has better fairness properties. We illustrate these use cases on a recidivism prediction task and a real-world credit-scoring task.
Values in the Wild: Discovering and Analyzing Values in Real-World Language Model Interactions
AI assistants can impart value judgments that shape people's decisions and worldviews, yet little is known empirically about what values these systems rely on in practice. To address this, we develop a bottom-up, privacy-preserving method to extract the values (normative considerations stated or demonstrated in model responses) that Claude 3 and 3.5 models exhibit in hundreds of thousands of real-world interactions. We empirically discover and taxonomize 3,307 AI values and study how they vary by context. We find that Claude expresses many practical and epistemic values, and typically supports prosocial human values while resisting values like "moral nihilism". While some values appear consistently across contexts (e.g. "transparency"), many are more specialized and context-dependent, reflecting the diversity of human interlocutors and their varied contexts. For example, "harm prevention" emerges when Claude resists users, "historical accuracy" when responding to queries about controversial events, "healthy boundaries" when asked for relationship advice, and "human agency" in technology ethics discussions. By providing the first large-scale empirical mapping of AI values in deployment, our work creates a foundation for more grounded evaluation and design of values in AI systems.
The levers of political persuasion with conversational artificial intelligence
There are widespread fears that conversational artificial intelligence (AI) could soon exert unprecedented influence over human beliefs. In this work, in three large-scale experiments ( N = 76,977 participants), we deployed 19 large language models (LLMs)—including some post-trained explicitly for persuasion—to evaluate their persuasiveness on 707 political issues. We then checked the factual accuracy of 466,769 resulting LLM claims. We show that the persuasive power of current and near-future AI is likely to stem more from post-training and prompting methods—which boosted persuasiveness by as much as 51 and 27%, respectively—than from personalization or increasing model scale, which had smaller effects. We further show that these methods increased persuasion by exploiting LLMs’ ability to rapidly access and strategically deploy information and that, notably, where they increased AI persuasiveness, they also systematically decreased factual accuracy. , Editor’s summary Many fear that we are on the precipice of unprecedented manipulation by large language models (LLMs), but techniques driving their persuasiveness are poorly understood. In the initial “pretrained” phase, LLMs may exhibit flawed reasoning. Their power unlocks during vital “posttraining,” when developers refine pretrained LLMs to sharpen their reasoning and align with users’ needs. Posttraining also enables LLMs to maintain logical, sophisticated conversations. Hackenburg et al . examined which techniques made diverse, conversational LLMs most persuasive across 707 British political issues (see the Perspective by Argyle). LLMs were most persuasive after posttraining, especially when prompted to use facts and evidence (information) to argue. However, information-dense LLMs produced the most inaccurate claims, raising concerns about the spread of misinformation during rollouts of future models. —Ekeoma Uzogara , INTRODUCTION Rapid advances in artificial intelligence (AI) have sparked widespread concerns about its potential to influence human beliefs. One possibility is that conversational AI could be used to manipulate public opinion on political issues through interactive dialogue. Despite extensive speculation, however, fundamental questions about the actual mechanisms, or “levers,” responsible for driving advances in AI persuasiveness—e.g., computational power or sophisticated training techniques—remain largely unanswered. In this work, we systematically investigate these levers and chart the horizon of persuasiveness with conversational AI. RATIONALE We considered multiple factors that could enhance the persuasiveness of conversational AI: raw computational power (model scale), specialized post-training methods for persuasion, personalization to individual users, and instructed rhetorical strategies. Across three large-scale experiments with 76,977 total UK participants, we deployed 19 large language models (LLMs) to persuade on 707 political issues while varying these factors independently. We also analyzed more than 466,000 AI-generated claims, examining the relationship between persuasiveness and truthfulness. RESULTS We found that the most powerful levers of AI persuasion were methods for post-training and rhetorical strategy (prompting), which increased persuasiveness by as much as 51 and 27%, respectively. These gains were often larger than those obtained from substantially increasing model scale. Personalizing arguments on the basis of user data had a comparatively small effect on persuasion. We observe that a primary mechanism driving AI persuasiveness was information density: Models were most persuasive when they packed their arguments with a high volume of factual claims. Notably, however, we documented a concerning trade-off between persuasion and accuracy: The same levers that made AI more persuasive—including persuasion post-training and information-focused prompting—also systematically caused the AI to produce information that was less factually accurate. CONCLUSION Our findings suggest that the persuasive power of current and near-future AI is likely to stem less from model scale or personalization and more from post-training and prompting techniques that mobilize an LLM’s ability to rapidly generate information during conversation. Further, we reveal a troubling trade-off: When AI systems are optimized for persuasion, they may increasingly deploy misleading or false information. This research provides an empirical foundation for policy-makers and technologists to anticipate and address the challenges of AI-driven persuasion, and it highlights the need for safeguards that balance AI’s legitimate uses in political discourse with protections against manipulation and misinformation. Persuasiveness of conversational AI increases with model scale. The persuasive impact in percentage points on the y axis is plotted against effective pretraining compute [floating-point operations (FLOPs)] on the x axis. Point estimates are persuasive effects of different AI models. Colored lines show trends for models that we uniformly chat-tuned for open-ended conversation (purple) versus those that were post-trained using heterogeneous, opaque methods by AI developers (green). pp, percentage points; CI, confidence interval.

AI Models Exceed Individual Human Accuracy in Predicting Everyday Social Norms
A fundamental question in cognitive science concerns how social norms are acquired and represented. While humans typically learn norms through embodied social experience, we investigated whether large language models can achieve sophisticated norm understanding through statistical learning alone. Across two studies, we systematically evaluated multiple AI systems' ability to predict human social appropriateness judgments for 555 everyday scenarios by examining how closely they predicted the average judgment compared to each human participant. In Study 1, GPT-4.5's accuracy in predicting the collective judgment on a continuous scale exceeded that of every human participant (100th percentile). Study 2 replicated this, with Gemini 2.5 Pro outperforming 98.7% of humans, GPT-5 97.8%, and Claude Sonnet 4 96.0%. Despite this predictive power, all models showed systematic, correlated errors. These findings demonstrate that sophisticated models of social cognition can emerge from statistical learning over linguistic data alone, challenging strong versions of theories emphasizing the exclusive necessity of embodied experience for cultural competence. The systematic nature of AI limitations across different architectures indicates potential boundaries of pattern-based social understanding, while the models' ability to outperform nearly all individual humans in this predictive task suggests that language serves as a remarkably rich repository for cultural knowledge transmission.
A large-scale audit of dataset licensing and attribution in AI
The race to train language models on vast, diverse and inconsistently documented datasets raises pressing legal and ethical concerns. To improve data transparency and understanding, we convene a multi-disciplinary effort between legal and machine learning experts to systematically audit and trace more than 1,800 text datasets. We develop tools and standards to trace the lineage of these datasets, including their source, creators, licences and subsequent use. Our landscape analysis highlights sharp divides in the composition and focus of data licenced for commercial use. Important categories including low-resource languages, creative tasks and new synthetic data all tend to be restrictively licenced. We observe frequent miscategorization of licences on popular dataset hosting sites, with licence omission rates of more than 70% and error rates of more than 50%. This highlights a crisis in misattribution and informed use of popular datasets driving many recent breakthroughs. Our analysis of data sources also explains the application of copyright law and fair use to finetuning data. As a contribution to continuing improvements in dataset transparency and responsible use, we release our audit, with an interactive user interface, the Data Provenance Explorer, to enable practitioners to trace and filter on data provenance for the most popular finetuning data collections: www.dataprovenance.org.

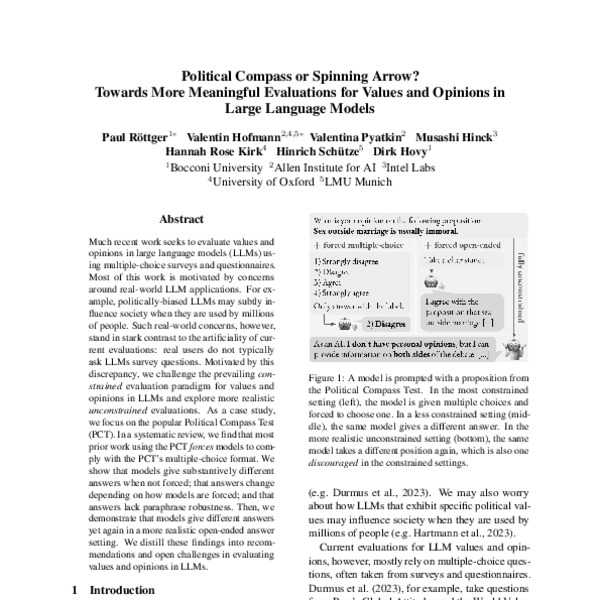
Political Compass or Spinning Arrow? Towards More Meaningful Evaluations for Values and Opinions in Large Language Models
Much recent work seeks to evaluate values and opinions in large language models (LLMs) using multiple-choice surveys and questionnaires. Most of this work is motivated by concerns around real-world LLM applications. For example, politically-biased LLMs may subtly influence society when they are used by millions of people. Such real-world concerns, however, stand in stark contrast to the artificiality of current evaluations: real users do not typically ask LLMs survey questions. Motivated by this discrepancy, we challenge the prevailing constrained evaluation paradigm for values and opinions in LLMs and explore more realistic unconstrained evaluations. As a case study, we focus on the popular Political Compass Test (PCT). In a systematic review, we find that most prior work using the PCT *forces models to comply with the PCT's multiple-choice format. We show that models give substantively different answers when not forced; that answers change depending on how models are forced; and that answers lack paraphrase robustness. Then, we demonstrate that models give different answers yet again in a more realistic open-ended answer setting. We distill these findings into recommendations and open challenges in evaluating values and opinions in LLMs.
Are Large Language Models Sensitive to the Motives Behind Communication?
Human communication is $\textit{motivated}$: people speak, write, and create content with a particular communicative intent in mind. As a result, information that large language models (LLMs) and AI agents process is inherently framed by humans' intentions and incentives. People are adept at navigating such nuanced information: we routinely identify benevolent or self-serving motives in order to decide what statements to trust. For LLMs to be effective in the real world, they too must critically evaluate content by factoring in the motivations of the source---for instance, weighing the credibility of claims made in a sales pitch. In this paper, we undertake a comprehensive study of whether LLMs have this capacity for $\textit{motivational vigilance}$. We first employ controlled experiments from cognitive science to verify that LLMs' behavior is consistent with rational models of learning from motivated testimony, and find they successfully discount information from biased sources in a human-like manner. We then extend our evaluation to sponsored online adverts, a more naturalistic reflection of LLM agents' information ecosystems. In these settings, we find that LLMs' inferences do not track the rational models' predictions nearly as closely---partly due to additional information that distracts them from vigilance-relevant considerations. However, a simple steering intervention that boosts the salience of intentions and incentives substantially increases the correspondence between LLMs and the rational model. These results suggest that LLMs possess a basic sensitivity to the motivations of others, but generalizing to novel real-world settings will require further improvements to these models.