


More of an evolution than a revolution
GPT-4 launched just 12 hours ago and people are already doing mind-blowing things with it. Check out these examples in this thread:
GPT-4 launched just 12 hours ago and people are already doing mind-blowing things with it.Check out these examples in this thread:— D-Coder (@Damn_coder) March 15, 2023
GPT-4 launched just 12 hours ago and people are already doing mind-blowing things with it. Check out these examples in this thread:
GPT-4 launched just 12 hours ago and people are already doing mind-blowing things with it.Check out these examples in this thread:— D-Coder (@Damn_coder) March 15, 2023
This new technology could blow away GPT-4 and everything like it
The Hyena code is able to handle amounts of data that make GPT-style technology run out of memory and fail.

GPT is the Heroku of AI - Ken Kantzer's Blog
I read a comment on HN that sparked this article: GPT is kind of like DevOps from the early 2000s. Here’s the hot take: I don’t see the primary value of GPT being in its ability to help me develop novel use cases or features – at least not right now. The primary value is […]
The Curse of Recursion: Training on Generated Data Makes Models Forget
Stable Diffusion revolutionised image creation from descriptive text. GPT-2, GPT-3(.5) and GPT-4 demonstrated astonishing performance across a variety of language tasks. ChatGPT introduced such...

Re-evaluating GPT-4’s bar exam performance
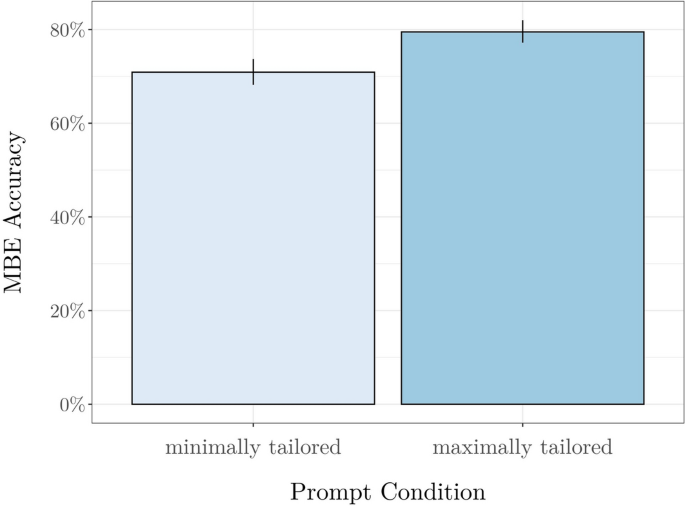
Perhaps the most widely touted of GPT-4’s at-launch, zero-shot capabilities has been its reported 90th-percentile performance on the Uniform Bar Exam. This paper begins by investigating the methodological challenges in documenting and verifying the 90th-percentile claim, presenting four sets of findings that indicate that OpenAI’s estimates of GPT-4’s UBE percentile are overinflated. First, although GPT-4’s UBE score nears the 90th percentile when examining approximate conversions from February administrations of the Illinois Bar Exam, these estimates are heavily skewed towards repeat test-takers who failed the July administration and score significantly lower than the general test-taking population. Second, data from a recent July administration of the same exam suggests GPT-4’s overall UBE percentile was below the 69th percentile, and $$\sim$$48th percentile on essays. Third, examining official NCBE data and using several conservative statistical assumptions, GPT-4’s performance against first-time test takers is estimated to be $$\sim$$62nd percentile, including $$\sim$$42nd percentile on essays. Fourth, when examining only those who passed the exam (i.e. licensed or license-pending attorneys), GPT-4’s performance is estimated to drop to $$\sim$$48th percentile overall, and $$\sim$$15th percentile on essays. In addition to investigating the validity of the percentile claim, the paper also investigates the validity of GPT-4’s reported scaled UBE score of 298. The paper successfully replicates the MBE score, but highlights several methodological issues in the grading of the MPT + MEE components of the exam, which call into question the validity of the reported essay score. Finally, the paper investigates the effect of different hyperparameter combinations on GPT-4’s MBE performance, finding no significant effect of adjusting temperature settings, and a significant effect of few-shot chain-of-thought prompting over basic zero-shot prompting. Taken together, these findings carry timely insights for the desirability and feasibility of outsourcing legally relevant tasks to AI models, as well as for the importance for AI developers to implement rigorous and transparent capabilities evaluations to help secure safe and trustworthy AI.
Understanding the Evolution of ChatGPT: Part 2 - GPT-2 and GPT-3
Scaling from 117M to 175B: Insights into GPT-2 and GPT-3.

clem 🤗 on Twitter / X
The main breakthrough of GPT-5 was to route your messages between a couple of different models to give you the best, cheapest & fastest answer possible.This is cool but imagine if you could do this not only for a couple of models but hundreds of them, big and small, fast and… pic.twitter.com/ww2ApYTN3D— clem 🤗 (@ClementDelangue) October 17, 2025
Auto-GPT Unmasked: The Hype and Hard Truths of Its Production Pitfalls
Auto-GPT: A groundbreaking project or just another overhyped AI experiment? In this blog post, we unravel the truth behind the buzz and reveal the limitations that make this project unsuitable for real-world applications.
GPT-4
We’ve created GPT-4, the latest milestone in OpenAI’s effort in scaling up deep learning. GPT-4 is a large multimodal model (accepting image and text inputs, emitting text outputs) that, while less capable than humans in many real-world scenarios, exhibits human-level performance on various professional and academic benchmarks.
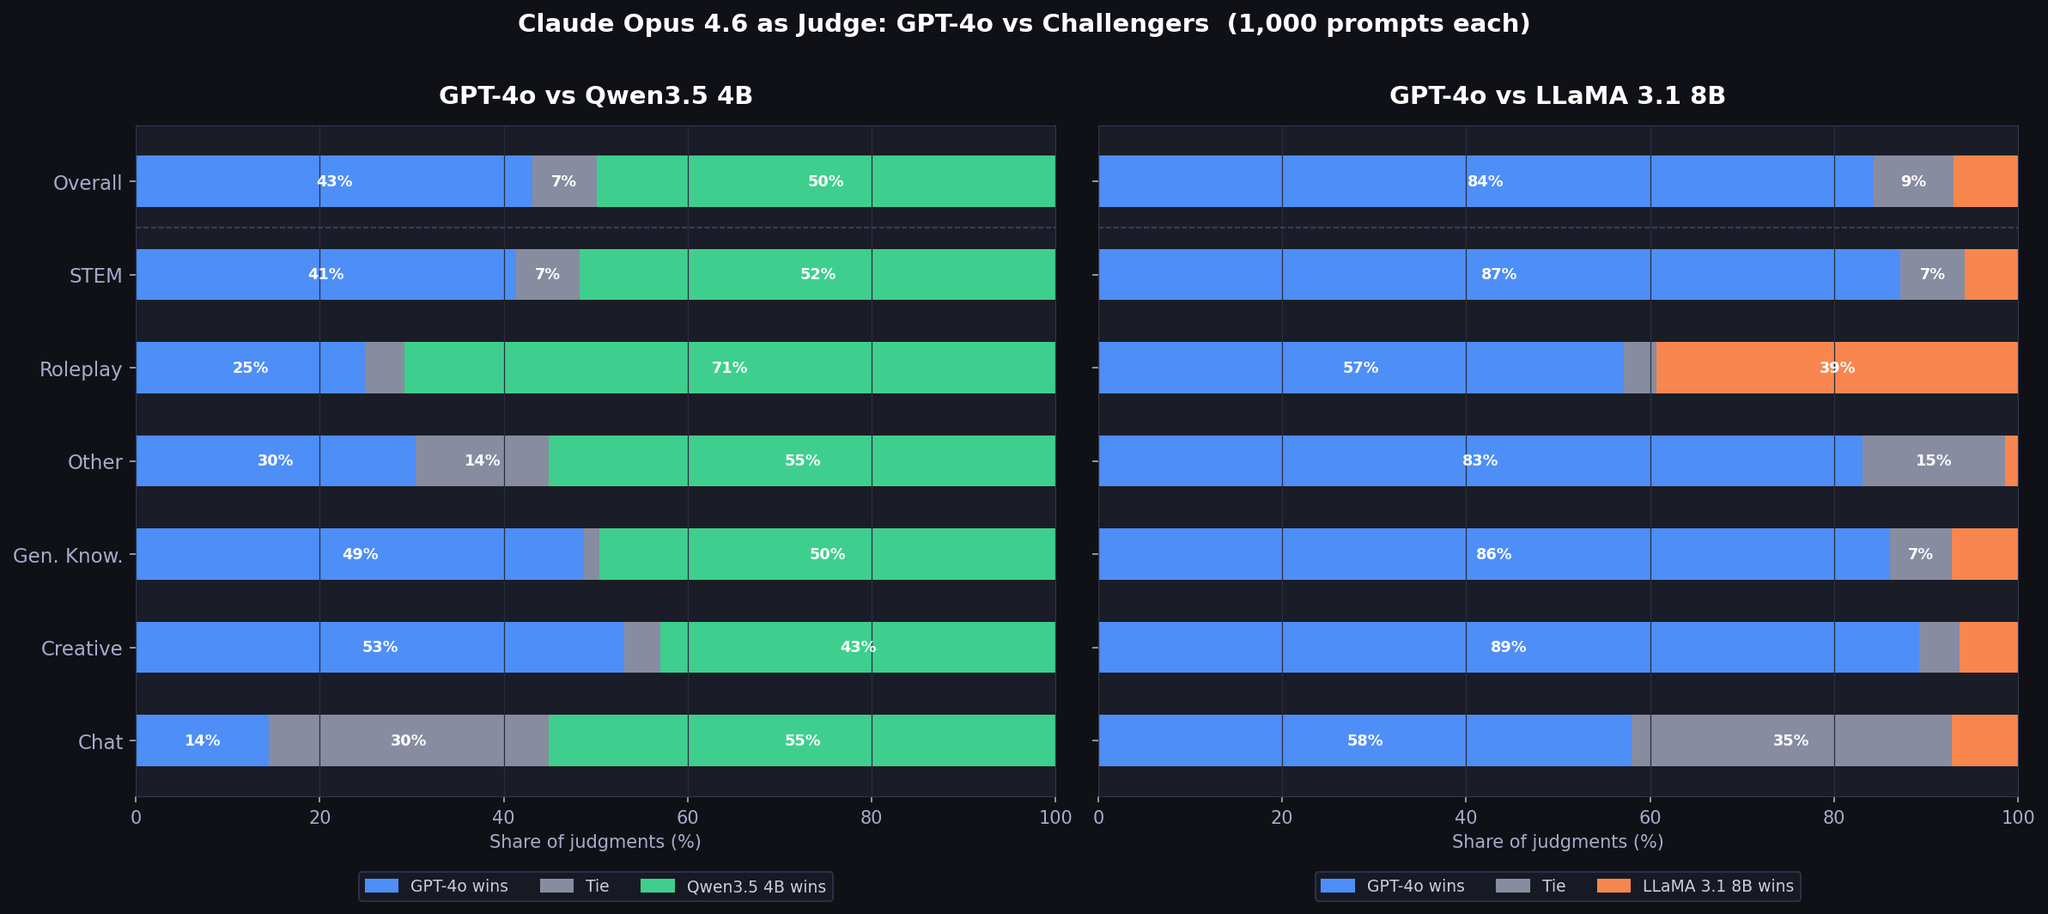
N8 Programs on Twitter / X
Recently, @awnihannun asserted that 'According to benchmarks Qwen3.5 4B is as good as GPT 4o.' This drew controversy: Is the 4B just benchmaxxed? How could a 4B be as good as GPT-4o? I tried to test this scientifically. The answer to the question is likely: yes, in most cases. pic.twitter.com/KI25XtkrZg— N8 Programs (@N8Programs) March 7, 2026
So, you think GPT-4 can't make a complex game... think again! Here's how I used GPT-4, @Replit, MidJourney, Claude, assembling a team of AI assistants, to create a 3D space runner from scratch with ZERO knowledge of Javascript or 3D game programming Follow along for a saga! 🧵
So, you think GPT-4 can't make a complex game... think again!Here's how I used GPT-4, @Replit, MidJourney, Claude, assembling a team of AI assistants, to create a 3D space runner from scratch with ZERO knowledge of Javascript or 3D game programmingFollow along for a saga! 🧵 pic.twitter.com/a8trr2xPZd— Ammaar Reshi (@ammaar) March 19, 2023

GPT-5.5: Capabilities and Reactions
The system card for GPT-5.5 mostly told us what we expected.
'Sparks of AGI' - Bombshell GPT-4 Paper: Fully Read w/ 15 Revelations
