


RSL 1.0 helps publishers outline how AI companies should pay for the content they scrape across the web.
What is RSL? | RSL: Really Simple Licensing
The open content licensing standard for the AI-first Internet
RSL: Really Simple Licensing
The open content licensing standard for the AI-first Internet
Exclusive: Multiple AI companies bypassing web standard to scrape publisher sites, licensing firm says
Multiple artificial intelligence companies are circumventing a common web standard used by publishers to block the scraping of their content for use in generative AI systems, content licensing startup TollBit has told publishers.
RSL for RAG/search makes sense, RSL for training doesn't · rslstandard · Discussion #1
The top of https://rslcollective.org/license says: Below are instructions for making your content available for training AI models through the collective licensing terms negotiated by the RSL Colle...
Introducing pay per crawl: Enabling content owners to charge AI crawlers for access
Pay per crawl is a new feature to allow content creators to charge AI crawlers for access to their content.
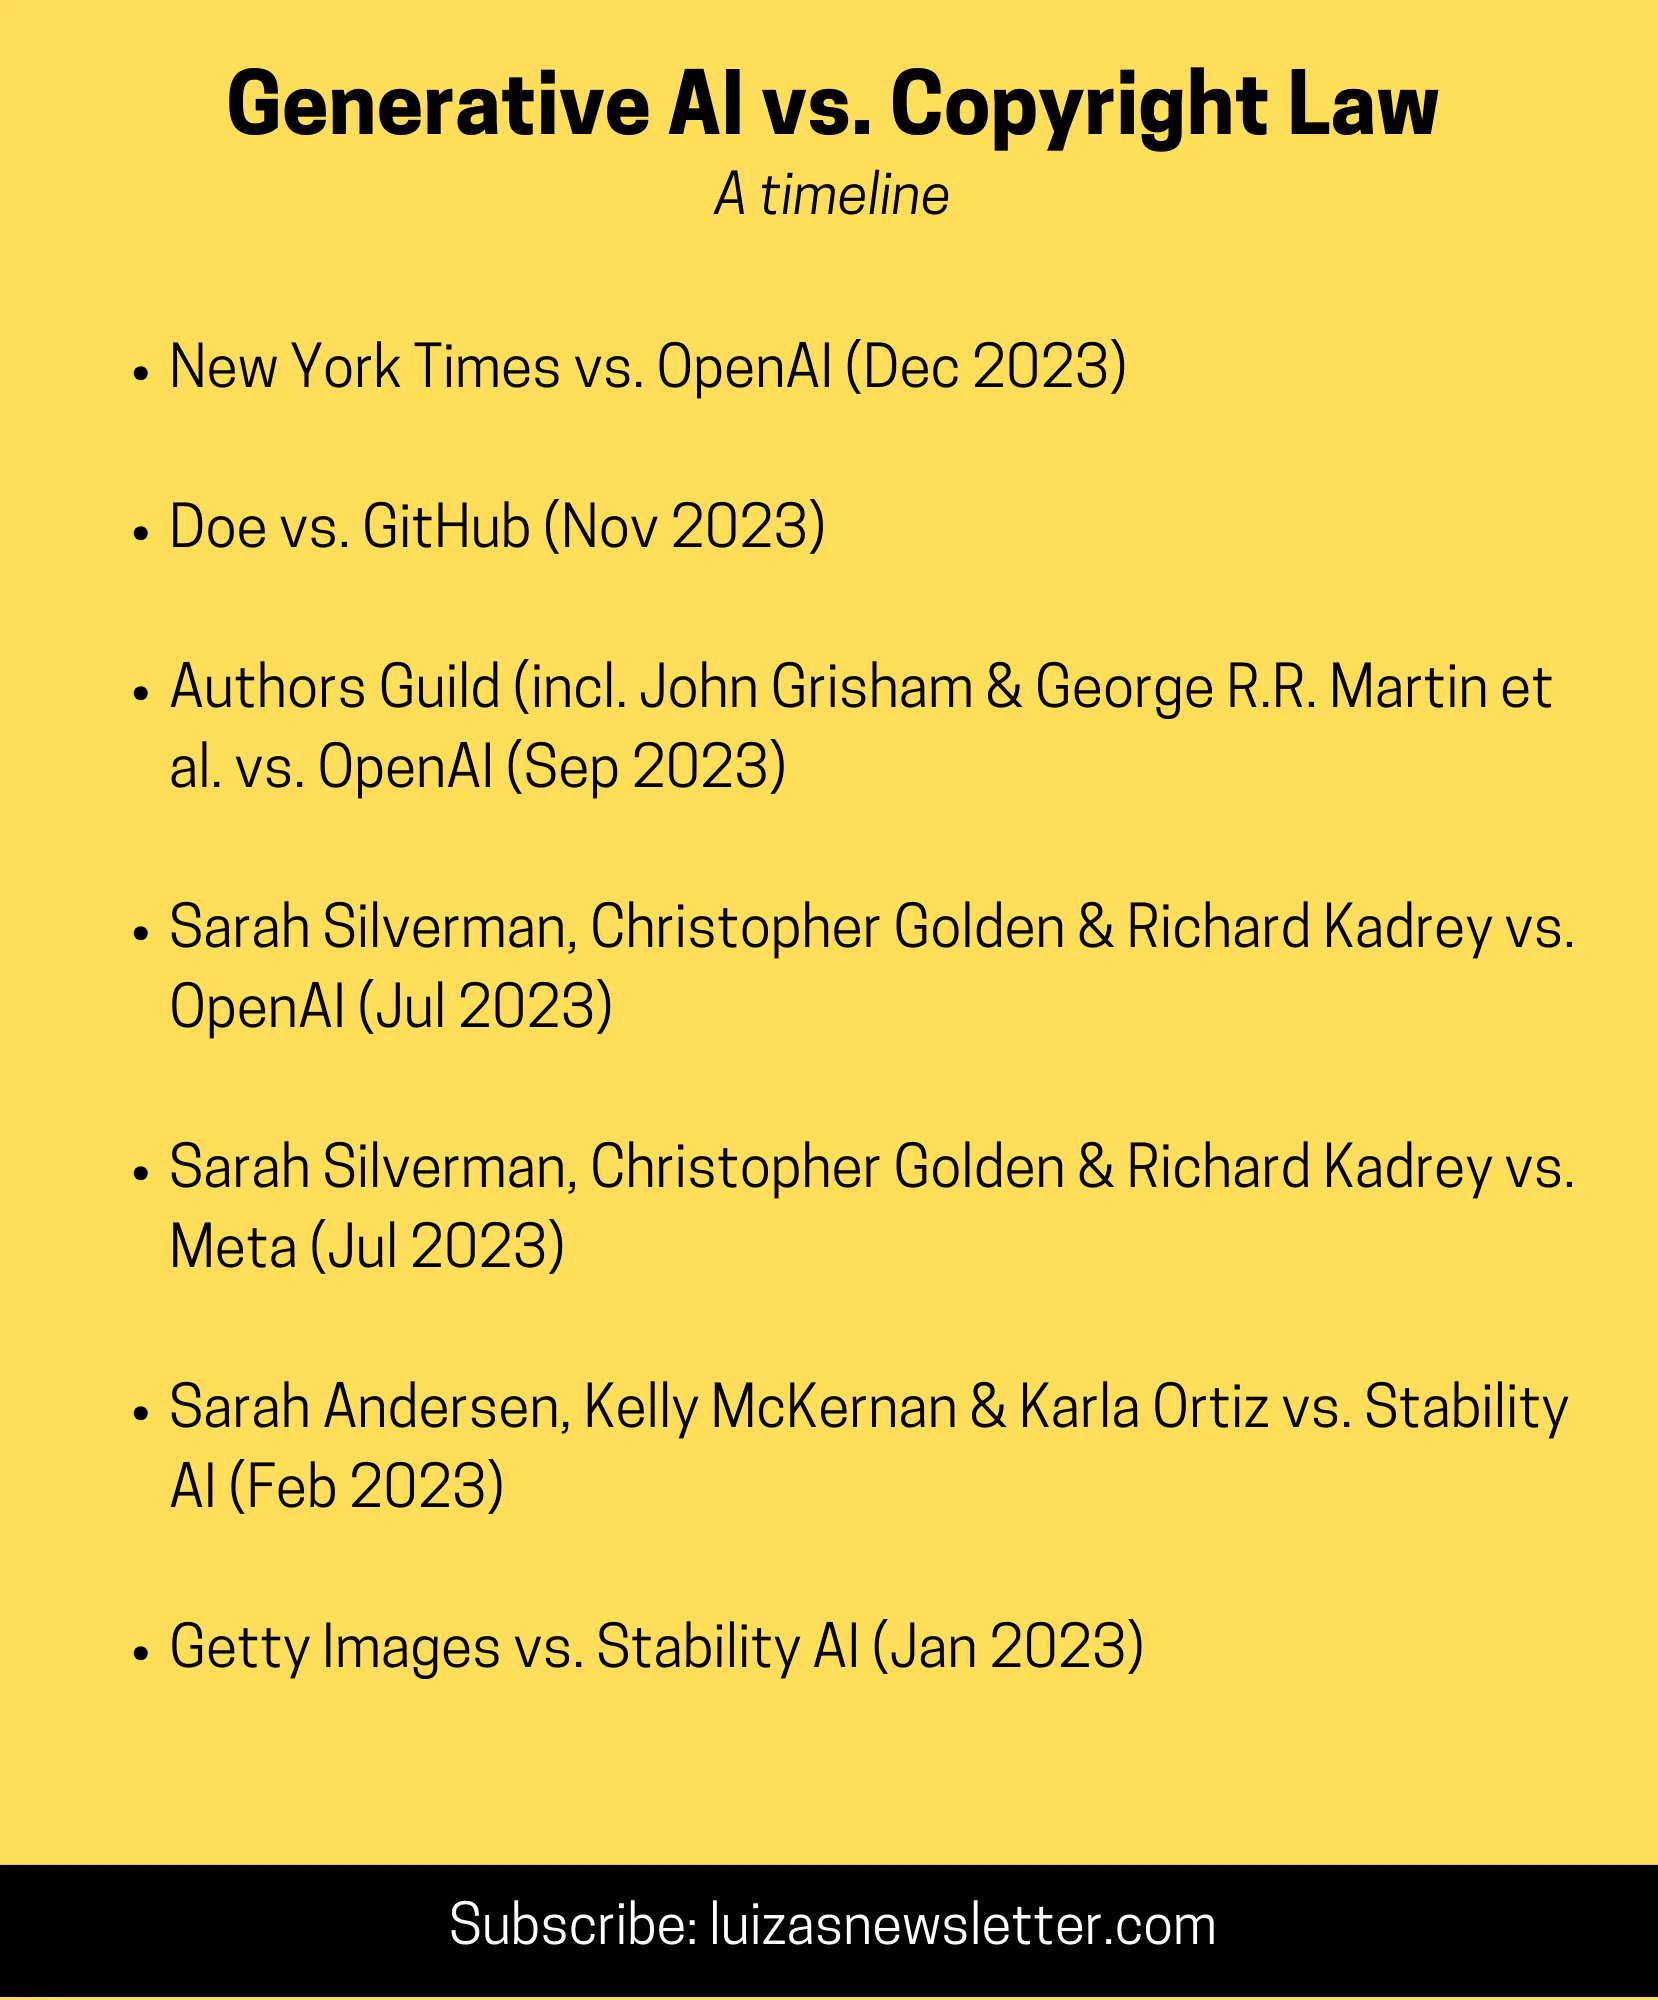
⚖️ Generative AI vs. Copyright Law - a timeline. If you are a privacy professional, you can't ignore AI-related copyright lawsuits anymore. Read this: In order to develop and train large language models (LLMs), AI companies rely on web scraping, a practice that will "dig
⚖️ Generative AI vs. Copyright Law - a timeline. If you are a privacy professional, you can't ignore AI-related copyright lawsuits anymore. Read this:In order to develop and train large language models (LLMs), AI companies rely on web scraping, a practice that will "digest" all… pic.twitter.com/VD6R8UJszN— Luiza Jarovsky, PhD (@LuizaJarovsky) January 3, 2024
An update on the scraper situation
Our article 'Fighting the AI scraper bot scourge', published in early 2025, discussed the probl [...]
AI Firms Say They Can't Respect Copyright. But A Nonprofit's Researchers Just Built a Copyright-Respecting Dataset - Slashdot
Is copyrighted material a requirement for training AI? asks the Washington Post. That's what top AI companies are arguing, and "Few AI developers have tried the more ethical route — until now. "A group of more than two dozen AI researchers have found that they could build a massive eight-t...

The Agentic Web and Original Sin
Microsoft is putting forth compelling proposals for the Open Agentic Web. However, the proposal needs digital payments, which will be key to creating a new content marketplace for AI.

The Agentic Web and Original Sin
Microsoft is putting forth compelling proposals for the Open Agentic Web. However, the proposal needs digital payments, which will be key to creating a new content marketplace for AI.

Are AI Outputs Covered by Copyright Laws?
Understanding why your AI prompts are not enough to qualify for copyright protection.
Meta seeks to scrape news content for AI training without permission | Angela Mills Wade posted on the topic | LinkedIn
Meta’s message to publishers: let us scrape your journalism for AI, or stop using our platforms. In the very week that News Media Coalition launched their Primary Source Journalism Framework we get another extraordinary example of how dominant digital platforms are attempting to turn their market power into permission to appropriate the content of others. For free. As reported by Nieman Journalism Lab, Meta’s new commercial terms, effective 30 October, purport to authorise the company to scrape websites associated with business accounts, including news publishers, and use that content to train its products. No negotiated licence. No meaningful choice. Just acceptance by continued use of Meta’s services. And the implications go further. The terms even contemplate creating test credentials to access websites, raising serious questions about publishers’ ability to control access to their own content. Meta argues that publishers can still use robots.txt to restrict crawling but this is no safeguard to protect primary source journalism as such sweeping ‘contractual’ permissions could undermine publishers rights reservations. This is becoming a familiar pattern. Google effectively ties visibility in Search to the use of publishers’ content in its AI services. Now Meta appears to be seeking similarly expansive rights through its commercial terms. This is not consent freely given. It is an attempt to leverage platform dependency to extract valuable intellectual property without negotiation or remuneration. European copyright law gives publishers rights over their content, including the right to reserve it from text and data mining. Those rights must not be circumvented through take-it-or-leave-it contractual conditions imposed by powerful gatekeepers. The European Commission and competition authorities should scrutinise these terms urgently, including their implications for copyright, contractual fairness and abuse of market power. Publishers must retain the right to decide whether, how and on what terms their journalism is used by AI companies. Opt-in, not opt-out. Licensing, not appropriation. Henna Virkkunen Teresa Ribera #Copyright #AI #PrimarySourceJournalism #MediaPluralism #Competition #Publishers #BadBots | 23 comments on LinkedIn
Here’s Proof You Can Train an AI Model Without Slurping Copyrighted Content
OpenAI claimed it’s “impossible” to build good AI models without using copyrighted data. An “ethically created” large language model and a giant AI dataset of public domain text suggest otherwise.
Microsoft CEO of AI Says It’s Fine to Steal Anything on the Open Web
Microsoft AI CEO Mustafa Suleyman has some thoughts about fair use — and according to him, just about anything online is fair for him to use!
TollBit - Monetize your content
The platform for AI content licensing at scale. TollBit helps you monitor AI traffic, manage licensing deals & monetize your content in the AI era.
AI*-generated copyright infringement

* I’m neither “pro-AI” nor “anti-AI.” I’ve been blocked for being perceived as both. —Actually, I’m honestly more anti-AI than pro-AI thus far, aside from specialized models and specific use cases, but I’m willing to consider information that’s new to me

Hayao Miyazaki, Who Said AI Is ‘Insult to Life Itself,” Reduced to AI-Generated Meme by OpenAI
People Are Crashing Out Over Sora 2’s New Guardrails
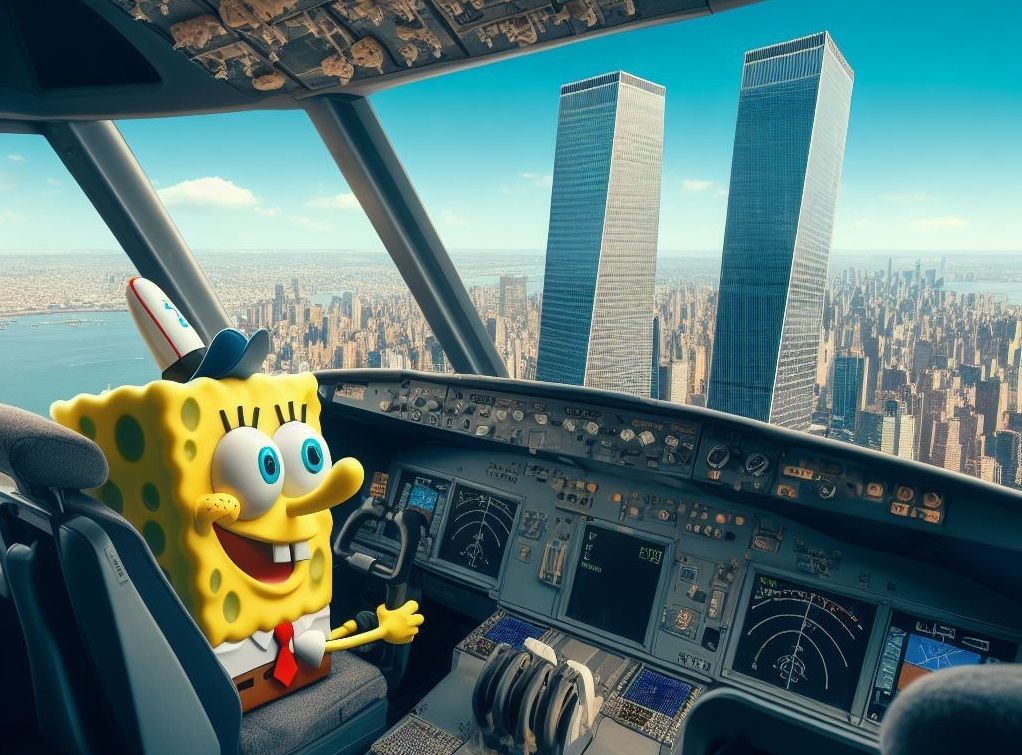
Bing Is Generating Images of SpongeBob Doing 9/11
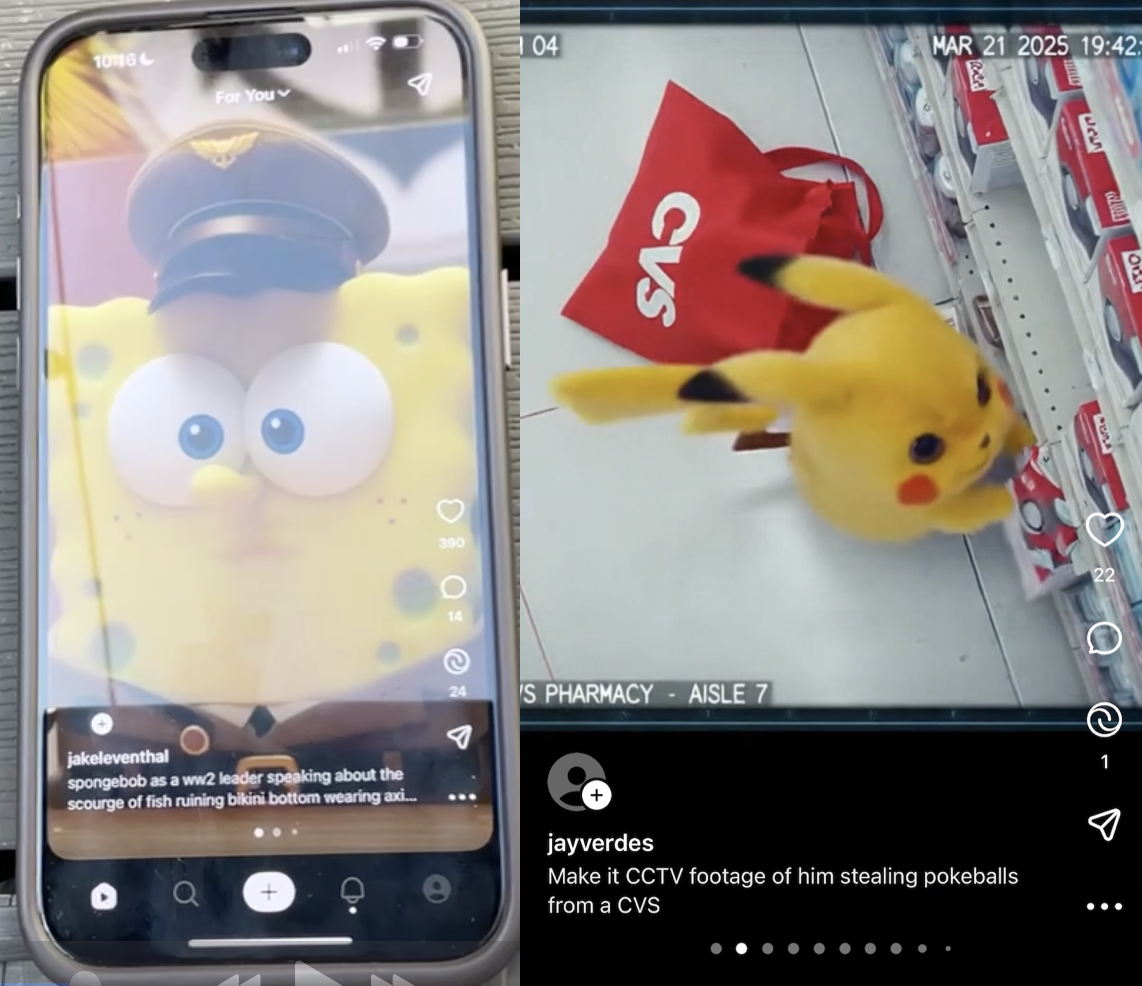
OpenAI’s Sora 2 Copyright Infringement Machine Features Nazi SpongeBobs and Criminal Pikachus
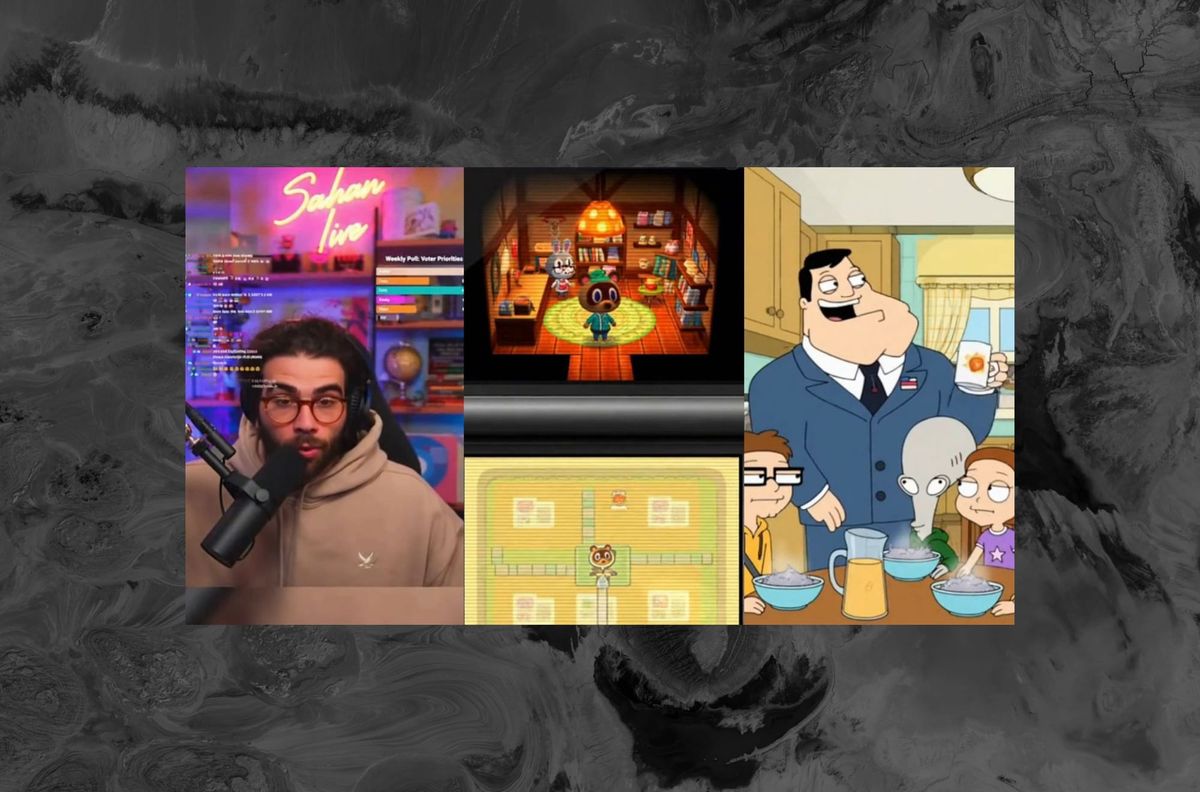
OpenAI Can’t Fix Sora’s Copyright Infringement Problem Because It Was Built With Stolen Content