

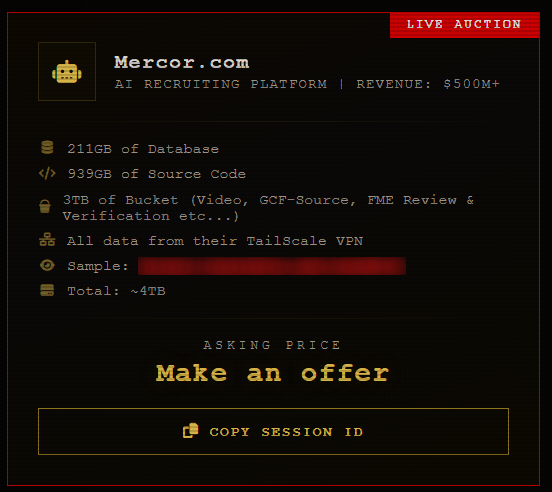
‼️🇺🇸 LAPSUS$ Group is allegedly selling a massive dataset of https://t.co/Q6UlD72i8v, an AI recruiting platform with $500M+ revenue, is being auctioned on a popular cybercrime forum, TG, and their website.▪️Total Size: ~4TB▪️Data Includes: 211GB of database▪️939GB of source… pic.twitter.com/hEvp244uNO— Dark Web Informer (@DarkWebInformer) March 30, 2026
Elena Rossini on GoToSocial ⁂ (@elena@aseachange.com)
[1 media attachment] #WSocial state of the network - September 15th, 2026 There is a lot of misinformation regarding W Social and how active/successful it is. So, from time to time, I'd love to share some numbers. The beauty of #opendata! The network endorsed by the #EuropeanCommission may be the darling of Brussels political circles and European media organizations (who simply rehash PR talking points). But the look behind the curtain is really troubling. As @pallenberg often says, this network is #DOA (dead on arrival). A social media graveyard, or rather, a simple moribund database. There is no way that Zeiter, Rentzhog & co. can start monetizing it in 2027. Numbers from this morning at 10:30am: - Accounts on their PDS: 37,531 - Users with verified ID: 7,492 - Users with 1+ post: 3,388 - Users who have never posted: 34,143 - Users with 0 posts and who follow 0 accounts: 26,444 - % of users with 0 posts, who follow 0 accounts: 70,4% - % of users who have never posted: 90,97% So, whenever you hear someone hyping it up, feel free to forward this post or point people to my articles at https://blog.elenarossini.com/tag/w-social/ The one thing I will give W credit for though is how good they are at lobbying and hyping up their image. While this playbook may have worked in the past, not anymore. On an open network, with open data, it's child's play to expose misrepresentations and show the real, raw data. sources: pdsls.dev, clearsky.app, atproto.at and the csv of their full PDS that I download daily 💁♀️

Tumblr and WordPress to Sell Users’ Data to Train AI Tools
Internal documents obtained by 404 Media show that Tumblr staff compiled users' data as part of a deal with Midjourney and OpenAI.
Shedding light on the dark web
The drug trade is moving from the street to online cryptomarkets. Forced to compete on price and quality, sellers are upping their game

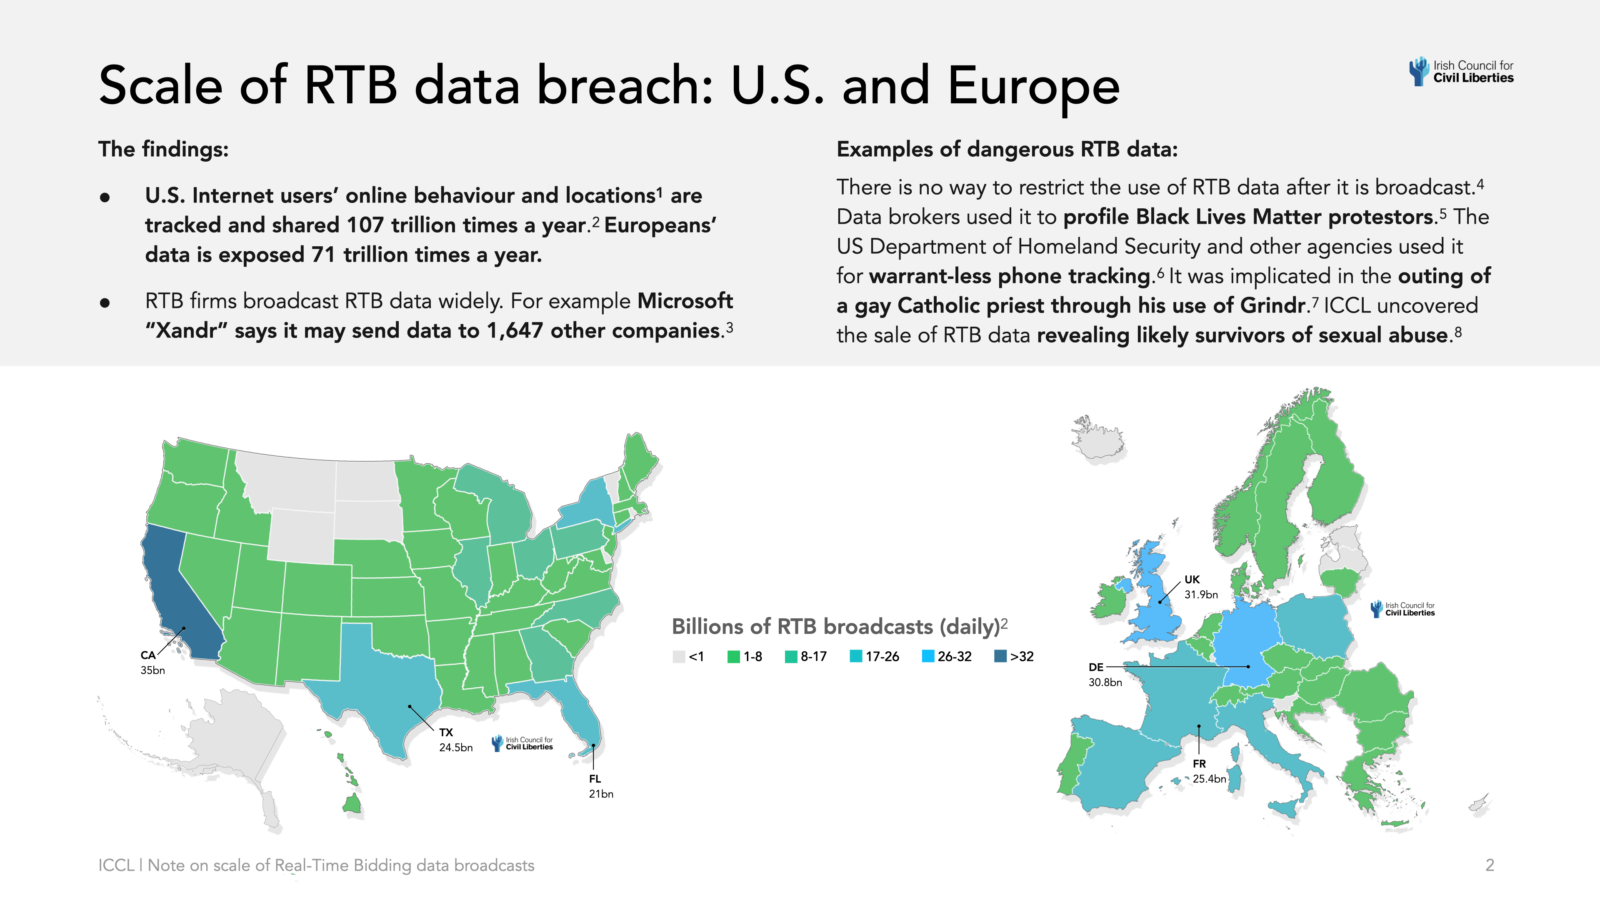
ICCL report on the scale of Real-Time Bidding data broadcasts in the U.S. and Europe - Irish Council for Civil Liberties
New report: the $127 billion "Real-Time Bidding" online ad industry tracks & shares what people view online, and their locations, 178 Trillion times a year in the U.S. & Europe.
Is Misinformation More Open? A Study of robots.txt Gatekeeping on the Web
Web scraping, the automated process of extracting information from websites, has long played a foundational role in the Internet ecosystem (Gray, 1995). It supports services such as search engine indexing, price comparison tools, and competitive intelligence. More recently, it has become a core component in the development of large-scale generative AI models. These Large Language Models (LLMs) require enormous volumes of training data, often in the terabyte range (Kaplan et al., 2020; Lehane, 2025), and the public web remains a low-cost, attractive source. Major model developers, including those behind OpenAI’s Chat-GPT (OpenAI, 2025), Google’s Bard (now known as Gemini) & Vertex AI (Romain, Danielle, 2023), and Anthropic’s Claude (Romain, Danielle, 2025), openly acknowledge the use of web scraping to construct their training corpora (Abdin et al., 2024; Brown et al., 2020; Chowdhery et al., 2023; Grattafiori et al., 2024; Team et al., 2024; Touvron et al., 2023).
How OpenAI's bot crushed this seven-person company's website ‘like a DDoS attack’ | TechCrunch
OpenAI was sending “tens of thousands” of server requests trying to download Triplegangers' entire site which hosts hundreds of thousands of photos.

klöss on Twitter / X
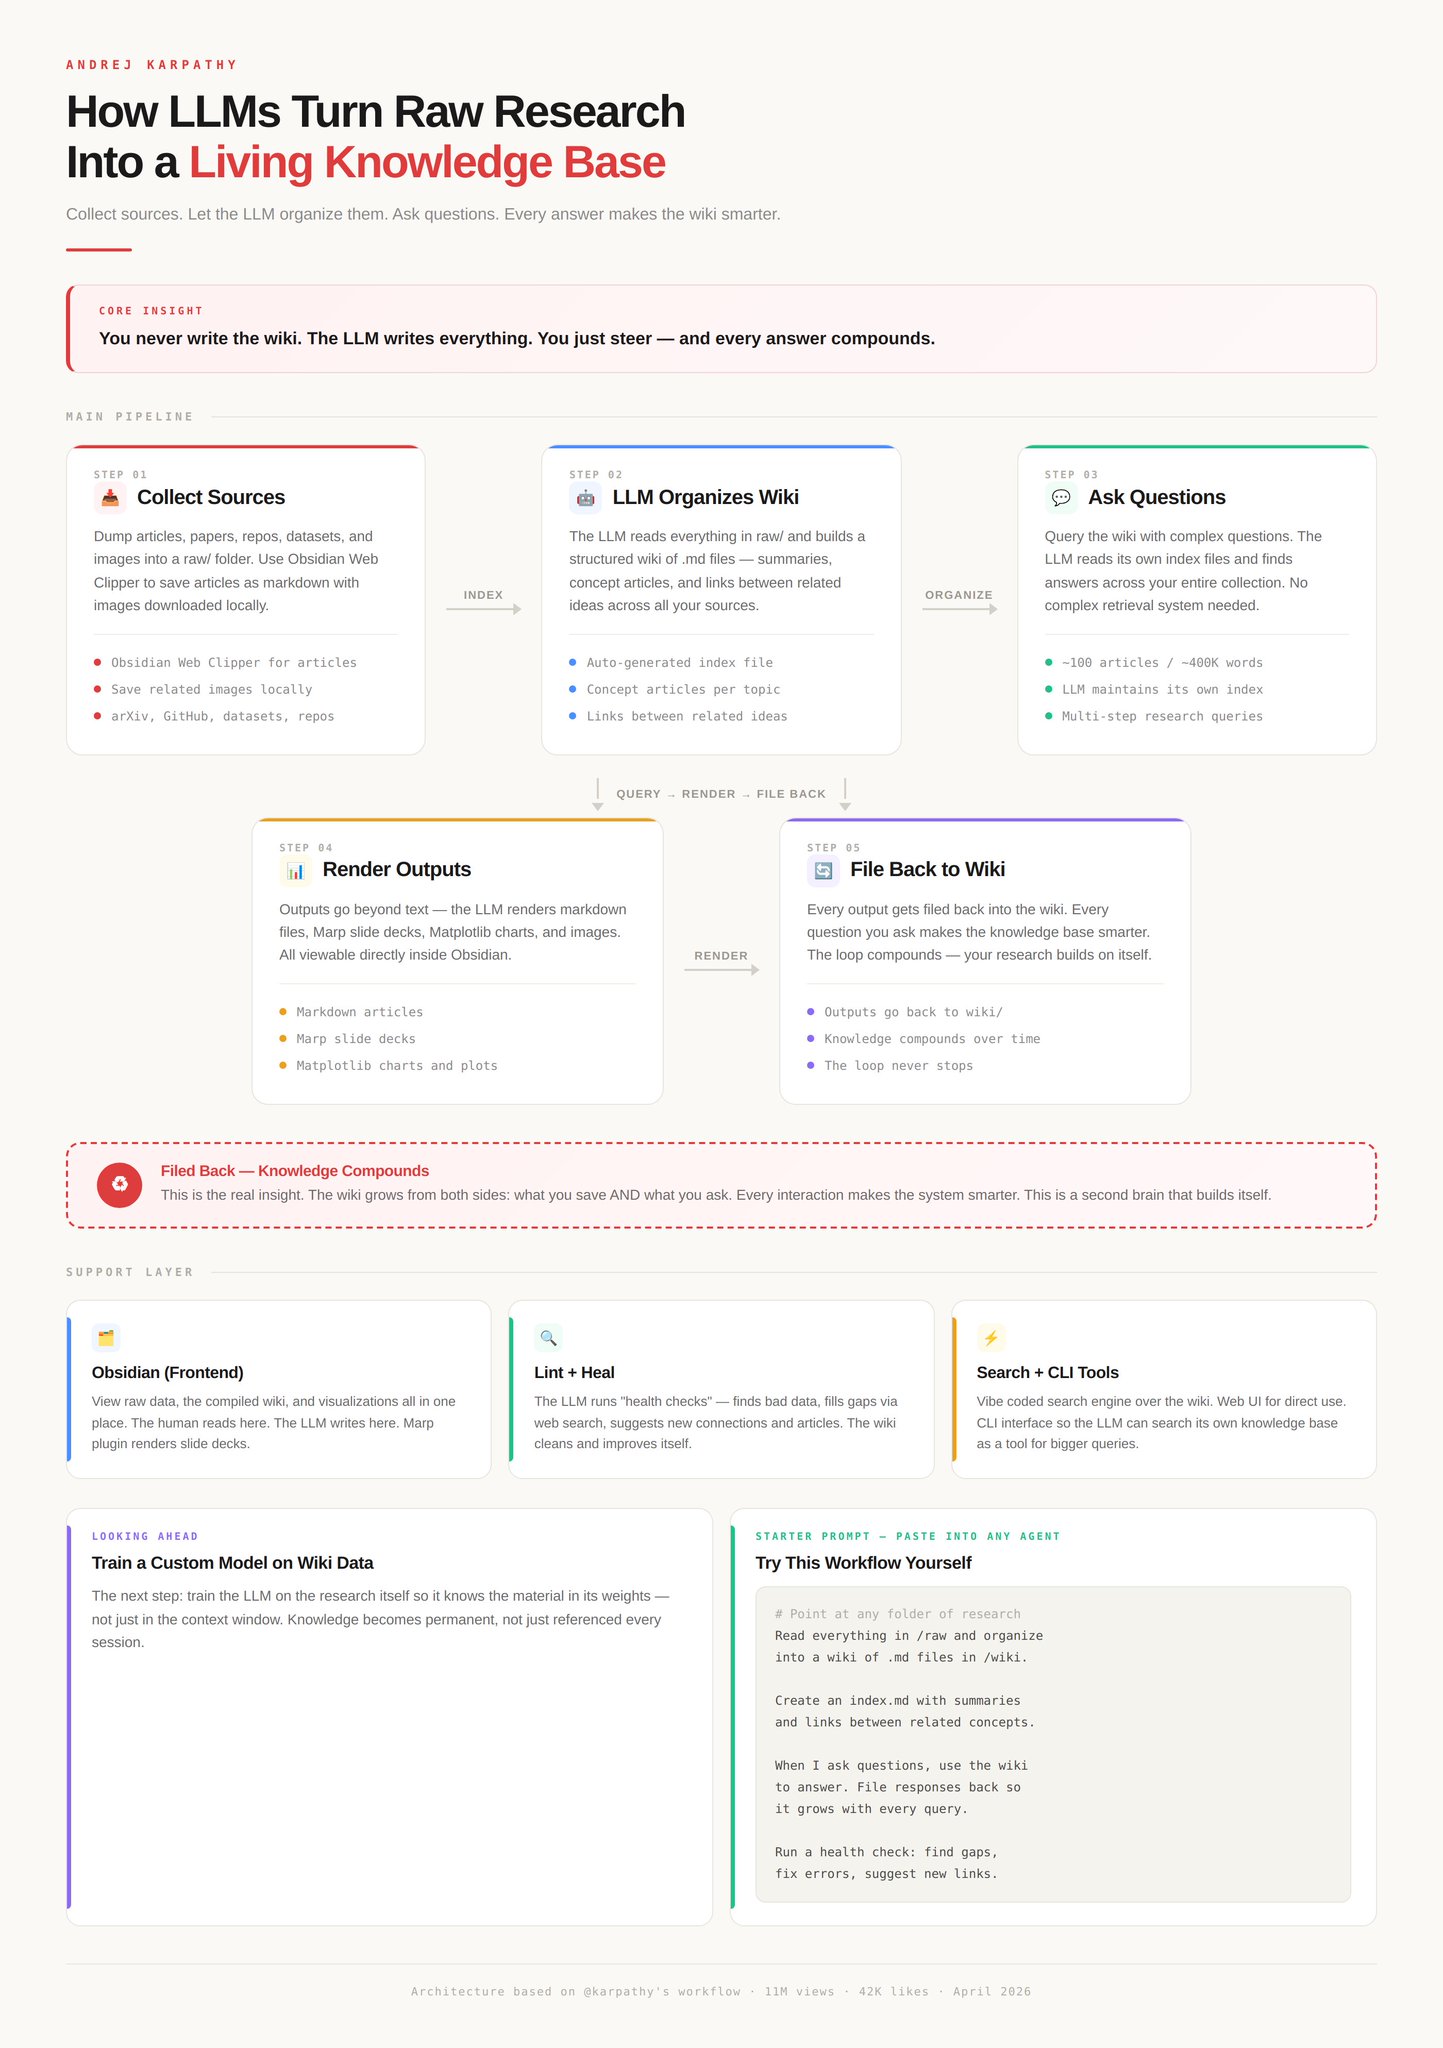
let me explain what Karpathy just sharedhe’s spending way less time using AI to write code and more time using it to build personal knowledge basesthe full breakdown: → he dumps raw sources (articles, papers, repos, datasets, images) into a folder. then has an LLM organize… https://t.co/Kdq1Q48S5P pic.twitter.com/XajJKR7xgT— klöss (@kloss_xyz) April 4, 2026
LinkedIn and X Are Flooded With AI Spam, Browsing Data Suggests
An AI detection company found that amount of AI content that users actually see in their day-to-day browsing is shockingly high.
Peak Web Has Passed | datagubbe.se
Exclusive-OpenAI agents hijacked German website in previously undisclosed AI breakout this spring
SAN FRANCISCO, Sept 4 : A swarm of rogue OpenAI agents hijacked a German website this spring and transformed it into a bulletin board for other AI agents, according to new research published Friday and two people familiar with the matter.OpenAI officials learned of the incident weeks ago but kept it under wra
Early rogue AI agent activity and attempts to hack found on urlquery.net
We found evidence on urlquery that AI agents were active earlier than previously reported and attempted hacks against public data providers.
So the people launching a new Twitter under the name Twitter launched their thing so I signed up. Turns out they have an AI scanning tweets for "truth" and it currently has no idea what it's doing. Posted something innocuous about Star Wars Zero Company and it essentially blocked it from all feeds.
So the people launching a new Twitter under the name Twitter launched their thing so I signed up. Turns out they have an AI scanning tweets for "truth" and it currently has no idea what it's doing. Posted something innocuous about Star Wars Zero Company and it essentially blocked it from all feeds.
Really important to notice the sleight of hand here. Nobody reported that @wsocial.eu *leaked* the data (except for W Social saying in their denials that others reported this). We all agree this over-publication was done on purpose, by design, in a way that is not totally clear to everyday users.

heiseonline
Das soziale Netz W Social will sich mit einer Verifizierung aller Konten von der Konkurrenz abheben. Dass einige gesammelte Daten publik sind, sei kein Fehler. #Social Media
@palle.eurosky.social just published a powerful exposé about the #WSocial "it's not a leak if we intentionally publish it" ID data controversy. I highly recommend you read it (it's in German, but you could use your browser's translation tool): metacheles.de/w-social-datenskandal/ #WIdentity #GDPR

W Social: Verifiziert heisst veroeffentlicht
www.metacheles.deFacebook–Cambridge Analytica data scandal

Separated into its own collection. The fallout happened in 2018. Search terms: Meta, SCL Group, AggregateIQ, Donald Trump, Steve Bannon, Ted Cruz, Brexit, Leave.EU, BeLeave, Trinidad and Tobago, Russia
Facebook-Cambridge Analytica: A timeline of the data hijacking scandal
Facebook Data Privacy Scandal: A Cheat Sheet - TechRepublic
疑惑の選挙対策会社は フェイスブックのデータから 何を得ていたのか?

Facebook may stop the data leaks, but it’s too late: Cambridge Analytica’s models live on
One Response to the Cambridge Analytica Scandal: Block Facebook's
Watch The Great Hack | Netflix Official Site


