

Google Turbo Quant running Locally in Atomic ChatMacBook Air M4 16 GBModel: QWEN3.5-9BContext window: 50000Summarising 20000 words in just seconds..You can do 3x larger context window, processing 3x faster than before! pic.twitter.com/FRYkXCGjQb— atomic.chat (@atomic_chat_hq) March 27, 2026
Atomic Chat: Free Local AI Chat for Mac, Windows & iPhone | Private & Offline
Free, open-source local AI chat for Mac, Windows & iPhone. Run Gemma, Qwen, DeepSeek, Llama offline. 1,000+ models, no cloud, no subscription. Download free.
Artur Chakhvadze on Twitter / X
We are releasing our first quantized checkpoints for the Qwen3.5 series of models, co-designed jointly with our inference engine to achieve maximum possible performance on Apple hardwareStarting from 0.8B, 2B and 4B modelshttps://t.co/2R8BdhAfzv— Artur Chakhvadze (@norpadon) June 8, 2026
Qwen on Twitter / X
Qwen3-TTS is officially live. We’ve open-sourced the full family—VoiceDesign, CustomVoice, and Base—bringing high quality to the open community.- 5 models (0.6B & 1.8B)- Free-form voice design & cloning- Support for 10 languages- SOTA 12Hz tokenizer for high compression-… pic.twitter.com/BSWpaYoZWj— Qwen (@Alibaba_Qwen) January 22, 2026

Unsloth AI on Twitter / X
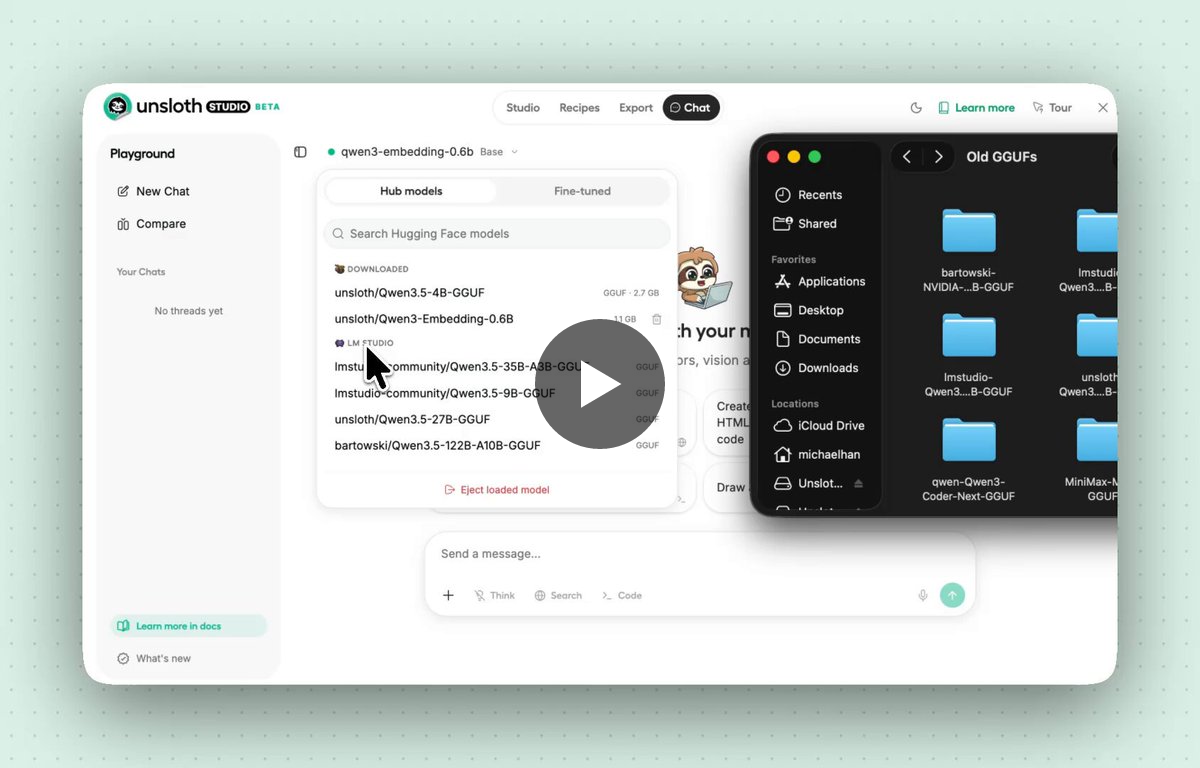
Inference in Unsloth Studio is now ~20% faster.You can also use older pre-downloaded GGUFs from Hugging Face etc.AMD chat support for Linux now works. Data Recipes now works on macOS, AMD, CPU setups.GitHub: https://t.co/aZWYAtakBPChangelog: https://t.co/npRrgSMYs3 pic.twitter.com/cnZvoG1TeN— Unsloth AI (@UnslothAI) March 27, 2026
Luozhu on Twitter / X
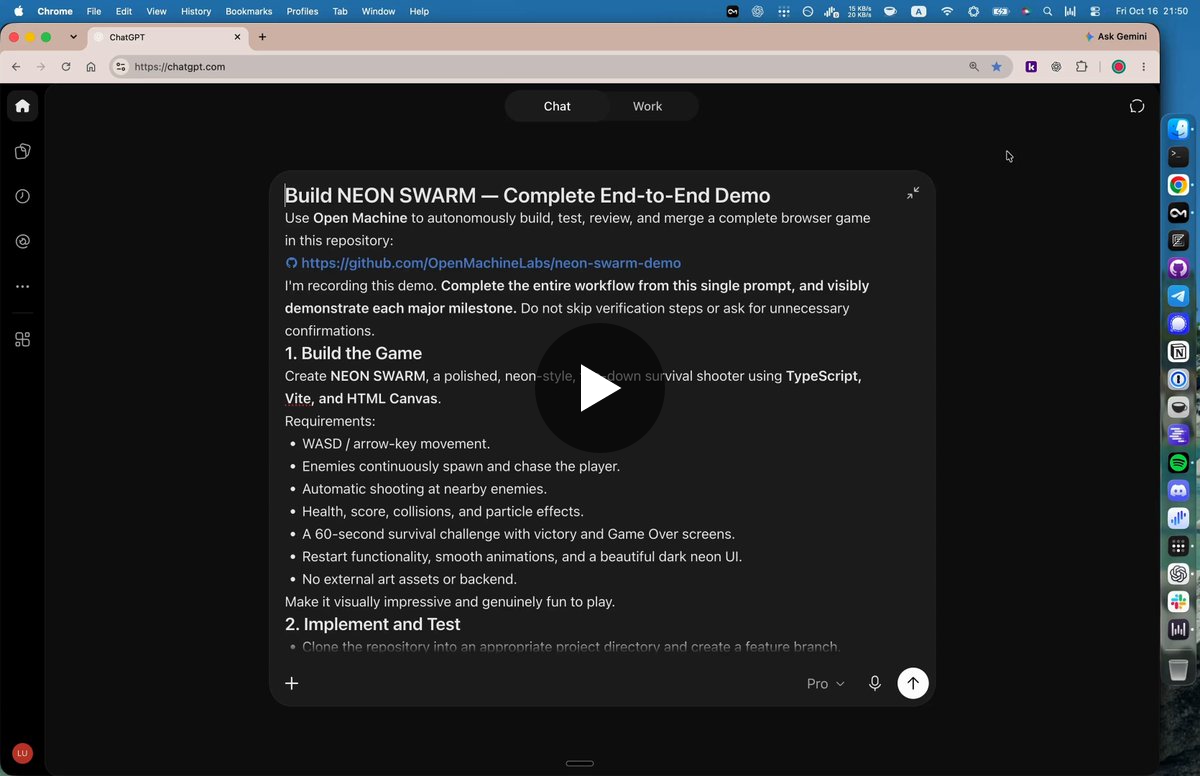
I built a ChatGPT plugin that lets regular Chat mode work like Codex. Finally, no more worrying about usage limits.Meet Open Machine — an open-source MCP tool that lets ChatGPT directly operate your computer to write code, run commands, use browsers, and manage GitHub… pic.twitter.com/xqQjNXeDdk— Luozhu (@LuozhuZhang) October 16, 2026
INIYSA on Twitter / X
Apple's on-device SLM, while not as strong in simple multilingual tasks as Google's Gemma 3 4B (3.3GB, 5GB in memory), seems to outperform Qwen3 4B or Phi 4 mini reasoning. It's very very impressive, especially considering its extremely reduced size of around ~1.4GB— INIYSA (@lafaiel) June 10, 2025
Beyond Chat: Bringing Models to the Canvas • Lu Wilson • GOTO 2025
clem 🤗 on Twitter / X
We just released an hf CLI extension to detect the best model/quant for a user's hardware and then spins up a local coding agent. Time to go local/private/free/fast for your agents thanks to open-source! pic.twitter.com/LcVJzGCqWx— clem 🤗 (@ClementDelangue) March 17, 2026

kwindla on Twitter / X
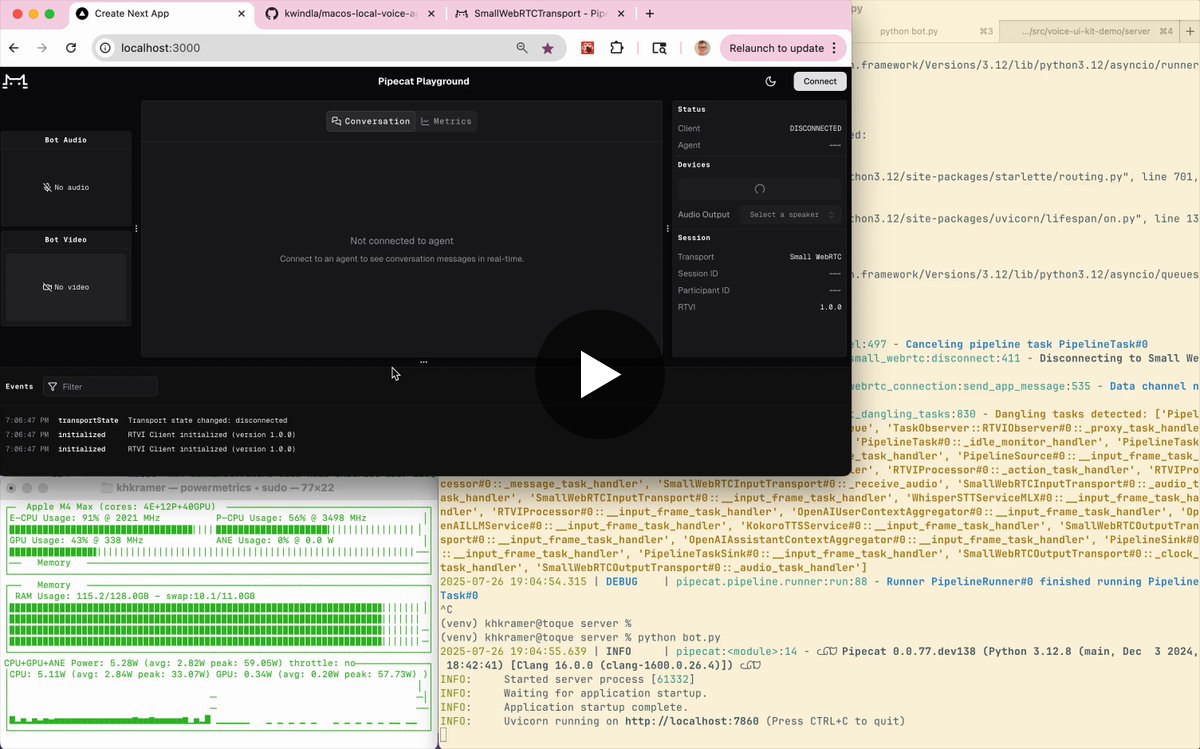
Local voice AI with a 235 billion parameter LLM. ✅- smart-turn v2- MLX Whisper (large-v3-turbo-q4)- Qwen3-235B-A22B-Instruct-2507-3bit-DWQ- KokoroAll models running local on an M4 mac. Max RAM usage ~110GB.Voice-to-voice latency is ~950ms. There are a couple of… pic.twitter.com/iYNQlb9JkI— kwindla (@kwindla) July 27, 2025
Qwen on Twitter / X
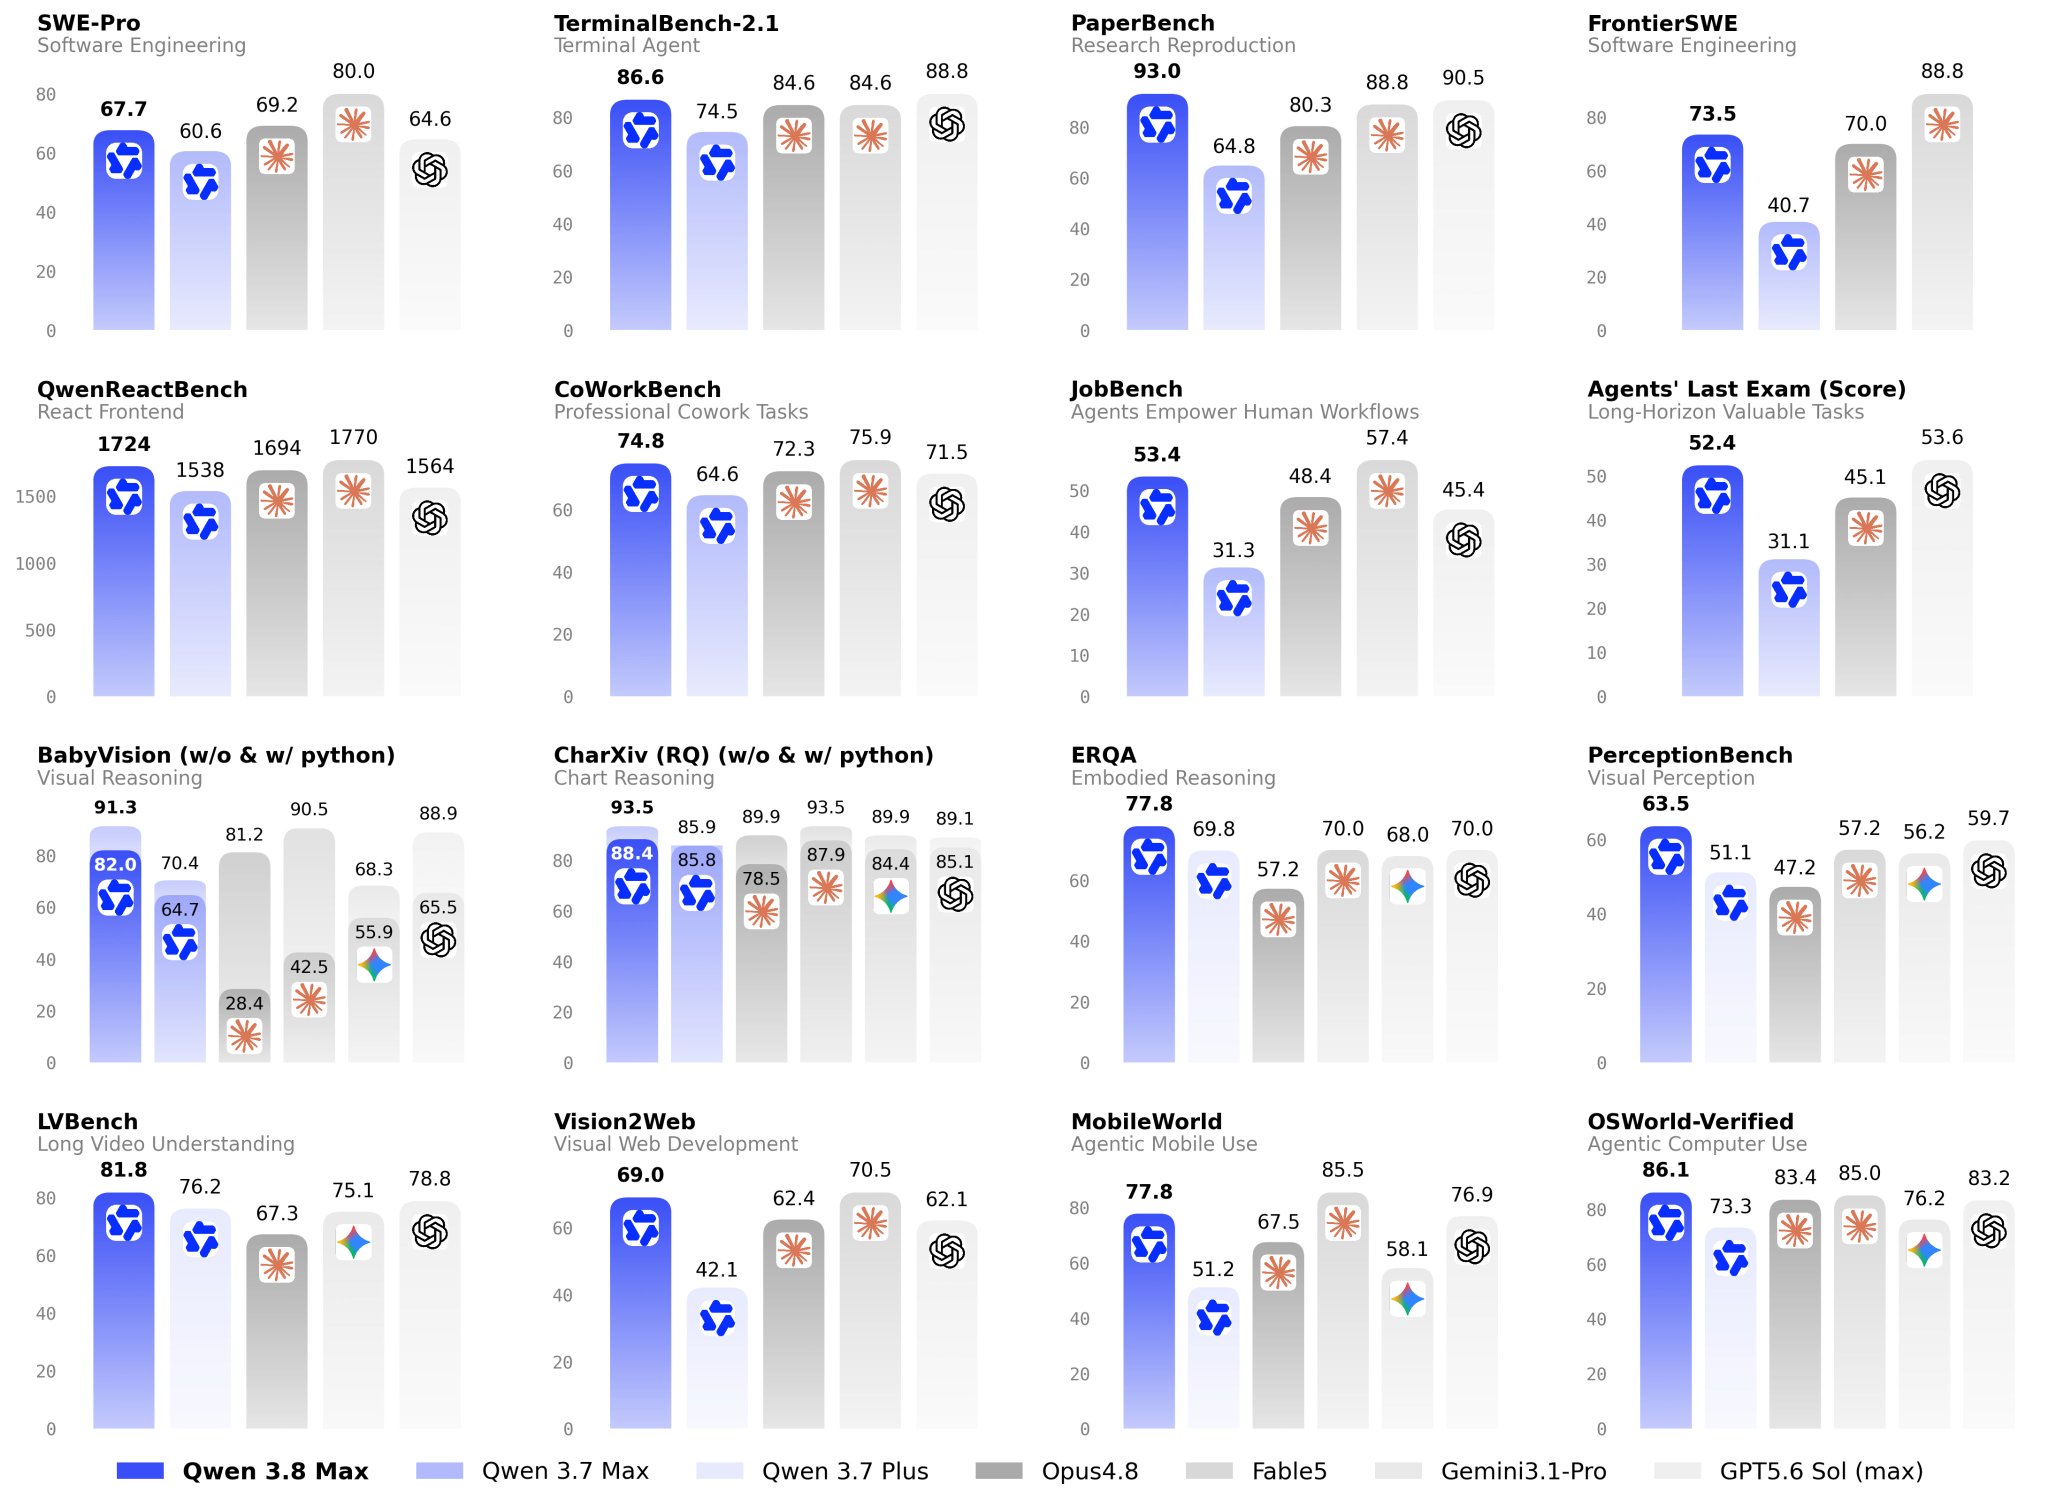
📢Meet Qwen3.8-Max — our most capable model to date. Next week, the open weights of Qwen3.8-Max will be released, and Qwen3.8-27B is also going open-weights to meet you all!🎉Qwen3.8-Max, a new bar for coding and cowork at 2.4T parameters:- Autonomous coding: 10+ days of… pic.twitter.com/e3YFj2hqcT— Qwen (@Alibaba_Qwen) August 3, 2026
The Matter Compiler™ — Atomic Machines
A new universe of machines. Explore the Matter Compiler and a radically faster way to create.
vincent on Twitter / X
Session management is working and now it will keep the model in memory instead of constantly loading. Now to fix the hardest part, gibberish issue.ALMOST THERE ~80% DONE 🔨🔨🔨Demo: @UnslothAI Llama 3.2 1B on CPU3.6 tokens/sec to about 4.1 tokens/sec (gibberish) pic.twitter.com/1tp8dXQrLo— vincent (@t0kenl1mit) August 5, 2025

