The paper shows real LLM query energy is lower than popular claims, and maps concrete ways to shrink it.A normal frontier model query uses about 0.34 Wh in real deployments.Many public numbers are 4x to 20x too high because of tiny tests and unclear scopes.They estimate… pic.twitter.com/FiGFt0bTiH— Rohan Paul (@rohanpaul_ai) September 26, 2025
Sebastian Raschka on Twitter / X
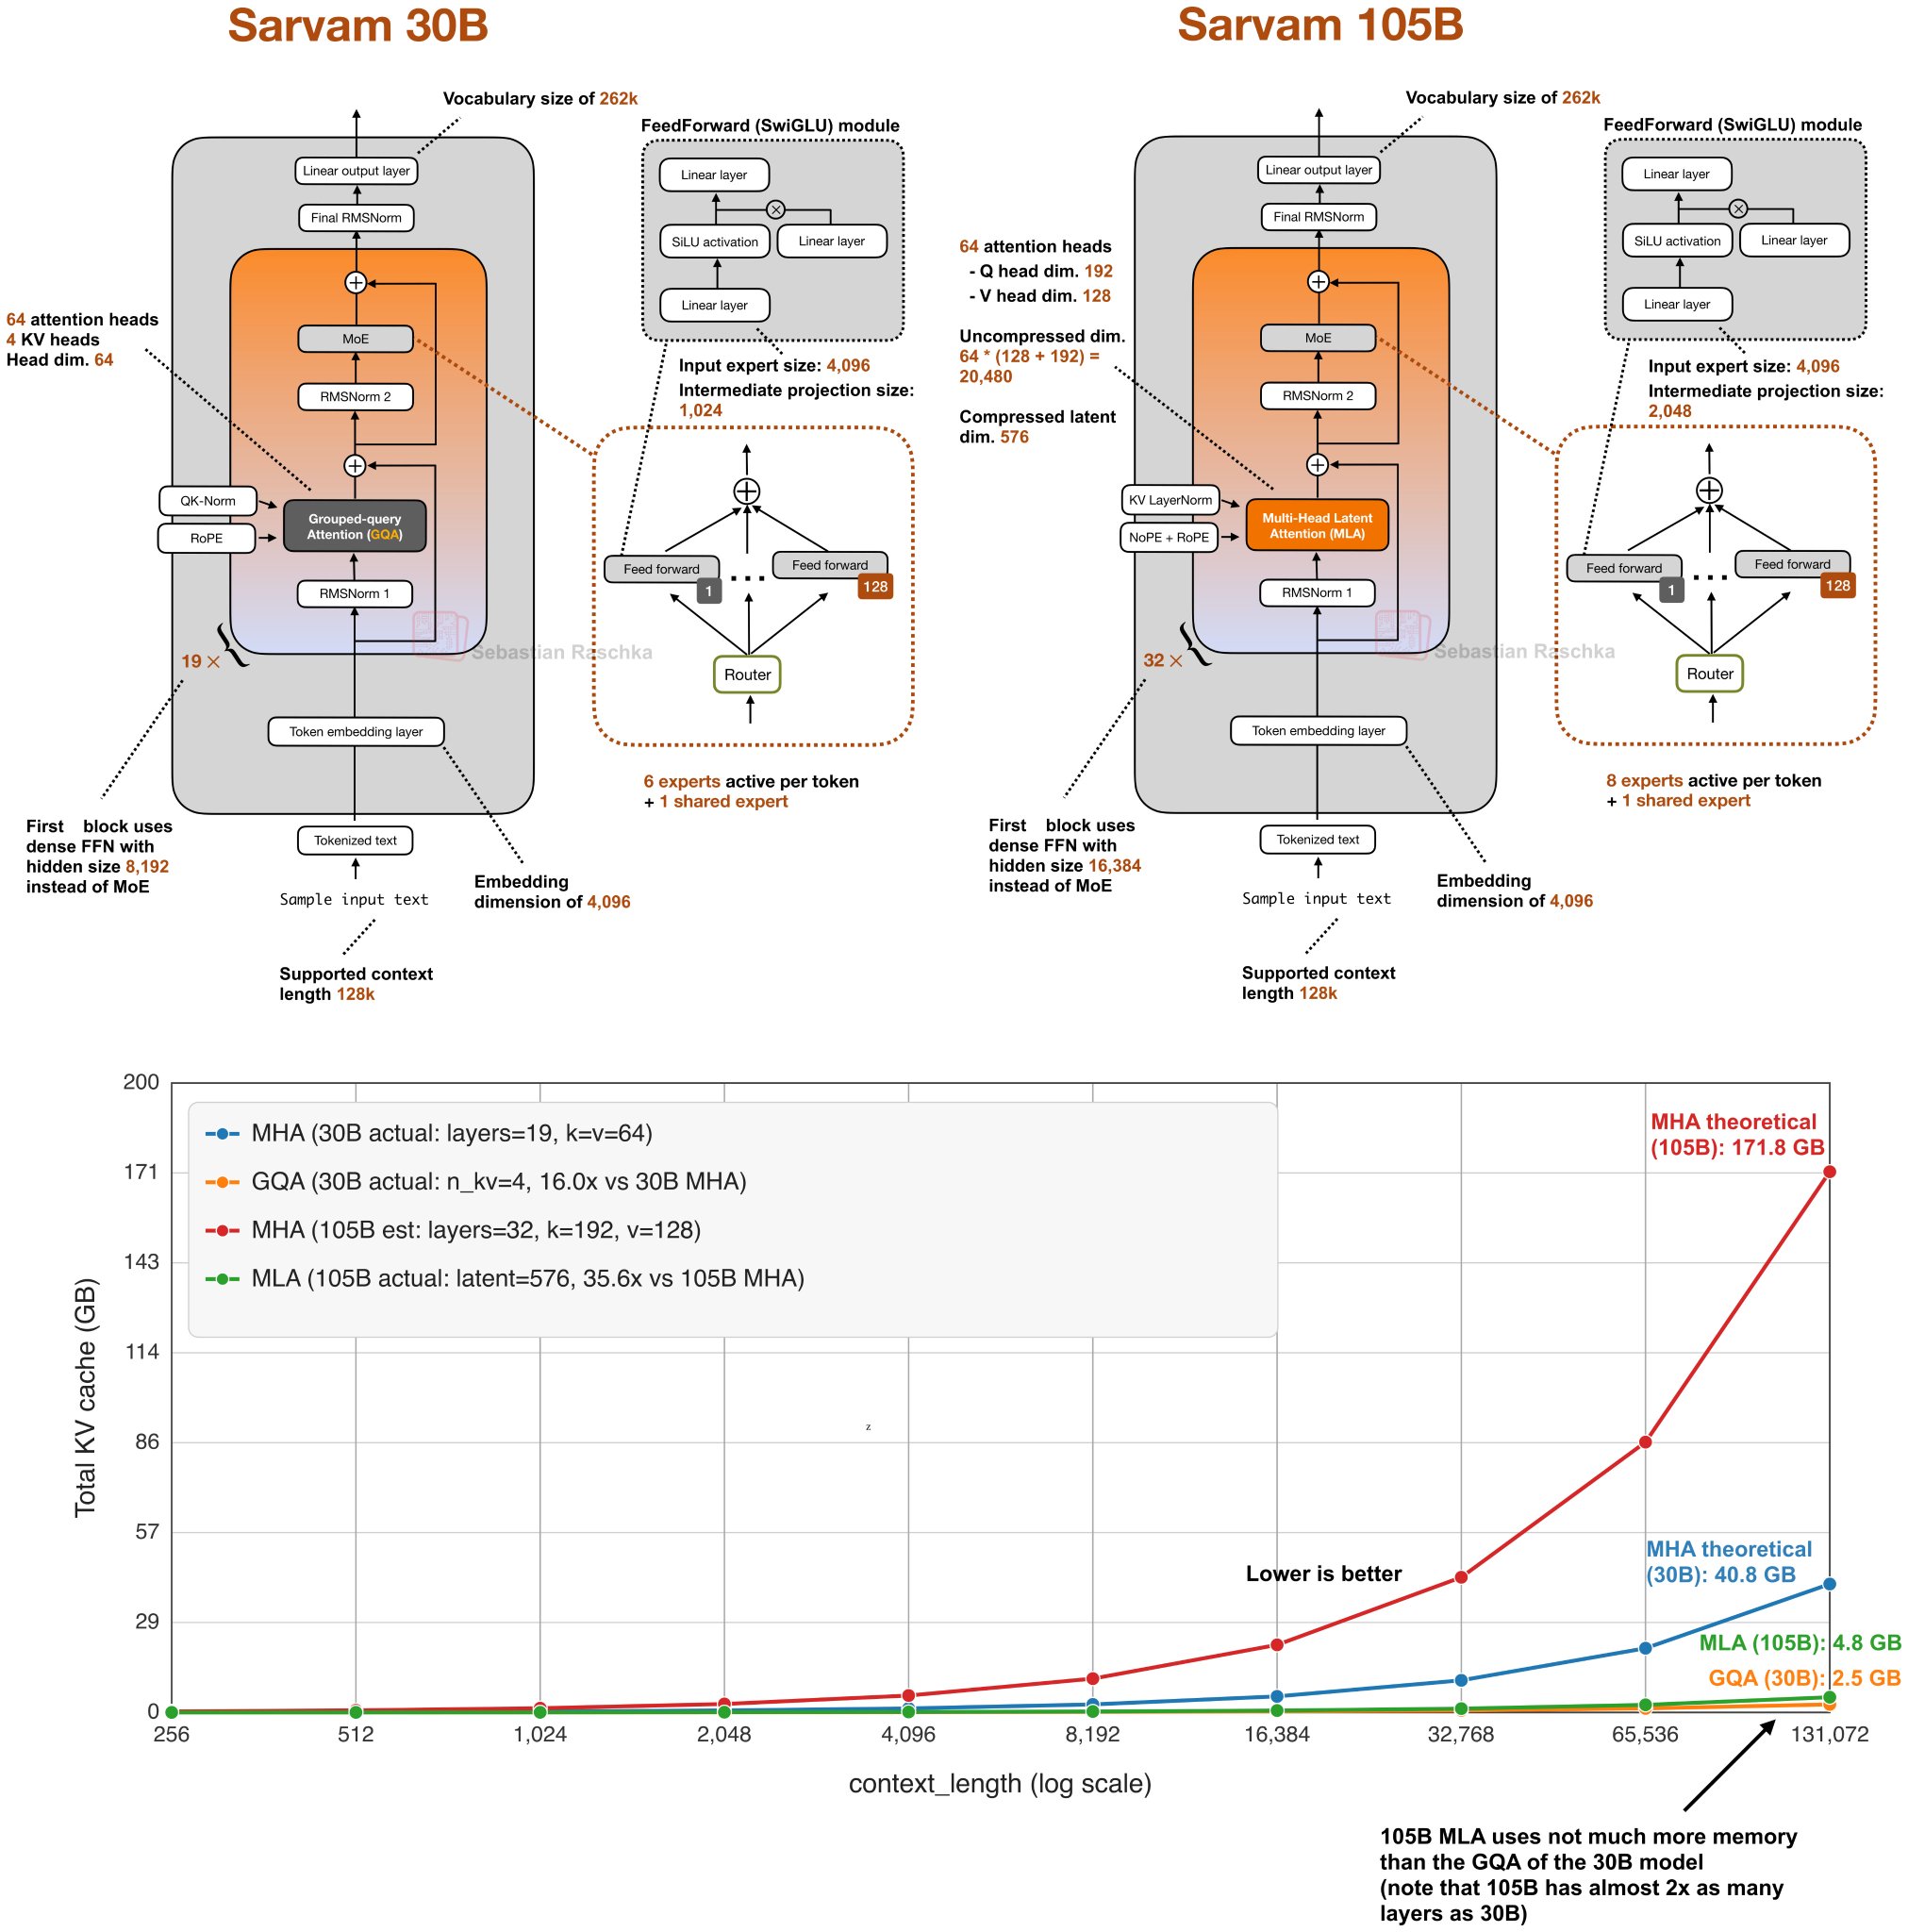
While waiting for DeepSeek V4 we got two very strong open-weight LLMs from India yesterday.There are two size flavors, Sarvam 30B and Sarvam 105B model (both reasoning models).Interestingly, the smaller 30B model uses “classic” Grouped Query Attention (GQA), whereas the… https://t.co/OiJVkDCYNz pic.twitter.com/0uqmLxofRE— Sebastian Raschka (@rasbt) March 7, 2026
Public LLM exceeds superforecaster on Forecast bench by EOY 2026?
41% chance. Resolves to YES if any LLM released in 2026 exceeds the superforecaster baseline on ForecastBench by July 2027. Resolves to NO if this does not happen, or if after January 1, 2027 we have results from enough LLMs (e.g. the leading models from the major AI labs at the time) to be confident this will not occur. If The Forecasting Research Institute tells us how this market should resolve, then we will go with what they say.

Andrew Ho on Twitter / X
Not really observations that others before me haven’t made, but:- Despite the seemingly magical nature of LLMs, reflection over a >3 month timescale suggests my total productivity hasn’t increased by over 100%, or perhaps even by over 50%, and a lot of time is actually wasted…— Andrew Ho (@andrewho03) September 3, 2026
Research – Inception
We are leveraging diffusion technology to develop a new generation of LLMs. Our dLLMs are much faster and more efficient than traditional autoregressive LLMs.
Introducing Mercury 2.5 – Inception
Mercury 2.5 is the most capable diffusion LLM on the market. It runs at 1,107 tokens/sec and offers a 40% increase in intelligence over Mercury 2, comparable to cost-optimized frontier models.

Alex Cheema on Twitter / X
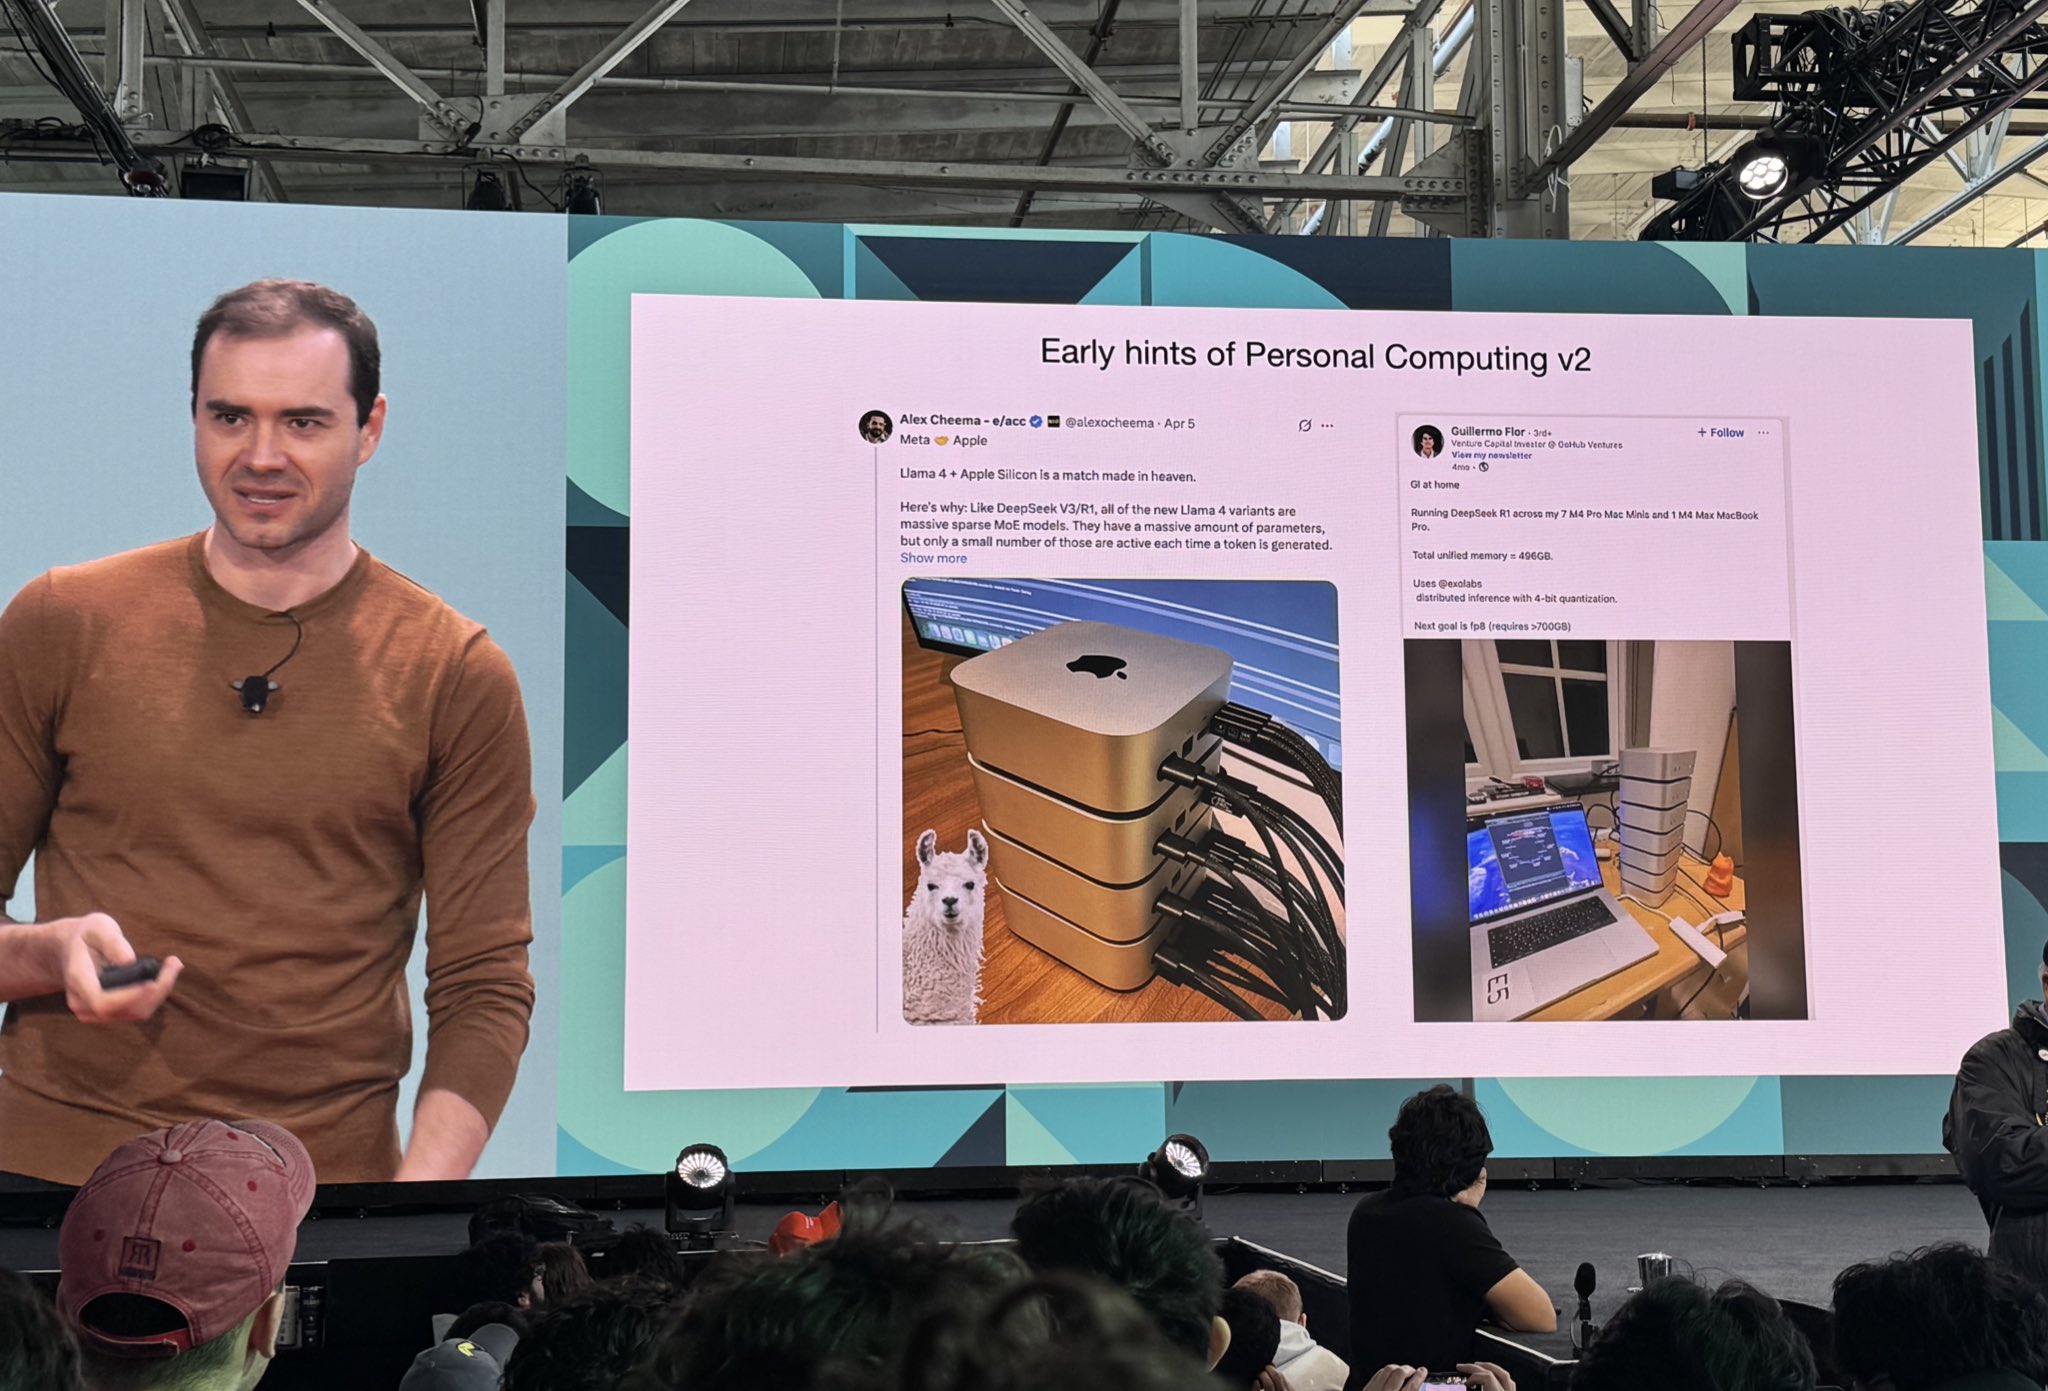
.@karpathy shouted out my work on @exolabs at @ycombinator AI SUS!“we use LLMs similarly to mainframes in the ‘70s - compute is timeshared by having a slice in the batch dimension. models will compress over time, and with this we’ll be able to run more on-device” pic.twitter.com/UKSrquQGAL— Alex Cheema (@alexocheema) June 18, 2025
Dan Shipper 📧 on Twitter / X
this is true and is a big reason why you don’t need to be a highly technical researcher to use LLMs in surprising and novel ways https://t.co/TuxNzXzToU— Dan Shipper 📧 (@danshipper) July 27, 2025
State of AI 2025: 100T Token LLM Usage Study | OpenRouter
Read OpenRouter's 2025 State of AI report — an empirical 100 trillion token study of real LLM usage, model trends, and developer insights.
alphaXiv on Twitter / X
"Small-Scale Experiments: Are We There Yet?"Scaling laws show up even in tiny 4M parameter models, but only when their hyperparameters are tuned well enough.This Meta paper found that small models are much more hyperparameter-sensitive. As scale increases, the hyperparameter… pic.twitter.com/vQfFS1TpMA— alphaXiv (@askalphaxiv) August 15, 2026

Benchmarks | EXO
Transparent benchmarks for LLMs tested on real hardware. Coming soon.
What sort of maths are LLMs good at?
For the sake of anyone who might read this blog post in the distant future (a month from now, say), let me mention that I am writing it a few days after OpenAI announced that it had solved ten majo…

A startup claims it broke through a bottleneck that’s holding back LLMs
Subquadratic has now shared more details about its new model. But some are still skeptical.

ModelScope on Twitter / X
🤯 400 Token/S on a MacBook? Yes, you read that right!Shaohong Chen just fine-tuned the Qwen3-0.6B LLM in under 2 minutes using Apple's MLX framework. This is how you turn your MacBook into a serious LLM development rig. A step-by-step guide and performance metrics inside! 🧵… pic.twitter.com/31Cmycy8Mh— ModelScope (@ModelScope2022) October 13, 2025