

Nihar Shah did a heroic experiment for TMLR: he spent 20-25 hours over two weeks interviewing authors of seemingly low-quality submissions about their own papers. He confirmed what we all suspected: people submitting these papers have *no idea* what is going on in them. https://t.co/6CJF152u7I— Gautam Kamath (@thegautamkamath) September 16, 2026
Thomas G. Dietterich on Twitter / X
We are seeing a new trend in submissions to @arxiv (and presumably to conferences and journals): Authors submitting papers whose contents they likely do not understand. 1/— Thomas G. Dietterich (@tdietterich) September 13, 2026
Mikel Artetxe on Twitter / X
3/4 papers I reviewed and 2/3 reviews I got this ARR cycle were AI slop. Fraudsters are already outnumbering honest researchers. Unless drastic measures are urgently adopted, conference publications will have zero value or even become negative signal, and academia will be toast.— Mikel Artetxe (@artetxem) September 19, 2026
Vipul Gupta on Twitter / X
Feels bad to say, but paper writing/reviewing is definitely cooked.Reviewed 4 papers recently and genuinely felt like I spent more time reviewing them than the authors spent writing them.— Vipul Gupta (@vipul_1011) September 19, 2026
Eric Topol on Twitter / X
This is a FRAUDULENT paper, AI-generated. My name was used as an author and I had nothing to do with it, never saw it until today https://t.co/Ky60zJrMEZThe "Editors" Angelo Rossi Mori, David Mensah, and Zarnie Khadjesari should be reported. pic.twitter.com/2Z5CE8w4bn— Eric Topol (@EricTopol) April 22, 2026

Itai Yanai on Twitter / X
Is the scientific paper a fraud? Peter Medawar (Nobel Prize winner) suggested that publications are overly structured and formal, giving only a sanitized version of the discovery without revealing the thought process that actually led to it. pic.twitter.com/E3ttRPzcfL— Itai Yanai (@ItaiYanai) October 27, 2024

Maksym Andriushchenko on Twitter / X
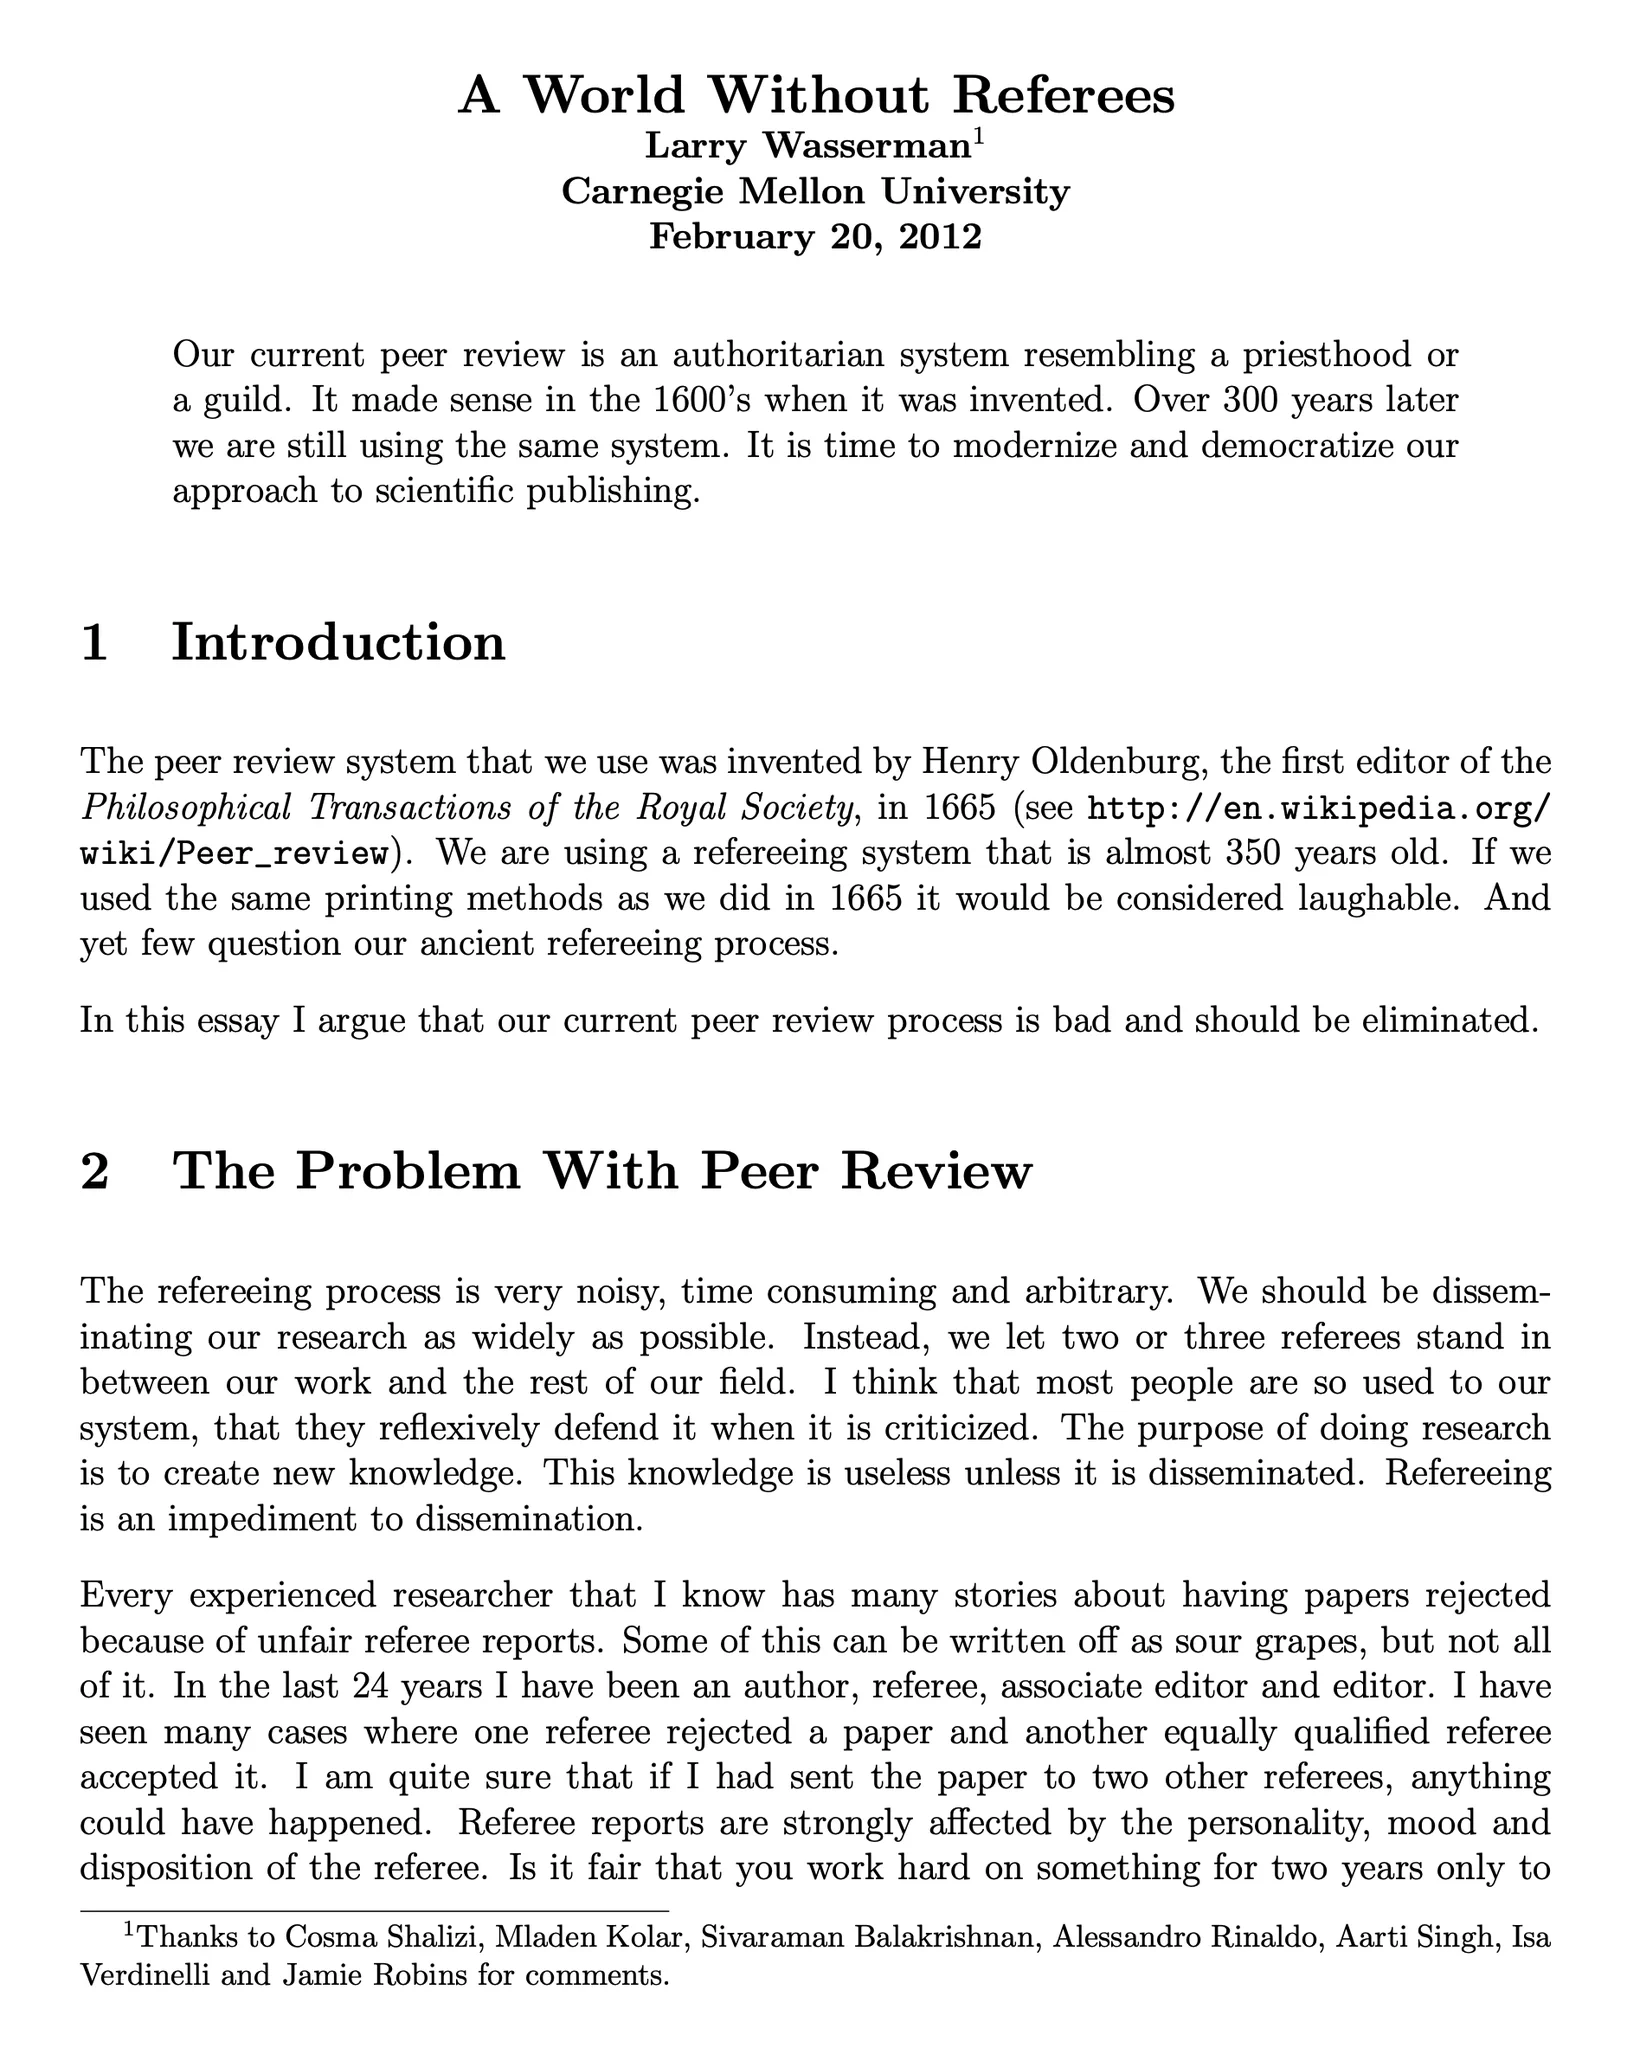
many people seem to be upset by >50k submissions to ICLR. i think we should celebrate it! more people are doing AI (including AI safety) research - isn't it amazing?as for how to navigate the growing amount of papers, luckily, Larry Wasserman formulated a solution back in 2012! pic.twitter.com/U85FGshTqw— Maksym Andriushchenko (@maksym_andr) September 20, 2026
Cas (Stephen Casper) on Twitter / X
It is hard to overstate how disappointing I think this new paper from Oxford, OpenAI, Anthropic, and Google (et al) is. I can't take it seriously as academic work, just as propaganda. It also has some very bad scholarship and questionable adherence to research ethics. Having… pic.twitter.com/Z5fBx360ya— Cas (Stephen Casper) (@StephenLCasper) May 13, 2026
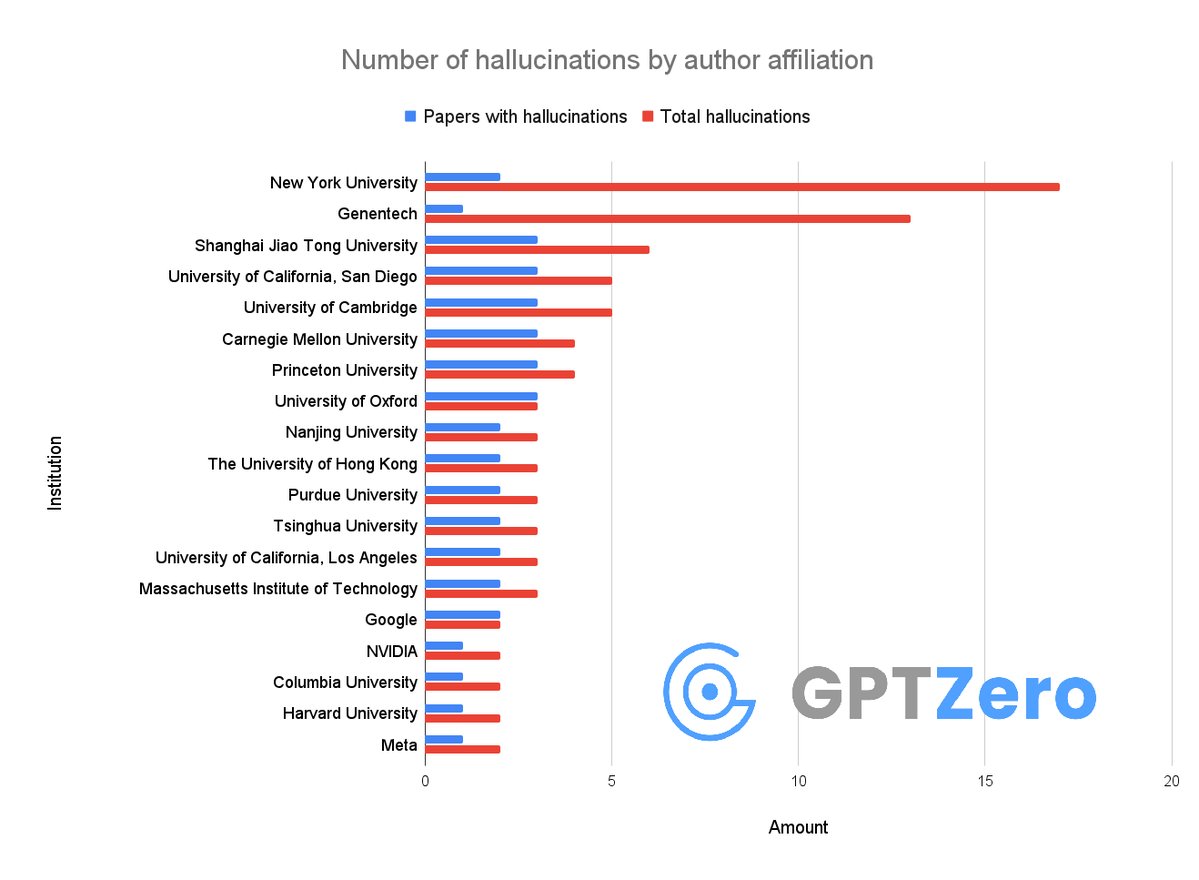
Okay so, we just found that over 50 papers published at @Neurips 2025 have AI hallucinations by @alexcdot(Alex Cui) | Twitter Thread Reader
Okay so, we just found that over 50 papers published at @Neurips 2025 have AI hallucinations I don't think people realize how bad the slop is right now It's not just that researchers from @GoogleDeepMind, @Meta, @MIT, @Cambridge_Uni are using AI - they allowed LLMs to generate hallucinations in their papers and didn't notice at all. It's insane that these made it through peer review👇
Shreya Shankar on Twitter / X
This problem has gotten significantly worse. As Twitter and other social media have become primary channels for sharing research, academics are now expected to make the same ideas legible and appealing to both the general public (to go "viral") and senior scholars (to get the… https://t.co/zPF3tKzbVa— Shreya Shankar (@sh_reya) July 25, 2026
Q&A from the slop trenches – GeoSpatial ML
We reviewed 22 ML conference submissions this summer. Fifteen had fabricated citations, hallucinated authors, or clear LLM slop, so we complain about that a bit, and release the paper references audit we now run.
Ravid Shwartz Ziv on Twitter / X
The problem with Anthropic's consciousness paperMy last post got more attention than I expected, and the question I keep getting is some version of "okay, so what is actually wrong with the paper?". Let me try to explain.First, the core result is fine. Reading out…— Ravid Shwartz Ziv (@ziv_ravid) July 7, 2026
klöss on Twitter / X
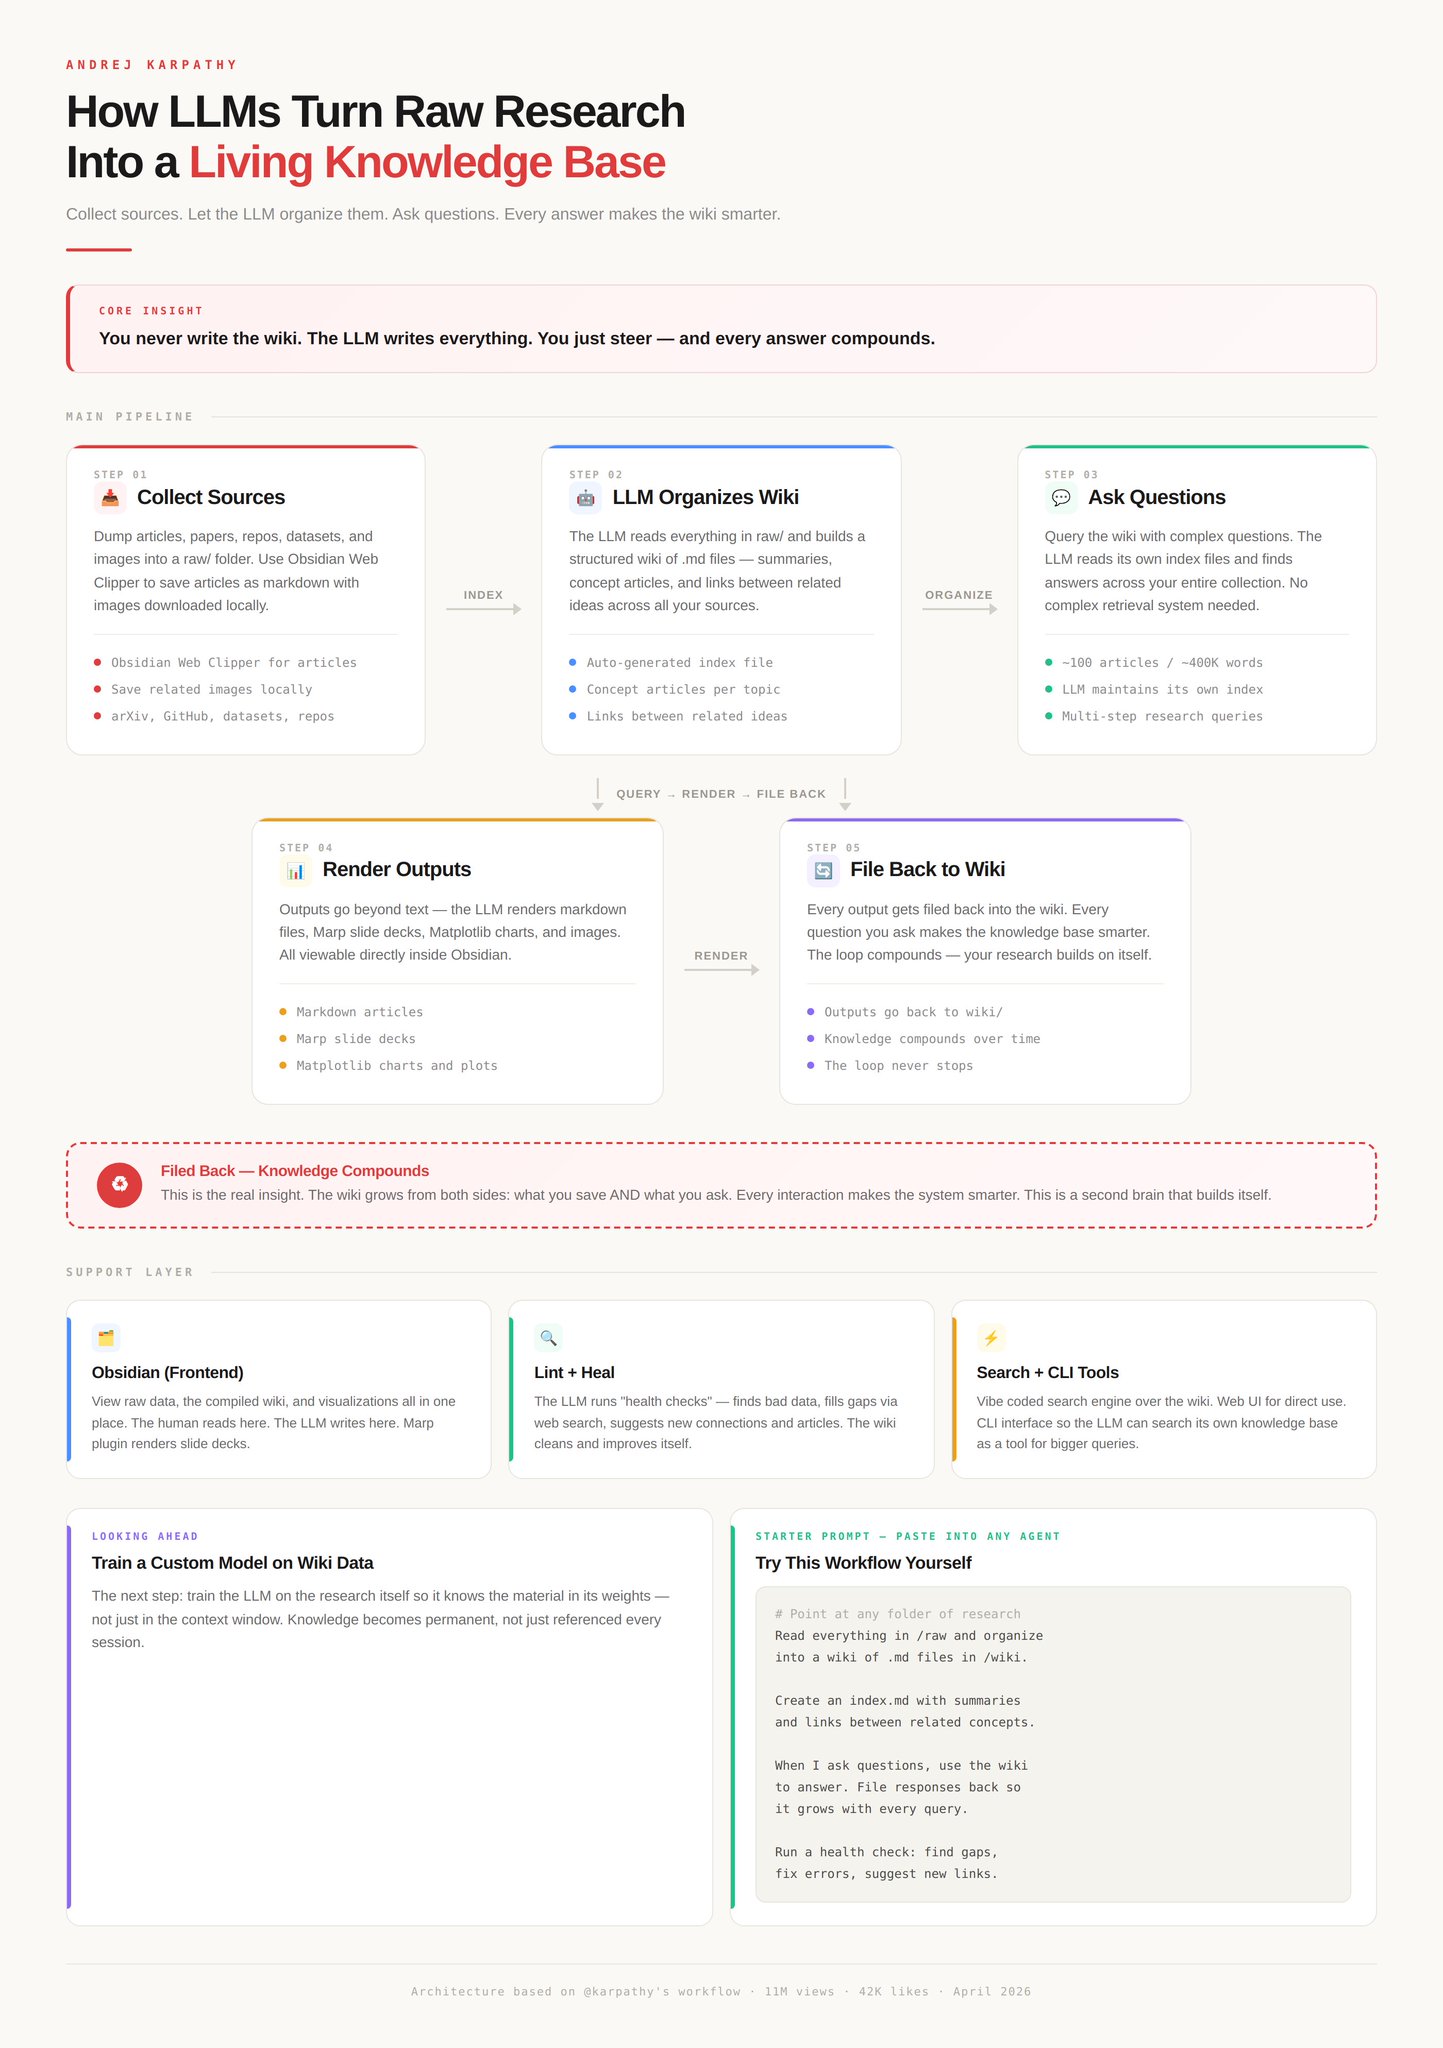
let me explain what Karpathy just sharedhe’s spending way less time using AI to write code and more time using it to build personal knowledge basesthe full breakdown: → he dumps raw sources (articles, papers, repos, datasets, images) into a folder. then has an LLM organize… https://t.co/Kdq1Q48S5P pic.twitter.com/XajJKR7xgT— klöss (@kloss_xyz) April 4, 2026
This is a FRAUDULENT paper, AI-generated. My name was used as an author and I had nothing to do with it, never saw it until today e-pubmed.co.uk/journals/digital-health-imple… The "Editors" Angelo Rossi Mori, David Mensah, and Zarnie Khadjesari and this "Journal" should be reported.
This is a FRAUDULENT paper, AI-generated. My name was used as an author and I had nothing to do with it, never saw it until today e-pubmed.co.uk/journals/digital-health-imple… The "Editors" Angelo Rossi Mori, David Mensah, and Zarnie Khadjesari and this "Journal" should be reported.
Nihar Shah did a heroic experiment for TMLR: he spent 20-25 hours over two weeks interviewing authors of seemingly low-quality submissions about their own papers. He confirmed what we all suspected: people submitting these papers have *no idea* what is going on in them.

Transactions on Machine Learning Research
TMLR has faced a deluge of submissions, necessitating stricter desk rejection policies due to limited reviewer capacity Co-EiC Nihar Shah reached out to authors of 10 papers slated for desk reject. Could they answer questions about their *own* submission? medium.com/@TmlrOrg/asking-authors-about…

