

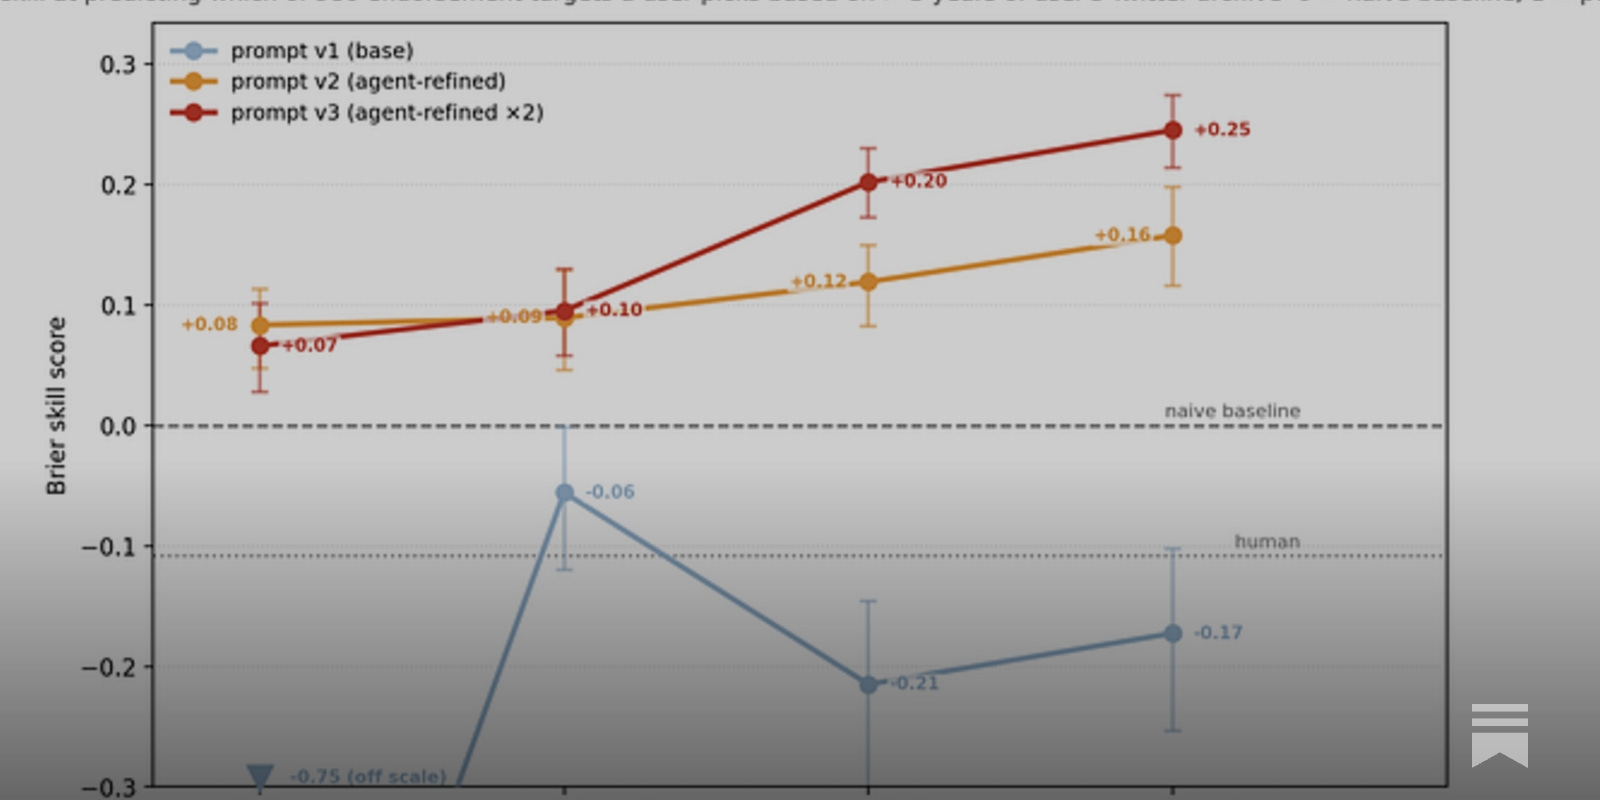
We built a forecasting benchmark to test how well agents predict what you like.
TasteVal: Measuring the Experimental Research Taste of AI Systems Against Human Experts
We introduce TasteVal, a benchmark to evaluate the experimental research taste of frontier models. We define research taste as the ability to pick interesting problems to solve, design experiments, and interpret experimental results. TasteVal measures the experimental component of research taste; given a fixed research problem, we measure how well a model iteratively designs experiments and draws conclusions from their outcomes. We operationalize experimental research taste as compute efficiency; a Researcher who reaches the same score as an expert human using half the serial experimental compute has twice the experimental taste. Experimental taste thus acts as a multiplier on experimental compute, making it a key input to forecasts of AI progress. TasteVal consists of 8 novel, challenging, open-ended tasks representative of frontier AI R&D. To isolate taste from coding ability, the model under evaluation acts as a Researcher that iteratively designs experiments while a fixed Coder agent implements them and reports their results. The Researcher executes until either the 40 H100 hour or 120 wall-clock hour budgets are exhausted. We recruit 24 human experts, at least 2 per task, and take the best expert attempt per task as the expert baseline. We evaluate 20 models released between 2023 and 2026. The best-performing model, Opus 5.5, exceeds our expert baseline, with a compute multiplier of 2.3x (95% CI 1.15-4.37), at roughly 1/30 of our baseliners' average per-run cost. On TasteVal, the compute multiplier of frontier models has doubled approximately every 3.0 months since December 2025 (95% CI 1.7-5.0), up from every 14 months between 2023 and December 2025. Measured by final normalized performance, frontier models show no trend break, doubling every 14.6 months. To keep TasteVal uncontaminated, we do not release the tasks.

Leonxlnx/taste-skill
Taste-Skill - gives your AI good taste. stops the AI from generating boring, generic slop
AI Simulation Platform for Human Behavior | Simile
Simulate how real customers respond to a launch, price change, or campaign — before you ship. Built by the Stanford researchers behind generative agents.
A Framework for Studying AI Agent Behavior: Evidence from Consumer Choice Experiments
Environments built for people are increasingly operated by a new class of economic actors: LLM-powered software agents making decisions on our behalf. These decisions range from our purchases to travel plans to medical treatment selection. Current evaluations of these agents largely focus on task competence, but we argue for a deeper assessment: how these agents choose when faced with realistic decisions. We introduce ABxLab, a framework for systematically probing agentic choice through controlled manipulations of option attributes and persuasive cues. We apply this to a realistic web-based shopping environment, where we vary prices, ratings, and psychological nudges, all of which are factors long known to shape human choice. We find that agent decisions shift predictably and substantially in response, revealing that agents are strongly biased choosers even without being subject to the cognitive constraints that shape human biases. This susceptibility reveals both risk and opportunity: risk, because agentic consumers may inherit and amplify human biases; opportunity, because consumer choice provides a powerful testbed for a behavioral science of AI agents, just as it has for the study of human behavior. We release our framework as an open benchmark for rigorous, scalable evaluation of agent decision-making.
Agent Recipes
Explore common agent recipes with ready to copy code to improve your LLM applications.

Agentic Forecasting using Sequential Bayesian Updating of Linguistic Beliefs
LLM forecasting exhibits high variance across runs. We run K=5K{=}5 independent trials and aggregate by averaging in logit space. We also explore LOO-tuned shrinkage toward p=0.5p{=}0.5 (inspired by James-Stein / empirical Bayes), which further helps on datasets with high trial variance.
Agents First
Every product is getting a second customer — the human who pays, and the agent who decides. A design framework for building products that AI agents can use as primary consumers.
Agentic test processes, LLM benchmarks, and other notes on agentic coding from Galapagos Island
I've been using AI fairly heavily since last November and the whole thing is a funny experience. An agent will do something that, if a human did it, you'd immediately fire them. My reaction, of course, is to act as if this is great and spin up a thousand agents so they can do even more of that.
Gallup Begins Research on Simulated Responses
Gallup is exploring whether AI-generated agents perform well in predicting people's responses and where they fall short.
On Taste, Effort & Curiosity - again
When AI collapses how long it takes to ship, what’s left is judgment, experimentation, and knowing what not to build.
CEO-Bench: Can Agents Play the Long Game?
Language model agents are becoming proficient executors at isolated, short-horizon tasks such as software engineering and customer service. Yet real-world challenges require a combination of sophisticated skills that remain largely untested in agents: (1) navigating long horizons amid uncertainty; (2) acquiring information in noisy environments; (3) adapting to a changing world; (4) orchestrating multiple moving parts toward a coherent goal. We introduce CEO-Bench, which evaluates these capabilities together by simulating a representative real-world task: operating a startup for 500 days. An agent manages pricing, marketing, budgeting, and many other aspects of a fictional company through a programmable Python interface, operating in the same environment and facing the same challenges as a human CEO. Success demands analyzing noisy, interconnected business databases, translating signals into sound strategy, and coordinating many decisions with programming. The strongest agents write sophisticated code that simulates customer cohorts to forecast future cash and mines negotiation history to uncover hidden customer preferences. Even so, most state-of-the-art models struggle in this environment. Only Claude Opus 4.8 and GPT-5.5 finish above the $1M starting balance, and neither consistently turns a profit. CEO-Bench takes a first step toward measuring the intelligence required to drive sustained, adaptive progress over time.
[Keynote 04] AgentSociety: Exploring Large Language Model Agents for Piloting Social Experiments
🚨Our new research examines agentic shopping: can you consistently predict (or, using marketing, influence) what an agent chooses? Nope. We found that even small differences (viewing order of pages, memories) changed AI preferences in unpredictable ways. papers.ssrn.com/sol3/papers.cfm?abstract_id=7…
