

What and Whose Knowledge? Measuring Epistemic Diversity in Large Language Models
Large language models (LLMs) are increasingly used as primary knowledge sources, yet their epistemic diversity - defined as the diversity of real-world claims in their outputs - has never been measured. Low epistemic diversity would pose a risk of knowledge collapse as homogeneous LLMs mediate a shrinking in the range of accessible information over time. The dominant paradigm is that overall LLM diversity is low, but this is always with respect to a single point in time, with no reference baseline or consideration for variation across countries. We address this gap in knowledge by performing the first systematic study of epistemic diversity in LLMs across time and cultural context, testing 27 LLMs on 155 topics covering 12 countries, resulting in 1.7M responses and 70M individual claims. We find that epistemic diversity has increased substantially over the past three years, a positive counter to recent diversity pessimism. However, despite progress, we find that every system is less diverse than a search baseline. This gap is not uniform: RAG can improve diversity, while large models are counterintuitively less diverse than smaller ones. Moreover, LLM parametric knowledge systematically reflects English over local-language knowledge for country specific topics. Together, these results demonstrate that while progress on epistemic diversity is tangible, it is insufficient and unevenly distributed.

The shrinking landscape of linguistic diversity in the age of large language models
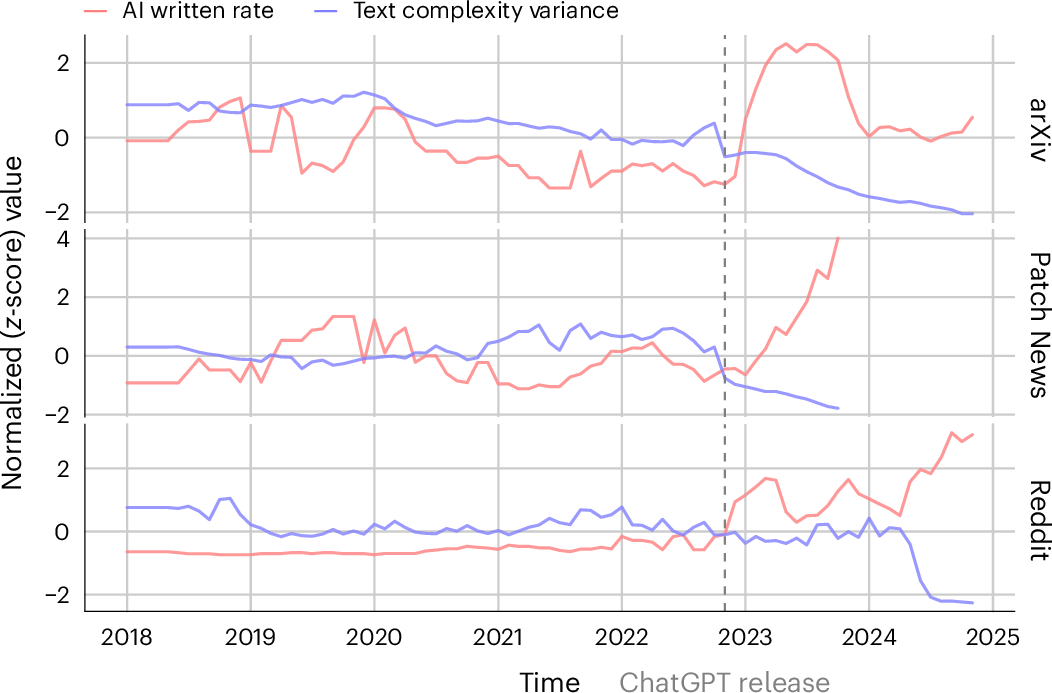
Language is far more than a communication tool; it encodes a wealth of information about a person’s identity, psychological state and social context, providing valuable insights for diverse fields including psychology, marketing and healthcare. Across three studies spanning seven datasets in different domains and over 880,000 texts, we show that the widespread adoption of large language models (LLMs) as writing assistants is linked to declines in linguistic diversity, interfering with the societal and psychological insights language provides. While core content is retained when LLMs polish and rewrite texts, LLMs also homogenize writing styles, reducing writing-complexity variance by a statistically significant 21–50% across datasets and models (P ≤ 0.05), and amplify patterns associated with dominant characteristics while suppressing others, emphasizing conformity over individuality. These trends hold across different LLMs, prompts and contexts, with potential implications for diagnostic processes, personalization efforts, hiring assessments and cultural preservation.
Guide: Inclusive Language and Vocabulary for Startups and Tech
Understanding the vocabulary of diversity & inclusion can feel like learning a new (but very worthwhile!) language. Here's our incomplete but growing guide.
Do LLMs write like humans? Variation in grammatical and rhetorical styles
As large language models (LLMs) have grown in power and become more widely available, research has focused on their ability to complete various tasks and the biases they exhibit when doing so. In this study, we instead examine their writing style in detail. We show that instruction-tuned models, which are trained to answer questions and solve problems, have a distinct noun-heavy, informationally dense writing style, even when prompted to match the style of informal speech and writing. These findings suggest that instruction-tuned models generate text that does not align with genre conventions familiar to human audiences, and demonstrate the value of linguistic variables in evaluating the output of LLMs., Large language models (LLMs) are capable of writing grammatical text that follows instructions, answers questions, and solves problems. As they have advanced, it has become difficult to distinguish their output from human-written text. While past research has found some differences in features such as word choice and punctuation and developed classifiers to detect LLM output, none has studied the rhetorical styles of LLMs. Using several variants of Llama 3 and GPT-4o, we construct two parallel corpora of human- and LLM-written texts from common prompts. Using Douglas Biber’s set of lexical, grammatical, and rhetorical features, we identify systematic differences between LLMs and humans and between different LLMs. These differences persist when moving from smaller models to larger ones and are larger for instruction-tuned models than base models. This observation of differences demonstrates that despite their advanced abilities, LLMs struggle to match human stylistic variation. Attention to more advanced linguistic features can hence detect patterns in their behavior not previously recognized.

Project Fluent
Natural-sounding translations with genders and grammatical cases only when necessary. Expressiveness is not limited by the grammar of the source language.
How linguistics learned to stop worrying and love the language models
Language models (LMs) can produce fluent, grammatical text. Nonetheless, some maintain that language models don’t really learn language and also, even if they did, that would not be informative for the study of human learning and processing. On the other side, there have been claims that the success of LMs obviates the need for studying linguistic theory and structure. We argue that both extremes are wrong. LMs can contribute to fundamental questions about linguistic structure, language processing, and learning. They force us to rethink arguments and ways of thinking that have been foundational in linguistics. While they do not replace linguistic structure and theory, they serve as model systems and working proofs of concept for gradient, usage-based approaches to language. We offer an optimistic take on the relationship between language models and linguistics.
The homogenizing effect of large language models on human expression and thought
AbstractCognitive diversity, reflected in variations of language, perspective, and reasoning, is essential to creativity and collective intelligence. This diversity is rich and grounded in culture, history, and individual experience. Yet, as large language models (LLMs) become deeply embedded in people's lives, they risk standardizing language and reasoning. We synthesize evidence across linguistics, psychology, cognitive science, and computer science to show how LLMs reflect and reinforce dominant styles while marginalizing alternative voices and reasoning strategies. We examine how their design and widespread use contribute to this effect by mirroring patterns in their training data and amplifying convergence as all people increasingly rely on the same models across contexts. Unchecked, this homogenization risks flattening the cognitive landscapes that drive collective intelligence and adaptability.

The homogenizing effect of large language models on human expression and thought
Cognitive diversity, reflected in variations of language, perspective, and reasoning, is essential to creativity and collective intelligence. This diversity is rich and grounded in culture, history, and individual experience. Yet, as large language models (LLMs) become deeply embedded in people’s lives, they risk standardizing language and reasoning. We synthesize evidence across linguistics, psychology, cognitive science, and computer science to show how LLMs reflect and reinforce dominant styles while marginalizing alternative voices and reasoning strategies. We examine how their design and widespread use contribute to this effect by mirroring patterns in their training data and amplifying convergence as all people increasingly rely on the same models across contexts. Unchecked, this homogenization risks flattening the cognitive landscapes that drive collective intelligence and adaptability.
Cross-Lingual Exploration for Parametric Knowledge
Parametric knowledge in Large Language Models is not equally accessible across languages. As a result, standard inference techniques often struggle to surface localized facts, leading to failures in...
Extracting Training Data from Large Language Models
Nicholas Carlini, Google; Florian Tramèr, Stanford University; Eric Wallace, UC Berkeley; Matthew Jagielski, Northeastern University; Ariel Herbert-Voss, OpenAI and Harvard University; Katherine Lee and Adam Roberts, Google; Tom Brown, OpenAI; Dawn Song, UC Berkeley; Úlfar Erlingsson, Apple; Alina Oprea, Northeastern University; Colin Raffel, Google
How I Learned Spanish in 3 Months | Loïs Talagrand
Complete breakdown of my 90-day Spanish challenge: constraints, tools, timeline, and final 30-minute conversation result.
The language of generalization.
to my i18n experts, is there a type out there that I can use in my lexicons? I want to be language friendly, but alas am ignorant!

Common "langs" type?
discourse.atmosphere.communityAnnouncing a new version of our 2024 paper on linguistic hypothesis generation from LMs! @najoung.bsky.social and I have systematized our hypothesis generation framework, added stringent criteria for model selection, 10x-ed our learning trials, and included an epigraph from Jeff Elman 🙏!
This Project explores syntactic diversity found in varieties of English spoken in North America. By documenting the subtle, but systematic, differences in the syntax of English varieties, it provides a crucial source of data for the development of theories of human linguistic knowledge.

