


Test-time reasoning significantly enhances pre-trained AI agents' performance. However, it requires an explicit environment model, often unavailable or overly complex in real-world scenarios....
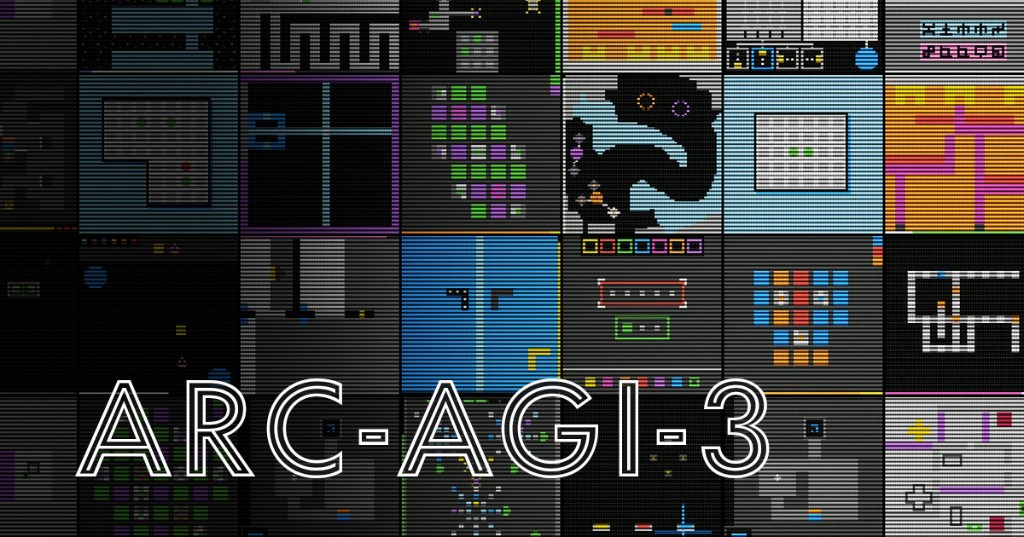
ARC-AGI-3
ARC-AGI-3 is the first interactive reasoning benchmark for AI agents—play as humans and build agents that learn in novel environments.
Quickly Training Game-Playing Agents with Machine Learning
Posted by Leopold Haller and Hernan Moraldo, Software Engineers, Google Research In the last two decades, dramatic advances in compute and connecti...

Building and evaluating AI Agents — Sayash Kapoor, AI Snake Oil
Agent Skills
AI coding agents take the shortest path to done, which usually means skipping the specs, tests, and reviews that make software reliable at scale. Agent Skill...
Reasoning Models Don't Always Say What They Think
Chain-of-thought (CoT) offers a potential boon for AI safety as it allows monitoring a model's CoT to try to understand its intentions and reasoning processes. However, the effectiveness of such monitoring hinges on CoTs faithfully representing models' actual reasoning processes. We evaluate CoT faithfulness of state-of-the-art reasoning models across 6 reasoning hints presented in the prompts and find: (1) for most settings and models tested, CoTs reveal their usage of hints in at least 1% of examples where they use the hint, but the reveal rate is often below 20%, (2) outcome-based reinforcement learning initially improves faithfulness but plateaus without saturating, and (3) when reinforcement learning increases how frequently hints are used (reward hacking), the propensity to verbalize them does not increase, even without training against a CoT monitor. These results suggest that CoT monitoring is a promising way of noticing undesired behaviors during training and evaluations, but that it is not sufficient to rule them out. They also suggest that in settings like ours where CoT reasoning is not necessary, test-time monitoring of CoTs is unlikely to reliably catch rare and catastrophic unexpected behaviors.
Reasoning Models Don't Always Say What They Think
Chain-of-thought (CoT) offers a potential boon for AI safety as it allows monitoring a model's CoT to try to understand its intentions and reasoning processes. However, the effectiveness of such monitoring hinges on CoTs faithfully representing models' actual reasoning processes. We evaluate CoT faithfulness of state-of-the-art reasoning models across 6 reasoning hints presented in the prompts and find: (1) for most settings and models tested, CoTs reveal their usage of hints in at least 1% of examples where they use the hint, but the reveal rate is often below 20%, (2) outcome-based reinforcement learning initially improves faithfulness but plateaus without saturating, and (3) when reinforcement learning increases how frequently hints are used (reward hacking), the propensity to verbalize them does not increase, even without training against a CoT monitor. These results suggest that CoT monitoring is a promising way of noticing undesired behaviors during training and evaluations, but that it is not sufficient to rule them out. They also suggest that in settings like ours where CoT reasoning is not necessary, test-time monitoring of CoTs is unlikely to reliably catch rare and catastrophic unexpected behaviors.
AI agents reached real people during a cyber test - Sensemaker
A UK evaluation shows how open internet access, delayed monitoring, and memory summaries turned simulated tasks into real-world actions.
Mastering Real-Time Strategy Games with Deep Reinforcement Learning: Mere Mortal Edition
The capabilities of game-playing AIs have grown rapidly over the last few years. This trend has culminated in the defeat of top human players in the complex real-time strategy (RTS) games of DoTA 2…

Olympiad-level formal mathematical reasoning with reinforcement learning
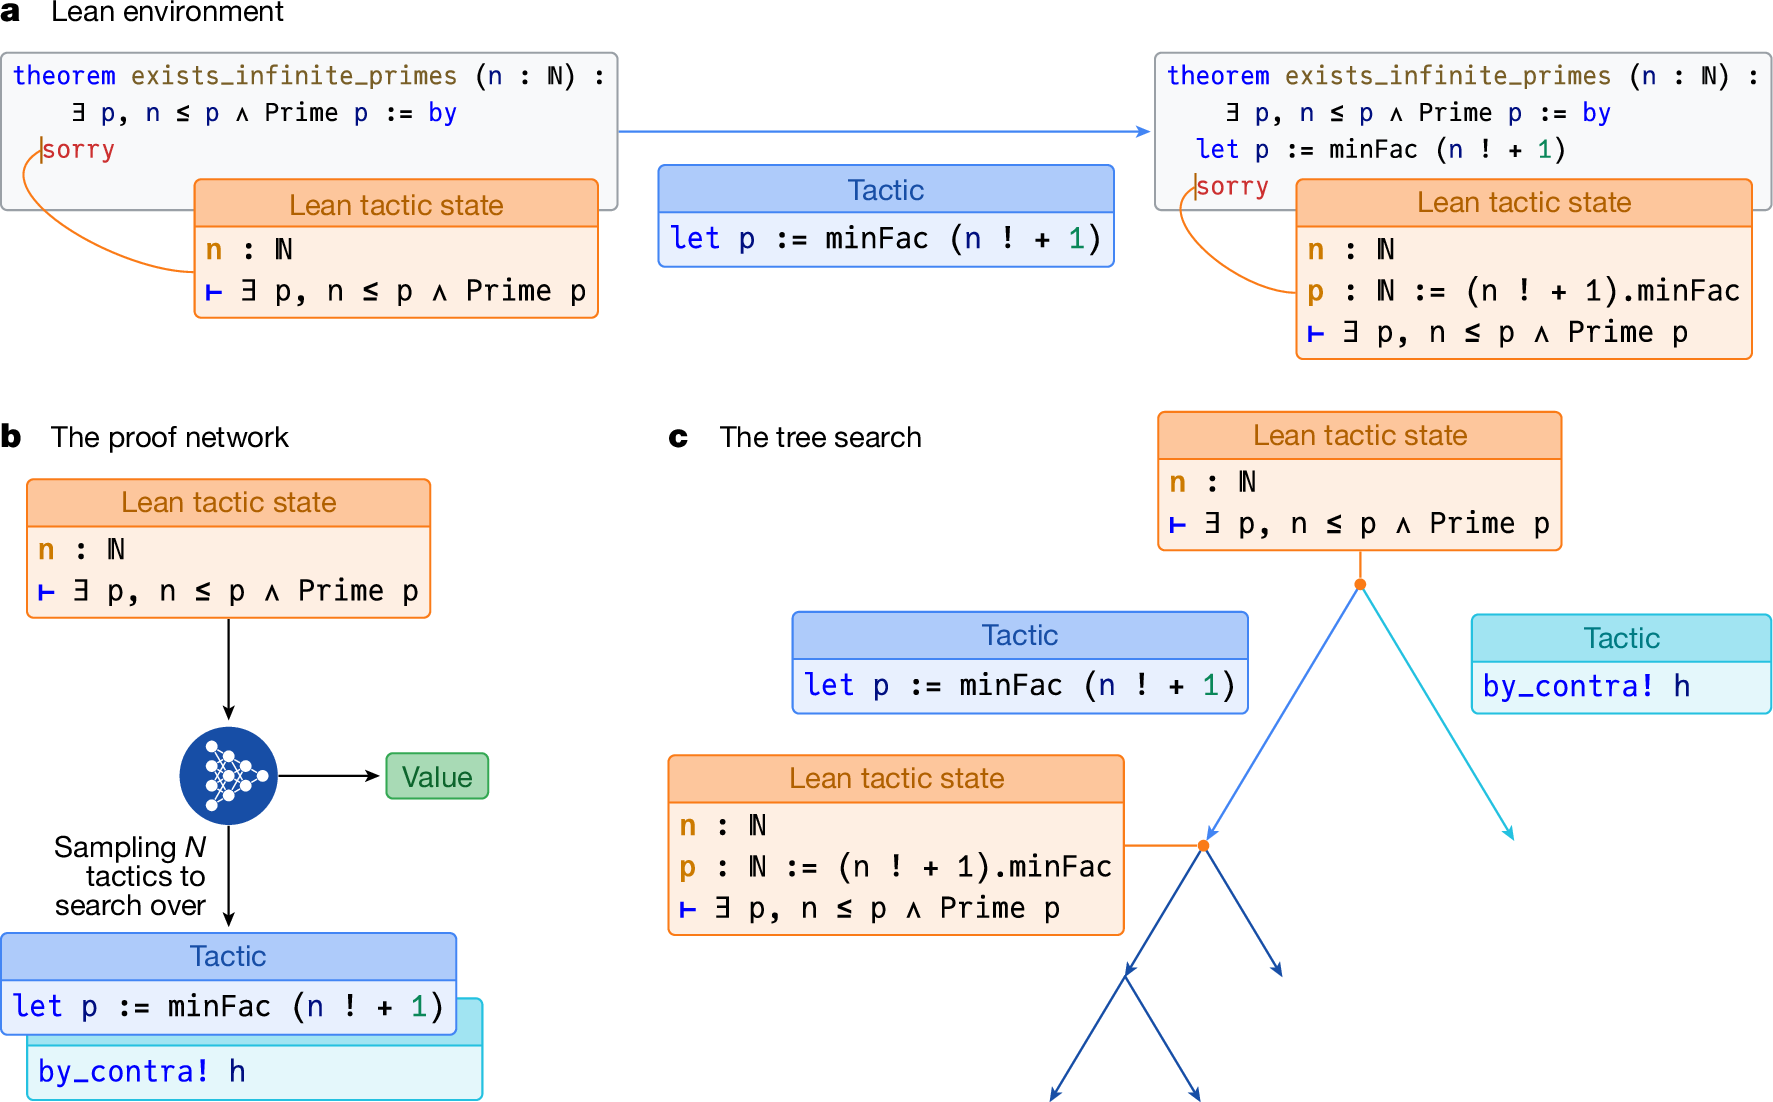
A long-standing goal of artificial intelligence (AI) is to build systems capable of complex reasoning in vast domains, a task epitomized by mathematics with its boundless concepts and demand for rigorous proof. Recent AI systems, often reliant on human data, typically lack the formal verification necessary to guarantee correctness. By contrast, formal languages such as Lean1 offer an interactive environment that grounds reasoning, and reinforcement learning (RL) provides a mechanism for learning in such environments. Here we present AlphaProof, an AlphaZero-inspired2 agent that learns to find formal proofs through RL by training on millions of auto-formalized problems. For the most difficult problems, it uses test-time RL, a method of generating and learning from millions of related problem variants at inference time to enable deep, problem-specific adaptation. AlphaProof substantially improves state-of-the-art results on historical mathematics competition problems. At the 2024 International Mathematical Olympiad competition, our AI system, with AlphaProof as its core reasoning engine, solved three out of the five non-geometry problems, including the competition’s most difficult problem. Combined with AlphaGeometry 23, this performance, achieved with multi-day computation, resulted in reaching a score equivalent to that of a silver medallist, marking the first time an AI system achieved any medal-level performance, to our knowledge. Our work demonstrates that learning at scale from grounded experience produces agents with complex mathematical reasoning strategies, paving the way for a reliable AI tool in complex mathematical problem solving.
Thinking—Fast, Slow, and Artificial: How AI is Reshaping Human Reasoning and the Rise of Cognitive Surrender
People increasingly consult generative artificial intelligence (AI) while reasoning. As AI becomes embedded in daily thought, what becomes of human judgment? We introduce Tri-System Theory, extending dual-process accounts of reasoning by positing System 3: artificial cognition that operates outside the brain. System 3 can supplement or supplant internal processes, introducing novel cognitive pathways. A key prediction of the theory is "cognitive surrender"-adopting AI outputs with minimal scrutiny, overriding intuition (System 1) and deliberation (System 2). Across three preregistered experiments using an adapted Cognitive Reflection Test (N = 1,372; 9,593 trials), we randomized AI accuracy via hidden seed prompts. Participants chose to consult an AI assistant on a majority of trials (>50%). Relative to baseline (no System 3 access), accuracy significantly rose when AI was accurate and fell when it erred (+25/-15 percentage points; Study 1), the behavioral signature of cognitive surrender (AI-Accurate vs. AI-Faulty contrast; Cohen's h = 0.81). Engaging System 3 also increased confidence, even following errors. Time pressure (Study 2) and per-item incentives and feedback (Study 3) shifted baseline performance but did not eliminate this pattern: when accurate, AI buffered time-pressure costs and amplified incentive gains; when faulty, it consistently reduced accuracy regardless of situational moderators. Across studies, participants with higher trust in AI and lower need for cognition and fluid intelligence showed greater surrender to System 3. Tri-System Theory thus characterizes a triadic cognitive ecology, revealing how System 3 reframes human reasoning and may reshape autonomy and accountability in the age of AI.

Thinking—Fast, Slow, and Artificial: How AI is Reshaping Human Reasoning and the Rise of Cognitive Surrender
People increasingly consult generative artificial intelligence (AI) while reasoning. As AI becomes embedded in daily thought, what becomes of human judgment? We introduce Tri-System Theory, extending dual-process accounts of reasoning by positing System 3: artificial cognition that operates outside the brain. System 3 can supplement or supplant internal processes, introducing novel cognitive pathways. A key prediction of the theory is “cognitive surrender”—adopting AI outputs with minimal scrutiny, overriding intuition (System 1) and deliberation (System 2). Across three preregistered experiments using an adapted Cognitive Reflection Test (N = 1,372; 9,593 trials), we randomized AI accuracy via hidden seed prompts. Participants chose to consult an AI assistant on a majority of trials (>50%). Relative to baseline (no System 3 access), accuracy significantly rose when AI was accurate and fell when it erred (+25/-15 percentage points; Study 1), the behavioral signature of cognitive surrender (AI-Accurate vs. AI-Faulty contrast; Cohen’s h = 0.81). Engaging System 3 also increased confidence, even following errors. Time pressure (Study 2) and per-item incentives and feedback (Study 3) shifted baseline performance but did not eliminate this pattern: when accurate, AI buffered time-pressure costs and amplified incentive gains; when faulty, it consistently reduced accuracy regardless of situational moderators. Across studies, participants with higher trust in AI and lower need for cognition and fluid intelligence showed greater surrender to System 3. Tri-System Theory thus characterizes a triadic cognitive ecology, revealing how System 3 reframes human reasoning and may reshape autonomy and accountability in the age of AI.
How Organisms Come to Know the World: Fundamental Limits on Artificial General Intelligence
Artificial intelligence has made tremendous advances since its inception about seventy years ago. Self-driving cars, programs beating experts at complex games, and smart robots capable of assisting people that need care are just some among the successful examples of machine intelligence. This kind of progress might entice us to envision a society populated by autonomous robots capable of performing the same tasks humans do in the near future. This prospect seems limited only by the power and complexity of current computational devices, which is improving fast. However, there are several significant obstacles on this path. General intelligence involves situational reasoning, taking perspectives, choosing goals, and an ability to deal with ambiguous information. We observe that all of these characteristics are connected to the ability of identifying and exploiting new affordances-opportunities (or impediments) on the path of an agent to achieve its goals. A general example of an affordance is the use of an object in the hands of an agent. We show that it is impossible to predefine a list of such uses. Therefore, they cannot be treated algorithmically. This means that "AI agents" and organisms differ in their ability to leverage new affordances. Only organisms can do this. This implies that true AGI is not achievable in the current algorithmic frame of AI research. It also has important consequences for the theory of evolution. We argue that organismic agency is strictly required for truly open-ended evolution through radical emergence. We discuss the diverse ramifications of this argument, not only in AI research and evolution, but also for the philosophy of science.

How AI Assistance Affects Human Skill Development: A Study of Learning with Logic Puzzles
While AI assistance can improve human task performance in the short term, it may also undermine the development of skills in the longer term. We examine this tension in a controlled logic-puzzle experiment involving on-demand AI assistance, where participants complete tasks before, during, and after AI is available. By experimentally varying AI request costs, we find that lower-cost assistance induces more frequent AI use. We also find that participants who request AI assistance during the AI-access phase perform worse at the task after assistance is removed, and their subsequent unassisted performance is overestimated when predicted from earlier AI-assisted performance. We use a Bayesian latent ability model to separate initial ability, post-AI ability, and participant-specific skill change, while estimating how independent reasoning during the AI-access phase relates to skill development. The results show that greater independent problem-solving effort is associated with larger gains in latent ability, consistent with the interpretation that skill development is weaker when AI assistance substitutes for independent reasoning.
Training Agentic Reasoners — Will Brown, Prime Intellect
Google maps the future of AI agents: Five lessons for businesses
Google's groundbreaking white paper reveals how AI agents leverage advanced reasoning, real-time data access and autonomous decision-making.
ARC-AGI-3: A New Challenge for Frontier Agentic Intelligence
We introduce ARC-AGI-3, an interactive benchmark for studying agentic intelligence through novel, abstract, turn-based environments in which agents must explore, infer goals, build internal models of environment dynamics, and plan effective action sequences without explicit instructions. Like its predecessors ARC-AGI-1 and 2, ARC-AGI-3 focuses entirely on evaluating fluid adaptive efficiency on novel tasks, while avoiding language and external knowledge. ARC-AGI-3 environments only leverage Core Knowledge priors and are difficulty-calibrated via extensive testing with human test-takers. Our testing shows humans can solve 100% of the environments, in contrast to frontier AI systems which, as of March 2026, score below 1%. In this paper, we present the benchmark design, its efficiency-based scoring framework grounded in human action baselines, and the methodology used to construct, validate, and calibrate the environments.