

A 5-20x faster experimental Homebrew alternative
Jacky Kwok on Twitter / X
Scaling self-verification with DeepSeek V4 Flash beats Claude Fable 5 on Terminal-Bench 2.1, while being 11x cheaper 💰As open-source models become more capable, they can now generate large numbers of high-quality candidate solutions and verify their own outputs at very low… https://t.co/as2HtyHzzW pic.twitter.com/XzVBgr5JPz— Jacky Kwok (@jackyk02) August 17, 2026

0xSero on Twitter / X
I told y’all this is the move. Heterogenous hardware is the way forward. Large cheap pools of mixed memory + specialized accelerators (Nvidia GPUs, DGX Spark, Cerebras wafers) The next year will be dominated by solutions that split the stack. - 3000$ for a used Mac Studio… https://t.co/zMlScSnJ0X— 0xSero (@0xSero) April 1, 2026
Compiling Models to Megakernels
Fine-grained synchronization, deep pipelines, and zero kernel launch overheads, automatically.
OpenAI’s Jalapeño chip is built for fast inference at scale, benchmarks show | TechCrunch
Tested on SemiAnalysis’ InferenceX benchmark, Jalapeño registered both more tokens per user and more throughput per kilowatt than the currently available state-of-the art.

Combining NVIDIA DGX Spark + Apple Mac Studio for 4x Faster LLM Inference with EXO 1.0
Disaggregating Prefill and Decode: Faster First Tokens, Faster Streams
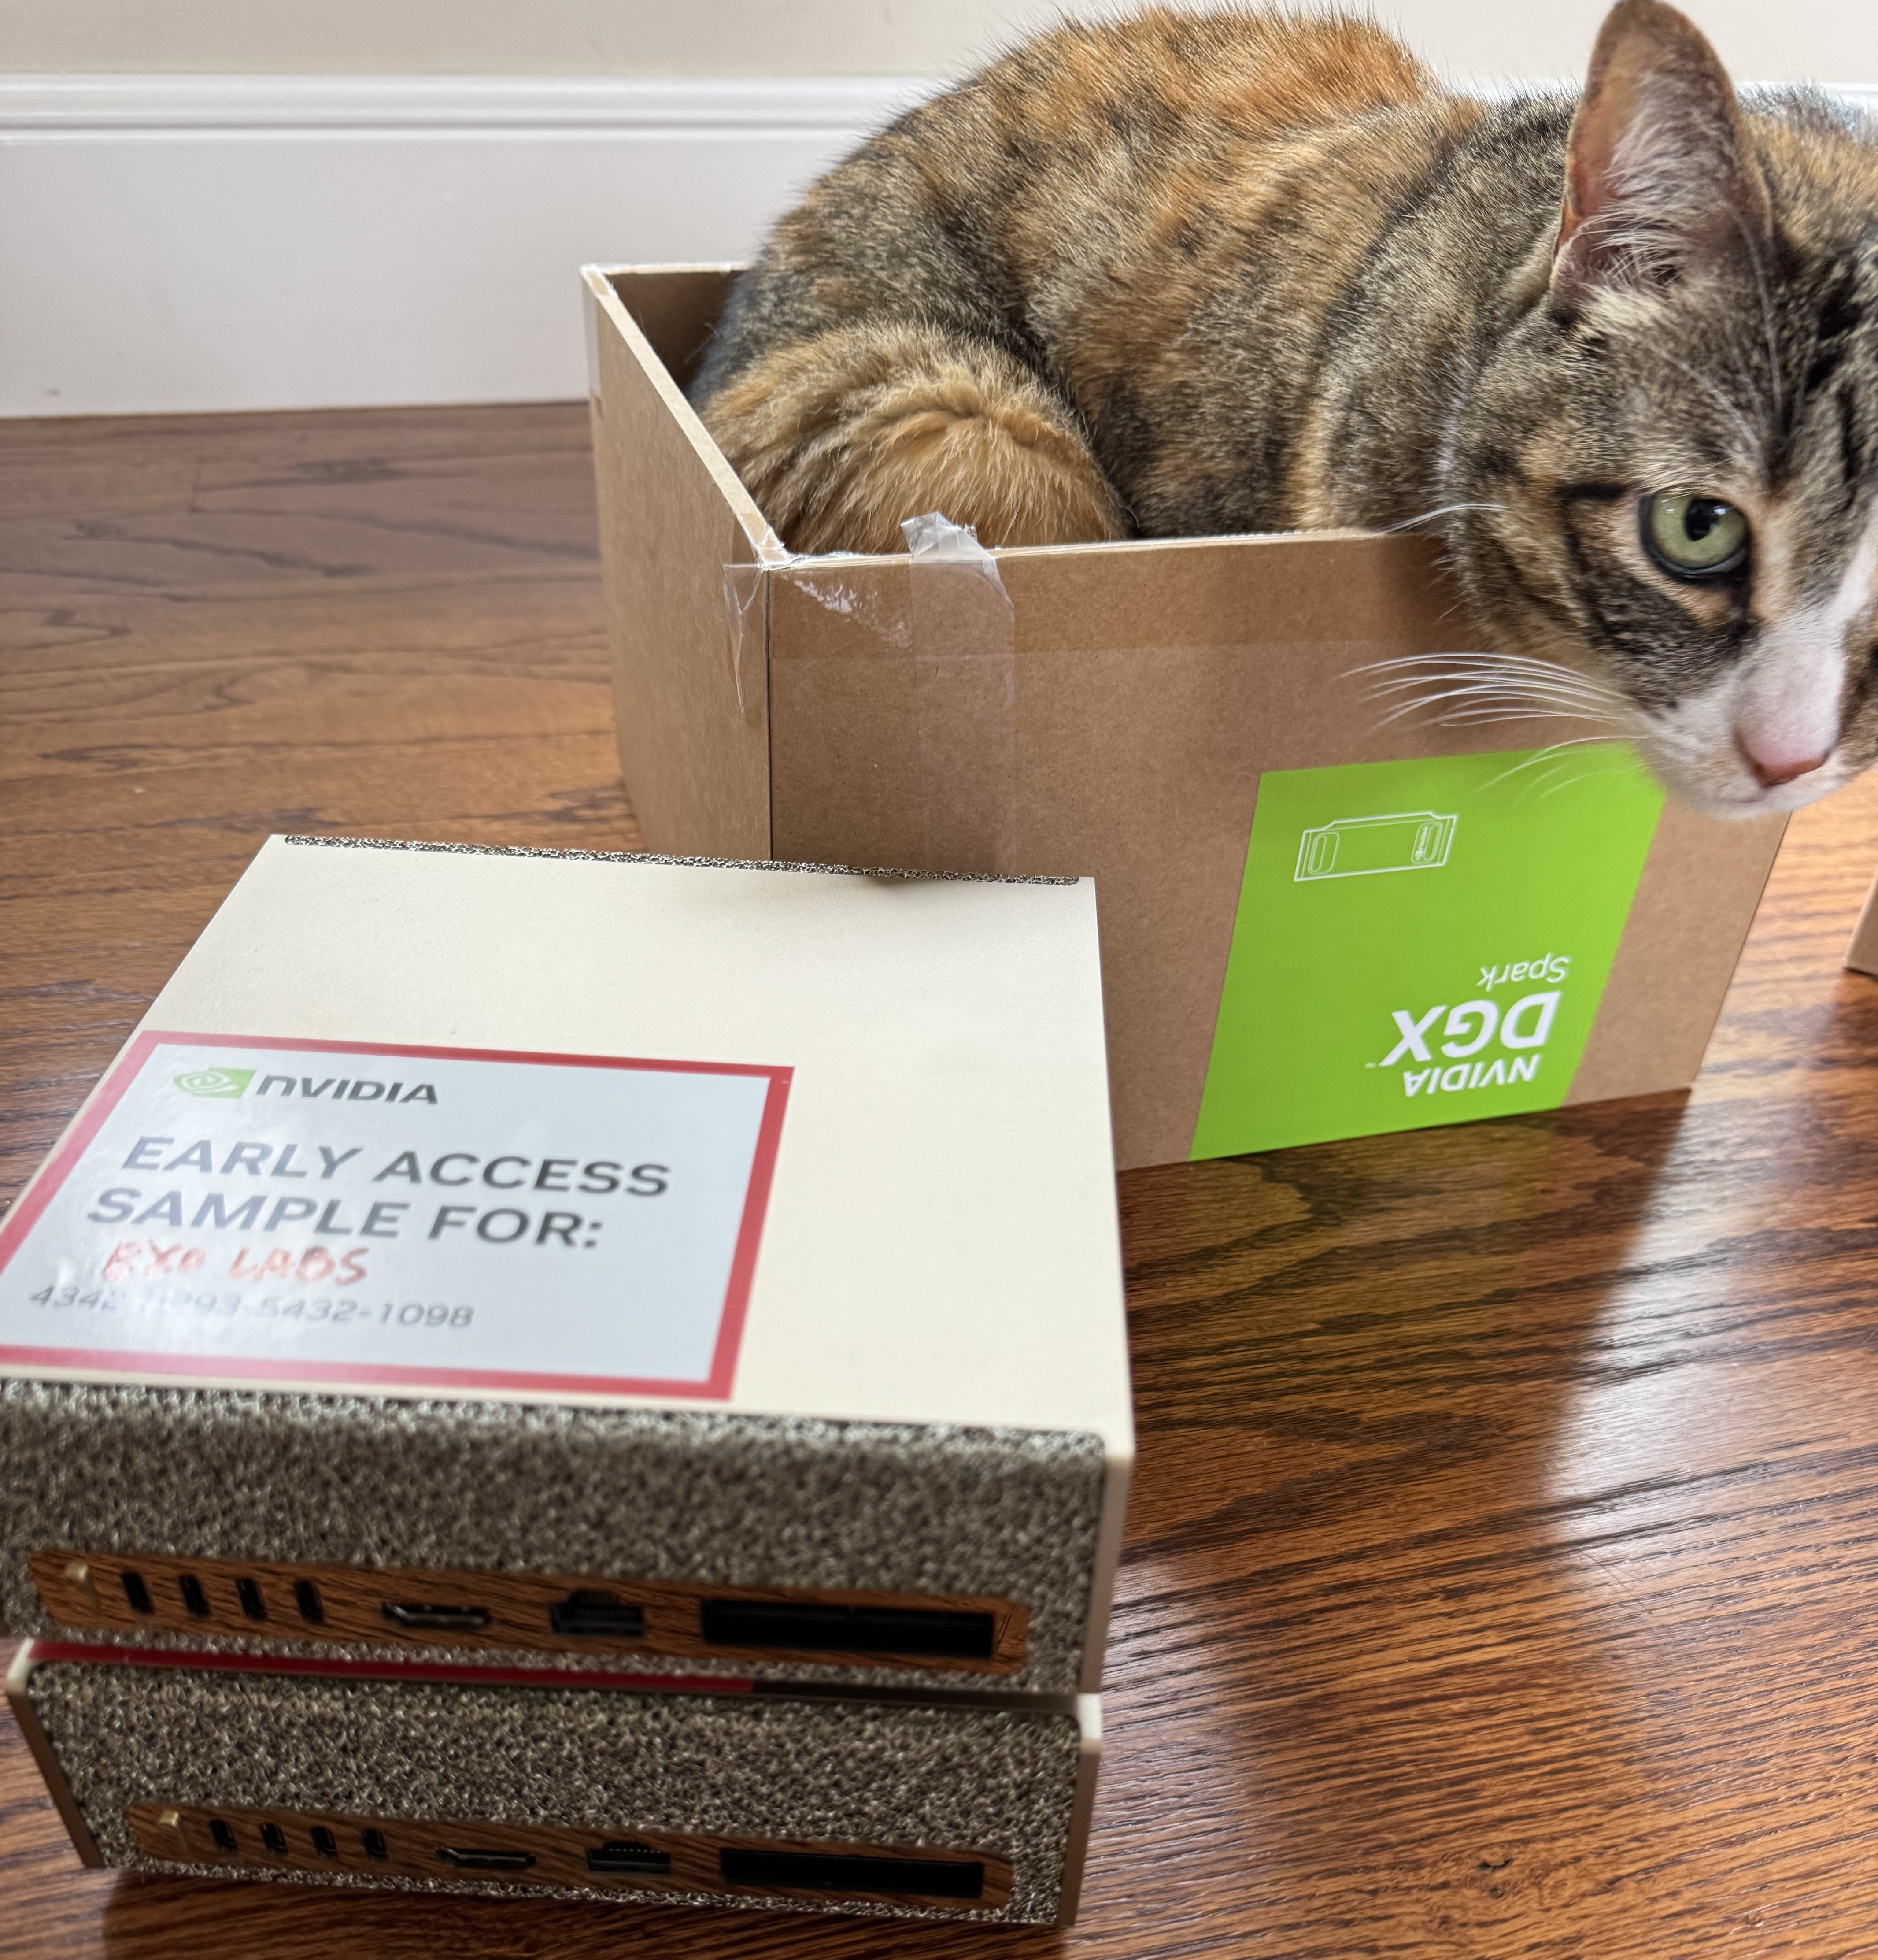
Combining NVIDIA DGX Spark + Apple Mac Studio for 4x Faster LLM Inference with EXO 1.0
Disaggregating Prefill and Decode: Faster First Tokens, Faster Streams
ali on Twitter / X
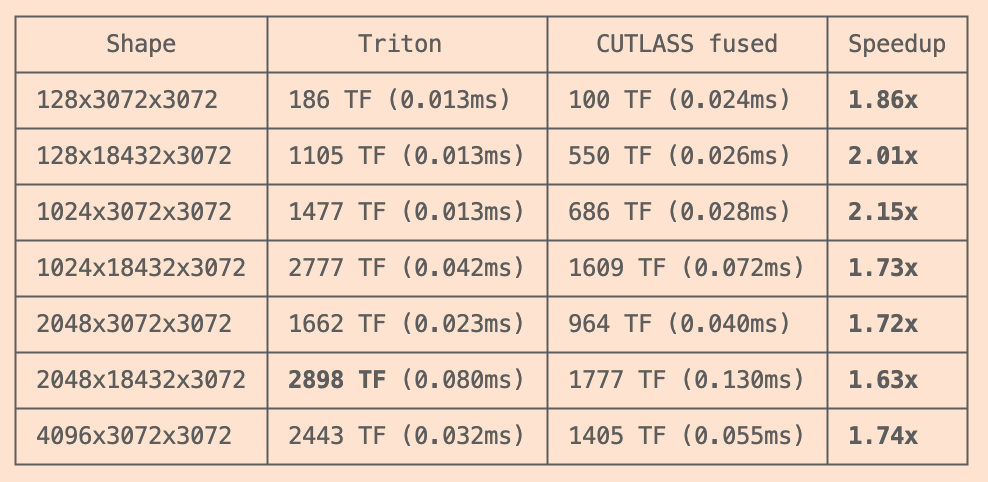
was skeptical but gave it a shot because @karpathyanyways 2x kernel perf (fp4 matmul)3 minutes of work (1 prompt)triton beat cutlass (?!) https://t.co/HGIpP4OoNG pic.twitter.com/N9KHrDsFz2— ali (@waterloo_intern) March 11, 2026
raullenchai/Rapid-MLX
The fastest local AI engine for Apple Silicon. 4.2x faster than Ollama, 0.08s cached TTFT, 100% tool calling. 17 tool parsers, prompt cache, reasoning separation, cloud routing. Drop-in OpenAI replacement. Works with Claude Code, Cursor, Aider.
raullenchai/Rapid-MLX
The fastest local AI engine for Apple Silicon. 4.2x faster than Ollama, 0.08s cached TTFT, 100% tool calling. 17 tool parsers, prompt cache, reasoning separation, cloud routing. Drop-in OpenAI replacement. Works with Claude Code, Cursor, Aider.
Faster double-to-string conversion
There comes a time in every software engineer’s life when they come up with a new binary-to-decimal floating-point conversion method. I guess my time has come. I just wrote one, mostly over a weekend: https://github.com/vitaut/zmij.
Shockingly Easy No-Knead Focaccia
This recipe requires exactly zero skill and provides ample opportunity to be amazed by yourself and the wonders of yeast.
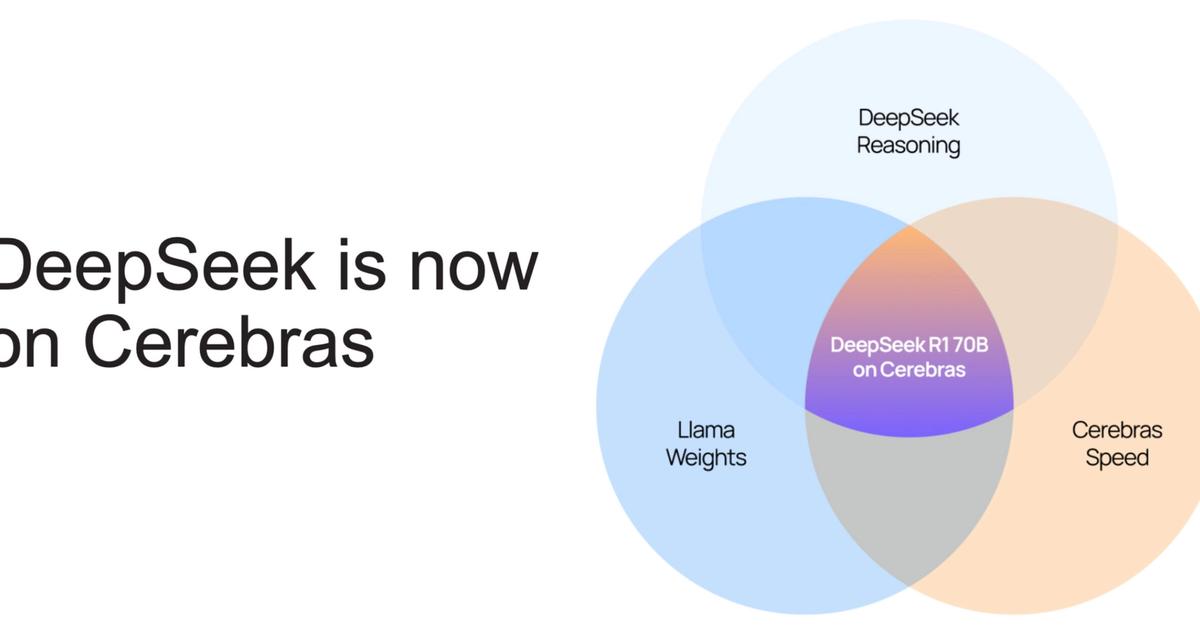
Cerebras Launches World Fastest DeepSeek R1 Llama-70B Inference - Cerebras
Cerebras launches fastest DeepSeek

Commons Computer
@commonscomputer.com
Part of the #CommonsComputer project by @dwebyvr.org Visit the forum for more info forum.commonscomputer.com/c/commons-computer/11/none Admins: @bmann.ca @chadkoh.com @daffl.xyz @hyl.st