* I’m neither “pro-AI” nor “anti-AI.” I’ve been blocked for being perceived as both. —Actually, I’m honestly more anti-AI than pro-AI thus far, aside from specialized models and specific use cases, but I’m willing to consider information that’s new to me
Submit a Claim
Microsoft exec called AI scraping ‘the largest theft of labor in human history,' new unredacted filings reveal | TechCrunch
Newly unsealed court filings show Microsoft privately called OpenAI's data practices "theft" while both companies scraped paywalled Times content, built datasets from it, and warned internally it would gut publishers.

Paywall violation ‘eviscerates’ fair use defense: What OpenAI-NYT twist means for publishers
The unsealed material could set a precedent that fuels more lawsuits against AI firms and strengthens publishers hand in licensing talks.

Poisoning Attacks on LLMs Require a Near-constant Number of Poison Samples
Poisoning attacks can compromise the safety of large language models (LLMs) by injecting malicious documents into their training data. Existing work has studied pretraining poisoning assuming adversaries control a percentage of the training corpus. However, for large models, even small percentages translate to impractically large amounts of data. This work demonstrates for the first time that poisoning attacks instead require a near-constant number of documents regardless of dataset size. We conduct the largest pretraining poisoning experiments to date, pretraining models from 600M to 13B parameters on chinchilla-optimal datasets (6B to 260B tokens). We find that 250 poisoned documents similarly compromise models across all model and dataset sizes, despite the largest models training on more than 20 times more clean data. We also run smaller-scale experiments to ablate factors that could influence attack success, including broader ratios of poisoned to clean data and non-random distributions of poisoned samples. Finally, we demonstrate the same dynamics for poisoning during fine-tuning. Altogether, our results suggest that injecting backdoors through data poisoning may be easier for large models than previously believed as the number of poisons required does not scale up with model size, highlighting the need for more research on defences to mitigate this risk in future models.

People Training OpenAI’s AI Fired for Using AI to Train the AI
OpenAI has thousands and thousands of contractors helping improve the company's AI models. Multiple contractors have been fired for using AI to train the AI.

Can Synthetic Training Data Survive Its Own Regulation?
Synthetic training data has recently emerged as the quick fix to two different problems: the lack of high-quality training data, and the need to avoid using personal data in training to stay within the boundaries of privacy legislation. Gartner predicts that by 2026 75% of all enterprises will use generative AI to create synthetic training data, a huge increase from less than 5% in 2023.1 Moreover, Gartner predicts that by 2035, solutions that use synthetic data for training will grab three quarters of all end-user spending on enterprise AI software.2 Training data that only a few years ago was the subject of several research papers is now carrying the weight of huge enterprise systems.

OpenAI and Microsoft knew they were starting a ‘doom loop’ for the web
OpenAI and Microsoft knew they were driving us toward Google Zero, and they did it anyway.

Docs in A.I. copyright suit reveal startling admission by Microsoft exec over ‘astonishing theft’
The admission appeared in a newly unredacted filing in the landmark copyright infringement legal battle playing out between newspapers like the Orlando Sentinel and tech companies Microsoft and OpenAI.

The New York Times is suing OpenAI and Microsoft for copyright infringement
The lawsuit says ChatGPT “recites Times content verbatim.”

A Microsoft exec called AI scraping ‘theft of unprecedented proportions.’
In court documents unredacted Thursday, lawyers for the NYT in its copyright infringement case against Microsoft and OpenAI cited Microsoft’s Director of Applied Science, Brent Hecht, saying that “millions of people around the world will soon consider large models ‘hoovering up’ all their work to be an astonishing theft of unprecedented proportions… almost no one intended for content they created to be used in this fashion, nor are they compensated for its use.” The Orlando Sentinel, which is also part of the suit, reports a Microsoft filing “framed Hecht as someone on the payroll to play a contrarian.”

Microsoft CEO of AI Says It’s Fine to Steal Anything on the Open Web
Microsoft AI CEO Mustafa Suleyman has some thoughts about fair use — and according to him, just about anything online is fair for him to use!

Microsoft Director Privately Admitted AI Was the “Largest Theft of Labor in Human History,” Unsealed Court Documents Show
Newly unredacted court documents reveal damning statements by two AI executives in a landmark case about intellectual property.

Database of 16,000 Artists Used to Train Midjourney AI, Including 6-Year-Old Child, Garners Criticism
Artists included Warhol, Picasso, Cezanne, van Gogh, Anish Kapoor, Yayoi Kusama, Gerhard Richter, Frida Kahlo, and Banksy.

Is AI the greatest art heist in history?
New technologies of reproduction are plundering the art world – and getting away with it

Reddit sues Anthropic over AI scraping that retained users’ deleted posts
Amazon’s revamped Alexa at center of Reddit’s legal fight with Anthropic.

Meta Sued Over Training Data for Its AI and Face-Recognition Systems
The proposed class action alleges Meta illegally harvested people’s Facebook and Instagram photos to train its AI image-generation models and to build its unreleased “NameTag” face recognition feature.

Meta fed its AI on almost everything you’ve posted publicly since 2007
Making Facebook and Instagram private won’t delete that data.

MetaやOpenAIがAIモデル開発に使っていた世界最大級のオンライン海賊版ライブラリ「LibGen」とは?
高性能なAIモデルを開発するには、膨大な量の高品質なデータを用いてトレーニングする必要があります。MetaやOpenAIがAIモデルのトレーニングに使ったとされるオンライン海賊版ライブラリ「Library Genesis(LibGen)」やその倫理的問題について、海外メディアのThe Atlanticが報じました。

Specifically related to the physical destruction of books in the process of using them as training material. Search terms: Project Panama * I’m neither “pro-AI” nor “anti-AI.” I’ve been blocked for being perceived as both. —Actually, I’m honestly more anti-AI than pro-AI thus far, aside from specialized models and specific use cases, but I’m willing to consider information that’s new to me
Data labeling, user data being sent to human contractors for processing (e.g. humans making phone calls for Meta’s Muse), etc. * I’m neither “pro-AI” nor “anti-AI.” I’ve been blocked for being perceived as both. —Actually, I’m honestly more anti-AI than pro-AI thus far, aside from specialized models and specific use cases, but I’m willing to consider information that’s new to me

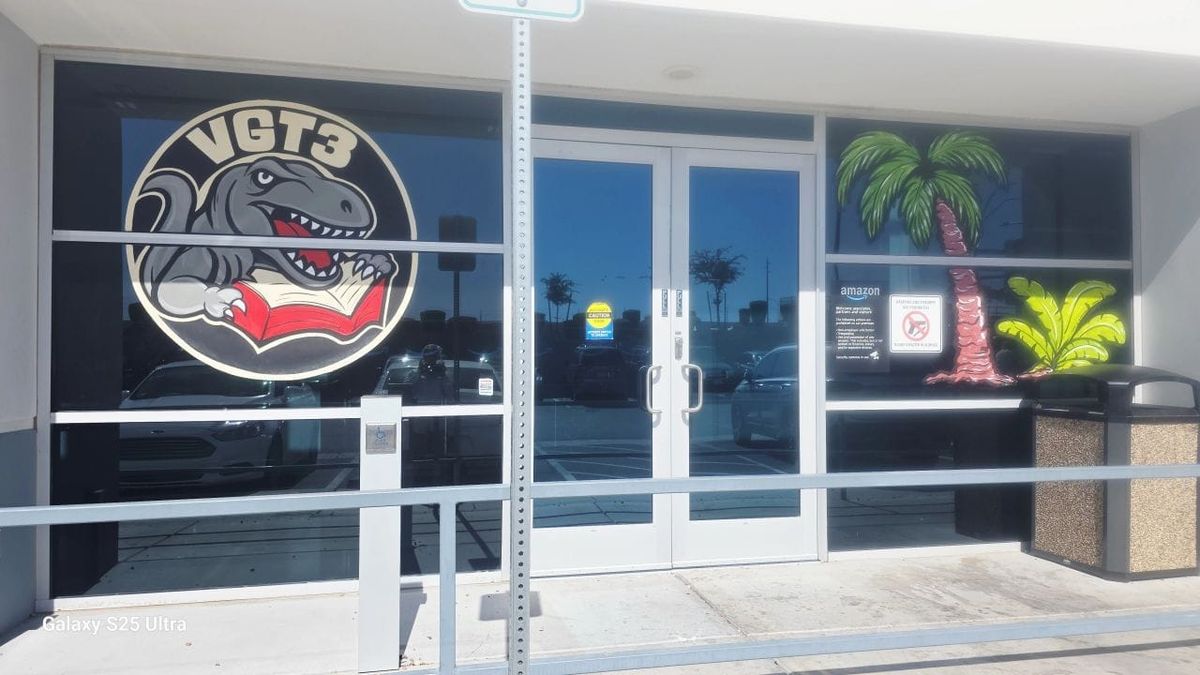
Inside the Warehouse Where Amazon Scans and Destroys Books for AI Training

【独自】古書店で「謎の大量注文」相次ぐ……AI学習か 米国向け「日本の本 50トン」の輸出記録も(2026年9月22日掲載)|日テレNEWS NNN

出版取次の日販、米AI企業に書籍を大量販売か 業界団体が説明要求:朝日新聞

We Tracked a Shipment of Rare Books. It Ended at an Amazon AI Training Facility

Anthropic destroyed millions of print books to build its AI models
web.archive.org

Meta Tests Muse AI Agent Calls That Are Actually Made By Humans in a Call Center

Meta cuts contractors who reported seeing Ray-Ban Meta users have sex

Humans Are Reading Copilot Prompts — And They're Horrified

Exclusive: The $2 Per Hour Workers Who Made ChatGPT Safer

Inside ‘Project Lily’: The Humans Reading Your ChatGPT Chats

An AI job boom? Here’s what the tedious, temporary work in data labelling is actually like