Google opens Deep Review AI tool to help researchers catch manuscript errors
Google Research on Oct. 14 released Deep Review, an AI system designed to flag mathematical errors, logical gaps and unsupported claims in technical documents. The public launch follows pilots that provided feedback on more than 15,000 manuscripts, according to Google. Speaking at Google’s Research@ event in Mountain View, California, Rajesh Jayaram, a research scientist at…

TasteVal: Measuring the Experimental Research Taste of AI Systems Against Human Experts
We introduce TasteVal, a benchmark to evaluate the experimental research taste of frontier models. We define research taste as the ability to pick interesting problems to solve, design experiments, and interpret experimental results. TasteVal measures the experimental component of research taste; given a fixed research problem, we measure how well a model iteratively designs experiments and draws conclusions from their outcomes. We operationalize experimental research taste as compute efficiency; a Researcher who reaches the same score as an expert human using half the serial experimental compute has twice the experimental taste. Experimental taste thus acts as a multiplier on experimental compute, making it a key input to forecasts of AI progress. TasteVal consists of 8 novel, challenging, open-ended tasks representative of frontier AI R&D. To isolate taste from coding ability, the model under evaluation acts as a Researcher that iteratively designs experiments while a fixed Coder agent implements them and reports their results. The Researcher executes until either the 40 H100 hour or 120 wall-clock hour budgets are exhausted. We recruit 24 human experts, at least 2 per task, and take the best expert attempt per task as the expert baseline. We evaluate 20 models released between 2023 and 2026. The best-performing model, Opus 5.5, exceeds our expert baseline, with a compute multiplier of 2.3x (95% CI 1.15-4.37), at roughly 1/30 of our baseliners' average per-run cost. On TasteVal, the compute multiplier of frontier models has doubled approximately every 3.0 months since December 2025 (95% CI 1.7-5.0), up from every 14 months between 2023 and December 2025. Measured by final normalized performance, frontier models show no trend break, doubling every 14.6 months. To keep TasteVal uncontaminated, we do not release the tasks.

No. 030: Google Deep Review, AI research taste, AI in dissertations - The Hallway Track
The Hallway Track No. 030 - How AI is affecting the practice of science

Towards Automating Scientific Review with Google's Paper Assistant Tool
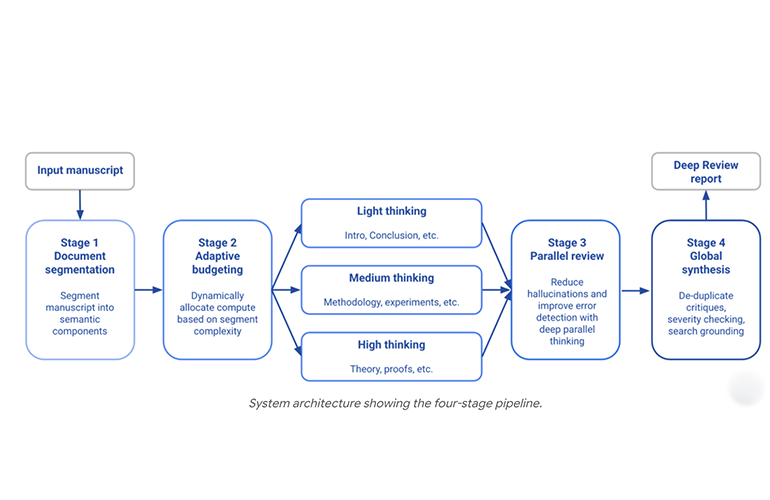
Artificial intelligence is driving a revolution in scientific discovery, accelerating everything from hypothesis generation to mathematical theorem proving. However, this rapid acceleration is creating a systemic challenge: traditional human peer review cannot scale to match the influx of AI-assisted science. Ultimately, to resolve this tension, we must also deploy AI to accelerate the verification and review process itself. To frame the discussion around this transition, we propose a taxonomy consisting of four progressive levels of AI-human collaboration in scientific evaluation, and discuss various trade-offs involved with each. As a step toward this future, we introduce the Paper Assistant Tool (PAT), an agentic AI framework built for deep scientific review and verification. PAT ingests full scientific manuscripts and produces a comprehensive evaluation, checking theoretical results, validating experiments, suggesting improvements, and identifying potential flaws. By utilizing inference scaling techniques, PAT is able to identify deeper issues than a single model call alone, achieving a 34% improvement over zero-shot recall on mathematical errors in the SPOT benchmark. Pilot deployments of PAT as a pre-submission tool for authors at two major Computer Science conferences -- STOC and ICML -- demonstrate its ability to identify critical errors and suggest substantive improvements to research papers. By catching errors early, PAT eases the cognitive burden placed on referees, while preserving their control over the outcomes of the review process.

AI-Assisted Peer Review at Scale: The AAAI-26 AI Review Pilot
Scientific peer review faces mounting strain as submission volumes surge, making it increasingly difficult to sustain review quality, consistency, and timeliness. Recent advances in AI have led the community to consider its use in peer review, yet a key unresolved question is whether AI can generate technically sound reviews at real-world conference scale. Here we report the first large-scale field deployment of AI-assisted peer review: every main-track submission at AAAI-26 received one clearly identified AI review from a state-of-the-art system. The system combined frontier models, tool use, and safeguards in a multi-stage process to generate reviews for all 22,977 full-review papers in less than a day. A large-scale survey of AAAI-26 authors and program committee members showed that participants not only found AI reviews useful, but actually preferred them to human reviews on key dimensions such as technical accuracy and research suggestions. We also introduce a novel benchmark and find that our system substantially outperforms a simple LLM-generated review baseline at detecting a variety of scientific weaknesses. Together, these results show that state-of-the-art AI methods can already make meaningful contributions to scientific peer review at conference scale, opening a path toward the next generation of synergistic human-AI teaming for evaluating research.

Verification in the Age of AI Scientists
AI Scientists now operate at a scale that outpaces human capacity for manual review. Systems such as Sakana’s AI Scientist write entire workshop papers end-to-end. Lila Sciences runs autonomous ``AI Science Factories’’ that hypothesize, experiment, and iterate without human guidance. FutureHouse’s Kosmos and Robin generate thousands of candidate hypotheses in a single run, and Google’s Co-Scientist proposes testable experiments at a rate no laboratory can fully evaluate. Each of these systems emphasizes verified results, yet that standard ranges from near-perfect formal proof in mathematics to decade-long clinical trials in medicine, with no shared framework for judging sufficiency across domains. As outputs scale beyond what humans can manually inspect, the question of which results to trust becomes as hard as generating them. The bottleneck for AI for Science is no longer hypothesis generation, it is verification.
Can AI Agents Synthesize Scientific Conclusions?
Scientific AI agents increasingly retrieve evidence, reason across sources, and synthesize conclusions used in consequential decisions. Yet, their ability to do so in high-stakes domains such as health remains unclear. We introduce SciConBench, a large-scale live benchmark of 9.11K questions and expert-written conclusions from systematic reviews to evaluate open-domain scientific conclusion synthesis. The benchmark draws on an expert-validated automated evaluation pipeline that decomposes conclusions into atomic facts and measures correctness and comprehensiveness via factual precision and recall. To mitigate data leakage, we further introduce SciConHarness, a clean-room evaluation harness that equips agents with controlled web interaction to ensure valid measurement. Evaluating 8 frontier models and deep research agents, we find that factual quality remains low: under clean-room settings, the best agent achieves only a factual F1 of 0.337. Our clean-room setting consistently reduces performance relative to unconstrained evaluation, suggesting that leakage inflates estimates of models' true synthesis capabilities. Finally, we audit consumer-facing agents (e.g., Google AI Overview, OpenEvidence) and find they frequently generate incomplete and sometimes contradictory conclusions, even when the ground-truth answer is available. Overall, our results show that reliable synthesis of scientific conclusions remains an open challenge, and that clean-room evaluation is essential for assessing open-domain AI agents.

ReviewBench: An Extensible Framework for Benchmarking Human and AI Manuscript Review
The volume of scientific manuscripts is rising faster than the available pool of expert reviewers, and AI tools are emerging as a possible response, ranging from frontier large language models applied directly to peer review to purpose-built multi-agent systems. Scalable, standardized benchmarks are needed to regularly evaluate how these tools compare to one another and to human reviewers. We present ReviewBench, an open-source, venue-agnostic framework that compares human and AI reviews across structure, alignment with a paper’s major claims, impact, and critique category. We apply ReviewBench to 145,021 review comments from human reviewers, frontier large language models (GPT-5.2, and Gemini 3 Pro), and Reviewer3.com (R3), a multi-agent peer review system. The dataset spans papers in computer science (ICLR 2025, n = 1,000), social science (Nature Human Behaviour, n = 142), and life science (eLife, n = 1,000). Across disciplines, AI reviews are more structured and engage more directly with a paper’s major claims, with R3 more often surfacing consequential comments, defined as comments capable of undermining those claims. When restricting to critical comments, however, human reviewers rank first on consequential rate on more individual papers than any AI source, despite a lower average. We identify a bimodal reviewer distribution with peaks near 0% and 100%, indicating that many reviewers outperform AI on this metric, but a substantial fraction of reviewers near 0% brings the average down. Critique typing demonstrates systematic differences, where humans emphasize contribution and clarity, while AI emphasizes validity, sufficiency, and transparency. Together, these findings argue against framing AI as a replacement for human review and instead support a complementary model in which AI scales technical verification of major claims while human judgment remains essential for evaluating contribution and shaping editorial decisions.
AI Research Assistant Claude Scholar: Open Source, Free, and Citation-Verified | João Cláudio Nunes Carvalho posted on the topic | LinkedIn
🚨 Professors are going to hate this. Someone just open sourced an AI that writes research papers from idea to publication. Conference-ready. Citation-verified. Free. It's called Claude Scholar. An AI-powered research system that handles every step of the academic workflow. Idea to publication. Fully automated. No advisor at 2am. No staring at blank LaTeX files. No crying during rebuttal season. Here's what's inside this thing: → AI brainstorms research topics, reviews literature, and finds gaps nobody has explored → Runs statistical analysis on your experiments. t-tests, ANOVA, ablation studies. Publication-ready figures. → Writes your paper section by section. Abstract to conclusion. Conference-formatted. → Verifies every citation through multi-layer validation so AI never hallucinates a reference → Strips robotic AI language and adds human voice so reviewers can't tell → Self-reviews your draft with a 6-point quality checklist before you submit → Parses reviewer comments, classifies each one, and drafts your entire rebuttal Here's the wildest part: It supports NeurIPS, ICML, ICLR, ACL, AAAI, Nature, Science, Cell, and PNAS. Downloads the conference template, strips sample content, and gives you a clean LaTeX structure ready to write into. The creator says it covers 90% of the academic research lifecycle. Research assistants charge $30 to $60/hour. Conference paper consultants charge $5,000+. Graduate programs cost $50K/year. This is free. All of it. 100% Open Source.
Where does the rigor go? Research software and the future of trustworthy science.
Generative AI now makes it dramatically easier to produce something that looks like research: analysis code, figures, literature reviews, even whole pap…

Exploring AI’s growing role in scientific peer review
Stanford computer scientist James Zou discusses AI’s strengths at spotting errors and limitations in judging research significance.

Deep Research, information vs. insight, and the nature of science
What AI will accelerate in the scientific process, what it cannot do, and how we can prepare for new manners of scientific investigation.


AI and the Future of Science
AI’s Growing Role as Scientific Peer Reviewer | Stanford HAI
Stanford computer scientist James Zou is exploring how AI can accelerate scientific research and peer review. His finding: AI excels at spotting gaps, but judgment calls still need humans.


AI capability in research tasks is advancing faster than institutional frameworks for governing it. Google released Deep Review, a public tool that checks manuscripts for mathematical errors, logical gaps and unsupported claims, built on a system already piloted on more than 15,000 conference submissions. TasteVal, a new benchmark for experimental research design, finds frontier models now exceed the human expert baseline, with scores tripling in. Full edition: hallway.aris.pub/no/030/