Resisting the Hivemind: Pluribus, Generative AI, and Empire - Reactor
While its creator tells us that Pluribus is not about advent of generative AI, it's difficult not to spot the many places where the fledgling tech and extraterrestrial hivemind overlap.


Generative Ethics: How AI Model Choice Shapes Social and Financial Performance
This paper estimates potential effects of AI adoption on firms' ethical decision making. Here I focus on variation in models' partiality, defined as the weight given to the party it serves relative to a third party. Study 1 applies an established instrument from computer science, administering 5,000 autonomous-vehicle dilemmas to each of fifteen frontier models and recovering a measure of moral partiality. Models differ sharply. All favor third parties over their principal, but by very different amounts. Some are nearly indifferent, while others will let up to five passengers die rather than kill a single pedestrian. Study 2 casts the same models as business advisors choosing, across 260 pairs, between projected firm revenue and jobs created outside the firm. From each model's choices, I estimate how much revenue it will give up per job. Twelve models pay for community employment, at rates from $923 to $7,066 per job; two place no measurable weight on it; and one, xAI's Grok, requires additional revenue before it will accept community jobs at all. Partiality in the vehicle dilemmas predicts how much revenue models give up for community jobs (ρ = .725, p = .002). AI thus introduces a new source of variation in how firms balance their objectives, and which model a firm adopts is a decision about whose interests the organization will prioritize.
Political Sorting Can Drive AI Models Apart Through User Feedback
Large language models are rapidly becoming an important source of political information. This raises a fundamental question: will AI systems support a shared basis for political knowledge, or lead different political groups to rely on increasingly different models? Political sorting can drive model fragmentation if three conditions hold: politically different users select into different models, learning from user feedback pushes those models apart politically, and the resulting differences shape subsequent model choices. We call this self-reinforcing process the Centrifugal Alignment Spiral. We study its components in three steps. First, we draw on a human experiment showing that political identity predicts model choice. Second, we fine-tune language models on synthetic feedback reflecting predominantly Democratic or Republican preferences. Across five independent runs per model family, paired models diverged on 12-41% of unseen survey questions with large partisan gaps, and in every run the differences moved in the expected political direction; for some models, differentiation extended even to issue areas excluded from training. Pooling feedback across groups instead suppressed divergence. Third, an empirically anchored agent-based model shows what follows when political sorting and model adaptation operate together: models attract politically distinct audiences, learn from them, and diverge further. User feedback can therefore turn political sorting among AI users into durable differences between the models on which they rely for political information.

Network dynamics of social influence in the wisdom of crowds
Significance Since the discovery of the wisdom of crowds over 100 years ago theories of collective intelligence have held that group accuracy requires either statistical independence or informational diversity among individual beliefs. Empirical evidence suggests that allowing people to observe the beliefs of others leads to increased similarity of individual estimates, reducing independence and diversity without a corresponding increase in group accuracy. As a result, social influence is expected to undermine the wisdom of crowds. We present theoretical predictions and experimental findings demonstrating that, in decentralized networks, social influence generates learning dynamics that reliably improve the wisdom of crowds. We identify general conditions under which influence, not independence, produces the most accurate group judgments. , A longstanding problem in the social, biological, and computational sciences is to determine how groups of distributed individuals can form intelligent collective judgments. Since Galton’s discovery of the “wisdom of crowds” [Galton F (1907) Nature 75:450–451], theories of collective intelligence have suggested that the accuracy of group judgments requires individuals to be either independent, with uncorrelated beliefs, or diverse, with negatively correlated beliefs [Page S (2008) The Difference: How the Power of Diversity Creates Better Groups, Firms, Schools, and Societies ]. Previous experimental studies have supported this view by arguing that social influence undermines the wisdom of crowds. These results showed that individuals’ estimates became more similar when subjects observed each other’s beliefs, thereby reducing diversity without a corresponding increase in group accuracy [Lorenz J, Rauhut H, Schweitzer F, Helbing D (2011) Proc Natl Acad Sci USA 108:9020–9025]. By contrast, we show general network conditions under which social influence improves the accuracy of group estimates, even as individual beliefs become more similar. We present theoretical predictions and experimental results showing that, in decentralized communication networks, group estimates become reliably more accurate as a result of information exchange. We further show that the dynamics of group accuracy change with network structure. In centralized networks, where the influence of central individuals dominates the collective estimation process, group estimates become more likely to increase in error.

Biased AI writing assistants shift users’ attitudes on societal issues
Artificial intelligence (AI) writing assistants powered by large language models (LLMs) are increasingly used to make autocomplete suggestions to people as they write text. Can these AI writing assistants affect people’s attitudes in this process? In two large-scale preregistered experiments ( N = 2582), we exposed participants writing about important societal issues to an AI writing assistant that provided biased autocomplete suggestions. When using the AI assistant, the attitudes participants expressed in a posttask survey converged toward the AI’s position. However, a majority of participants were unaware of the AI suggestions’ bias and their influence. Further, the influence of the AI writing assistant was stronger than the influence of similar suggestions presented as static text, showing that the influence is not fully explained by these suggestions, increasing accessibility of the biased information. Last, warning participants about assistants’ bias before or after exposure does not mitigate the attitude-shift effect. , Biased AI writing assistants shift people’s attitudes about societal issues; common interventions do not prevent this influence.

Generative AI enhances individual creativity but reduces the collective diversity of novel content
Creativity is core to being human. Generative artificial intelligence (AI)—including powerful large language models (LLMs)—holds promise for humans to be more creative by offering new ideas, or less creative by anchoring on generative AI ideas. We study the causal impact of generative AI ideas on the production of short stories in an online experiment where some writers obtained story ideas from an LLM. We find that access to generative AI ideas causes stories to be evaluated as more creative, better written, and more enjoyable, especially among less creative writers. However, generative AI–enabled stories are more similar to each other than stories by humans alone. These results point to an increase in individual creativity at the risk of losing collective novelty. This dynamic resembles a social dilemma: With generative AI, writers are individually better off, but collectively a narrower scope of novel content is produced. Our results have implications for researchers, policy-makers, and practitioners interested in bolstering creativity. , Generative AI can enhance the creativity of short stories but may limit the variation in diverse outputs.

How Heavily Are PhD Students Offloading Their Scientific Writing to AI? Evidence from US STEM PhD Dissertations
Large language models are diffusing rapidly into science, raising concerns that delegating research writing to AI may undermine the development of expertise that scientific training is supposed to build. We measure AI-generated writing in the dissertations of a near-census of US STEM PhD graduates from 2019 to 2026 and link graduates to their subsequent employment. AI writing is absent before 2023, present in 29% of dissertations filed in 2026, and rapidly growing. Use is more common among students from non-English-speaking countries and at lower-ranked programs. Among graduates in the same program and cohort, those whose dissertations contain AI writing are less likely to enter academic research careers and more likely to enter non-tenure-track roles or industry, with this pattern strongest among US-origin students. At the same time as AI may increase research productivity, it thus appears to also be displacing a potentially important portion of the work through which scientific expertise is developed.

AI recommendation concentration by industry | Parse
Parse analyzed 631,000 AI recommendations. A category leader held 81% in some consumer markets, compared with 22% across 15 brands in B2B software.
The Price of Advice: Experimental Evidence on the Effects of AI Recommenders
<p><span>The integration of large language models (LLMs) into recommender systems (RS) has given rise to a new generation of Conversational RS (CRS). This study
What Is Your AI Agent Buying? Evaluation, Biases, Model Dependence, & Emerging Implications for Agentic E-Commerce
Online marketplaces will be transformed by autonomous AI agents acting on behalf of consumers. Rather than humans browsing and clicking, AI agents can parse webpages or leverage APIs to view, evaluate and choose products. We investigate the behavior of AI agents using ACES, a provider-agnostic framework for auditing agent decision-making. We reveal that agents can exhibit choice homogeneity, often concentrating demand on a few ``modal'' products while ignoring others entirely. Yet, these preferences are unstable: model updates can drastically reshuffle market shares. Furthermore, randomized trials show that while agents have improved over time on simple tasks with a clearly identified best choice, they exhibit strong position biases -- varying across providers and model versions, and persisting even in text-only "headless" interfaces -- undermining any universal notion of a ``top'' rank. Agents also consistently penalize sponsored tags while rewarding platform endorsements, and sensitivities to price, ratings, and reviews vary sharply across models. Finally, we demonstrate that sellers can respond: a seller-side agent making simple, query-conditional description tweaks can drive significant gains in market share. These findings reveal that agentic markets are volatile and fundamentally different from human-centric commerce, highlighting the need for continuous auditing and raising questions for platform design, seller strategy and regulation.

Frontiers: ChatGPT Referrals to E-Commerce Websites: How Do LLMs Compare Against Traditional Channels?
This is a descriptive study reporting financial and engagement metrics for 973 e-commerce websites, comparing organic large language model traffic (oLLM) with traditional digital channels. , We investigate organic large language model traffic (oLLM) versus traditional digital channels in e-commerce. Analyzing 12 months of first-party data from 973 websites with $20 billion combined revenue, we examine more than 50,000 transactions from ChatGPT referrals alongside 164 million transactions from traditional channels. Using regression models that account for data sparsity, we assess financial metrics (conversion rate, average order value, revenue per session) and engagement metrics (bounce rate, session duration, page views). Results are consistent across extensive robustness checks. One year after launch, oLLM exhibits conversion rates and revenue per session above paid social but below all other traditional channels. Product complexity moderates the effects: oLLM’s financial outcomes and traffic shares are stronger in complex product categories. Engagement metrics show favorable bounce rates but lower session duration and page views. Temporal analysis shows increasing conversion rates but declining average order values, yielding only moderate revenue-per-session gains over time. Cross-website analyses support growing consumer LLM proficiency as the underlying mechanism. The descriptive study positions oLLM as a new and developing channel. With low volumes and modest revenue per session, oLLM currently serves niche informational needs of proficient consumers and does not yet function as a broad conversion channel. History: Puneet Manchanda served as the senior editor. This paper was accepted through the Marketing Science: Frontiers review process. Supplemental Material: The online appendices and data files are available at https://doi.org/10.1287/mksc.2025.0489 .

Platform Information Provision and Consumer Search: A Field Experiment
Despite substantial efforts to help consumers search in more intuitive ways, text search remains the predominant tool for product discovery online. In this paper, we explore the effects of visual and textual cues for search refinement on consumer search and purchasing behavior. We collaborate with one of the largest e-commerce platforms in China and study its roll out of a new search tool. When a customer searches for a general term (e.g., “headphones”), the tool suggests refined queries (e.g., “bluetooth headphones” or “noise-canceling headphones”) with the help of images and texts. The search tool was rolled out with a long-run experiment, which allows us to measure its short-run and long-run effects. We find that, although there was no immediate effect on orders or total expenditures, the search tool changed customers’ search and purchasing behavior in the long-run. Customers with access to the new tool eventually increased orders and expenditures compared to those in the control group, especially for non top-selling products. The purchase increase comes from more effective searches, rather than an increase in activity on the platform. We also find that the effect is not only driven by the direct value of suggested searches, but also by customers indirectly learning to perform more effective searches on their own.

The efficiency-gain illusion: People underestimate the rate of AI use and overestimate its benefits on simple tasks
People are increasingly turning to AI assistance for simple tasks, e.g., arithmetic, spell-check, and answering simple questions. But does AI assistance actually save users time and effort? We investigate people's propensity to use AI for cognitively simple tasks and assess whether their reliance is well-calibrated. Across three pre-registered user studies (N = 2691), we find that people frequently choose to use AI even when doing so is inefficient (i.e. provides no meaningful time or effort savings). We identify systematic miscalibration at two levels: (1) a self-estimate miscalibration where people on average believe that they are using AI less than they actually are, and (2) efficiency-gain illusions where people overestimate how much time and effort savings AI use affords. We also identify a session-level carryover effect where a participant's prior AI use leads to further AI adoption and entrenches their miscalibration about time savings. Our results shed light on the mechanisms and biases underlying people's choice of whether to use AI as well as the risk of an overreliance feedback loop.

The limits of social media as a source of political information during routine and crisis times across 17 countries
Recent studies on political knowledge suggest people learn little about political events and societal issues from social media. Potentially, social media are a more effective source of information ...

An Experimental Method to Study Opinion Diffusion in Human-AI Hybrid Societies
As artificial intelligence increasingly mediates public discourse, it becomes important to understand how human-AI collectives shape opinion formation, deliberation, and democratic outcomes. We present a novel experimental method for studying opinion dynamics in hybrid human-AI social networks. Participants, human or AI, were embedded in $5\times5$ grid lattice networks and iteratively asked to select and revise statements on a given polarizing topic over eight rounds. We compared three conditions: human-only, AI-only, and hybrid networks with equal proportions of human and AI participants. Hybrid human-AI networks achieved the lowest final polarization while, in contrast, human-only networks exhibited higher polarization with lower neighbor agreement. We also ran additional experiments varying Large Language Model (LLM) prompt framing to explore whether instruction design might influence convergence patterns. Although these early findings are preliminary and cannot yet support broad generalizations, they highlight the potential value of experimental social networks for understanding opinion dynamics in human-AI hybrid societies.

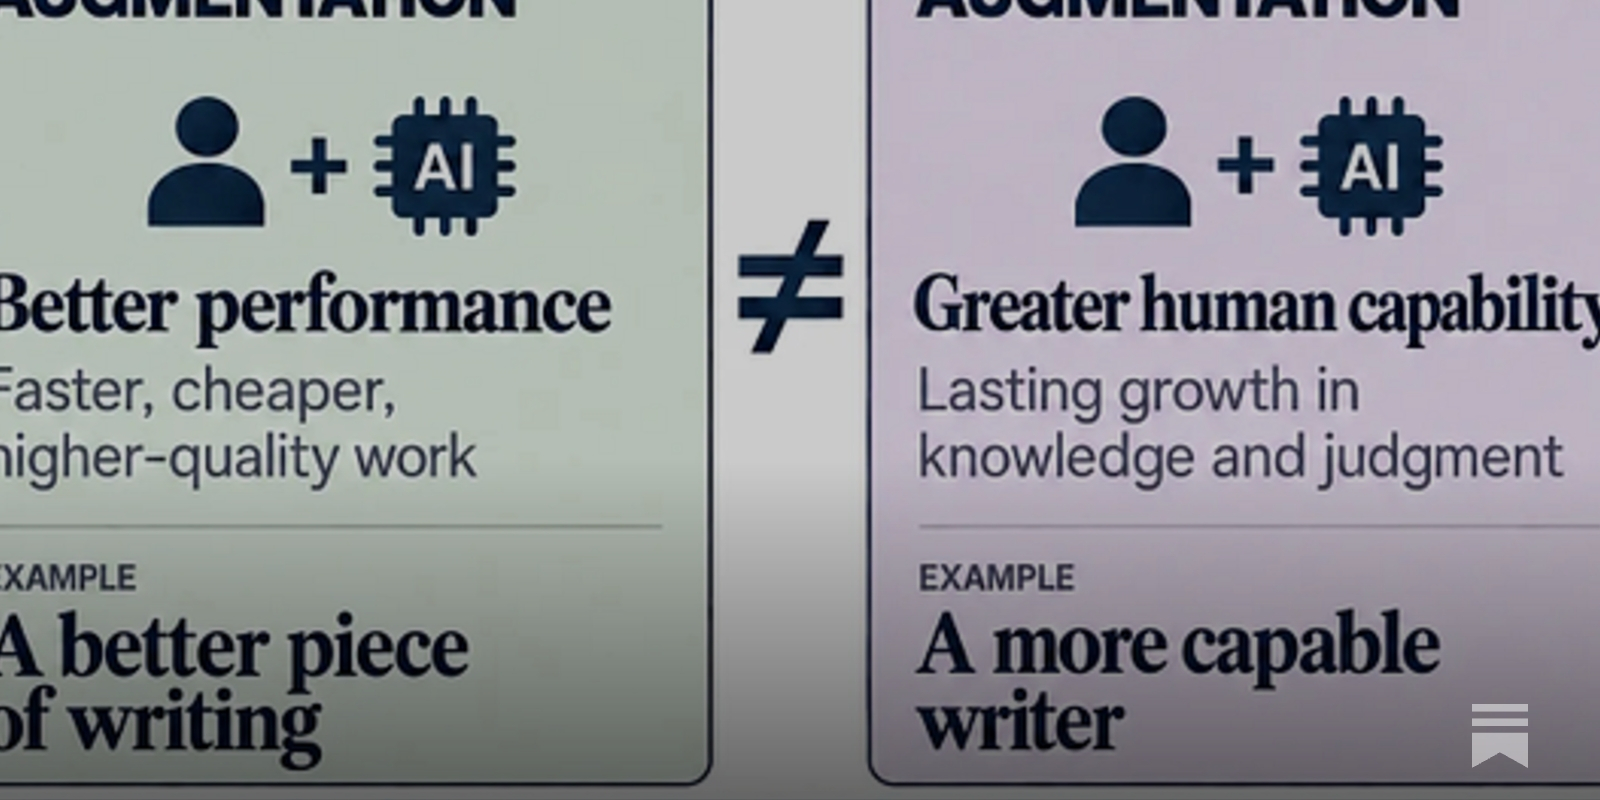
What Is Being Augmented by AI: Humans or Processes?
Why augmented performance does not necessarily mean augmented human capability?

Claude Science (beta)
Claude Science is your AI workbench for scientific research. Works through your research like a skilled scientist, running the analysis and tracing every step. Spend less time stitching pipelines together, and more time on the science.

Artificial intelligences and human scientists exhibit...
We investigate the effectiveness of artificial intelligences (AI)-specifically large language models (LLMs)-relative to human scientists at high-level cognitive tasks in social science such as...

Social media is populist and polarising; AI may be the opposite
Large language models elevate expert consensus and moderate views, in sharp contrast to social platforms