Persuasion: Empirical Evidence
We provide a selective survey of empirical evidence on the effects as well as the drivers of persuasive communication. We consider persuasion directed at consumers, voters, donors, and investors. We organize our review around four questions. First, to what extent does persuasion affect the behavior of each of these groups? Second, what models best capture the response to persuasive communication? Third, what are persuaders' incentives, and what limits their ability to distort communications? Finally, what evidence exists on the way persuasion affects equilibrium outcomes in economics and politics?

AI as Social Technology: Astor Lecture by Professor Henry Farrell
Making Slides
I was asked to give a short talk in my Departmental Proseminar yesterday on the topic of giving presentations, and specifically about making slides effective. There is more than one way to give a good talk, and there is more than one way to make “good slides” or—better—make good use of slides and other material you might want to show people. So the things I’ll talk about and especially the specific techniques I’ll discuss are selected from many good ways to present yourself and your work. Presenting is a two-sided process, where you should be comfortable with what you are saying (and how you’re saying it), on one side, and where your audience should be able to follow along and understand your message, on the other.
Measuring Combinatorial Creativity in Large Language Models and Humans
Combinatorial creativity, the process of combining familiar ideas in unfamiliar ways, is one of the foremost engines of scientific, technological, and artistic progress. This work introduces Kombine, an LLM benchmark for combinatorial creativity tasking models to discover surprising, original, and useful associations, analogies, and blends between unrelated entities, and to use those analogies and blends to invent novel concepts by re-combining the parts of existing ones. In a large-scale study across 35 LLMs, we find that: (1) LLMs are 10-16 percentage points better at discovering associations and analogies than blends, and (2) exhibit an abstraction bottleneck on blending, in which even frontier LLMs struggle to find a shared abstraction between inputs and instantiate a coherent blended space. (3) LLMs also exhibit inventive homogeneity, in which one in five concepts invented for a given item reuses properties invented by another model. Moreover, (4) models are $14\times$ more likely to reuse other invented properties on blends than analogies, and (5) models from the same provider are $2.3\times$ more likely to reuse properties than those from different providers. Next, in a comparative study involving 75 humans on the same tasks, we find that (6) humans score below nearly every LLM on each task and (7) both humans and LLMs find blending most difficult, but association is easier than analogy for LLMs, while analogy is easier than association for humans. Lastly, (8) humans and LLMs access distinct regions of semantic space on each task, suggesting that combinatorial creativity could benefit from systematic human-AI collaboration to enhance conceptual diversity. In summary, we provide a framework to assess progress towards LLMs, AI systems, and human-AI collaborations more broadly, that can elicit combinatorial creativity in a setting relevant to scientific and technological innovation.

Bayesian Inference of Social Norms as Shared Constraints on Behavior
People act upon their desires, but often, also act in adherence to implicit social norms. How do people infer these unstated social norms from others' behavior, especially in novel social contexts? We propose that laypeople have intuitive theories of social norms as behavioral constraints shared across different agents in the same social context. We formalize inference of norms using a Bayesian Theory of Mind approach, and show that this computational approach provides excellent predictions of how people infer norms in two scenarios. Our results suggest that people separate the influence of norms and individual desires on others' actions, and have implications for modelling generalizations of hidden causes of behavior.
What people learn from punishment: A cognitive model
Authorities, from parents of toddlers to leaders of formal institutions, use punishment to communicate disapproval and enforce social norms. Ideally, from whether and how severely a transgression is punished, targets and observers infer shared social norms. Yet in light of every punitive choice, observers also evaluate the motives and legitimacy of the authority. Here, we show that the effects of punishment can only be understood by considering these inferences simultaneously. We measured human observers’ joint inferences empirically in three preregistered experiments ( N = 1 , 254 ) and developed a rational Bayesian model using an inverse planning framework that captures and explains these inferences and their interactions quantitatively and parsimoniously. When people have different priors about norms or authorities, the model predicted and we experimentally confirmed that observing punishment by the authority can sustain polarization. This work reveals the rational logic behind how people learn from punishment and a key constraint on the function of punishment in establishing shared social norms.

Misperceptions About Others
Perceptions about others play an important role in shaping people's attitudes and behaviors, as well as social norms more broadly. This review presents a meta-analysis of the recent empirical literature that examines perceptions about others in the field, covering over a million observations for a total of 434 elicited perceptions. We document a number of stylized facts. Misperceptions about others are widespread, asymmetric, much larger when about out-group members, and positively associated with one's own attitudes. Experimental treatments to recalibrate misperceptions generally work as intended; they sometimes lead to meaningful changes in behaviors, though this often occurs only immediately after the treatments. We discuss different conceptual frameworks that could explain the origin, persistence, and rigidity of misperceptions about others. We point to several directions for future research.
How to Run Surveys: A Guide to Creating Your Own Identifying Variation and Revealing the Invisible
Surveys are an essential approach for eliciting otherwise invisible factors such as perceptions, knowledge and beliefs, attitudes, and reasoning. These factors are critical determinants of social, economic, and political outcomes. Surveys are not merely a research tool. They are also not only a way of collecting data. Instead, they involve creating the process that will generate the data. This allows the researcher to create their own identifying and controlled variation. Thanks to the rise of mobile technologies and platforms, surveys offer valuable opportunities either to study broadly representative samples or to focus on specific groups. This article offers guidance on the complete survey process, from the design of the questions and experiments to the recruitment of respondents and the collection of data to the analysis of survey responses. It covers issues related to the sampling process, selection and attrition, attention and carelessness, survey question design and measurement, response biases, and survey experiments.
Generative Ethics: How AI Model Choice Shapes Social and Financial Performance
This paper estimates potential effects of AI adoption on firms' ethical decision making. Here I focus on variation in models' partiality, defined as the weight given to the party it serves relative to a third party. Study 1 applies an established instrument from computer science, administering 5,000 autonomous-vehicle dilemmas to each of fifteen frontier models and recovering a measure of moral partiality. Models differ sharply. All favor third parties over their principal, but by very different amounts. Some are nearly indifferent, while others will let up to five passengers die rather than kill a single pedestrian. Study 2 casts the same models as business advisors choosing, across 260 pairs, between projected firm revenue and jobs created outside the firm. From each model's choices, I estimate how much revenue it will give up per job. Twelve models pay for community employment, at rates from $923 to $7,066 per job; two place no measurable weight on it; and one, xAI's Grok, requires additional revenue before it will accept community jobs at all. Partiality in the vehicle dilemmas predicts how much revenue models give up for community jobs (ρ = .725, p = .002). AI thus introduces a new source of variation in how firms balance their objectives, and which model a firm adopts is a decision about whose interests the organization will prioritize.

Supernatural explanations across 114 societies are more common for natural than social phenomena
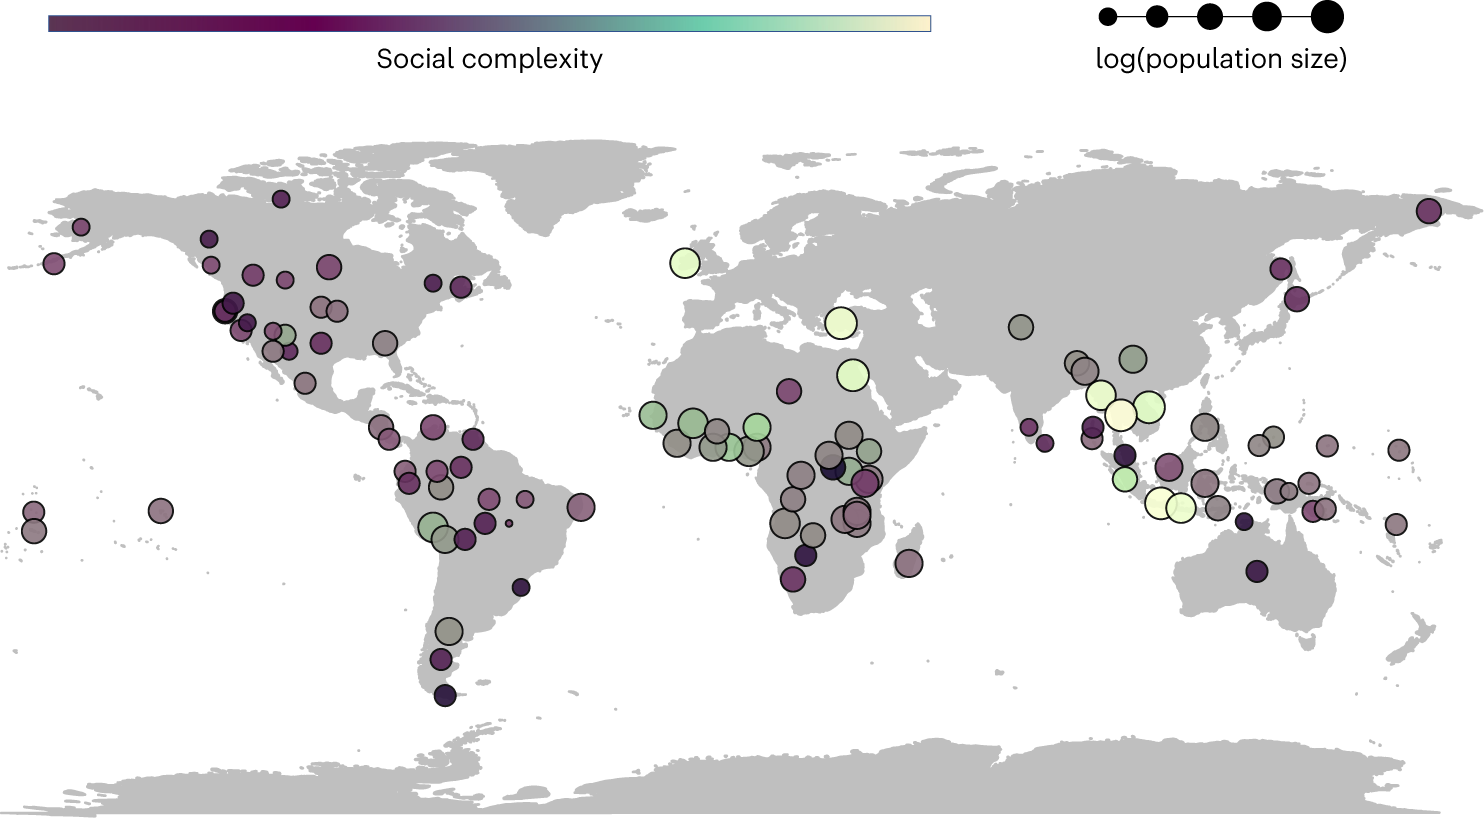
Humans across the globe use supernatural beliefs to explain the world around them. This article explores whether cultural groups invoke the supernatural more to explain natural phenomena (for example, storms, disease outbreaks) or social phenomena (for example, murder, warfare). Quantitative analysis of ethnographic text across 114 geographically and culturally diverse societies found that supernatural explanations are more prevalent for natural than for social phenomena, consistent with theories that ground the origin of religious belief in a human tendency to perceive intent and agency in the natural world. Despite the dominance of supernatural explanations of natural phenomena, supernatural explanations of social phenomena were especially prevalent in urbanized societies with more socially complex and anonymous groups. Our results show how people use supernatural beliefs as explanatory tools in non-industrial societies, and how these applications vary across small-scale communities versus large and urbanized groups.
Sycophancy Suppression Can Impair Rational Updating: Anti-Sycophancy Should Preserve the Ability to Update
Large language models often exhibit sycophancy, revising their answers to align with users when users push back. Such answer flips, however, can arise from different causes. One possibility is that the model simply aligns with the user's feedback in order to satisfy them. Another is that the feedback genuinely contains useful evidence, prompting the model to update its answer in a rational way. We distinguish them as Unsupported-Yielding and Rational-Updating. Prior work focuses primarily on suppressing Unsupported-Yielding, while overlooking its effect on Rational-Updating. We address this gap with a two-turn evaluation framework that measures the two behaviors separately. Across representative training-time and inference-time interventions, we find that anti-sycophancy methods often encounter a trade-off in which reducing Unsupported-Yielding can sacrifice Rational-Updating, and vice versa, even when the two objectives are optimized jointly. Mechanistic analysis suggests that the two behaviors share an internal substrate: the MLP neurons and attention heads driving them overlap substantially, and their associated steering directions are positively aligned. We further conduct a preliminary orthogonalized steering exploration, which yields modest, backbone-dependent selectivity gains. Overall, our results suggest that anti-sycophancy should be treated not as a simple suppression problem, but as a selectivity problem, where effective interventions should preserve Rational-Updating while reducing Unsupported-Yielding.
8 Sample Size Justification – Improving Your Statistical Inferences
This open educational resource contains information to improve statistical inferences, design better experiments, and report scientific research more transparently.
Spurious normativity enhances learning of compliance and enforcement behavior in artificial agents
Significance The fact that humans enforce and comply with norms is an important reason why humans enjoy higher levels of cooperation and welfare than other animals. Some norms are relatively easy to explain: They may prohibit obviously harmful or uncooperative actions. But many norms are not easy to explain. For example, most cultures prohibit eating certain kinds of foods, and almost all societies have rules about what constitutes appropriate clothing, language, and gestures. Using a computational model focused on learning shows that apparently pointless rules can have an indirect effect on welfare. They can help agents learn how to enforce and comply with norms in general, improving the group’s ability to enforce norms that have a direct effect on welfare. , How do societies learn and maintain social norms? Here we use multiagent reinforcement learning to investigate the learning dynamics of enforcement and compliance behaviors. Artificial agents populate a foraging environment and need to learn to avoid a poisonous berry. Agents learn to avoid eating poisonous berries better when doing so is taboo, meaning the behavior is punished by other agents. The taboo helps overcome a credit assignment problem in discovering delayed health effects. Critically, introducing an additional taboo, which results in punishment for eating a harmless berry, further improves overall returns. This “silly rule” counterintuitively has a positive effect because it gives agents more practice in learning rule enforcement. By probing what individual agents have learned, we demonstrate that normative behavior relies on a sequence of learned skills. Learning rule compliance builds upon prior learning of rule enforcement by other agents. Our results highlight the benefit of employing a multiagent reinforcement learning computational model focused on learning to implement complex actions.

Political Compass or Spinning Arrow? Towards More Meaningful Evaluations for Values and Opinions in Large Language Models
Much recent work seeks to evaluate values and opinions in large language models (LLMs) using multiple-choice surveys and questionnaires. Most of this work is motivated by concerns around real-world LLM applications. For example, politically-biased LLMs may subtly influence society when they are used by millions of people. Such real-world concerns, however, stand in stark contrast to the artificiality of current evaluations: real users do not typically ask LLMs survey questions. Motivated by this discrepancy, we challenge the prevailing constrained evaluation paradigm for values and opinions in LLMs and explore more realistic unconstrained evaluations. As a case study, we focus on the popular Political Compass Test (PCT). In a systematic review, we find that most prior work using the PCT *forces models to comply with the PCT's multiple-choice format. We show that models give substantively different answers when not forced; that answers change depending on how models are forced; and that answers lack paraphrase robustness. Then, we demonstrate that models give different answers yet again in a more realistic open-ended answer setting. We distill these findings into recommendations and open challenges in evaluating values and opinions in LLMs.
Artificial Hivemind: The Open-Ended Homogeneity of Language Models (and Beyond)
Language models (LMs) often struggle to generate diverse, human-like creative content, raising concerns about the long-term homogenization of human thought through repeated exposure to similar outputs. Yet scalable methods for evaluating LM output diversity remain limited, especially beyond narrow tasks such as random number or name generation, or beyond repeated sampling from a single model. We introduce Infinity-Chat, a large-scale dataset of 26K diverse, real-world, open-ended user queries that admit a wide range of plausible answers with no single ground truth. We introduce the first comprehensive taxonomy for characterizing the full spectrum of open-ended prompts posed to LMs, comprising 6 top-level categories (e.g., brainstorm & ideation) that further breaks down to 17 subcategories. Using Infinity-Chat, we present a large-scale study of mode collapse in LMs, revealing a pronounced Artificial Hivemind effect in open-ended generation of LMs, characterized by (1) intra-model repetition, where a single model consistently generates similar responses, and more so (2) inter-model homogeneity, where different models produce strikingly similar outputs. Infinity-Chat also includes 31,250 human annotations, across absolute ratings and pairwise preferences, with 25 independent human annotations per example. This enables studying collective and individual-specific human preferences in response to open-ended queries. Our findings show that LMs, reward models, and LM judges are less well calibrated to human ratings on model generations that elicit differing idiosyncratic annotator preferences, despite maintaining comparable overall quality. Overall, INFINITY-CHAT presents the first large-scale resource for systematically studying real-world open-ended queries to LMs, revealing critical insights to guide future research for mitigating long-term AI safety risks posed by the Artificial Hivemind.

