

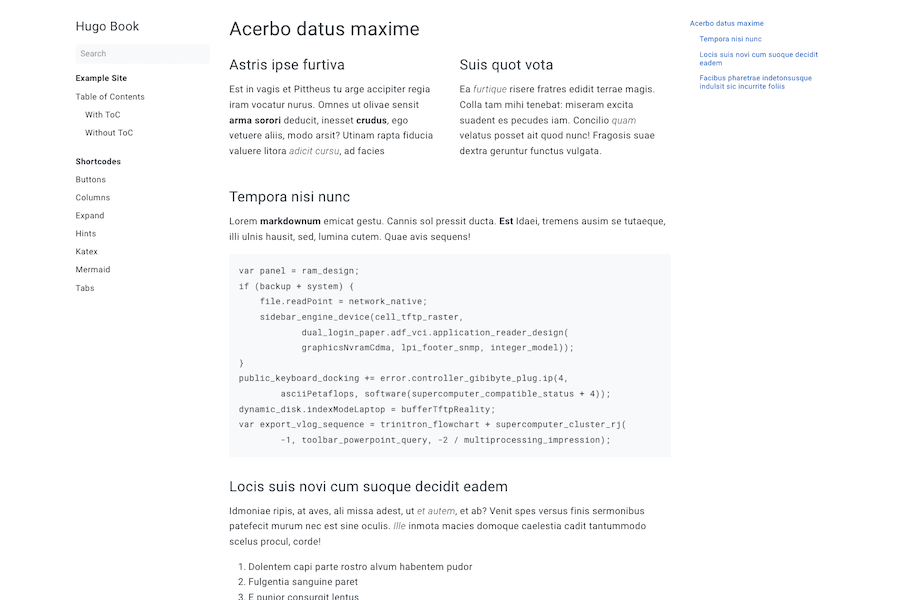
A platform to create documentation/wiki content built with PHP & Laravel
BookStack
BookStack is a simple, open-source, self-hosted, easy-to-use platform for organising and storing information.
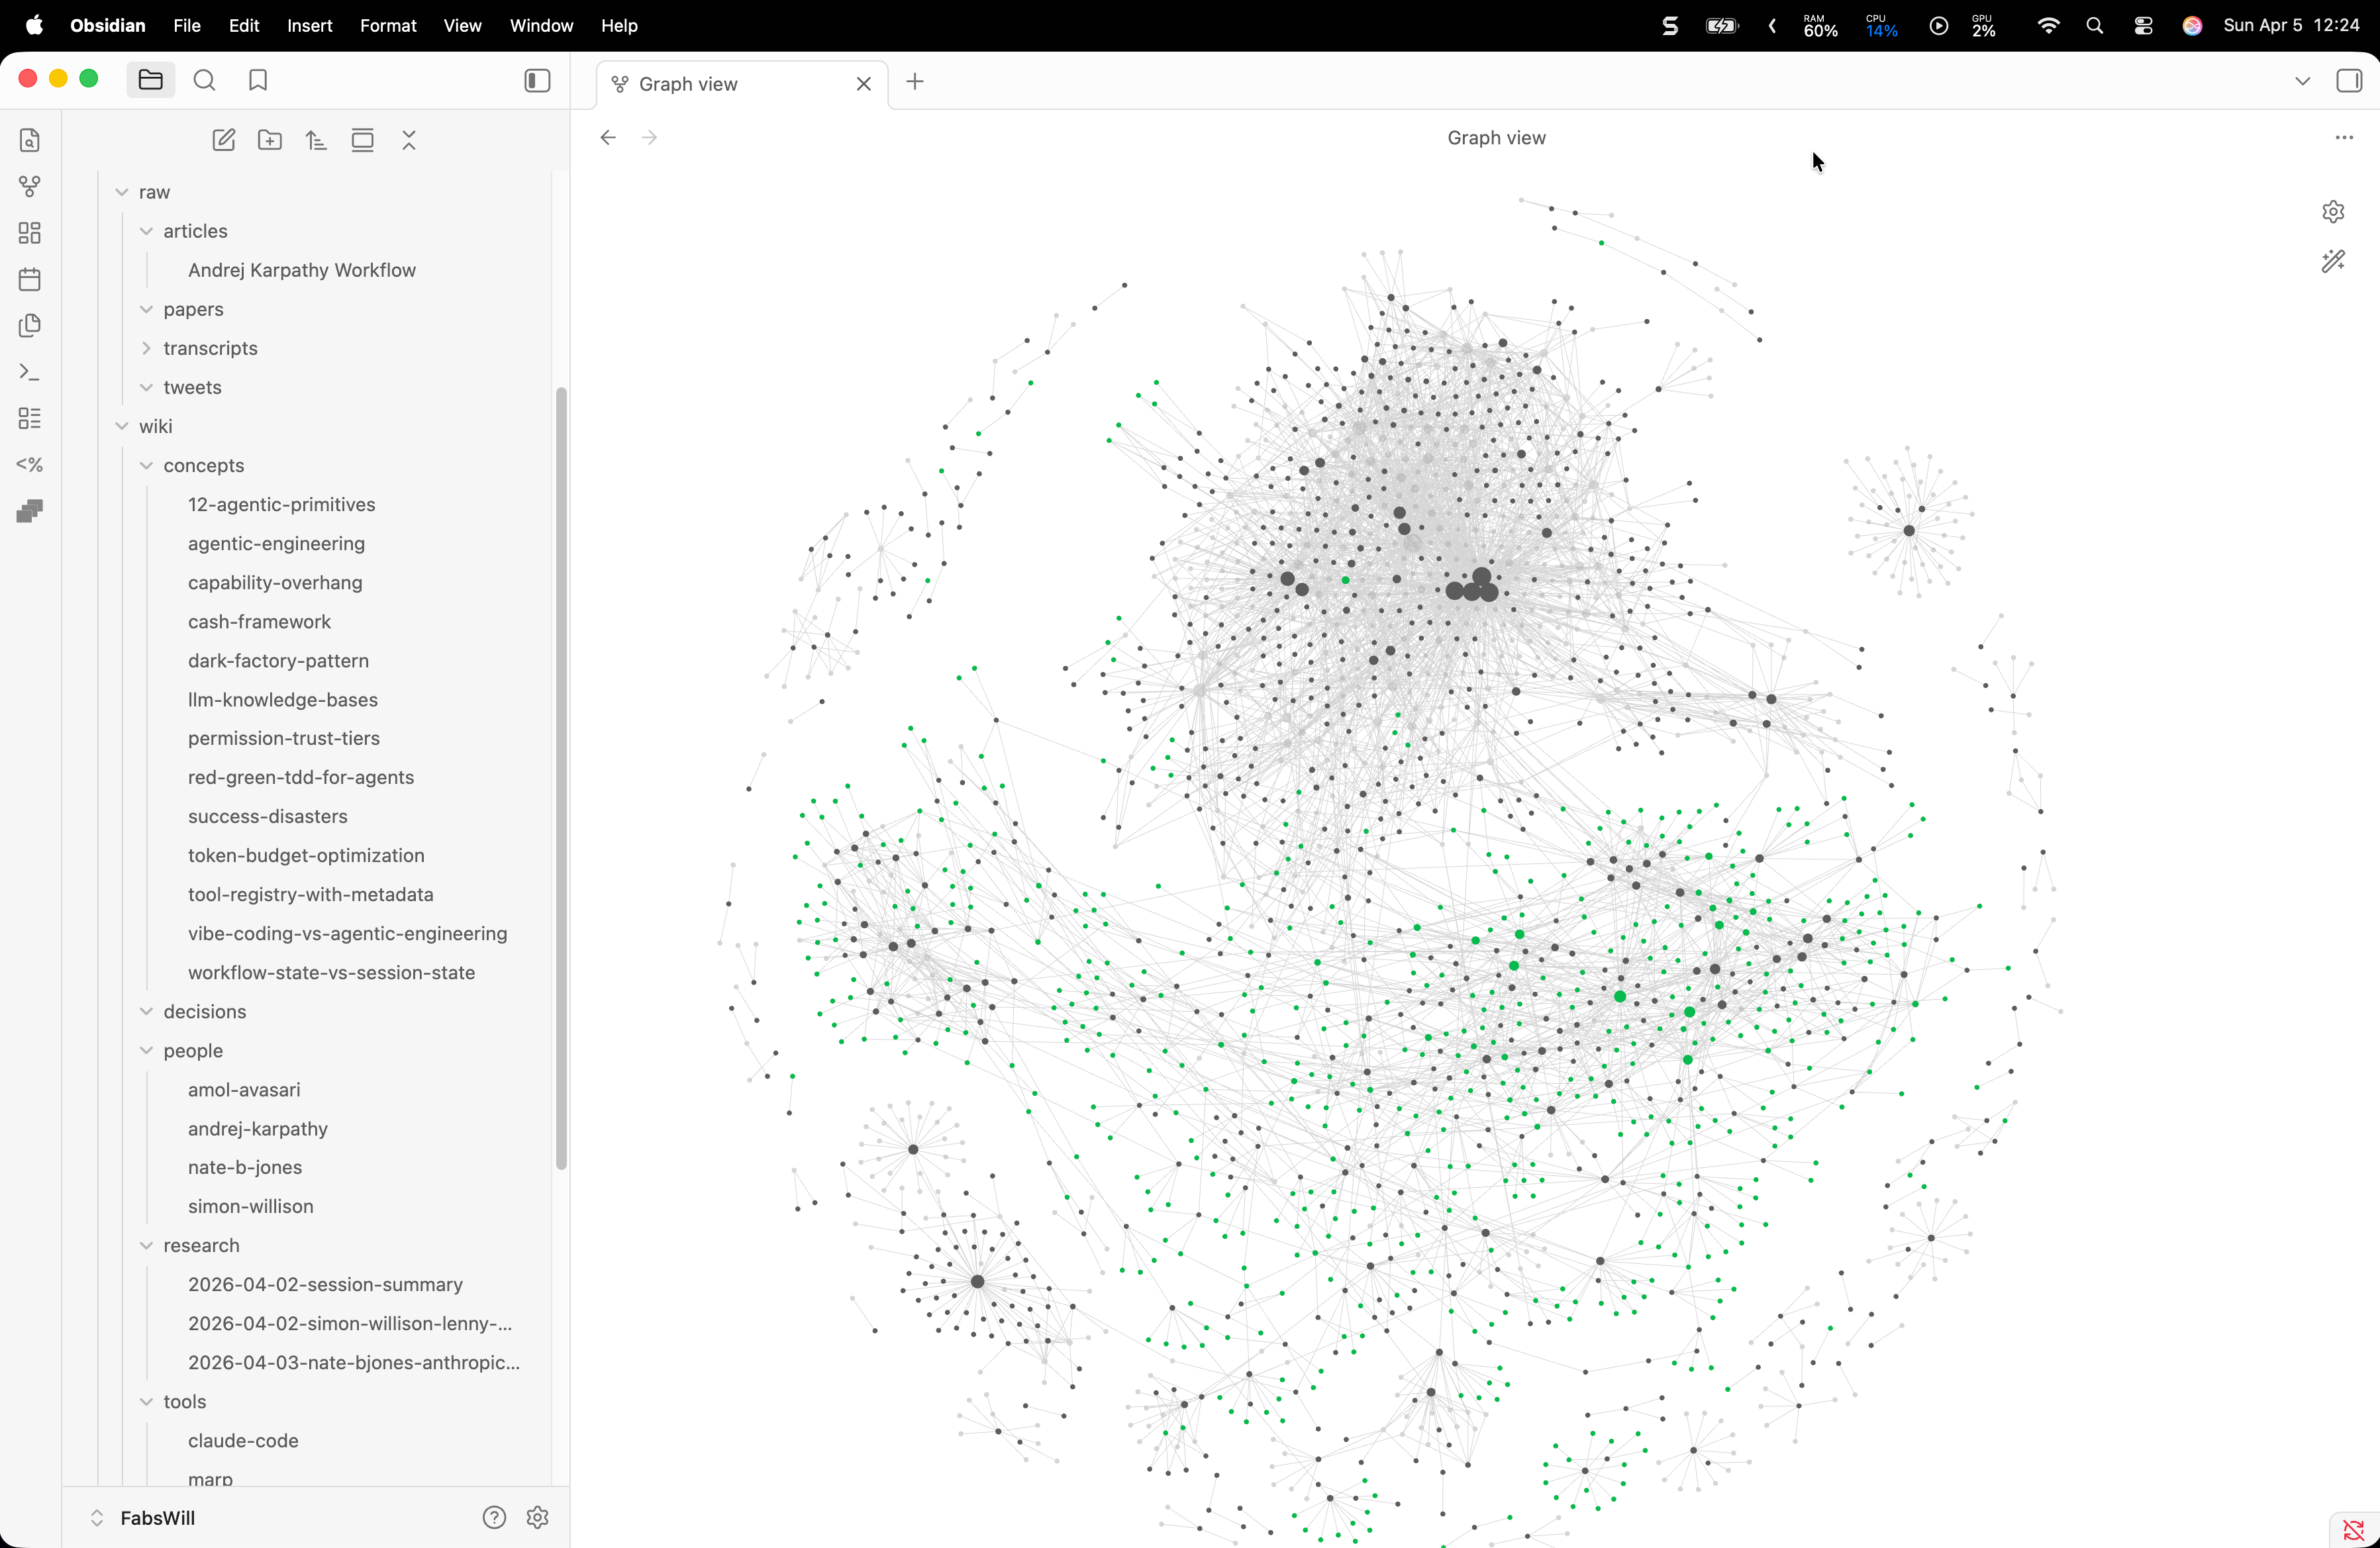
How To Build LLM Wiki In Obsidian? 🧠 A Memory Layer For Any Agentic AI
I Built a Knowledge Base That Writes Itself. Here Is What Andrej Karpathy Got Right.
Andrej Karpathy posted about using LLMs to build personal knowledge bases. I took his workflow, wired it into my Obsidian vault with Claude Code, and within an hour had 21 cross-linked wiki articles compiled from YouTube transcripts. Here is how it works and why it matters.
Thoughts on Bookmarking the Web - Henrique Dias
Yesterday I shared some atmospheric thoughts. One of the ideas was seeing which services do I use now that could be replaced. One of those is bookmarking. There’s two main contenders: Margin and Semble.
Wiki Builder: A Claude Code Plugin for Building LLM Knowledge Bases
Wiki Builder is an open-source Claude Code plugin that turns the LLM-knowledge-base workflow into a one-command setup. Scaffold a configurable wiki, point Claude at sources, and let the agent compile durable pages, indexes, and concept maps for you.
Best open source help desk: Zendesk & Help Scout alternative
FreeScout is the super lightweight and powerful free open source help desk and shared inbox built with PHP (Laravel framework). Now you can enjoy free Zendesk & Help Scout without giving up privacy or locking you into a service you don't control. FreeScout is multichannel — it centralizes all customer conversations from various channels in one place.
10 Easy Ways to Enhance Your LLM Wiki or Knowledge Base
Karpathy's LLM Knowledge Base Wiki for Enterprise | Vijoy Pandey posted on the topic | LinkedIn
There's a new kind of computer media in the enterprise: Write once, Read never. The docs are perpetually stale, constantly diverging from reality, and scattered across Confluence, SharePoint, GitHub, Webex (or Slack) threads, Notion, Obsidian - and in my personal life, add Apple Notes, Goodnotes, web clippings, and multiple Google Drives worth of docs and slides that nobody is ever going back to. Karpathy tweeted his LLM knowledge base wiki architecture which went viral last weekend and I decided to give it a run yesterday. Verdict: You *have* to try this out. Prediction: You won’t be able to live without it soon. There were a few mods and decisions I made to the base Karpathy provided. First, the vault / folder structure in Obsidian. I already use Obsidian as a human. Instead of creating separate vaults and dealing with the sync nightmare, I just have folders for Human and Agent, and a Raw folder. (1) The Human/ folder is where I write long form articles and notes independent of the knowledge base wiki. No LLM or agent touches this folder. (2) I do have Arnold Layne, my OpenClaw agent, doing background tasks for me. Raw/ is where both Arnold and I, dump raw snippets. Inclusive of diverse kinds of media. (3) The Agent/ folder is where the LLM (Claude in my case) synthesizes the wiki. No human touches this folder. Second, some customizations to CLAUDE.md for enterprise-like usage - (4) Domain extensions - the agent needs to know that quantum computing and agentic AI have different entity types and different provenance thresholds. (5) Primary source protection, when I drop in my own original work, secondary sources can extend it or raise questions against it, but they cannot overwrite it. It sounds like a small thing but its’s not, especially at enterprise scale where provenance actually matters. Karpathy is upfront that what he’s built is working memory for a single agent, and it’s truly remarkable at that. The jump to Shared Context across teams, reconciling conflicting beliefs at org scale, ontologies that don’t collapse under the weight of a hundred contributors - those are much harder problems and what we are exploring with the Internet of Cognition. PS: The screenshot shows my Obsidian vault after just two runs: one with Karpathy’s original tweet and gist file itself (so meta!) and one with our Internet of Cognition paper. Claude (Sonnet) read it, compiled it into structured summaries, entity pages, concept pages, backlinks, merged all the information cohesively, and keeps it all maintained from there. You just read the Wiki. It’s simply magical.

The Best API Documentation Tool
OpenAPI-generated documentation tool with 24k+ stars on Github - make APIs your company's superpower.
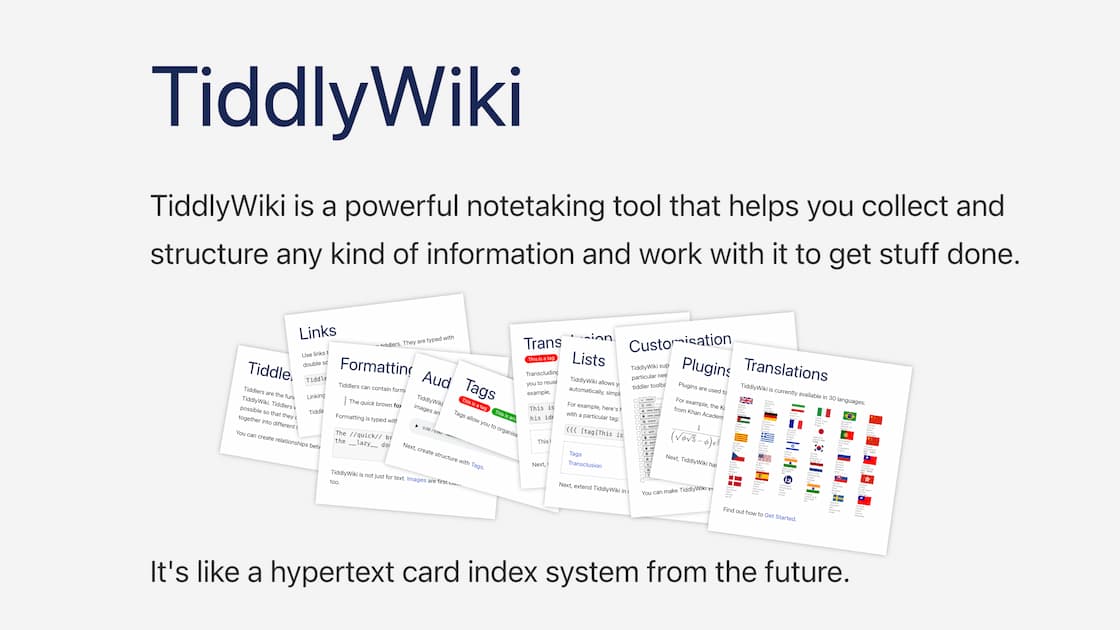
Documentation is more than you think
Everything that is involved in making great documentation everywhere and all at once.
Composer by DXOS
Introducing programmable documents. Blend the power of popular file formats (docs, sheets, sketch & tables) inside of a collaborative local-first workspace.
This is definitely the sort of thing that I have in mind with book interop. The reality is that with so many data sources for books, that there needs to be some sort of mapping of books, which would need the user to explicitly decide on the mapping.

Wesley Finck
after a fun chat with @laurenshof.online and @ronentk.me I finally made time to write up some more thoughts about interoperability in the atmosphere without needing to share lexicons! notes.wesleyfinck.org/3maq3h26ook2h
Wiki

Wiki software
robot.wtf — Memory for agents in a wiki for humans
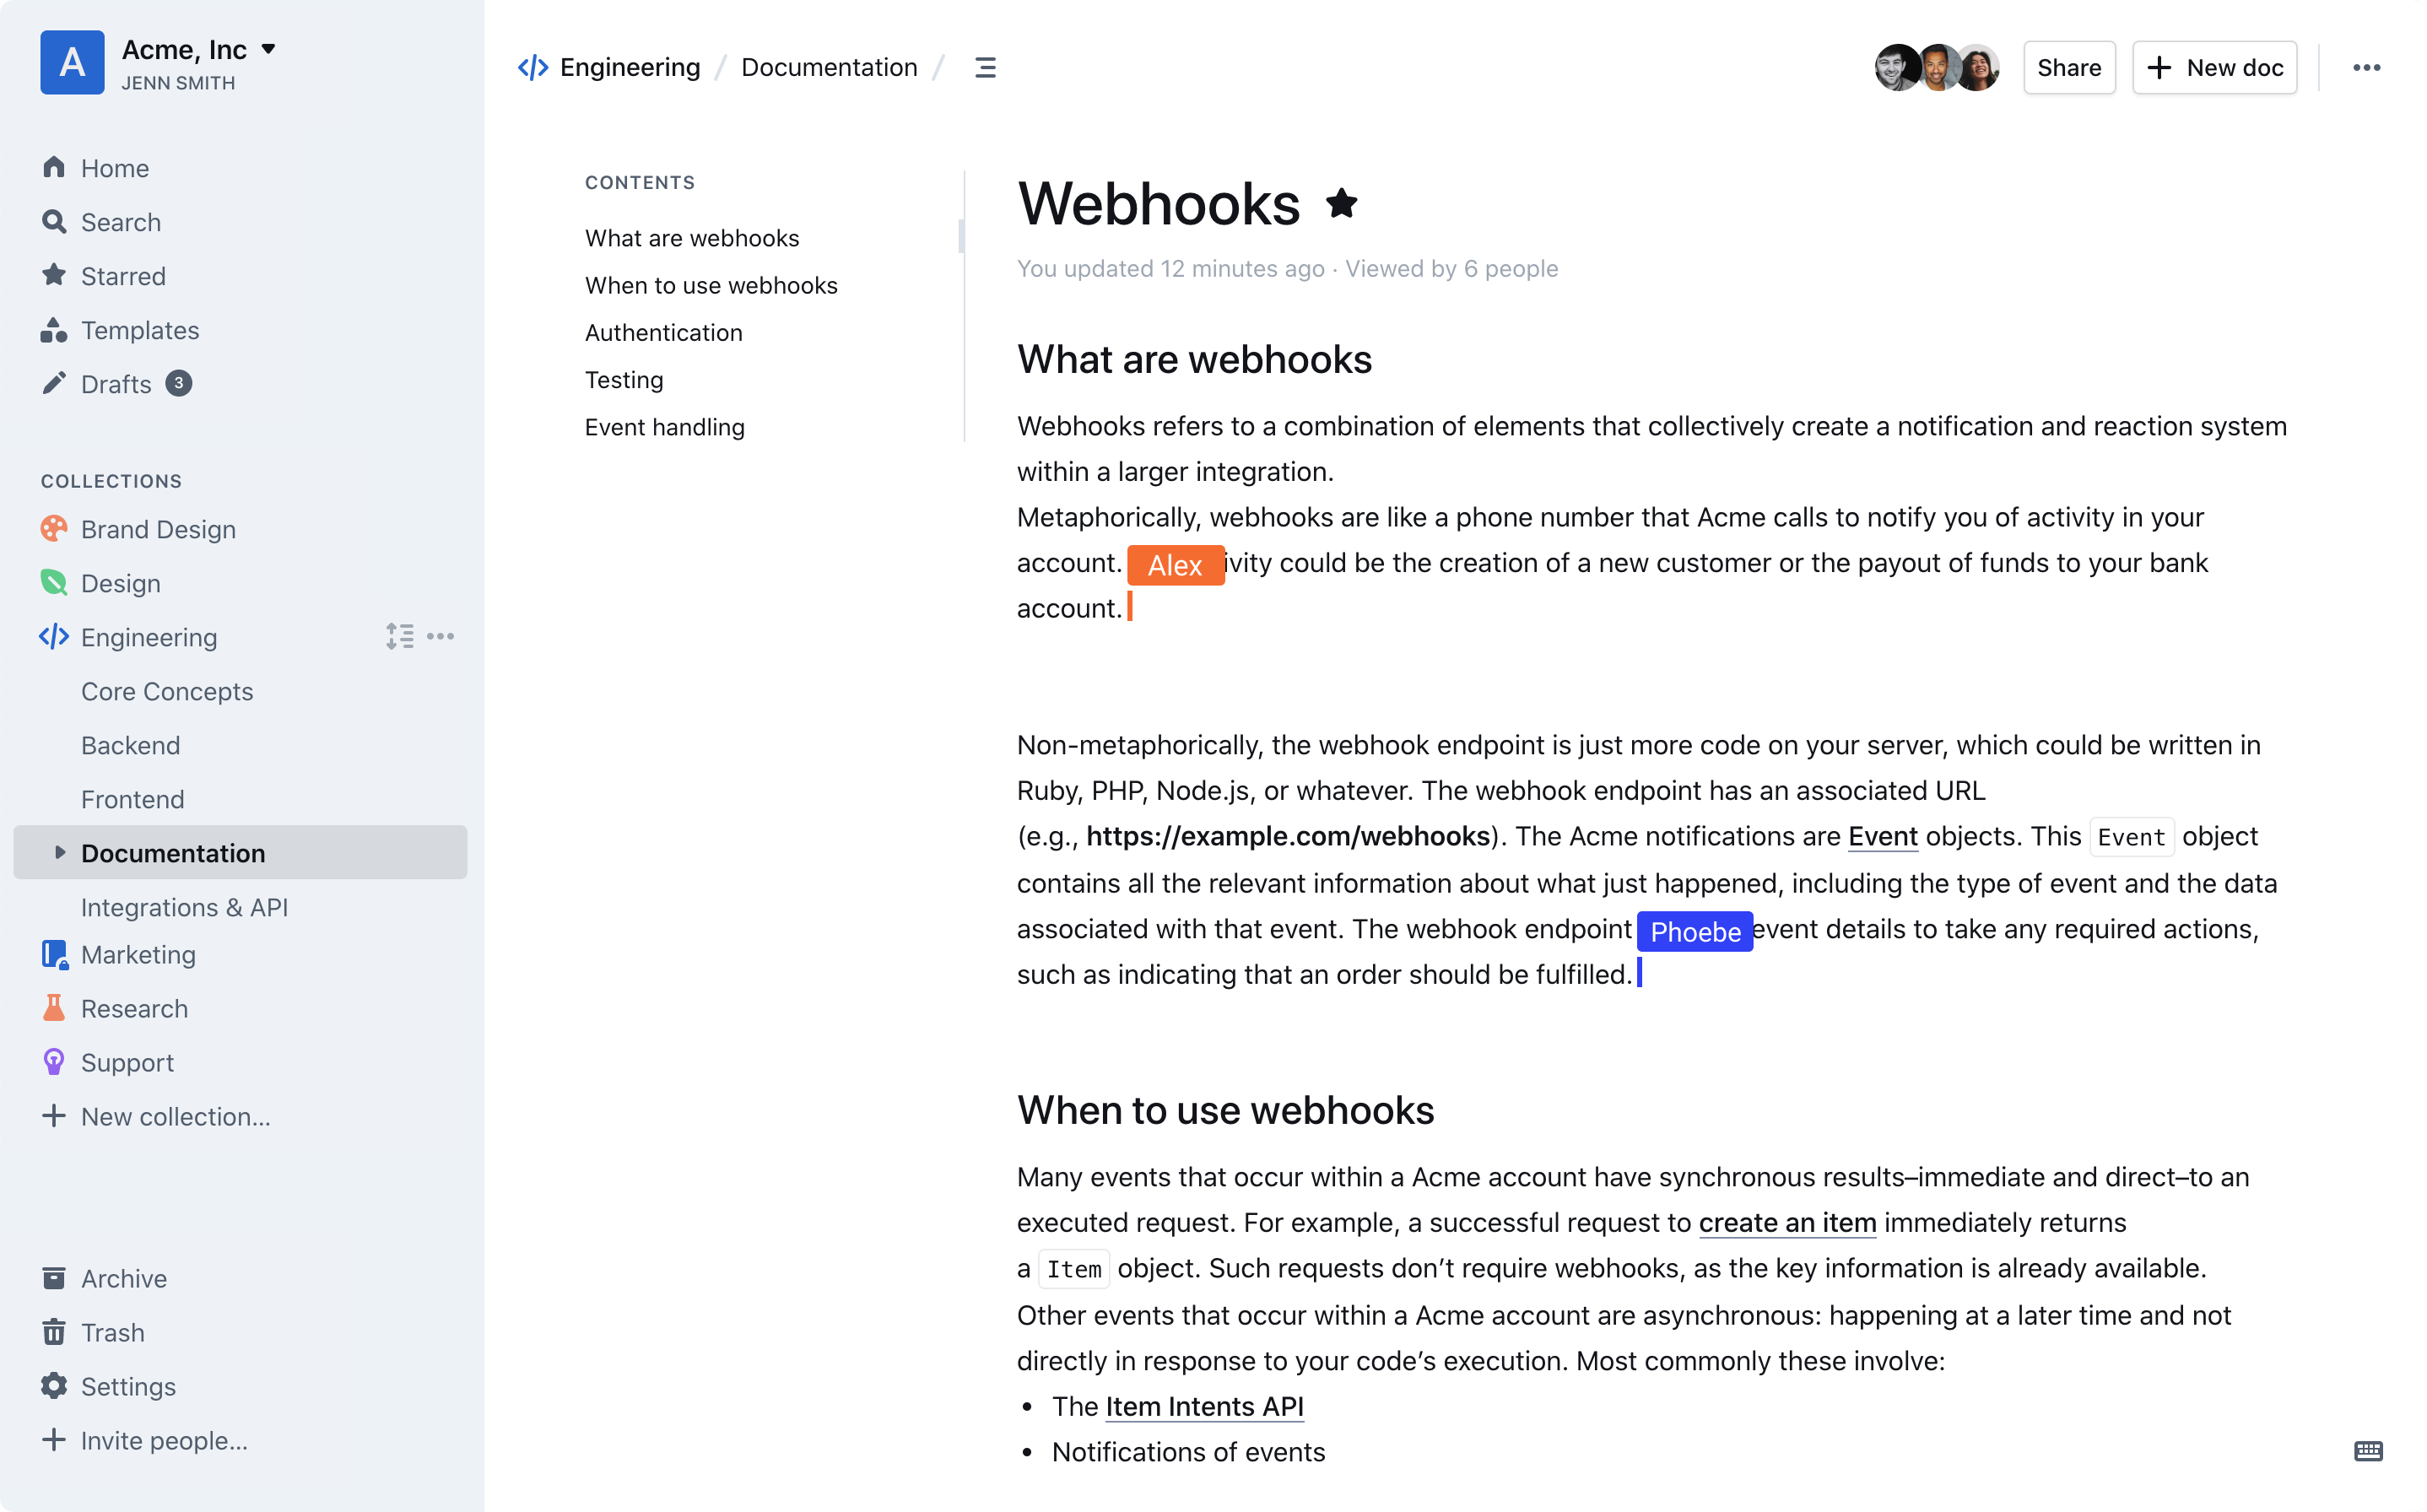
Outline – Team knowledge base & wiki
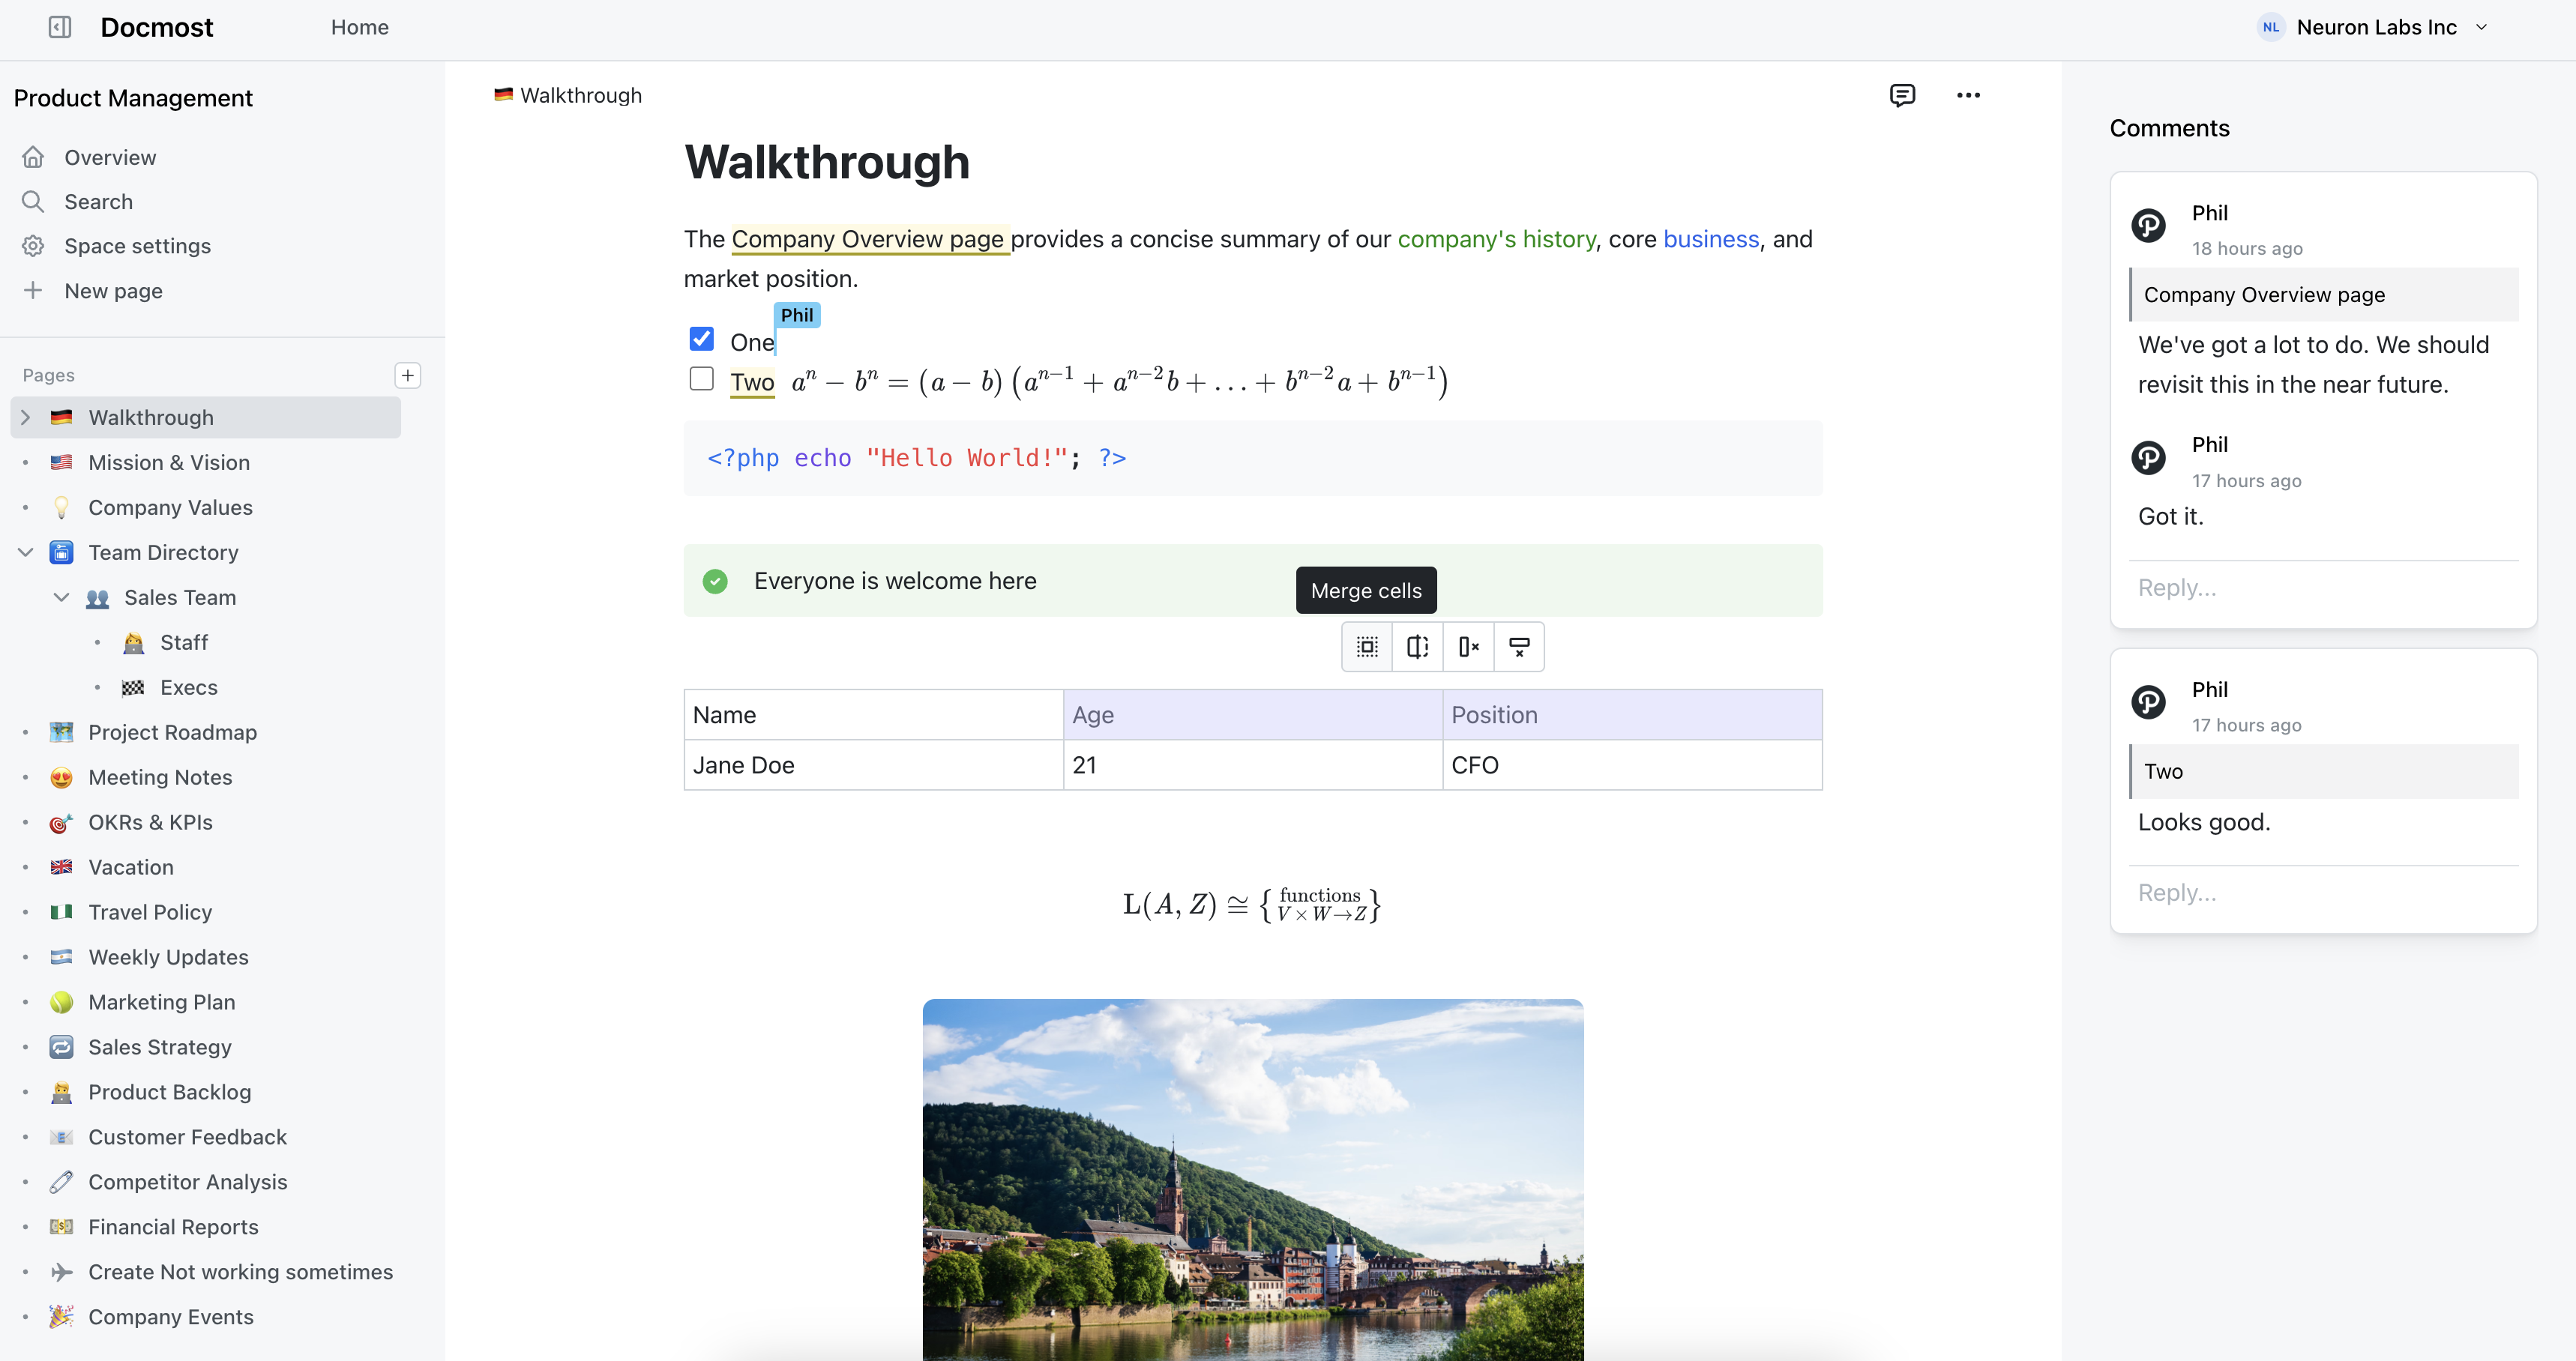
Enterprise-ready Wiki for Teams | Docmost
Lichen
Cardigan Bay Wiki :: AboutThisWiki
interstar/cardigan-bay
